Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Hightouch states |
|---|---|
Data sources | Connects directly to your data warehouse. Snowflake and Google BigQuery are the most used sources; databases, CSV files, SFTP and BI tools can also be sources. |
Deployment | Listed for CDP and AI Decisioning plans: deployment in the EU region or in multiple regions, and SSH tunneling. |
Security and compliance | Listed for CDP and AI Decisioning plans: ISO 27001 certified; SOC 2 & SOC 3, HIPAA and GDPR compliance; custom security review (BAA, DPA, full SOC2 report). |
Access control | Listed for CDP and AI Decisioning plans: role-based and label-based access control, Google and Azure SSO, and SAML SSO (Okta, Azure AD and others). |
Support | Listed for CDP and AI Decisioning plans: email & Slack support, a dedicated shared Slack, dedicated CSM, white glove onboarding, a dedicated solutions architect, and custom product uptime and support SLAs. |
Automation and licence | Resource API (listed for CDP and AI Decisioning plans). The Hightouch CLI is Apache-2.0 licensed; it logs in with an API key and lists or inspects sources, models, destinations, syncs and runs, and triggers syncs. |
Our take
Hightouch is a strong fit if your customer data already sits in a warehouse and you want to activate it in marketing and business tools, buying only the products you need. If your customer data is not yet in a warehouse or another supported source, fix that first: Hightouch works from your data where it lives.
Evaluate Hightouch
Comparisons
Where it stands out
Wide destination catalog. Hightouch can sync data to 300+ integrations, and multiple instances of the same destination count only once. That helps when you sync to several accounts of the same tool.
Buy only what you use. All products can be purchased separately. Hightouch says its usage-based pricing has no MTU (Monthly Tracked Users) limits and no caps on sources, destinations or user seats.
Choice of where sync work runs. On CDP and AI Decisioning plans, sync planning and caching can run on Hightouch, on your warehouse, or on your custom storage. This lets data teams keep that work inside their own stack.
Sync debugging and change control. The feature list for CDP and AI Decisioning plans includes a live debugger, test runs (test-a-row), in-app and warehouse sync logs, custom alerting by sync, Git version control, approval flows and audit logs. Check which plan includes each item.
Hooks into the data stack. Premium extensions for CDP and AI Decisioning plans include a dbt model selector (git rep), a dbt Cloud sync scheduler, a Fivetran sync scheduler, a Looker model selector, a Tableau integration and a Sigma workbook integration. These let syncs follow existing models and pipelines.
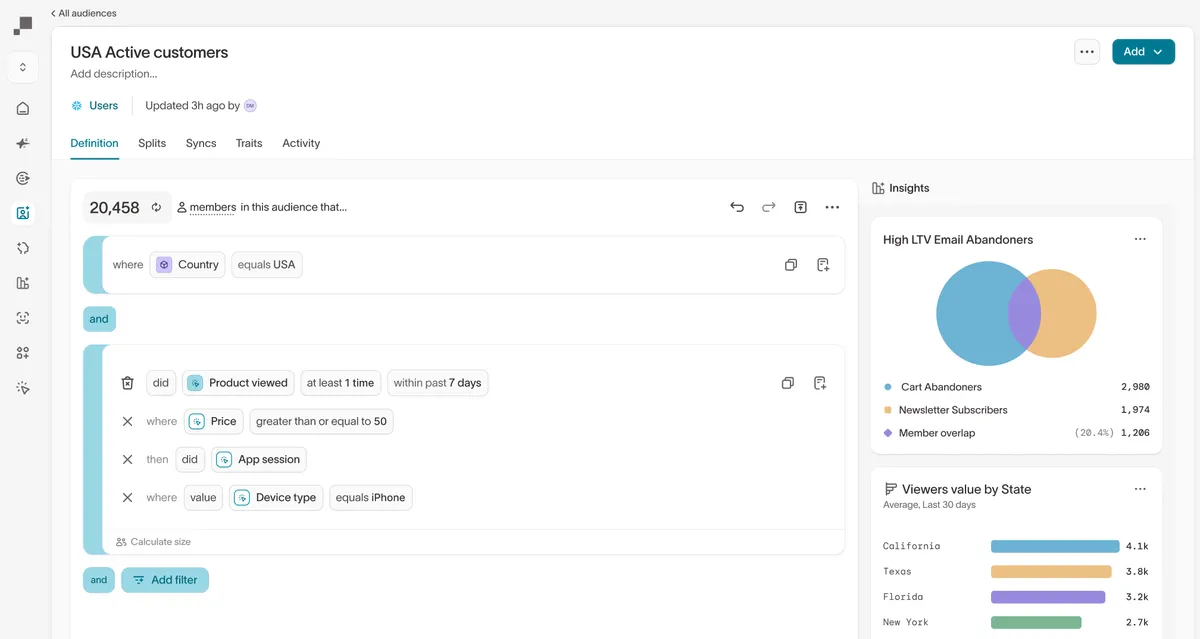
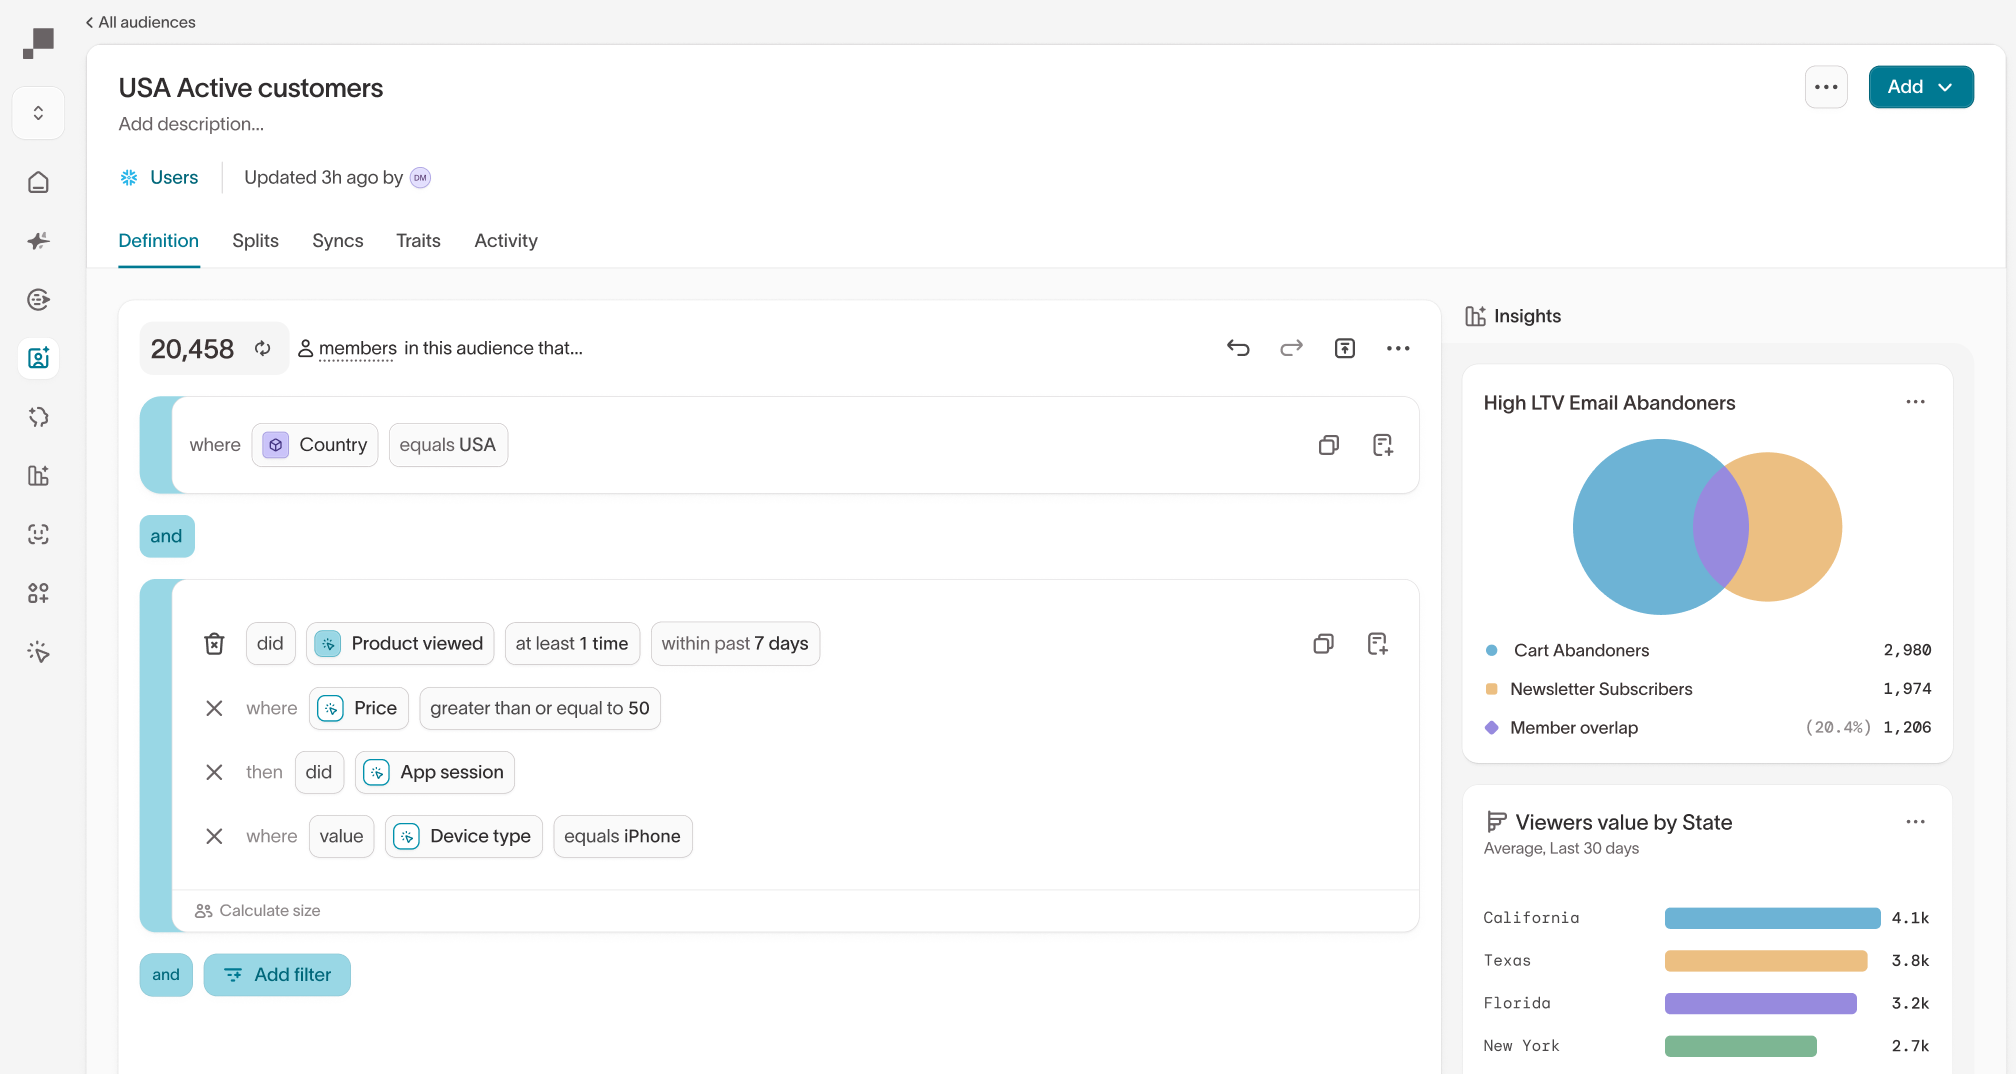
Product screenshot
Trade-offs to weigh
The free tier is for a pilot. Basic Reverse ETL allows up to 2 active syncs, enough to prove a use case or two. A team that runs more syncs in production needs the paid, usage-based products.
A full CDP is assembled from parts. Events, Customer Studio, Identity Resolution, Match Booster and Real-time Personalization are separate products in the Composable CDP selection. Decide which ones you need before you compare Hightouch with an all-in-one CDP, because each one you add becomes part of the usage you pay for.
Your team owns the data. Hightouch connects directly to your warehouse and leaves you in control of data governance and storage. The flip side is that modelling and data quality stay with your data team.
Pricing and plan conditions
Hightouch prices by usage: you pay for the products you select and how much you use them. Hightouch says unit costs shrink as usage grows. Questions about payments, invoices or overages go to accounting@hightouch.com.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Basic Reverse ETL | Free tier | For teams with limited use cases getting started with the Reverse ETL Platform: up to 2 active syncs, unlimited destination count and unlimited user seats. |
Agentic Marketing Platform | Usage-based pricing | Ad Studio, Lifecycle Studio and AI Decisioning. Includes a pre-set amount of monthly personalized actions, integrations with any marketing platform, enterprise security and observability features. |
Composable CDP | Composable and usage-based pricing | A full CDP or a la carte functionality, chosen from Reverse ETL Platform, Hightouch Events, Customer Studio, Real-time Personalization, Identity Resolution and Match Booster. Lists unlimited user seats, enterprise security, premium extensions, advanced observability, advanced access management, dedicated expert support, custom SLAs and Data Agents. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
0 GitHub commits 90d13 GitHub stars0 vulnerabilities across 1 package
See all signals from 5 sources
PyPI · hightouch@1.31.0
Alternatives to Hightouch
The reviewed substitutes for Hightouch among the customer data platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Census (now Fivetran Activations)
- Hightouch and Census (now Fivetran Activations) sync modeled data from the warehouse into business tools such as CRMs, ad platforms and support desks. Hightouch puts its weight on marketing work like audience targeting and personalization, while Census is now part of Fivetran and suits teams that already load their data with Fivetran.Applies to: Choosing the tool that sends modeled warehouse data to CRMs, ad platforms and support desks.
- Polytomic
- For reverse ETL, Polytomic and Hightouch each send warehouse records to CRMs, ad platforms and other SaaS tools. Hightouch builds out marketing features such as audiences and personalization, while Polytomic targets business teams that want one no-code app for syncing data in any direction.Applies to: Choosing between these two for the reverse etl activation decision.
- RudderStack
- Getting customer data out to ad platforms, email tools and CRMs is the job of Hightouch and RudderStack. Hightouch is a commercial platform that works from tables already in the warehouse, while RudderStack is open source and adds real-time event collection and identity resolution to its warehouse syncs.Applies to: Choosing the platform that will collect customer events and send them to downstream tools.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Segment
- Segment has been a prominent CDP by market share for several years and was the platform Hightouch was originally built to compete against with its warehouse-native alternative approach. **Segment** (by Twilio) is a customer data platform that collects, unifies, and routes customer data into any system via a single API.Applies to: for teams that need event collection, identity resolution, and real-time data routing without requiring a pre-existing data warehouse.
Head to head
See detailed alternatives analysis
If you are evaluating Hightouch alternatives, you are likely looking for a data activation or reverse ETL platform that better fits your architecture, budget, or team workflow. Hightouch is a warehouse-native activation platform that uses reverse ETL to sync customer data from cloud data warehouses (Snowflake, BigQuery, Databricks, Redshift) to marketing, sales, and advertising tools. It has evolved from a single-purpose reverse ETL tool (founded 2018) through "Composable CDP" positioning (2022) to its current "agentic marketing platform" framing (2025), adding capabilities like Customer Studio (no-code audience builder), AI Decisioning (reinforcement learning for campaign optimization), and Adaptive Identity Resolution along the way. Hightouch operates on a freemium model with basic reverse ETL available at no cost, and it does not store customer data or provide native messaging -- every activation requires an external destination tool.
Below, we break down the top Hightouch alternatives across architecture, pricing, and use cases to help you find the right fit.
Top Alternatives Overview
Census (now Fivetran Activations) is the closest direct competitor to Hightouch in the reverse ETL space. Census syncs data from warehouses to 200+ business tools like Salesforce, HubSpot, and Marketo. It was acquired by Fivetran and rebranded as Fivetran Activations, consolidating reverse ETL into Fivetran's broader data movement platform. Census offers a free tier with limited syncs, with paid plans scaling based on destination count and sync volume. Census is best suited for data teams that already have a well-modeled warehouse and need to activate that data in CRM, marketing, and sales tools without heavy engineering involvement. The combined Fivetran Activations platform now includes an Audience Hub for self-service audience creation, AI-powered data enrichment columns, and 200+ pre-built activation destinations.
Fivetran is the industry-leading managed ELT platform with 700+ automated connectors for SaaS applications, databases, ERPs, and files. With its acquisition of Census, Fivetran now covers the full data movement lifecycle: automated ingestion (ELT), transformation orchestration via dbt integration, and activation through reverse ETL. Fivetran offers a free tier and usage-based pricing across its consolidated platform. It holds SOC 1, SOC 2, GDPR, HIPAA BAA, ISO 27001, and PCI DSS Level 1 certifications, making it one of the most security-certified platforms in the data pipeline space. Fivetran is ideal for organizations that want a single managed platform for both data ingestion and activation rather than stitching together separate tools.
Segment (by Twilio) is a customer data platform that collects, unifies, and routes customer data into any system via a single API. Unlike Hightouch's warehouse-native approach, Segment ingests data into its own infrastructure and then distributes it to 200+ downstream tools. Segment operates on a freemium model and is best for teams that need event collection, identity resolution, and real-time data routing without requiring a pre-existing data warehouse. Segment has been a prominent CDP by market share for several years and was the platform Hightouch was originally built to compete against with its warehouse-native alternative approach.
Polytomic combines ETL, reverse ETL, and CDC streaming in a single platform, allowing bidirectional data sync between warehouses, databases, CRMs, and SaaS applications. Polytomic offers a free tier for up to 5 users, with paid plans available at higher tiers. It supports self-hosting for turnkey deployment to your private cloud and is built for enterprise scale with multi-tenant workspaces, entity-level RBAC permissions, and first-class Terraform support for infrastructure-as-code workflows. Polytomic stands out for teams that need both forward and reverse data movement in one tool rather than maintaining separate pipelines.
Hevo Data is an ingestion option with dbt integration on paid plans. Free covers limited connectors and up to 1M events/month. Starter starts at $299/month billed monthly or $265/month billed annually for 5M events/month; On-Demand usage above quota costs extra. Events are destination inserts, updates and deletes. Evaluate activation requirements separately: a managed ingestion subscription does not establish a complete Hightouch replacement or eliminate maintenance work.
Meltano takes an open-source, CLI-first approach to data integration. Built for data engineers who want complete control and visibility, Meltano is self-hosted, debuggable, and extensible. It has accumulated over 2,400 GitHub stars and embraces DevOps best practices throughout the data lifecycle. Meltano is the strongest option for teams that prioritize infrastructure-as-code, version-controlled pipeline definitions, and full pipeline ownership without vendor lock-in.
Architecture and Approach Comparison
The fundamental architectural divide among Hightouch alternatives is between warehouse-native activation and platform-hosted data management. Hightouch, Census (Fivetran Activations), and Polytomic all follow the warehouse-native pattern: they query your existing data warehouse and push results to downstream destinations without storing a copy of your data. Segment, by contrast, ingests data into its own infrastructure and maintains its own customer profiles before routing data outward. This distinction has significant implications for data governance, latency, and cost.
Hightouch's architecture connects directly to Snowflake, BigQuery, Databricks, or Redshift, runs SQL queries or visual audience definitions via Customer Studio, and syncs results to 200+ destinations. Every sync is a data push from warehouse to destination. This means Hightouch inherits whatever data modeling and transformation you have already built in your warehouse, but it also means you need a well-structured warehouse before Hightouch adds value. The platform does not provide its own transformation or modeling layer, though it integrates with dbt and warehouse-native transformation tools for that purpose.
Fivetran (with Census/Activations) now offers the most complete managed data movement stack: automated ingestion from 700+ sources, transformation orchestration via dbt integration, and reverse ETL activation to 200+ destinations. This end-to-end approach eliminates the need to manage separate vendors for each stage of the pipeline. Fivetran's hybrid deployment option also lets organizations run pipelines in their own environment for stricter security requirements, with data never leaving the customer's infrastructure.
Segment's approach is architecturally different in a fundamental way. It acts as an event collection and routing layer, capturing behavioral data via SDKs and APIs and then fanning it out to downstream tools in near-real-time. This makes Segment stronger for real-time event-driven use cases but means data lives in Segment's infrastructure, which may raise governance concerns for organizations committed to warehouse-centric architectures. Hightouch has addressed the event collection gap with Hightouch Events, which streams behavioral data to the warehouse, but this adds another component to manage.
Polytomic differentiates by offering bidirectional sync capabilities, covering ETL, reverse ETL, CDC streaming, and even direct SaaS-to-SaaS syncing in one platform. This is valuable for teams that need to move data both into and out of their warehouse without maintaining separate tools. Its self-hosting option and first-class Terraform support also appeal to organizations with strict data residency requirements and infrastructure-as-code workflows.
Meltano occupies a unique position as the only fully open-source, CLI-first option in this space. It gives data engineers full control over pipeline configuration, supports infrastructure-as-code workflows with pipeline definitions stored in version control, and avoids vendor lock-in entirely. The trade-off is a higher setup and maintenance burden compared to managed platforms like Fivetran or Hightouch, making it best suited for teams with dedicated data engineering capacity.
For organizations already invested in a modern data stack with a well-modeled warehouse, warehouse-native tools like Hightouch and Census/Fivetran Activations offer the most direct path to activation. For teams without a mature warehouse or with strong real-time event requirements, Segment's platform-hosted model may be more practical. For teams that need maximum flexibility in data movement direction and deployment model, Polytomic and Meltano each offer distinct advantages.
Pricing Comparison
Pricing in the data activation space varies significantly by architecture, scale, and bundling strategy. All of the major Hightouch alternatives offer some form of free entry point, but costs diverge substantially as usage scales.
Hightouch operates on a freemium model with basic reverse ETL available at no cost. Paid tiers scale based on usage, but Hightouch does not publicly list specific tier pricing on its website, requiring teams to contact sales for detailed quotes. The platform's pricing model signals include freemium and usage-based components.
Census (now Fivetran Activations) follows the same consolidated pricing model as the broader Fivetran platform. Usage is measured in monthly active rows (MAR) for both connections and activations, plus monthly model runs (MMR) for transformations. The free tier includes 500,000 MAR for connections, 3,500 MAR for activations, and 5,000 MMR for transformations, along with unlimited users, 15-minute sync frequency, 700+ connectors, 200+ activation destinations, dbt Core integration, and role-based access control. The Standard tier adds SSH tunnel encryption. The Enterprise tier unlocks 1-minute syncs, the Audience Hub, enterprise database connectors, hybrid deployment, custom roles, SCIM provisioning, and multi-cloud provider support. The Business Critical tier adds customer-managed encryption keys, PCI DSS Level 1 certification, and private networking.
Polytomic's paid plans begin with its Standard tier, which includes bidirectional sync between databases, warehouses, spreadsheets, apps, and APIs with unlimited users and connections plus live chat support from engineers. The Enterprise tier adds SSO, dedicated support, SLA guarantees, and additional governance features.
Hevo Free includes hourly scheduling and up to 5 users, with limited connectors and up to 1M events/month. Starter adds the paid connector catalog, dbt integration, SSH/SSL and up to 10 users. Professional starts at $849/month billed monthly or $750/month billed annually for 20M events/month and adds unlimited users, pipeline APIs and Reverse SSH. Business Critical is custom-quoted. Request the overage rate and required activation scope before committing.
Estuary Flow provides a free developer tier, with paid plans scaling upward based on usage and throughput requirements. Its pricing model is usage-based with clear tier progression.
Meltano is open-source and free to self-host under its open-source license, making it the most cost-effective option for organizations with the engineering capacity to manage their own infrastructure. A Pro tier is available for teams that want managed features and support.
When evaluating total cost of ownership, consider that Hightouch's warehouse-native approach requires a separate data warehouse subscription (Snowflake, BigQuery, etc.) and separate messaging tools for actual customer communication, which can significantly increase the overall stack cost beyond the activation platform fee alone. Platforms like Fivetran that bundle ingestion and activation can consolidate some of this cost, while Segment bundles data collection and routing into its platform fee.
When to Consider Switching
Switching from Hightouch makes sense in several specific scenarios based on your organization's needs and data maturity.
If your organization needs both data ingestion and activation in a single platform, Fivetran (with its Census acquisition) eliminates the need to manage Hightouch alongside a separate ELT tool. This consolidation reduces vendor management overhead, simplifies billing into a single usage-based model, and provides unified observability across the full data pipeline from source to destination.
If your team lacks a mature, well-modeled data warehouse, Hightouch's warehouse-native approach may not deliver immediate value. The platform queries warehouse tables directly, so poorly modeled data leads to poor activation results. Segment provides its own data collection, identity resolution, and profile management without requiring an existing warehouse, making it a more practical starting point for organizations earlier in their data maturity journey.
If you need bidirectional data sync -- moving data both into and out of your warehouse, databases, and SaaS tools through a single interface -- Polytomic's unified platform handles ETL, reverse ETL, and CDC streaming without requiring multiple tools or vendors. Hightouch focuses primarily on the warehouse-to-destination direction, requiring separate tooling for data ingestion.
If cost control and vendor independence are priorities, Meltano's open-source model lets you self-host and maintain full control over your data pipelines with pipeline definitions stored as code in version control. This avoids usage-based pricing that can scale unpredictably as data volumes grow and eliminates vendor lock-in concerns entirely.
Choose ingestion and activation around the work each must perform. A Hevo pilot should validate source access, schema changes, failure handling and downstream data quality. Managed connector operation may change who does that work, but this evidence does not quantify labor savings against Hightouch.
If your primary use case is data replication from diverse SaaS sources and databases into a warehouse rather than activation out of a warehouse, Fivetran's core ELT capabilities with 700+ connectors and automated schema management are purpose-built for that workflow and represent unnecessary complexity if you do not need reverse ETL.
Conversely, Hightouch remains a strong choice if you have an established, well-modeled warehouse, need advanced CDP capabilities like AI Decisioning and Adaptive Identity Resolution directly on warehouse data, and want to avoid duplicating customer data into a separate platform. Its Composable CDP approach and Agentic Marketing Platform features are particularly compelling for marketing teams at data-mature organizations.
Migration Considerations
Migrating away from Hightouch requires careful planning around several technical and operational dimensions to ensure continuity of your data activation workflows.
First, audit your current sync configurations thoroughly: document every source query, destination mapping, sync frequency, field transformation, and Customer Studio audience definition currently running in Hightouch. Most alternatives support similar destination connectors, but field mappings, sync logic, and audience membership criteria will need to be recreated in the target platform.
For teams moving to Fivetran Activations (Census), the migration is relatively straightforward since both tools follow the same warehouse-native reverse ETL pattern. The primary work involves recreating audience definitions and sync configurations in the new platform. Fivetran's acquisition of Census means the combined platform shares a unified pricing model and observability layer, and the 200+ activation destinations overlap significantly with Hightouch's connector catalog.
Migrating to Segment represents a more fundamental architectural shift. Instead of querying a warehouse and pushing data outward, you would implement Segment's SDKs and tracking API for event collection and configure Segment as the central routing layer. This requires instrumenting your applications with Segment's tracking code and potentially rethinking how data flows through your organization. The benefit is native event collection and identity resolution, but the transition demands more engineering effort.
For Polytomic migrations, the key advantage is that you can replicate Hightouch's reverse ETL syncs while also consolidating any separate ETL pipelines into the same platform. Plan to test bidirectional sync configurations carefully, especially if you are syncing data between multiple SaaS tools and databases. Polytomic's Terraform support can accelerate the migration for teams already using infrastructure-as-code practices.
When moving to Meltano, expect a higher upfront investment in pipeline configuration and infrastructure setup. The trade-off is long-term flexibility, cost savings from self-hosting, and complete independence from vendor pricing changes. Meltano's CLI-first approach means your pipeline definitions live as code in version control, which aids reproducibility, team collaboration, and disaster recovery.
Regardless of destination platform, plan for a parallel running period where both Hightouch and the new tool operate simultaneously. This allows you to validate data accuracy, sync reliability, and audience membership counts before cutting over completely. Pay special attention to identity resolution logic, audience segment definitions, and any custom transformations that may not have direct equivalents in the target platform. Budget adequate time for the migration based on the number of active syncs and the complexity of your audience definitions and transformation logic.