The best observability & monitoring tools help teams connect application behavior, infrastructure health, logs, metrics, traces, data workloads, and AI systems into actionable operational evidence. This category spans observability platforms, LLM observability, cloud native monitoring, telemetry pipelines, metrics and dashboards, log management, instrumentation standards, synthetic monitoring, data observability, error tracking, AI governance, and agent observability. The right choice depends first on the operational question you need answered, then on where telemetry originates and how much control you need over its cost and routing.
How to Choose
Start with product type. An observability platform such as New Relic is for correlating telemetry across an application and infrastructure stack to investigate root causes. Cloud native monitoring, represented here by Azure Monitor, is best when the operating environment is already centered on a cloud platform and teams need a unified view of applications, infrastructure, and networks. Metrics and dashboards tools such as Grafana focus on presenting operational data from multiple sources, while log management concentrates on storing and searching log records.
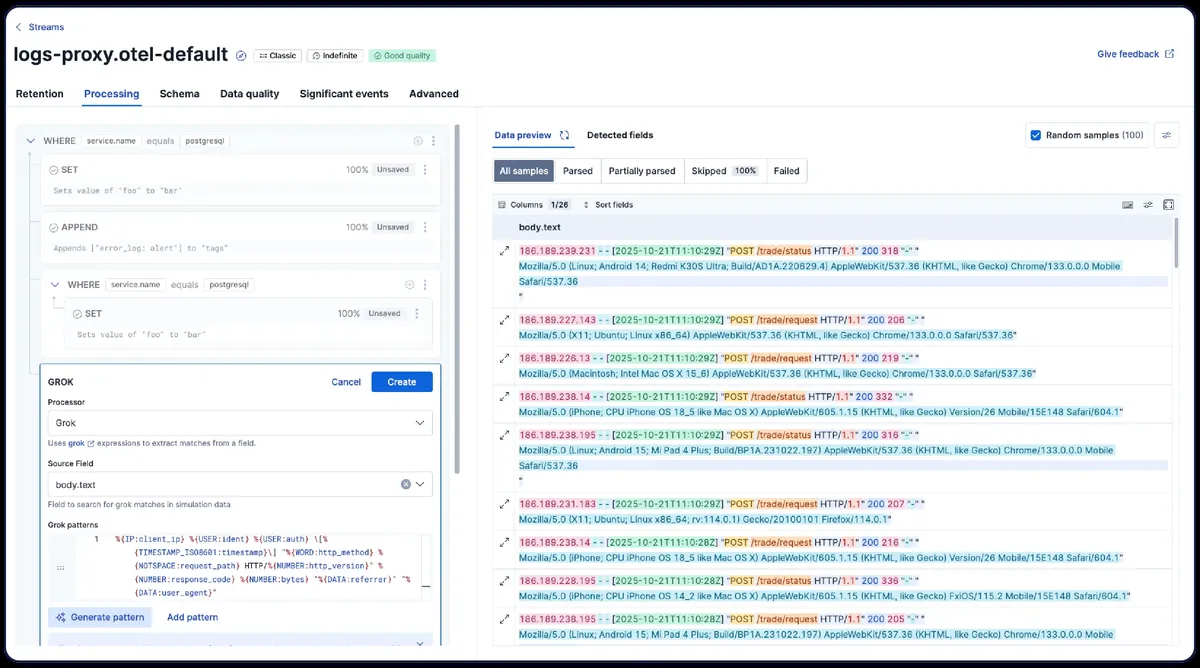
Telemetry pipelines solve a different problem: Vector collects, transforms, and routes logs and metrics before they reach a backend. OpenTelemetry is not a monitoring backend at all; it is the vendor-neutral instrumentation standard for generating, collecting, and exporting traces, metrics, and logs. Synthetic monitoring, such as Checkly, tests APIs and browser journeys from outside the application. Data observability tools address warehouse workload, latency, cost, and storage questions. LLM observability platforms such as Braintrust capture AI-product traces while making evaluation and release gating a central workflow. Error tracking, AI governance, and agent observability serve still narrower operational needs.
Then assess these criteria:
-
Instrumentation portability. OpenTelemetry provides vendor-neutral instrumentation, auto-instrumentation, context propagation, and a collector pipeline. Choose it when avoiding backend-specific application instrumentation is an architectural requirement; its software is open source, but the selected backend still creates operating cost.
-
Data-routing control. Vector is built in Rust, supports logs and metrics, provides programmable transforms through VRL, and can run as a daemon, sidecar, or aggregator. It fits teams that need to transform or redirect telemetry before it is stored, rather than treating ingestion as a fixed vendor path.
-
Cost model and ingestion discipline. New Relic and Azure Monitor use usage-based pricing, and Azure Monitor billing is primarily based on ingested data volume. New Relic includes a free tier with 100 GB of monthly ingest, so teams should establish retention and ingestion controls before broad rollout.
-
Testing workflow. Checkly uses Playwright-based browser checks, multi-step API assertions, and a JavaScript/TypeScript SDK for monitoring as code. It is the appropriate type when a broken user journey should be caught in CI/CD or from multiple monitoring regions, not merely diagnosed after telemetry arrives.
-
Data-source coverage and visualization. Grafana has a pluggable data-source model, supports Graphite, Amazon CloudWatch, Microsoft Azure, MySQL, and other SQL databases, and offers dashboard template variables. It is a strong fit when teams already own their telemetry stores and need flexible shared dashboards rather than a replacement data backend.
Top Tools
New Relic
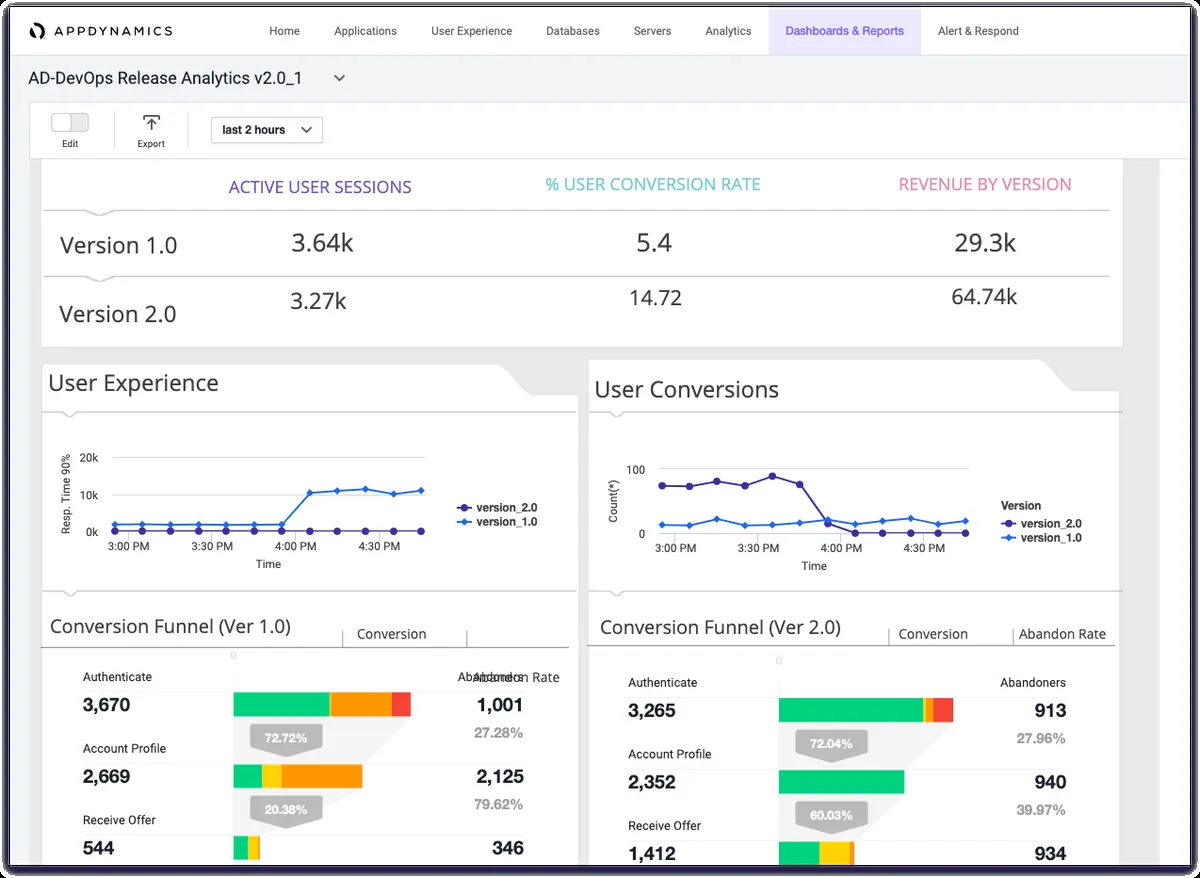
New Relic is an observability platform for web and mobile application performance management across cloud, dedicated, and hybrid environments. Its distinct capabilities include AI and agentic monitoring, OpenTelemetry support, distributed tracing, logs in context, hybrid infrastructure visibility, and more than 780 Quickstart integrations.
Best suited for: Engineering teams that need AI-assisted, full-stack telemetry correlation to isolate root causes and reduce MTTR.
Pricing: Usage-Based
The main trade-off is that teams must monitor ingest costs as observability volume grows. Datadog is a reviewed alternative; New Relic is differentiated here by its stated AI-assisted correlation, logs in context, and usage-based model.
Azure Monitor
Azure Monitor is a cloud native monitoring product for end-to-end visibility across applications, infrastructure, and networks, including hybrid and multicloud resources. It supplies curated insights with minimal configuration, centralized logs, distributed tracing, near-real-time alerts, autoscaling support, and a single-pane visualization of distributed environment data.
Best suited for: Platform teams standardized on Azure that need hybrid and multicloud visibility without adding a separate vendor.
Pricing: Usage-Based
The trade-off is ingestion-driven billing and possible additional charges for some functions. Amazon CloudWatch is a reviewed alternative; Azure Monitor is differentiated by its stated native Application Insights integration and Azure-first operating context.
Vector
Vector is a telemetry pipeline built in Rust to collect, transform, and route logs and metrics across a vendor-neutral ecosystem. Its VRL programmable transforms and deployment options as a daemon, sidecar, or aggregator make it a practical control point for shaping telemetry before it reaches storage or analysis systems.
Best suited for: Platform teams that need high-performance, programmable routing and transformation of logs and metrics.
Pricing: Enterprise
A trade-off is that the supplied evidence does not document published self-service pricing or a free tier; prospective buyers must contact Vector for pricing. It is not a substitute for a full monitoring backend when the requirement is dashboarding, incident response, or long-term telemetry analysis.
Open
Telemetry
OpenTelemetry is an open-source instrumentation standard, not a standalone observability destination. It provides vendor-neutral APIs, libraries, agents, collector services, auto-instrumentation, context propagation, and multi-language support for traces, metrics, and logs.
Best suited for: Engineering teams that want portable instrumentation and the ability to choose or change the telemetry backend.
Pricing: Open Source
The trade-off is that OpenTelemetry does not remove backend costs: those arise from the observability system selected to receive the data. Its value is standardizing collection and export, rather than supplying dashboards or a managed storage layer.
Checkly
Checkly is a synthetic monitoring platform built around monitoring as code. Teams can define Playwright or Puppeteer browser checks and HTTP assertions in JavaScript or TypeScript, run them from multiple regions, integrate checks into CI/CD, and use visual regression testing on Team and higher plans.
Best suited for: DevOps teams that want browser journeys and API checks versioned in Git alongside application code.
Pricing: Freemium from $24.00/mo
Its trade-off is scope: synthetic checks validate externally observable journeys and APIs, but do not replace broad telemetry collection for internal root-cause investigation. Better Stack is a reviewed alternative; Checkly separates itself through its code-first model and Playwright-native browser checks.
Grafana
Grafana is an open-source metrics and dashboards platform for visualizing metrics, logs, and traces. Its pluggable data-source model supports sources including Graphite, Amazon CloudWatch, Microsoft Azure, MySQL, and other SQL databases, while template variables enable dynamic dashboards.
Best suited for: Infrastructure and data teams that need flexible operational dashboards over existing telemetry and database sources.
Pricing: Freemium from $19.00/mo
The trade-off is that Grafana’s strength is visualization and source connectivity; teams still need to decide where telemetry is collected and stored. Grafana Cloud is a permitted alternative, while Grafana itself is the open-source platform described here.
Free Snowflake Observability Tool
Free Snowflake Observability Tool is a data observability and FinOps tool focused on Snowflake workload performance and cost. It provides end-to-end workload latency by warehouse and user, a costly-query leaderboard with AI suggestions, cluster idle-time monitoring, and storage recommendations.
Best suited for: Small, cost-conscious data teams seeking Snowflake usage, performance, and cost visibility without additional software spend.
Pricing: Free
The key limitation is that the available evidence does not establish enterprise-scale capabilities. It is purpose-built around Snowflake operational questions, so buyers needing broader application or infrastructure telemetry should evaluate a different product type.
Braintrust
Braintrust is an LLM observability platform built around evaluation-first AI development. It supports versioned datasets and experiments, side-by-side prompt and model comparison, scoring by LLM judge, code, or humans, scored CI evaluations that can block releases, and production logging of agent traces and tool calls.
Best suited for: Teams making scored LLM evaluations a release-gating discipline for AI products.
Pricing: Freemium from $249.00/mo
The supplied evidence does not identify a product limitation; its documented trade-off is a focused evaluation-first approach rather than a general-purpose infrastructure monitoring platform. Langfuse is a reviewed alternative; Braintrust is differentiated by versioned evaluation datasets and release blocking based on failing scores.
Comparison Table
These products do not compete in one interchangeable market. The table is a routing guide: select the type that matches the system and operational question, then validate deployment, ingestion, retention, and procurement requirements.
| Tool | Type | Best For | Pricing | Key Strength |
|---|---|---|---|---|
| New Relic | observability platform | Full-stack root-cause investigation | Usage-Based | AI and agentic monitoring, distributed tracing, logs in context |
| Azure Monitor | cloud native monitoring | Azure-centered hybrid and multicloud operations | Usage-Based | Centralized logs, distributed tracing, alerts, autoscaling |
| Vector | telemetry pipeline | Telemetry transformation and routing | Enterprise | Rust performance, VRL transforms, flexible deployment |
| OpenTelemetry | instrumentation standard | Portable telemetry instrumentation | Open Source | Vendor-neutral APIs, collectors, auto-instrumentation |
| Checkly | synthetic monitoring | Git-managed browser and API checks | Freemium from $24.00/mo | Playwright checks, CI/CD integration, multi-step assertions |
| Grafana | metrics and dashboards | Dashboards across existing data sources | Freemium from $19.00/mo | Pluggable sources and dynamic dashboards |
| Free Snowflake Observability Tool | data observability | Snowflake workload and cost visibility | Free | Query-cost leaderboard and workload latency |
| Braintrust | LLM observability | Evaluation-gated AI releases | Freemium from $249.00/mo | Versioned datasets, scored evals, production trace feedback |
Our Methodology
We evaluate observability & monitoring products using vendor documentation, stated product capabilities, published pricing information, editorial assessment, and available public adoption signals such as user ratings and review counts. Product evidence matters most: a claim is included only where the available material documents a concrete capability, deployment model, pricing structure, or workflow.
Public ratings can be useful signals of user experience, but they are not proof of enterprise adoption, implementation quality, security posture, or fit for a particular architecture. For example, New Relic’s available evidence includes a 7.9/10 rating from 353 reviews, and Grafana’s includes an 8.6/10 rating from 157 reviews; neither figure establishes which tool is right for a specific deployment.
We also distinguish product types instead of forcing a single ranking. OpenTelemetry and Vector can support an observability architecture without replacing a dashboarding or monitoring backend. Similarly, Checkly tests user-facing behavior, while Braintrust evaluates AI-product outputs. Where the evidence does not establish a capability, price detail, or limitation, we leave it unstated rather than infer it.
Frequently Asked Questions
Should we choose an observability platform or a telemetry pipeline?
Choose an observability platform such as New Relic when the main need is correlating telemetry to investigate operational root causes. Choose Vector when the main need is to collect, transform, and route logs and metrics before they reach a destination. Vector supports VRL programmable transforms and can run as a daemon, sidecar, or aggregator. The two can be complementary: a pipeline controls the telemetry path, while a platform analyzes the telemetry after delivery.
When should we use Open
Telemetry?
Use OpenTelemetry when vendor-neutral instrumentation is a requirement. It supplies APIs, libraries, agents, auto-instrumentation, context propagation, and collector services for traces, metrics, and logs. It is fully open source and free, but it is not a hosted telemetry backend. Costs come from the backend chosen to receive and retain its data.
Is Grafana a replacement for cloud monitoring?
Grafana is best understood as a visualization and dashboarding platform with a pluggable data-source model. It can connect to Amazon CloudWatch, Microsoft Azure, Graphite, MySQL, and other SQL databases, enabling shared views across existing sources. Azure Monitor, by contrast, provides centralized logs, distributed tracing, alerts, and autoscaling support for cloud native monitoring. Use Grafana when flexible visualization over current sources is the priority; use Azure Monitor when Azure-centered monitoring capabilities are the requirement.
How should AI teams evaluate Braintrust versus synthetic monitoring?
Braintrust is for AI-product evaluation: it supports versioned datasets, prompt and model comparisons, scored evaluations, release blocking, and production logging of agent traces and tool calls. Checkly is for synthetic browser and API checks, using Playwright-based browser monitoring and HTTP assertions. A failed Checkly check identifies a broken user journey or API behavior, while a failing Braintrust score evaluates AI output against a defined evaluation process. Teams operating AI applications may need both workflows for different failure modes.