Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Honeycomb states |
|---|---|
Billing basis | Pay by event volume, with no charge for adding fields or users; the pricing page lists unlimited seats and unlimited querying |
Instrumentation | OpenTelemetry-native; Honeycomb also maintains libhoney-go, an Apache-2.0 Go library (Go 1.19+) for sending events |
Deployment and network | Support for Honeycomb Private Cloud and AWS PrivateLink are listed on the Enterprise plan |
Security | SOC 2 Type II certified, with regular independent penetration testing; SSO starts on Pro |
Ways to evaluate | A Free plan described as free forever, and a sandbox to explore with no signup required |
Our take
Honeycomb is a good fit if your team debugs distributed services or LLM-backed features by asking new questions of production data, rather than reading a fixed set of dashboards. If you expect to run at Enterprise volumes, plan for a sales conversation early, because that tier is priced as a custom plan.
Evaluate Honeycomb
Popular comparisons
Where it stands out
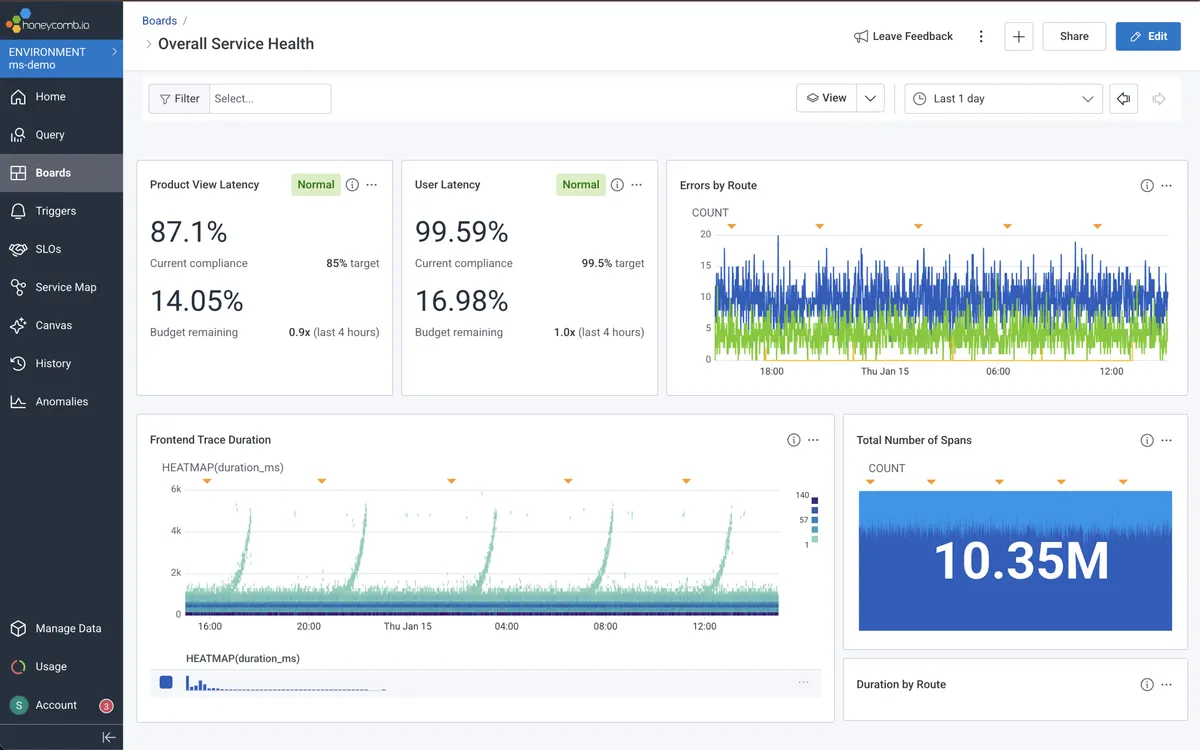
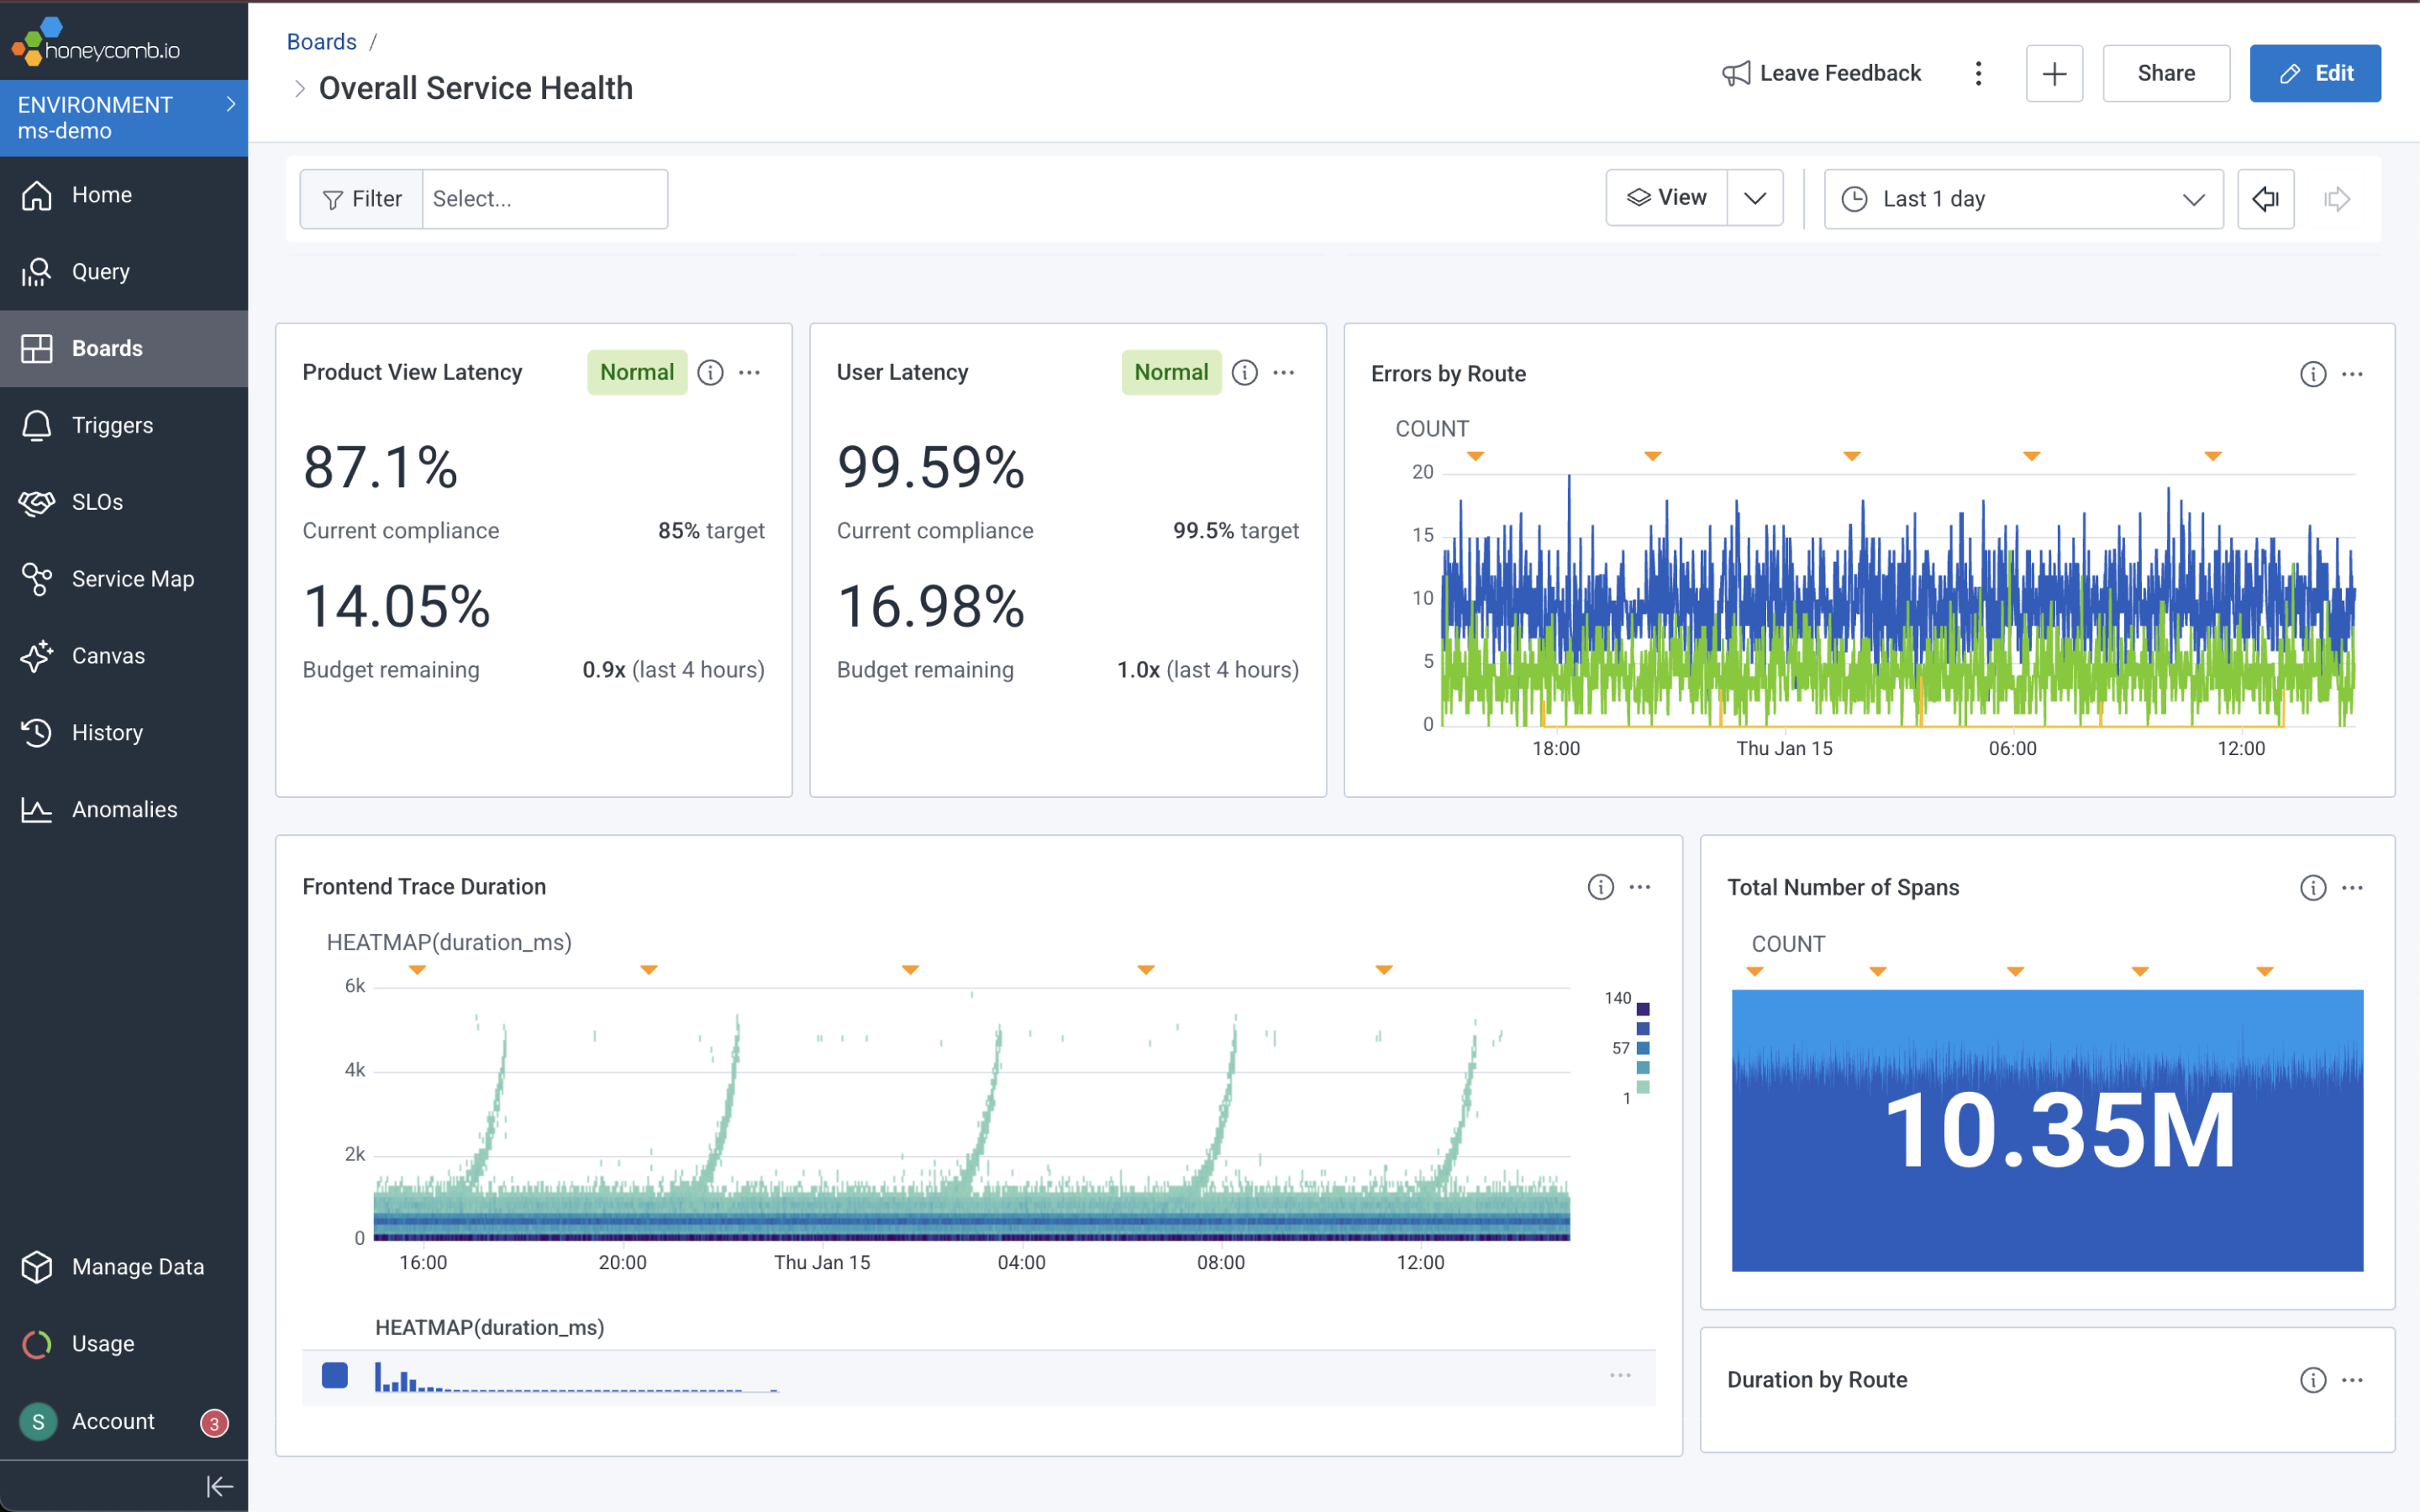
Querying without pre-aggregation. Honeycomb says its high-cardinality, event-based foundation lets engineers query production data in real time with "no sampling tricks, no preaggregation", and that its columnar data store gives sub-second query times. This matters when an incident needs a question nobody built a dashboard for.
BubbleUp for outliers. BubbleUp detects outliers and lets you drill into them across traces, metrics or logs. It is included from the Free plan, along with distributed tracing.
AI debugging tools on the Free plan. The Free plan lists Canvas AI Copilot, Honeycomb MCP and Agent Timeline. Agent Timeline shows LLM calls, tool invocations and agent handoffs in order, and Honeycomb MCP gives coding agents production context from the IDE.
SLO-based alerting. SLOs let teams define what good looks like and alert when a service falls below it, without alerting on noise. Honeycomb says every SLO is debuggable.
Product screenshot
Trade-offs to weigh
SLO count shapes the plan choice. A reliability program with more than two SLOs outgrows Pro and moves into a custom-priced Enterprise contract.
Several platform features sit on Enterprise only. Service Map, the Query Data API, the SLO Reporting API and Enterprise support for Refinery appear only in the Enterprise column, so a Pro evaluation will not show them.
Event volume drives the bill. Because pricing follows events, how much you instrument and send decides cost. Honeycomb offers expert help to keep the data you send focused while keeping costs predictable.
Pricing and plan conditions
Plans are set by monthly event volume and metrics data points. Pro is priced in steps: starting at $150 per 50M events and 250M time series data points, up to 750M events and 3.75B data points per month, on a monthly or annual subscription. Enterprise starts with a base allowance of 10 billion events per year, with volume discounts and extra capacity on request. Telemetry Pipeline (OpenTelemetry processing and fleet management) is priced separately, starting at $0.10 / GB.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Free | Free | Up to 20M events and up to 100M metrics data points per month; 2 Triggers, Distributed Tracing, BubbleUp, OpenTelemetry Support, Team Query History, Query Result Permalinks, Honeycomb Metrics, Canvas AI Copilot, Honeycomb MCP, Agent Timeline |
Pro | Starting at $150 per month | Up to 750M events and up to 3.75B metrics data points per month; all features from the Free Plan, plus 100 Triggers, 2 SLOs, Single-Sign On (SSO) and Honeycomb Support |
Enterprise | Custom plans; request a trial or a quote | Variable event volume; all features from the Pro Plan, plus starts with 300 Triggers and 100 SLOs, Service Map, Enterprise Support for Refinery, Enterprise-Grade Support + Onboarding, Query Data API, AWS PrivateLink, SLO Reporting API, Support for Honeycomb Private Cloud. Add-ons: frontend performance analysis, enterprise-grade alerting, installation and enablement services |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
3 GitHub commits 90d58 GitHub stars0 vulnerabilities across 2 packages
See all signals from 6 sources
npm · @honeycombio/opentelemetry-web@1.5.1 · PyPI · honeycomb-beeline@3.6.0
Alternatives to Honeycomb
The reviewed substitutes for Honeycomb among the observability platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Datadog
- Choose Datadog when you want a single vendor for the full observability stack and can afford the at-scale bill.Applies to: Choosing between these two for the apm observability decision.
- Dynatrace
- Choose Dynatrace when compliance, audit-ability, and automated diagnostics outweigh cost concerns — typically in regulated industries or orgs over 1,000 employees.Applies to: Choosing between these two for the apm observability decision.
- Elastic Observability
- Choose Elastic when your team is already fluent in Elasticsearch or when full-text log search at scale matters.Applies to: Choosing between these two for the apm observability decision.
- Observe
- Observe and Honeycomb help engineers investigate incidents by asking questions of their telemetry. Honeycomb is known for sub-second queries over high-detail trace and event data, while Observe correlates logs, metrics and traces stored in a data lake and offers an AI SRE that suggests fixes.Applies to: Choosing between these two for the apm observability decision.
- New Relic
- Choose New Relic when you want less configuration and more out-of-the-box coverage, or when AI-driven root-cause analysis matters more than ad-hoc event querying.Applies to: Choosing between these two for the apm observability decision.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Grafana Loki
- The fork is the shape of the data rather than the price of it. Honeycomb is built around wide structured events queried at high cardinality for debugging unknown-unknowns; Loki is a log store that indexes labels and keeps bodies in object storage. A team that has decided its telemetry is events rather than log lines is not shopping for a log store at all.
Head to head
See detailed alternatives analysis
Looking for Honeycomb alternatives? Honeycomb is the observability platform built around high-cardinality event data and BubbleUp-style anomaly detection, priced with a generous Free tier (20M events/month, 60-day retention) jumping to Pro at $150/month. Teams evaluate alternatives when the pricing jump from Free to Pro is too steep for their budget, when they need broader observability (infrastructure monitoring, full log management) that Honeycomb doesn't handle, or when they want a more mature OpenTelemetry backend with different trade-offs. Below, nine observability platforms worth evaluating — with honest trade-offs, DB-verified pricing, and clear guidance on when each one is the better choice.
Top Alternatives Overview
Datadog is the industry-standard broad observability platform. Free for up to 5 hosts, then Infrastructure Pro at $15 per host per month billed annually (usage-based add-ons extra). Datadog's strengths are breadth and polish — APM, infrastructure monitoring, logs, RUM, and synthetics in one product with consistent UX. Honeycomb's event model is sharper for high-cardinality investigation, but Datadog covers workflows Honeycomb doesn't (infra metrics, RUM, synthetics). Choose Datadog when you want a single vendor for the full observability stack and can afford the at-scale bill.
New Relic is full APM with AI-powered insights; Standard is $10 for the first full platform user and $99 per additional user, plus $0.40 per GB of data. New Relic auto-instruments Java, .NET, Node, Python, Go, and PHP applications without the OpenTelemetry-first setup Honeycomb requires. The 780+ quickstart integrations form an extensive ecosystem, alongside Honeycomb's ecosystem. Choose New Relic when you want less configuration and more out-of-the-box coverage, or when AI-driven root-cause analysis matters more than ad-hoc event querying.
Grafana Cloud takes the open-source approach with a managed Grafana stack (Loki for logs, Tempo for traces, Mimir for metrics). Freemium with vendor-quoted enterprise pricing. Grafana Cloud doesn't match Honeycomb's BubbleUp-style investigation UX but covers the broader observability stack (metrics, logs, traces) with more consistency. Choose Grafana Cloud when you already live in the Grafana ecosystem or want open-source portability.
Observe takes a streaming-data-lake approach, priced at $0.49 per GB for logs with additional tiers at $0.00, $0.01, and $0.59. Observe and Honeycomb are architectural peers — both reject the metrics-and-logs model in favor of event-centric storage. Honeycomb leans engineering-workflow (BubbleUp, OpenTelemetry-first), Observe leans data-lake-analytics (streaming queries over long time ranges). Either works for similar teams.
Dynatrace targets large enterprises with vendor-quoted pricing (no published rate card). Its differentiator is the Davis AI engine for automated root-cause analysis across metrics, traces, and logs. The OneAgent deployment model is simpler than OpenTelemetry setup. Choose Dynatrace when compliance, audit-ability, and automated diagnostics outweigh cost concerns — typically in regulated industries or orgs over 1,000 employees.
Sentry focuses specifically on application error tracking with stack-trace grouping, starting with a free Developer tier and Team at $26/month. For the "what broke and who fixed it" workflow, Sentry is sharper than Honeycomb; for broader observability investigation, Honeycomb wins. Most teams pair them: Sentry for errors, Honeycomb for high-cardinality investigation of everything else.
Splunk handles observability as a byproduct of log analytics — Splunk Community Edition is free (self-hosted, single-user); Splunk Enterprise uses custom pricing. SPL's query expressiveness is strong but the workflow is log-centric rather than event-centric. Choose Splunk when security and compliance drive your observability stack and high-cardinality event querying is a secondary need.
Elastic Observability is the managed Elasticsearch play — Elastic Cloud Hosted Standard at $99/month, Platinum at $131/month, Enterprise at $184/month, based on a production setup with 120 GB storage in 2 zones. Elasticsearch's full-text search is valuable for log-heavy workloads but the event-centric investigation workflow is less mature than Honeycomb's. Choose Elastic when your team is already fluent in Elasticsearch or when full-text log search at scale matters.
Amazon CloudWatch is AWS's native observability, free tier plus per-unit usage billing from $0.50 per GB of metric ingestion. CloudWatch handles infrastructure monitoring and logs well but has no high-cardinality event query equivalent to BubbleUp. Pair CloudWatch with Honeycomb: CloudWatch for AWS infra metrics, Honeycomb for application-layer high-cardinality investigation.
Architecture and Approach Comparison
These platforms split into three architectural camps. Honeycomb, Observe, and (to a lesser extent) Elastic Observability are event/data-lake platforms — they store full-fidelity events and query them ad-hoc rather than pre-aggregating into metrics. Datadog, New Relic, and Dynatrace are agent-based full-stack platforms that collect metrics, logs, and traces via proprietary SDKs, storing them in purpose-built backends with polished visualization layers. Grafana Cloud (with Prometheus + Loki + Tempo), CloudWatch, and Azure Monitor are composable stacks where metrics, logs, and traces are separate data types with separate query languages. Honeycomb's distinctive approach is rejecting the cardinality penalty that all metrics-based tools impose — every attribute is queryable without pre-declaring it as a metric. This architectural choice pays off for engineering teams running distributed systems and costs you for basic infrastructure monitoring where metrics-based tools are simpler and cheaper. The practical implication: switching from Honeycomb to any metrics-based tool requires re-thinking what you monitor, not just replacing the vendor.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Free Tier | Paid Plans (starting) | Focus Area / Key Differentiator |
|---|---|---|---|
| Honeycomb | Yes — up to 20M events/month and 100M metrics data points/month | Pro starts at $150 per month; Enterprise offers custom plans | Distributed tracing, BubbleUp, OpenTelemetry support, and Honeycomb Metrics |
Honeycomb’s Free plan is described as free forever. Pro includes up to 750M events per month and up to 3.75B metrics data points per month, with monthly or annual subscriptions. Enterprise has variable event and metrics allowances; its plans start with a base allowance of 10 billion events per year, and Honeycomb invites buyers to request a tailored Enterprise quote. The public documentation does not provide current pricing evidence for the alternative tools, so a like-for-like price comparison is not supported here.
When to Consider Switching
The Free-to-Pro pricing jump is too steep — Honeycomb Pro starts at $150 per month. Its Free plan includes up to 20M events per month and 100M metrics data points per month, while Pro includes up to 750M events per month and 3.75B metrics data points per month. Buyers should confirm the event and metrics capacity they need, whether a monthly or annual Pro subscription fits their requirements, and the terms of any Enterprise quote. Honeycomb describes Enterprise capacity as variable and says Enterprise plans start with a base allowance of 10 billion events per year; tailored Enterprise quotes are available on request.
Migration Considerations
Honeycomb-to-alternative migrations depend heavily on where you're going. Moving to Datadog, New Relic, or Dynatrace means re-instrumenting with their SDKs — the OpenTelemetry investment you made for Honeycomb mostly carries over (OTel data can flow to most modern backends), but vendor-specific features (BubbleUp, Honeycomb Intelligence) don't translate. Plan for 2-4 weeks of parallel running to validate alarm parity and dashboard rebuilds. Moving to Grafana Cloud or self-hosted Grafana is the smoothest path if you're already OpenTelemetry-first — Grafana Tempo accepts OTel traces natively. Moving to CloudWatch or Azure Monitor means giving up high-cardinality querying entirely; do this only if you're simplifying from full observability to basic infrastructure monitoring. For teams moving to Sentry, keep Honeycomb for non-error observability and let Sentry specialize in error grouping — they coexist well. Don't migrate during peak season; observability gaps during cutover are expensive. Finally, confirm data-retention parity — Honeycomb's 60-day retention is generous and alternatives may charge more for equivalent retention.