Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What the Prometheus project states |
|---|---|
License | Apache 2 License for all components; the project calls itself 100% open source and community-driven. |
Installation | Precompiled binaries for released versions (the latest production release binary is the recommended way), Docker images on Quay.io and Docker Hub, or a build from source with Go, NodeJS and npm version 10 or greater. |
Operating model | You run the servers. Each Prometheus server operates independently and relies only on local storage; the binaries are statically linked Go programs. |
Data scope | Metrics stored as time series, each identified by a metric name and a set of key-value pairs. |
Collection | HTTP pull model. Targets come from service discovery or static configuration; batch jobs can push time series through an intermediary gateway. |
Alerting | Alerting rules are written in PromQL; a separate Alertmanager component handles notifications and silencing. |
Governance | Cloud Native Computing Foundation graduated project, the second to graduate after Kubernetes. |
Our take
Prometheus is a sound choice if you run services on Kubernetes or other cloud and container managers and your team is ready to install and operate its own monitoring servers. If nobody on the team will own that operating work, settle who will before you adopt it.
Evaluate Prometheus
Popular comparisons
See all 6 Prometheus comparisons
Where it stands out
Follows changing services. Prometheus integrates with Kubernetes and other cloud and container managers to continuously discover and monitor your services, so monitoring keeps up as workloads move.
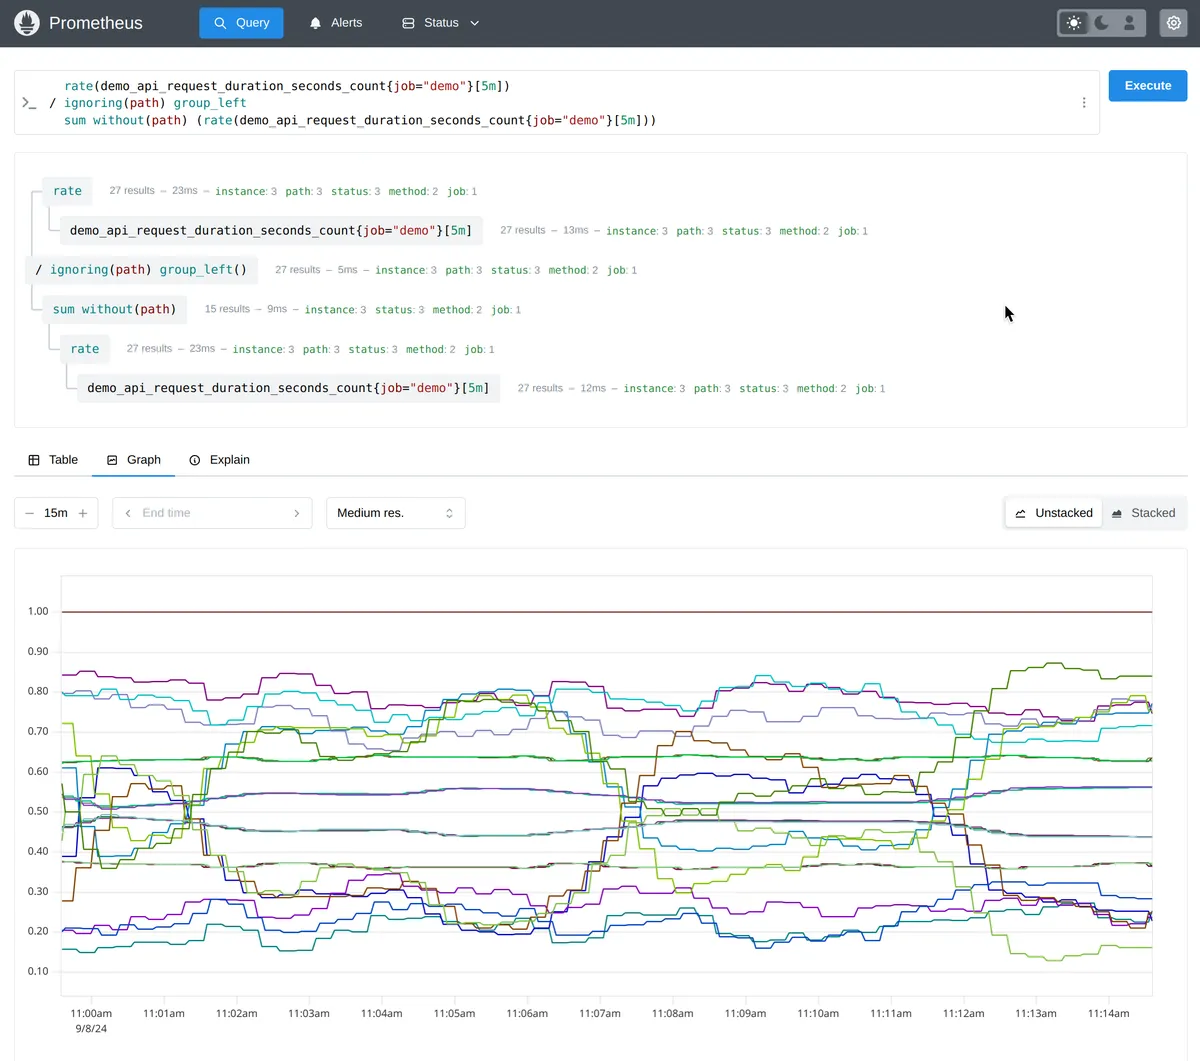
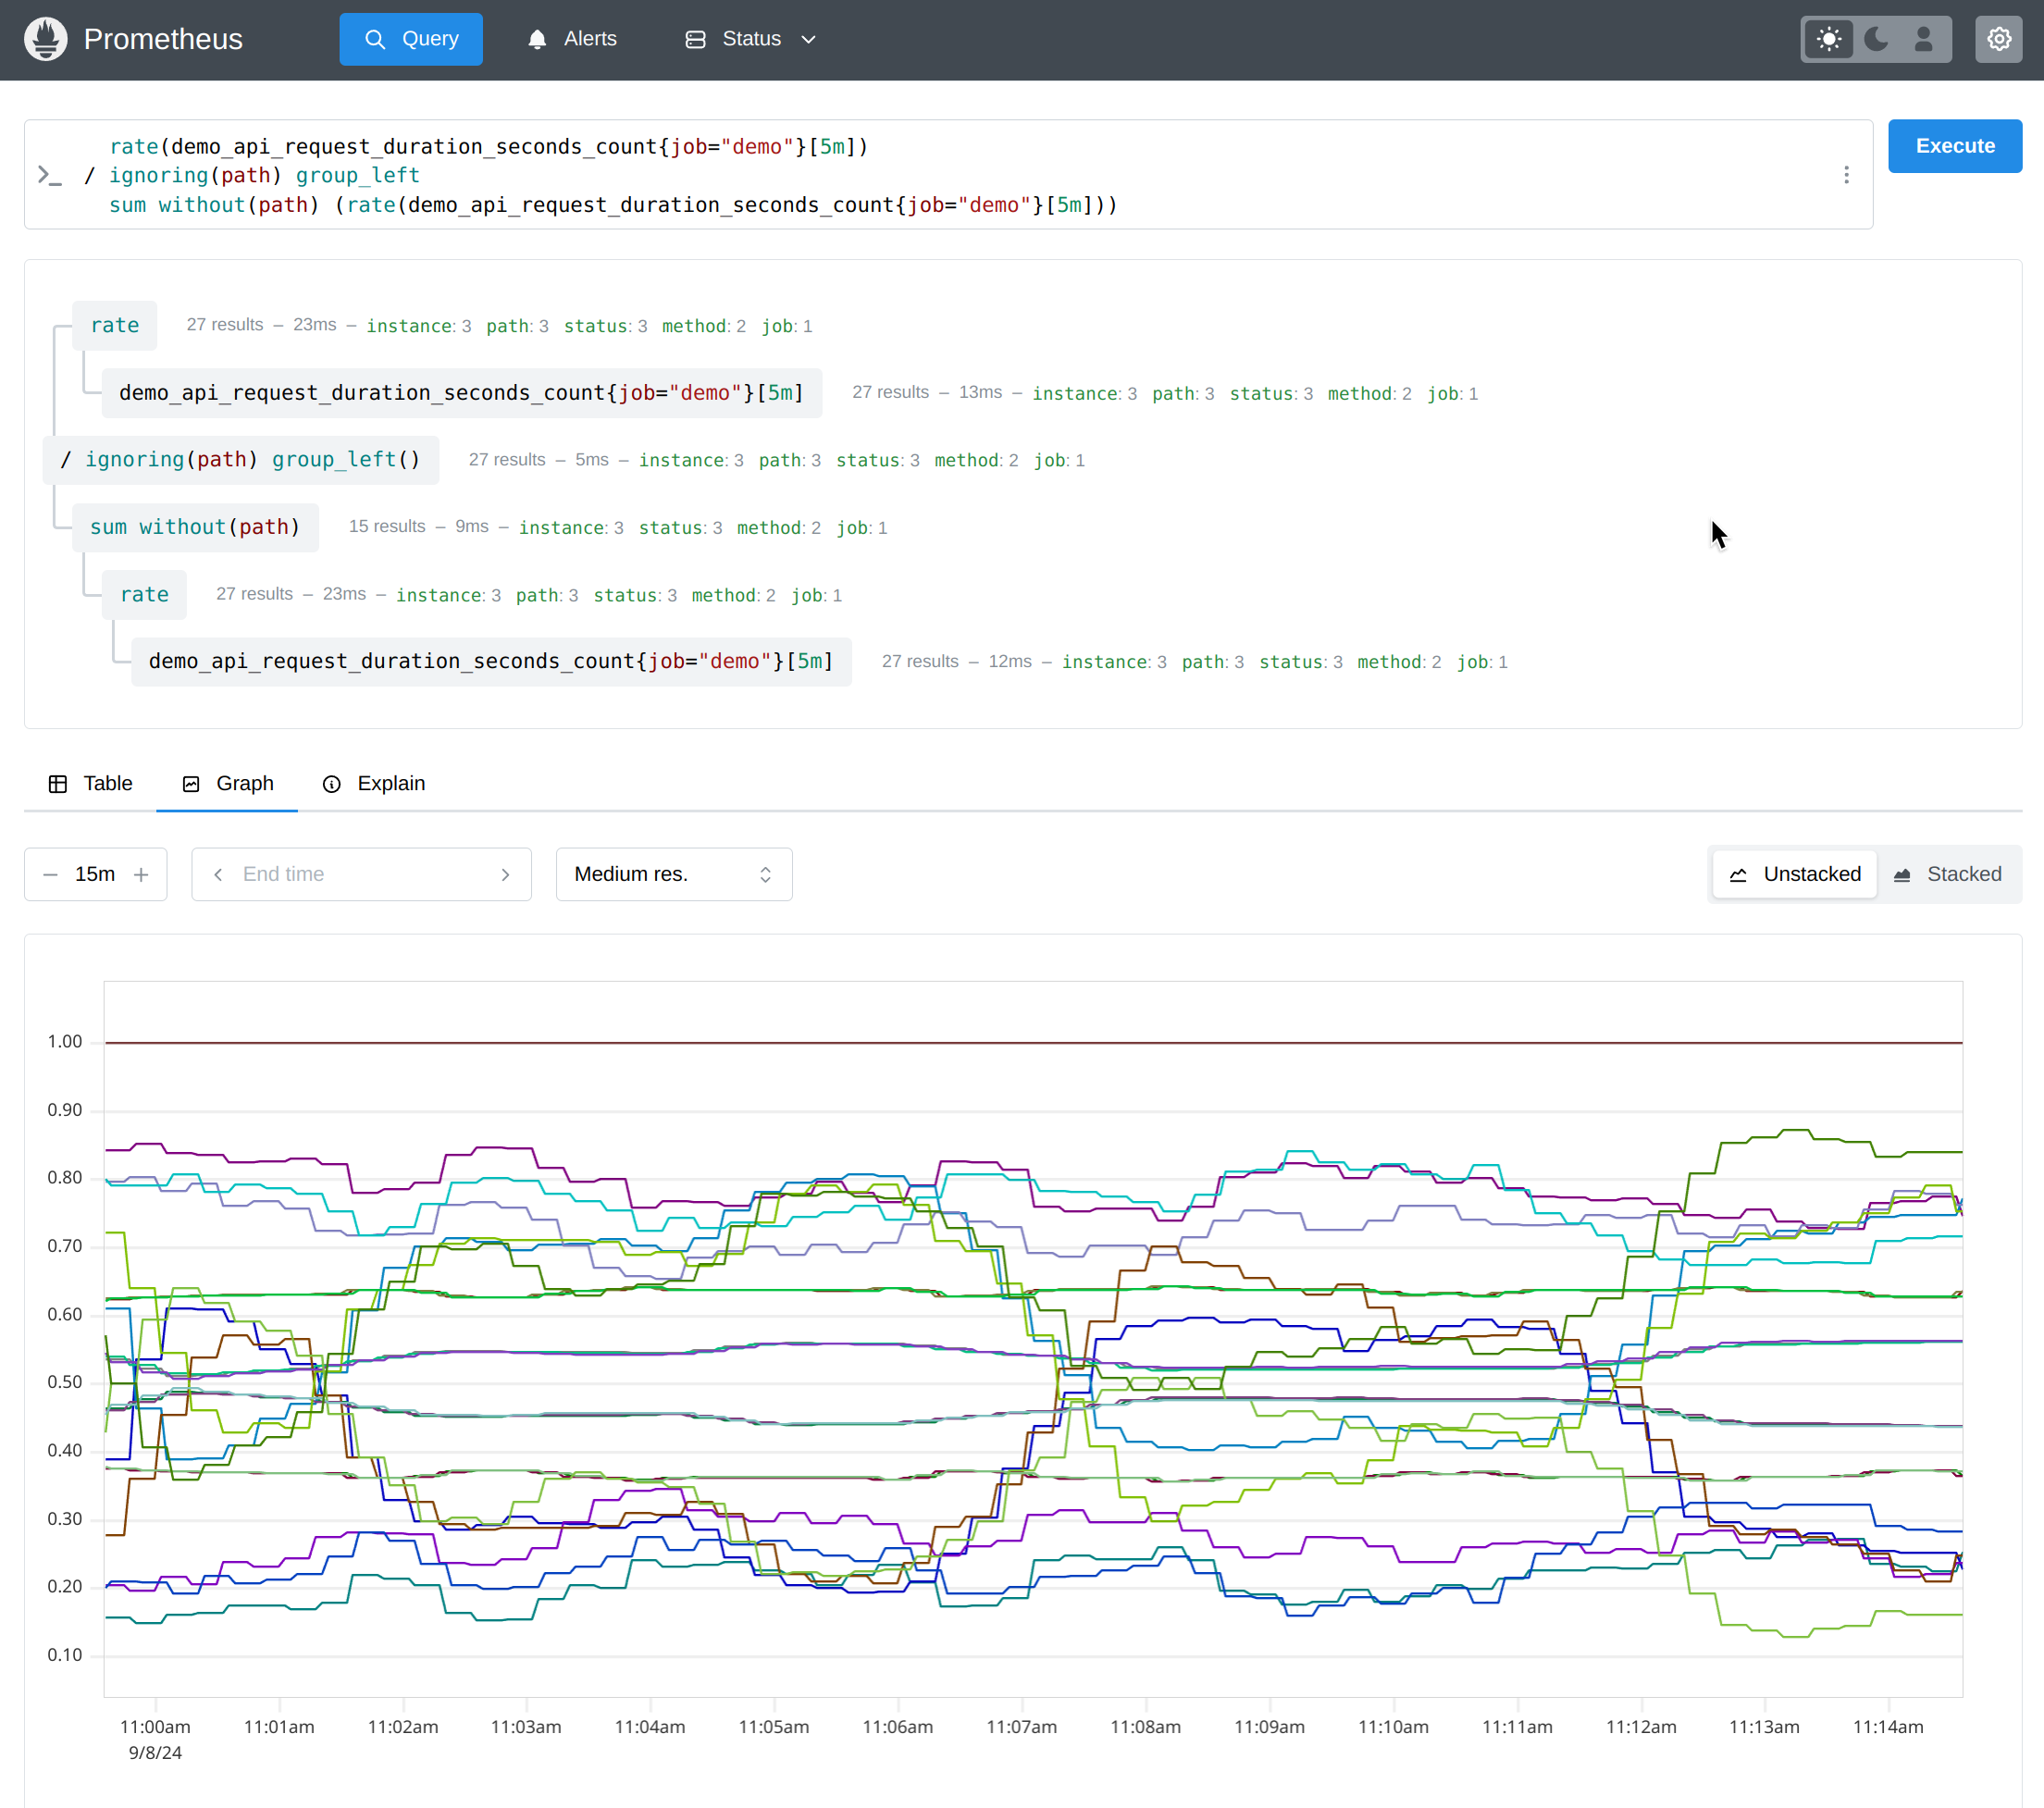
One query language for charts and alerts. PromQL can query, correlate and transform time series for visualizations and alerts, and alert rules use it with the full dimensional data model, so a dashboard query can become an alert.
Broad instrumentation. The project points to hundreds of official and community-contributed integrations for extracting metrics from existing systems, plus instrumentation libraries that cover most major languages.
Quick to try. A single
docker runcommand starts a container that is reachable at http://localhost:9090/, which makes a first evaluation cheap in time.Grows by federation. Prometheus supports hierarchical and horizontal federation, so separate servers can be linked as an estate grows.
Product screenshot
Trade-offs to weigh
Capacity planning is yours. Because each server keeps its own data, your team sizes disks per server and decides how servers are linked as the estate grows.
Batch jobs add a component. If you monitor short-lived batch work, plan to deploy and run the push gateway alongside the servers.
Alerts need a second service. A working alert path means running and configuring Alertmanager as well as Prometheus itself.
Not built for embedding. The prometheus/prometheus repository builds a stand-alone program and is not designed for use as a library; its internal Go APIs may break between minor user-facing releases. Go teams should use reusable libraries such as prometheus/common and prometheus/client-golang instead.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
902 GitHub commits 90d67.6k GitHub stars0 vulnerabilities across 2 packages
See all signals from 9 sources
npm · prom-client@15.1.3 · PyPI · prometheus-client@0.26.0
Alternatives to Prometheus
The reviewed substitutes for Prometheus among the metrics & dashboards, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Datadog
- Datadog and Prometheus both collect metrics from infrastructure and applications and alert on them. Prometheus is open-source software the team hosts and maintains, with PromQL and Kubernetes service discovery built in, while Datadog is a commercial SaaS platform that adds logs, traces and dashboards with no servers to run. Teams willing to operate their own stack lean to Prometheus.Applies to: Whether monitoring is assembled from open-source components or bought as a platform.
- Dynatrace
- Prometheus and Dynatrace both monitor applications and infrastructure and raise alerts. Prometheus is open source, so the team runs it, configures scraping and builds dashboards and alerts itself. Dynatrace is a commercial platform that discovers services automatically and uses AI to find root causes, so less is assembled by hand.Applies to: Whether monitoring is assembled from open-source components or bought as a platform.
- New Relic
- New Relic and Prometheus both measure how services behave and alert teams when they degrade. New Relic is a SaaS platform with code-level diagnostics that correlates telemetry across the whole stack, while Prometheus is open-source metrics software that a team deploys, scales and wires into dashboards itself. That trade between buying a platform and running open-source parts decides the pick.Applies to: Whether monitoring is assembled from open-source components or bought as a platform.
- Observe
- Observe and Prometheus can each be the place where a team monitors its systems. Prometheus is open-source metrics collection with PromQL and alerting, while Observe is a commercial platform that stores logs, metrics and traces in one data lake for search and correlation. A stack built on open metrics tooling points to Prometheus, and one seeking a single store for all telemetry points to Observe.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
- Splunk
- Splunk and Prometheus can both watch systems and alert when something goes wrong. Splunk indexes and searches machine data such as logs in one commercial repository, while Prometheus is an open-source tool that pulls metrics and queries them with PromQL. The pick depends on whether monitoring is built around searching logs or around time-series metrics.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
- InfluxDB
- Prometheus and InfluxDB both store time-series metrics and query them for monitoring. Prometheus is a complete open-source monitoring system that pulls metrics, alerts on them and discovers Kubernetes services, while InfluxDB is a general time series database from InfluxData that also serves sensor data, offered open source, in the cloud or as an enterprise edition. Whether the stack needs a monitoring system or a database to build on decides the pick.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Grafana Loki
- Different signals in the same stack: Prometheus holds the metrics, Loki holds the logs, and Loki's label model was designed to match Prometheus's so the two can be queried the same way. This is the pairing the guidance assumes when it calls Loki the natural fit for a Prometheus and Grafana shop.
Head to head
See detailed alternatives analysis
If you are evaluating Prometheus alternatives, you are likely looking for a monitoring and observability solution that better fits your team's operational needs, budget, or scaling requirements. Prometheus is the open-source monitoring standard for cloud-native environments, built around a pull-based metrics collection model, the PromQL query language, and native Kubernetes service discovery. Written in Go with over 63,000 GitHub stars and an Apache 2.0 license, it is a CNCF graduated project and the second project to graduate after Kubernetes. However, teams often outgrow single-server Prometheus deployments or need capabilities beyond pure metrics, such as log management, distributed tracing, or managed infrastructure. Below is a practical comparison of seven leading Prometheus alternatives in the Observability & Monitoring space.
Top Alternatives Overview
Datadog is a cloud-scale monitoring and observability platform that unifies metrics, logs, traces, and security monitoring into a single SaaS product. Where Prometheus requires you to self-host and manage your own time-series database, Datadog offers a fully managed experience with agent-based collection, real-time dashboards, and integrations spanning infrastructure, APM, log management, synthetic monitoring, and real user monitoring. Datadog follows a usage-based pricing model with a free tier available. Rated 8.6/10 across 346 reviews, users frequently highlight its powerful data visualization, log management, REST API access, and time-series capabilities. Common drawbacks cited include a steep learning curve and cost escalation at scale.
Grafana Cloud is a fully managed observability platform built on leading open-source tools including Grafana, Mimir (for metrics), Loki (for logs), and Tempo (for traces). For teams already using Prometheus, Grafana Cloud offers a natural upgrade path since it natively supports PromQL and can act as a remote-write backend for existing Prometheus instances. Rated 8.6/10 across 157 reviews, it follows a freemium pricing model with a free tier available. Grafana Cloud is particularly strong for teams that want to retain the open-source Prometheus ecosystem while gaining managed long-term storage, high availability, and a unified observability experience across metrics, logs, and traces.
New Relic is an AI-powered observability platform that correlates telemetry across the entire stack, covering application performance monitoring, infrastructure monitoring, log management, and alerting. Rated 7.9/10 across 353 reviews, it offers a usage-based pricing model with a free tier available. New Relic positions itself as a full-stack replacement for Prometheus by providing code-level diagnostics, distributed tracing, and browser monitoring in a single managed platform. It uses TLS encryption for data security and integrates with hundreds of technologies out of the box.
Dynatrace is an AI-powered observability platform focused on automated instrumentation, root cause analysis, and full-stack monitoring for large enterprise environments. Rated 8.4/10 across 617 reviews, it uses a usage-based pricing model. Dynatrace distinguishes itself through its OneAgent auto-instrumentation, Smartscape topology mapping, and the Grail data lakehouse for unified data storage and analysis. Users consistently praise its automated root cause analysis and end-to-end monitoring, though some cite the licensing model complexity as a drawback.
Elastic Observability is a full-stack observability solution built on the Elastic Stack (Elasticsearch, Kibana, Beats, Logstash), offering log analytics, APM, infrastructure monitoring, and AIOps capabilities. It supports over 450 integrations and is standardized on OpenTelemetry, positioning itself as a search-first observability platform that leverages Elasticsearch for fast querying across petabytes of log and metric data. Elastic's logsdb index mode can reduce data footprint by up to 65%. Deployment options include self-hosted, cloud, and serverless.
Splunk is an enterprise-grade platform for searching, monitoring, and analyzing machine-generated data. Rated 8.6/10 across 542 reviews, it offers a freemium model with a free community edition for self-hosted deployments. Splunk excels at processing massive volumes of unstructured data with its proprietary schema-on-read technology and is backed by a community of over 13,000 active members and 2,800+ apps on Splunkbase. It is widely adopted in enterprises with strong security and compliance requirements.
Observe is a modern observability platform built on a streaming data lake architecture, designed for faster search and correlation at lower cost. It follows a usage-based pricing model. Observe differentiates itself through its data lake approach and AI SRE capabilities that correlate signals using natural language to surface root causes and suggest actionable fixes.
Architecture and Approach Comparison
The fundamental architectural difference between Prometheus and its alternatives lies in the data collection model and storage backend. Prometheus uses a pull-based architecture where the server scrapes HTTP metrics endpoints at configured intervals, storing data in a local time-series database. Each Prometheus server operates independently with no clustering, which makes it simple to deploy but creates challenges for long-term storage and horizontal scaling. Prometheus models time series using a dimensional data model where each series is identified by a metric name and a set of key-value pairs. It is purpose-built for metrics and does not natively handle logs or traces.
Datadog and New Relic take an agent-based, push model approach. Lightweight agents installed on hosts collect and forward metrics, logs, and traces to their respective cloud backends via API. This eliminates the operational burden of managing storage and scaling, but it means your telemetry data resides on third-party infrastructure. Both platforms provide proprietary query languages alongside their visualization layers, and both support OpenTelemetry ingestion alongside their native agents.
Dynatrace uses a similar agent-based model with its OneAgent, which automatically discovers and instruments applications across the full stack. Its architecture is distinguished by the Smartscape topology mapping that identifies relationships between application components in real time, and its Grail data lakehouse that supports massively parallel processing for unified data storage and analytics. Dynatrace supports ingesting data from any source including OpenTelemetry, and processes traces, metrics, logs, events, and topology data.
Grafana Cloud takes a hybrid approach that is most compatible with existing Prometheus deployments. It accepts the Prometheus remote-write protocol, supports PromQL natively, and extends the stack with Loki for logs and Tempo for traces. Teams can gradually migrate from self-hosted Prometheus to Grafana Cloud without rewriting queries or dashboards, making it the lowest-friction migration path for teams with existing Kubernetes monitoring infrastructure.
Elastic Observability is built on the Elastic Stack, using Elasticsearch as its core storage and query engine with its ES|QL query language. This search-first architecture excels at log analytics and full-text search across massive datasets. It supports OpenTelemetry natively via its Elastic Distributions of OpenTelemetry (EDOT) and offers deployment flexibility including self-hosted, cloud, and hybrid options, which can be important for teams with data sovereignty or compliance requirements.
Splunk uses a schema-on-read architecture that ingests raw machine data and applies structure at query time using its SPL (Search Processing Language). This makes it exceptionally flexible for unstructured data analysis but can result in higher storage costs compared to schema-on-write approaches. Splunk is commonly deployed on-premises in enterprise environments with strict compliance requirements and integrates with over 2,800 apps from its Splunkbase marketplace.
Observe takes a streaming data lake approach that ingests all telemetry into a unified data lake, applying transformations and correlations in real time. This architecture is designed to provide cost advantages for high-volume environments by decoupling storage from compute.
For teams running Kubernetes-heavy environments, Prometheus and Grafana Cloud have the strongest native integration through service discovery and the established PromQL ecosystem. For teams needing a single platform covering metrics, logs, traces, and security, Datadog, Dynatrace, and New Relic offer the most comprehensive managed solutions.
Pricing Comparison
Prometheus itself is completely free and open source under the Apache 2.0 license. The cost of running Prometheus comes entirely from the infrastructure required to host it: compute, storage, and the engineering time to operate and scale it. There are no license fees, per-host charges, or usage-based costs for the software itself.
Datadog uses a multi-dimensional usage-based pricing model. It offers a free tier, and paid plans are structured around per-host charges for infrastructure monitoring, with additional costs for APM, log management, and other modules. Costs scale based on the number of hosts, volume of logs ingested, custom metrics, and additional features enabled. Teams should carefully model their expected usage across all dimensions before committing, as each unique combination of a metric name and its tag values counts as a separate billable metric.
Dynatrace follows a usage-based model with various pricing tiers across its capabilities. Based on its published pricing page, it lists options ranging from $7/mo for certain capabilities to $58/mo for others, with additional usage-based charges. Dynatrace emphasizes a single subscription model with volume-based discounts and no penalties for exceeding committed volumes.
Elastic Observability offers tiered pricing with Standard, Platinum, and Enterprise plans. It provides deployment flexibility across hosted cloud (resource-based pricing), serverless (usage-based pricing), and self-managed (license-based) options, allowing teams to choose the model that best fits their operational preferences.
Grafana Cloud follows a freemium model with a generous free tier. Paid plans scale based on usage of metrics, logs, and traces. For teams already running Prometheus, Grafana Cloud can serve as a cost-effective managed backend that eliminates the operational overhead of self-hosting while preserving the PromQL query experience.
New Relic operates on a usage-based pricing model with a free tier available. Its published pricing includes per-user charges and data ingestion costs. New Relic has moved toward a more transparent pricing model in recent years.
Observe uses usage-based pricing structured around data ingestion volume, with log ingestion starting at $0.49 per unit according to its published pricing.
Splunk offers a freemium model with a free community edition for self-hosted deployments. Enterprise pricing is custom and typically based on data volume ingested. For teams already committed to self-hosting, Splunk Community Edition provides a no-cost entry point similar to Prometheus.
The key pricing consideration when comparing Prometheus to commercial alternatives is the total cost of ownership: Prometheus has zero software cost but requires dedicated engineering effort to deploy, monitor, scale, and maintain. Commercial platforms shift that operational burden to the vendor but introduce ongoing subscription costs that grow with your infrastructure.
When to Consider Switching
Switching from Prometheus makes sense when your monitoring requirements have evolved beyond what a single-server, metrics-only tool can deliver. Here are the most common scenarios where teams benefit from evaluating alternatives.
You need long-term metric storage and high availability. Prometheus stores data locally on disk with limited retention. If your team needs months or years of historical data for capacity planning and trend analysis, a managed backend like Grafana Cloud (which natively supports PromQL) or a commercial platform with built-in long-term storage can eliminate the complexity of running Thanos or Cortex alongside Prometheus.
You need unified observability across metrics, logs, and traces. Prometheus handles metrics well but does not cover logs or distributed traces. If your team is currently stitching together Prometheus, a separate log aggregator, and a tracing backend, consolidating into a single platform like Datadog, New Relic, Dynatrace, or Elastic Observability can reduce tool sprawl and simplify incident investigation by correlating all signals in one place.
Your engineering team cannot dedicate resources to operating monitoring infrastructure. Running Prometheus at scale requires managing federation, remote storage, alerting pipelines, and upgrades. For teams where engineering time is better spent on product development, a fully managed SaaS platform removes this operational burden entirely.
You need automated root cause analysis and AI-powered insights. Prometheus provides raw metrics and basic alerting through Alertmanager, but root cause analysis is manual. Platforms like Dynatrace and Datadog offer automated anomaly detection and AI-driven root cause analysis that can significantly reduce mean time to resolution for complex distributed systems running across AWS, GCP, or Azure environments.
You have compliance or security monitoring requirements. If your organization needs SIEM capabilities, security monitoring, or compliance reporting alongside infrastructure observability, platforms like Splunk or Datadog offer integrated security features that Prometheus does not provide.
You are scaling beyond what a single Prometheus instance can handle. When your environment grows to thousands of targets producing millions of active time series, Prometheus requires careful capacity planning, sharding, and federation. Commercial platforms and managed services handle this scaling transparently.
Conversely, Prometheus remains an excellent choice if your team has strong infrastructure expertise, you primarily need metrics monitoring for Kubernetes workloads, you want to avoid vendor lock-in, or you need a monitoring solution with zero licensing cost.
Migration Considerations
Migrating away from Prometheus requires planning across several dimensions: instrumentation, queries, alerting rules, dashboards, and team workflows. The difficulty varies significantly depending on your target platform.
Preserving your PromQL investment. If your team has built extensive PromQL queries, alerting rules, and Grafana dashboards, migrating to Grafana Cloud is the path of least resistance. Grafana Cloud accepts the Prometheus remote-write protocol and supports PromQL natively, meaning your existing queries, alerts, and dashboards can transfer with minimal modification. Datadog and New Relic also support PromQL to varying degrees, though you may need to adapt some advanced queries to their native query languages.
Instrumentation changes. Prometheus uses a pull-based model with client libraries (available in Go, Python, Java, and other languages) that expose /metrics endpoints. Moving to a push-based platform like Datadog or New Relic requires installing agents and potentially modifying how your applications expose telemetry. Adopting OpenTelemetry as an instrumentation layer can serve as a bridge: instrument your applications once with OTel SDK libraries, and route the data to any compatible backend. Elastic Observability, Grafana Cloud, Dynatrace, and New Relic all support OpenTelemetry ingestion, which provides portability and reduces future migration risk.
Alerting rule migration. Prometheus Alertmanager rules will need to be translated to the target platform's alerting syntax. For Grafana Cloud, this is straightforward since it supports Prometheus-style alerting. For other platforms, expect to manually recreate alert conditions, routing rules, and notification channels in their respective systems.
Running in parallel. A recommended migration strategy is to run the new platform alongside Prometheus for a transition period. Send duplicate data to both systems, validate that the new platform produces equivalent results, and gradually shift team workflows. This reduces risk and allows your team to build confidence in the new tooling before decommissioning Prometheus.
Data migration versus fresh start. Historical Prometheus data is typically not migrated to the new platform. Most teams accept a clean break, keeping Prometheus running in read-only mode for a retention period while the new platform accumulates fresh data. If long-term historical continuity is critical, evaluate whether the target platform supports Prometheus remote-read or snapshot import via its API.
Team training and adoption. Budget time for your team to learn the new platform's query language (whether that is DQL for Dynatrace, ES|QL for Elastic, SPL for Splunk, or NRQL for New Relic), dashboard builder, and alerting configuration. Even if the new platform supports PromQL, it will have its own patterns and best practices. Invest in training sessions and documentation to ensure the migration delivers the expected productivity improvements rather than creating friction.