Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What InfluxData states |
|---|---|
License | InfluxDB 3 Core is open source under MIT or Apache 2, at your choice, and free to run with no license required. |
Who runs it | Self-managed: Core and Enterprise on your own on-prem, private cloud or edge infrastructure. Fully managed: Cloud Serverless and Cloud Dedicated (InfluxData) or Amazon Timestream for InfluxDB (AWS). |
Installation | Docker images, Debian and RPM packages, and tarballs; Core runs on Linux, Mac and Docker. |
Write and query | Line protocol for writes; SQL, InfluxQL and Flight SQL for queries; HTTP API on port 8181 (InfluxDB 3 Core). |
Storage | Apache Parquet on object storage (S3, Azure, GCP) or local disk; built with Rust, Apache Arrow and DataFusion (InfluxDB 3 Core). |
Certifications | SOC 2 Type II, ISO 27001 and ISO 27018 across the product line. On self-managed deployments you configure your own requirements on top. |
Support | Core: community support only. Enterprise: technical support SLA. Amazon Timestream for InfluxDB: AWS support plans honored. |
Our take
InfluxDB is worth shortlisting if your data is timestamped metrics, events or sensor telemetry that needs real-time ingest and fast queries. Choose the edition by who should run it and whether you need high availability. If you do, the shortlist is Enterprise (self-managed), Cloud Dedicated or Amazon Timestream for InfluxDB; Core and Cloud Serverless list no HA.
Evaluate InfluxDB
Comparisons
Where it stands out
A path from 1.x and 2.x. Core accepts the 1.x and 2.x write APIs and the 1.x InfluxQL query API. Enterprise supports migration from 1.x and 2.x, and Core users can upgrade to Enterprise in seconds.
Processing inside the database. Core has an embedded Python VM for plugins and triggers. In Enterprise, the Processing Engine runs transformation, anomaly detection, alerting, downsampling and external integrations without a separate pipeline.
Collection and client tooling. Telegraf, InfluxData's open source connector, has 400+ plugins. Client libraries cover Python, JavaScript, Go, C# and Java, and InfluxData documents monitoring setups with Grafana.
Fast latest-value lookups. InfluxData states that Enterprise returns last-value queries in under 10 milliseconds through its Last Value Cache, which suits dashboards and automation.
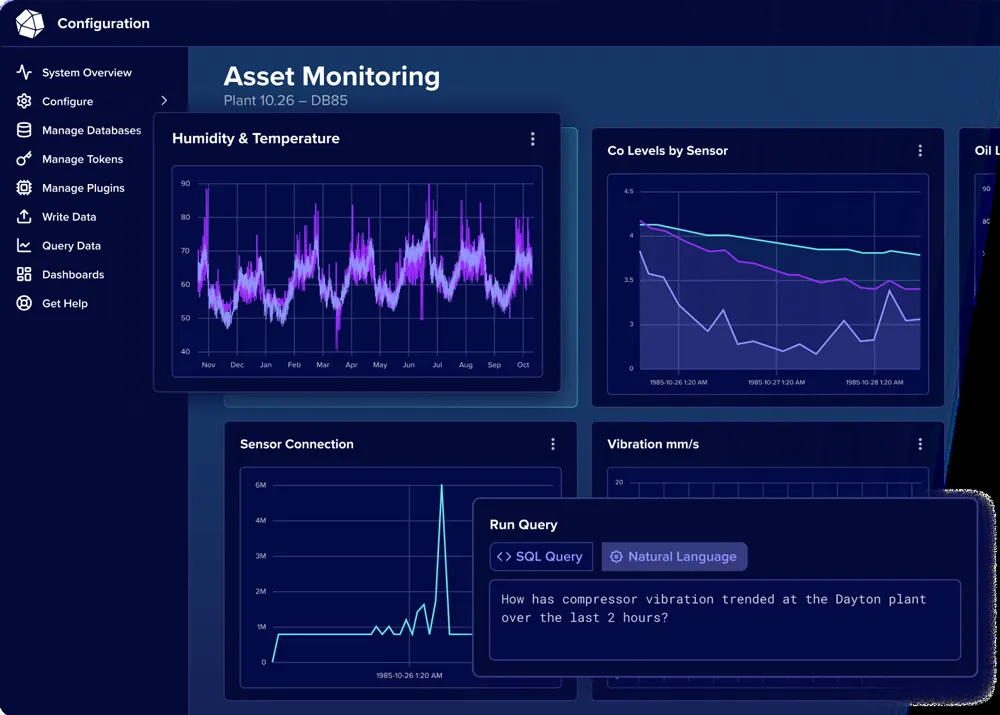
Product screenshot

Trade-offs to weigh
A Core pilot can outgrow its edition. If you stay self-managed, high availability, multi-node clustering, read replicas and long-range data compaction come with Enterprise, not Core. InfluxData positions Core for deployments that don't manage critical data, so plan the move before a pilot carries production data.
Serverless is sized for early work. The free tier has limited ingestion rates and 30-day retention. InfluxData calls the usage-based plan a fit for prototyping and low-volume workloads and points production scale to Cloud Dedicated.
Flux users have work to do. The v3 Core branch lists SQL and InfluxQL as its query languages; Flux appears only on the v2.x and v1.x branches. Check existing Flux queries before planning a move to v3.
Pricing and plan conditions
Cloud Serverless is the metered edition. It is usage-based with no minimum commitment or long-term contract, and new paid accounts get $250 in credits applied to the first 30 days. Annual plans with discounted rates in exchange for a usage commitment go through sales. Cloud Serverless is also sold on the AWS, Google Cloud and Microsoft Azure marketplaces. Amazon Timestream for InfluxDB is billed to your AWS account, where existing AWS credits and EDP discounts apply.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
InfluxDB 3 Core (OSS) | Free Forever | Self-managed, full InfluxDB 3 engine on Linux, Mac and Docker. No HA, no enterprise security. |
Cloud Serverless | Start for free, then usage-based: data in $0.0025 per MB written; $0.012 per 100 query executions; storage $0.002 per GB-hour; data out $0.09 per GB transferred out | Pay-as-you-go, multi-tenant cloud. Service quotas apply, no HA. |
InfluxDB 3 Enterprise | Custom pricing, based on CPU configuration | Self-managed on-prem, private cloud or edge; unlimited scale with no service quotas; high availability and read replicas; SAML/SSO and OAuth; technical support SLA. 30-day free trial, no credit card needed. |
Cloud Dedicated | Based on CPU/RAM and storage | Single-tenant, isolated infrastructure managed by InfluxData; disaster recovery support; private networking (add-on); SAML/SSO (add-on). |
Amazon Timestream for InfluxDB | AWS consumption pricing | InfluxDB 3 on fully managed AWS infrastructure; native IAM and VPC integration; high availability included. |
Telegraf Enterprise | Plans start at $18,000 / year | Management layer for Telegraf: centralized configuration, real-time agent health monitoring, visual config builder, RBAC and an enterprise support SLA. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
3 GitHub commits 90d31.8k GitHub stars0 vulnerabilities across 2 packages
See all signals from 8 sources
npm · @influxdata/influxdb-client@1.35.0 · PyPI · influxdb-client@1.50.0
Alternatives to InfluxDB
The reviewed substitutes for InfluxDB among the time-series databases, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- TimescaleDB
- Two time-series databases ingesting and querying timestamped measurements at high rates. They are compared directly on ingest throughput, query language and operational model, and a team runs one.Applies to: Choosing the database that will hold timestamped measurements.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- ClickHouse
- ClickHouse and InfluxDB both store and query large volumes of timestamped data such as metrics and events. InfluxDB is a purpose-built time series database for monitoring sensors and systems, available open source, in the cloud or as an enterprise product. ClickHouse is a general columnar SQL database, so it fits when time series are queried with full SQL next to other analytical data.Applies to: When timestamped metrics and events are the main data being stored and queried.
- Prometheus
- Prometheus and InfluxDB both store time-series metrics and query them for monitoring. Prometheus is a complete open-source monitoring system that pulls metrics, alerts on them and discovers Kubernetes services, while InfluxDB is a general time series database from InfluxData that also serves sensor data, offered open source, in the cloud or as an enterprise edition. Whether the stack needs a monitoring system or a database to build on decides the pick.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
See detailed alternatives analysis
InfluxDB has established itself as the leading time series database, with over 31,000 GitHub stars and recognition as the #1 time series database on DB-Engines. Built for high-volume, high-velocity data ingestion, it serves use cases ranging from infrastructure monitoring to IoT telemetry and real-time analytics. However, its evolving licensing model, the architectural shift from InfluxDB 2.x to 3.x, and the specialized nature of its time series focus lead many teams to evaluate InfluxDB alternatives. Whether you need broader analytical capabilities, a PostgreSQL-compatible interface, or a different cost structure, several strong contenders deserve consideration.
Top Alternatives Overview
Timescale extends PostgreSQL with native time series capabilities, offering automatic partitioning (hypertables), continuous aggregates, and built-in compression. Because it runs as a PostgreSQL extension, teams already invested in the PostgreSQL ecosystem can adopt it without learning a new query language or managing a separate database. Timescale's managed Tiger Cloud offers a free 30-day trial of its Performance plan, with compute from $30/mo plus storage for managed cloud deployments. Its compression ratios and query performance on time series workloads make it a natural fit for teams that want time series functionality without abandoning relational database tooling.
QuestDB is a high-performance time series database written in Java and C++ that emphasizes ultra-low-latency ingestion and querying. With over 16,800 GitHub stars and an Apache-2.0 license, QuestDB uses a column-oriented storage engine with SIMD-accelerated processing to achieve fast throughput on demanding workloads. It supports standard SQL and offers native Parquet support for data portability. QuestDB targets capital markets, industrial telemetry, and other latency-sensitive environments where ingestion speed is the primary bottleneck.
ClickHouse is a column-oriented OLAP database with over 48,000 GitHub stars, making it one of the most popular open-source analytical databases. While not purpose-built for time series, its columnar storage, aggressive compression, and vectorized query execution handle time-stamped data effectively. ClickHouse excels at analytical queries over large historical datasets and supports real-time data ingestion. It is free and open-source under the Apache-2.0 license, with a managed cloud offering (ClickHouse Cloud) available for teams that prefer a hosted solution.
Apache Druid is an open-source distributed data store that combines ideas from data warehouses, time series databases, and search systems. With nearly 14,000 GitHub stars and an Apache-2.0 license, Druid provides sub-second OLAP queries on both streaming and batch data. Its architecture supports real-time ingestion from Kafka and Kinesis alongside batch loading, making it suitable for interactive analytics dashboards and operational monitoring at scale.
DuckDB takes a fundamentally different approach as an in-process SQL OLAP engine with over 37,500 GitHub stars. Rather than running as a server, DuckDB embeds directly into applications, making it ideal for local analytics, data science workflows, and edge computing scenarios. Its columnar-vectorized execution engine delivers strong analytical performance without infrastructure overhead. DuckDB is completely free and open-source.
Elasticsearch rounds out the alternatives as a distributed search and analytics engine used broadly for logging, observability, and security analytics. With its RESTful API and robust full-text search capabilities, Elasticsearch serves teams whose time series needs overlap with log aggregation and search. Its pricing model is freemium, with Elastic Cloud Hosted tiers starting at $99/mo for managed cloud deployments.
Architecture and Approach Comparison
The fundamental architectural divide among these alternatives centers on their storage models and query execution strategies. InfluxDB 3.x has moved to a cloud-native, diskless architecture with separation of compute and storage, using object storage backends like S3. It employs a custom storage engine optimized specifically for time series write patterns, supporting its line protocol for high-speed ingestion and both SQL and InfluxQL for querying.
Timescale takes the opposite approach by building on top of PostgreSQL rather than creating a new storage engine. This means full ACID compliance, support for JOINs, foreign keys, and the entire PostgreSQL extension ecosystem. The tradeoff is that PostgreSQL's row-oriented storage is adapted for time series through hypertables and chunk-based partitioning, rather than being natively columnar. For teams that need to combine time series data with relational data in the same database, this integrated approach eliminates the need for a separate system.
QuestDB uses a purpose-built column-oriented storage engine with memory-mapped files and SIMD vectorization for maximum throughput. Its architecture is optimized for append-heavy workloads typical of time series data, with a multi-tier storage engine that supports both hot and cold data. QuestDB's use of native Parquet format for cold storage ensures data portability and avoids vendor lock-in.
ClickHouse employs a MergeTree storage engine family that excels at batch inserts and analytical scans. Data is organized into sorted parts that are merged in the background, providing excellent compression ratios and scan performance. Unlike InfluxDB, ClickHouse is not optimized for high-frequency single-row inserts typical of sensor data but handles batch ingestion of time-stamped events efficiently. Its distributed query execution supports horizontal scaling across clusters.
Apache Druid's architecture separates ingestion, storage, and query processing into distinct services, allowing independent scaling. It uses a segment-based storage format optimized for time-based partitioning and supports both real-time and batch ingestion paths. Druid's bitmap indexing and pre-aggregation capabilities target interactive dashboard queries where sub-second response times are essential.
DuckDB's in-process architecture eliminates network overhead entirely, making it suited for analytical workloads that can fit on a single machine. It processes data using a vectorized execution engine that operates on columns of values rather than individual rows. While not designed for concurrent multi-user access or streaming ingestion, DuckDB handles analytical queries on time-stamped data files (Parquet, CSV) with minimal setup.
Pricing Comparison
Most InfluxDB alternatives follow the open-source-core model, offering a free self-hosted version with paid managed services.
InfluxDB itself provides a free Community Edition for self-hosted deployments, with cloud pricing that includes usage-based tiers (dollar amounts starting at $0.00 for the free tier). The InfluxDB 3 Enterprise edition is available as a self-managed deployment with a 30-day trial.
Timescale's managed Tiger Cloud offers a free 30-day trial of its Performance plan, with compute from $30/mo plus storage billed per GB. Self-hosted TimescaleDB remains open-source and free. This makes Timescale one of the most accessible entry points for teams exploring managed time series solutions.
QuestDB is free and open-source under the Apache-2.0 license for self-hosted deployments. Enterprise features and support require contacting QuestDB directly for pricing details, following a sales-driven model for production deployments.
ClickHouse is free and open-source for self-hosted use. ClickHouse Cloud provides a managed service with usage-based pricing, though specific pricing details require checking their current offerings.
Apache Druid is completely free and open-source under the Apache License 2.0. Managed Druid services are available from third-party vendors like Imply, which offers commercial support and a cloud platform.
DuckDB is entirely free and open-source with no paid tiers, making it the most cost-effective option for teams that need analytical capabilities without ongoing service costs.
Elasticsearch follows a freemium model with self-managed options and Elastic Cloud Hosted pricing starting at $99/mo for Standard and $184/mo for Enterprise, with costs growing with the resources a workload needs.
When to Consider Switching
Teams should evaluate alternatives to InfluxDB when their use cases extend beyond pure time series workloads. If your team needs to JOIN time series data with relational tables, run complex analytical queries across dimensions, or leverage the PostgreSQL ecosystem, Timescale provides these capabilities natively without requiring a separate analytical database.
Consider QuestDB when ingestion latency is the primary constraint. Environments such as capital markets tick data processing, high-frequency sensor networks, or any scenario where microsecond-level write performance matters will benefit from QuestDB's SIMD-optimized ingestion pipeline.
ClickHouse becomes the stronger choice when your workload shifts from pure time series monitoring toward broader analytical queries. If you need to run ad-hoc aggregations across billions of rows of event data, combine time-stamped records with dimensional data, or build a general-purpose analytical data warehouse, ClickHouse's query engine handles these patterns efficiently.
Apache Druid fits scenarios requiring real-time interactive dashboards with high concurrency. When hundreds or thousands of users need to slice and dice data simultaneously with sub-second response times, Druid's pre-aggregation and segment-based architecture delivers consistent performance under load.
DuckDB is the right choice for local analytics, data science exploration, or embedded analytical workloads. If your team processes time series data in batch rather than streaming, and the data fits on a single machine, DuckDB eliminates the operational overhead of running a distributed database.
Elasticsearch makes sense when your time series needs are closely tied to log management, full-text search, or observability. If you already run an ELK stack for logging, extending it for metrics collection avoids introducing another database into your infrastructure.
Migration Considerations
Migrating from InfluxDB requires careful planning around data export, schema translation, and query rewriting. InfluxDB's data model uses measurements, tags, and fields rather than traditional tables and columns, so schema mapping is a critical first step. Most alternatives support bulk data import from Parquet, CSV, or line protocol formats, but the tag-to-column mapping and retention policy translation will require custom scripting.
For Timescale migrations, the PostgreSQL compatibility layer simplifies the transition for teams familiar with SQL. InfluxQL queries translate relatively well to SQL, though InfluxDB-specific functions like FILL() and GROUP BY time() need to be rewritten using Timescale's time_bucket() and continuous aggregates. The Timescale documentation provides migration guides specifically for InfluxDB users.
QuestDB supports InfluxDB Line Protocol for data ingestion, which significantly reduces the migration effort for the write path. Applications sending data via line protocol can often switch endpoints with minimal code changes. Query migration requires converting InfluxQL to standard SQL, which QuestDB supports natively.
ClickHouse migrations involve converting the InfluxDB data model into a table schema optimized for ClickHouse's MergeTree engine family. Time-based partitioning, proper ORDER BY key selection, and materialized views for common aggregations are essential for matching or exceeding InfluxDB query performance. Plan for a testing phase to validate that batch insert patterns align with ClickHouse's optimal ingestion model.
Apache Druid migrations require defining ingestion specs that map InfluxDB measurements to Druid datasources, with tags becoming dimensions and fields becoming metrics. Druid's real-time ingestion from Kafka can replace Telegraf-based collection pipelines, though the switch requires reconfiguring the upstream data flow.
Across all migration paths, plan for a parallel operation period where both the source InfluxDB instance and the target database run simultaneously. This allows validation of data completeness and query result parity before decommissioning the original system. Budget additional time for rewriting any dashboards, alerts, or downstream integrations that depend on InfluxDB-specific APIs.