Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What AWS states |
|---|---|
Deployment options | Provisioned clusters (you pick node type and count; AWS recommends RG) or Redshift Serverless (no node type to choose). AWS says both scale to petabytes of data and support thousands of concurrent users. |
Storage model | Redshift Managed Storage on RG and RA3 nodes and with Serverless scales separately from compute. The same storage rate applies whether data sits on local SSDs or in Amazon S3. |
Data lake access | Read-only ANSI SQL on Apache Iceberg, Apache Hudi and Delta Lake tables, and on Parquet, ORC, Avro, JSON and CSV files in Amazon S3. Read and write access for Apache Iceberg v3 tables. |
Loading data | Zero-ETL integrations from Amazon Aurora, RDS and DynamoDB; streaming ingestion from Amazon Kinesis Data Streams and Amazon MSK; auto-copy from Amazon S3. |
Security | Can run inside Amazon VPC; TLS in transit and AES-256 at rest can be enabled; dynamic data masking; single sign-on via IAM Identity Center and third-party IdPs such as Okta. Network isolation and row- and column-level permissions at no additional cost. |
Availability | Multi-AZ data warehouse with a 99.99% SLA, without standby resources. |
Connectivity | BSD-2-Clause JDBC 4.2 driver with IAM and IdP authentication. BI tools such as Amazon QuickSight, Tableau and Microsoft Power BI. |
Our take
Choose Redshift if your data platform already centres on AWS: Amazon S3 holds the lake, Aurora, RDS, DynamoDB, Kinesis or MSK feed it, and you want one SQL engine for warehouse and lake data, with the choice of sized clusters or Serverless.
Evaluate Amazon Redshift
Popular comparisons
See all 7 Amazon Redshift comparisons
Where it stands out
Two ways to run it. Provisioned clusters can be resized, scheduled to add or remove nodes daily or weekly, and paused. Serverless scales on its own and shuts down when idle.
Lake queries built into RG nodes. RG instances include a data lake query engine for Apache Iceberg and Apache Parquet. UNLOAD exports results back to the lake, including as Parquet.
Near real-time data. AWS says Redshift ingests hundreds of megabytes per second, and materialized views can sit directly on streams.
Free daily burst capacity. Concurrency Scaling adds capacity in seconds. Each cluster earns up to one hour of free credits per day, which AWS says covers 97% of customers.
Workload isolation with clear cost lines. Separate warehouses isolate workloads, and each is billed for its own compute.
Product screenshot
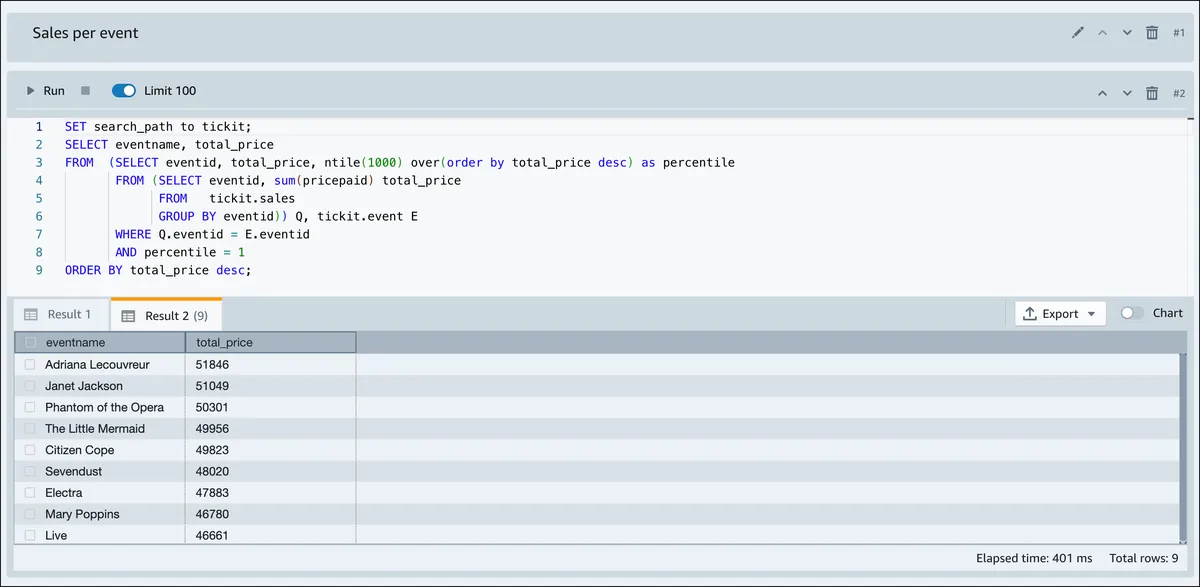

Trade-offs to weigh
Usage, not only capacity, sets the bill. On provisioned clusters, Spectrum scans and Concurrency Scaling beyond the free credits are charged per use, so query patterns change spend.
Clusters are yours to size and stop. AWS advises sizing RG or RA3 clusters to the data you process daily. An on-demand cluster bills while it runs, so idle environments need a manual or scheduled pause.
Writable lake tables mean Iceberg v3. Hudi and Delta Lake tables are read-only from Redshift, so pipelines that write lake tables need Apache Iceberg v3, created directly or upgraded from v2 in place.
Performance figures are AWS's own. AWS claims up to 8.3x better price-performance for new queries in dashboards and 7x better throughput than other cloud data warehouses. Test with your own queries.
JDBC 2.3.0 can break stored DataSources. A DataSource serialized by an older driver fails with java.io.InvalidClassException and needs a one-time conversion with the bundled helper on Java 9+ or 8u121+. Connecting by JDBC URL or JNDI reference is unaffected.
System tables keep 7 days by default. Longer history needs the Amazon S3 Tables integration, which stores it in Apache Iceberg format.
Pricing and plan conditions
Compute is one charge; managed storage is a second, based on the data you store rather than the compute you run. Data transfer and ML costs apply separately on both Provisioned and Serverless. AWS offers the AWS Pricing Calculator for an estimate.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Option | Published price | Billing conditions |
|---|---|---|
Provisioned, on-demand | Starts at $0.543 per hour | Hourly rate by node type and count; no commitment or upfront cost. Partial hours billed per second after a billable status change. While paused, only backup storage is billed. Multi-AZ: same rates for double the compute. |
Provisioned, Reserved Instances | Significant discounts over on-demand pricing (AWS) | For steady-state workloads. |
Redshift Serverless | Begins at $1.50 per hour | RPU-hours billed per second with a 60-second minimum; no charge for start-up or idle time. Concurrency scaling and Spectrum included. Base capacity 4 to 1024 RPUs; each RPU provides 16 GB of memory. |
Serverless Reservations | Up to 24% off for a 1-year term, up to 45% off for a 3-year term | Shareable between AWS accounts. Billed hourly, metered per second, 24 hours a day. Usage above the reserved RPU level is charged at on-demand rates. |
Redshift Managed Storage | Billed hourly for the data stored | RG, RA3 and Serverless; independent of node count. Serverless point-in-time restore within the last 24 hours, at 30-minute granularity, is free. |
Redshift Spectrum | Billed by bytes scanned | SQL on Amazon S3 data. Not required on RG instances; included with Serverless. |
Concurrency Scaling | Per-second on-demand rate beyond free credits | Charged only after the daily free credits are used; included with Serverless. |
Redshift ML | Costs for creating your model and storage after the Amazon SageMaker free tier | Create, train and deploy ML models with SQL; also available with Serverless. |
Free trial | $300 credit with a 90-day expiration | For first-time Serverless users, toward compute and storage. Where Serverless is unavailable: a two-month provisioned trial; on-demand rates after it or above 750 hours per month. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
12 GitHub commits 90d71 GitHub stars0 vulnerabilities across 2 packagesOpenSSF score 5.0/10
See all signals from 9 sources
npm · @aws-sdk/client-redshift@3.1164.0 · PyPI · redshift-connector@2.2.0
Alternatives to Amazon Redshift
The reviewed substitutes for Amazon Redshift among the cloud data warehouses, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Snowflake
- Fully managed cloud data platform with elastic compute and storage separation
- Google BigQuery
- The two hyperscaler-native cloud data warehouses. A team standardising on one cloud evaluates its warehouse against the other's.
- Teradata
- Amazon Redshift and Teradata are massively parallel data warehouses for enterprise reporting and analytics. Redshift is a fully managed AWS service that fits companies already running on Amazon's cloud. Teradata deploys across AWS, Azure, Google Cloud and on-premises hardware, which suits large firms with hybrid estates.Applies to: Choosing between these two for the cloud data warehouses decision.
- Vertica
- Amazon Redshift and Vertica are columnar, massively parallel databases for analytical SQL at scale. Redshift is a managed AWS service, so AWS runs the infrastructure and the warehouse plugs into the rest of the AWS stack. Vertica is software a team runs itself, on-premises or in any cloud, and adds in-database machine learning.Applies to: Choosing between these two for the cloud data warehouses decision.
- Azure Synapse Analytics
- Unified analytics service combining data warehousing, big data processing, and data integration with serverless and dedicated resource models.Applies to: Enterprise SQL analytics on a central warehouse: BI dashboards, ad-hoc exploration and scheduled transformation over the same governed dataset. The deciding factor is usually the existing cloud commitment, not the feature set.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Databricks
- A warehouse that owns its storage and a lakehouse or federated engine that queries data in open formats reach the same analytics by different architectures. The decision is whether data is loaded into one platform or left in object storage and queried where it sits, which is why these appear together on central-store shortlists.Applies to: Deciding whether analytical data is loaded into one platform or queried in open formats where it sits.
- Apache Hudi
- Choose Redshift when you want managed cluster-based SQL with streaming ingest; Hudi plus EMR wins on cost at scale.
- ClickHouse
- Amazon Redshift and ClickHouse each run analytical SQL on large columnar tables. Redshift is the AWS managed warehouse and the natural central store for an AWS-based company. ClickHouse is an open-source OLAP database tuned for real-time reports and high query concurrency, which matters when the warehouse is too slow for live dashboards.Applies to: Serving fast analytical queries, and whether the central warehouse can also carry them.
- Exasol
- Both answer the same enterprise analytics question with a columnar MPP engine. The difference in kind is architecture and hosting: Exasol is an in-memory analytics database run self-hosted or in your own cloud account, tuned for query latency, while redshift is a managed, storage-separated service that scales compute on demand.Applies to: Enterprise SQL analytics on a central warehouse: BI dashboards, ad-hoc exploration and scheduled transformation over the same governed dataset. Choose Exasol when query latency on a bounded working set matters most and you will operate the database; choose redshift for elastic managed capacity.
- MotherDuck
- Amazon Redshift and MotherDuck both serve as a managed SQL warehouse for a company's analytics and reporting data. Redshift uses massively parallel processing with deep links to Glue, SageMaker and other AWS services, which suits large AWS estates. MotherDuck is a serverless warehouse built on DuckDB that aims at simple setup for smaller data teams.Applies to: For smaller teams on AWS that need a SQL warehouse but not a massively parallel cluster.
- Yellowbrick Data
- Both are MPP SQL warehouses evaluated for the same enterprise analytics workload. The difference in kind is who runs it: Yellowbrick is a SQL data platform deployed on your own Kubernetes, including private cloud and on-premises, while redshift is consumed as a fully managed service. That is the same distinction that made Snowflake and Vertica a conditional pair rather than a direct one.Applies to: Enterprise SQL analytics on a central warehouse: BI dashboards, ad-hoc exploration and scheduled transformation over the same governed dataset. Choose Yellowbrick when the warehouse must run inside your own infrastructure or Kubernetes estate; choose redshift when a managed service is acceptable.
Head to head
See detailed alternatives analysis
If you are evaluating Amazon Redshift alternatives, you are likely running into one of several common friction points: cluster sizing and capacity planning demand hands-on tuning, concurrency degrades under mixed workloads, or costs become difficult to predict as data volumes and user counts grow. Redshift remains a strong choice for teams deeply embedded in the AWS ecosystem, but the cloud data warehouse landscape has expanded significantly. Whether you need serverless simplicity, lakehouse flexibility, or real-time analytics at sub-second latency, we have mapped out the strongest alternatives to help you find the right fit.
Top Alternatives Overview
We have identified ten platforms that cover a range of architectural approaches, pricing models, and specializations. Here is how they compare at a high level:
Snowflake is a fully managed cloud data platform that separates compute from storage and runs on AWS, Azure, and Google Cloud. Users consistently praise its ease of use and automatic performance optimization. It uses a consumption-based credit model and supports Standard, Enterprise, Business Critical, and Virtual Private Snowflake tiers.
Databricks takes a lakehouse approach, unifying data lake and data warehouse capabilities on top of Apache Spark and Delta Lake. It excels at data engineering, machine learning, and collaborative notebook workflows. Pricing is based on Databricks Units (DBUs), with rates varying by compute type and subscription tier.
Google BigQuery is a fully serverless data warehouse with pay-per-query pricing, making it an excellent choice for teams that want zero infrastructure management. It includes a free tier for data processing each month.
Starburst, built on Trino, enables federated queries across data lakes, warehouses, and databases without moving data. It offers a free tier for up to three clusters, with paid tiers using a credit-based pricing model starting at $0.50/credit for Pro and $0.75/credit for Enterprise, based on their published pricing page.
SingleStore (formerly MemSQL) combines transactions and analytics in a single distributed SQL engine, delivering real-time analytics with single-digit millisecond query latency. It offers a free shared workspace tier, and paid workspaces use on-demand hourly pricing.
Teradata VantageCloud is an enterprise analytics platform supporting hybrid multi-cloud environments across AWS, Azure, and GCP. It targets large organizations with complex analytics requirements and uses usage-based pricing.
Trino is an open-source distributed SQL query engine that can query data across multiple sources. The community edition is free and self-hosted under an Apache 2.0 license.
StarRocks is an open-source MPP OLAP database designed for sub-second real-time analytics and data lakehouse scenarios. It won InfoWorld's 2023 BOSSIE Award for best open source software.
TimescaleDB extends PostgreSQL with automatic time-based partitioning and columnar compression, making it ideal for time-series workloads while maintaining full SQL compatibility.
Vertica provides a columnar analytics platform with advanced compression and in-database machine learning, suitable for large-scale data analytics across warehouse and lakehouse environments.
Architecture and Approach Comparison
The core architectural difference among these alternatives centers on how each platform handles the relationship between compute, storage, and workload isolation.
Redshift uses a cluster-based massively parallel processing (MPP) architecture with columnar storage, zone maps, and data compression including the purpose-built AZ64 encoding. While RA3 nodes separate compute from managed storage, the cluster model still requires teams to plan capacity, choose node types, and configure distribution keys and sort keys. Redshift Serverless abstracts some of this complexity, but performance tuning and workload isolation still require meaningful expertise.
Snowflake and Google BigQuery represent the serverless end of the spectrum. Snowflake fully separates compute and storage, allowing teams to spin up independent virtual warehouses for different workloads without resource contention. BigQuery goes further by eliminating cluster management entirely: you submit queries and Google handles execution. Both platforms offer automatic scaling and optimization that Redshift requires manual configuration to achieve.
Databricks pioneered the lakehouse architecture, querying data stored in open formats (Delta Lake, Apache Iceberg, Parquet) directly in cloud object storage. This approach avoids data duplication between lakes and warehouses and gives data engineering and ML teams native Spark processing capabilities with collaborative notebooks. Redshift has added data lake querying via Redshift Spectrum, but Databricks offers a more deeply integrated experience for teams that work heavily with unstructured data and ML pipelines.
Starburst and Trino take a federated approach, enabling SQL queries across multiple data sources without requiring data movement. This is particularly valuable for organizations with data spread across multiple systems that want a single query layer rather than consolidating everything into one warehouse.
SingleStore and StarRocks are optimized for real-time analytics. SingleStore combines OLTP and OLAP in one engine with a unique Universal Storage layer (rowstore plus columnstore), handling both transactions and analytics without ETL. StarRocks uses a vectorized execution engine for sub-second query performance on high-concurrency analytical workloads. Both represent a strong alternative when Redshift's batch-oriented design struggles with low-latency use cases.
Teradata VantageCloud and Vertica are enterprise-grade analytical platforms with decades of MPP experience. Teradata supports hybrid multi-cloud deployments with ClearScape Analytics for in-database AI. Vertica provides advanced columnar compression and in-database machine learning. Both target large organizations with complex governance and compliance needs.
TimescaleDB fills a niche for time-series workloads. Built as a PostgreSQL extension, it adds automatic partitioning, columnar compression, and continuous aggregates without requiring teams to leave the PostgreSQL ecosystem.
Pricing Comparison
Pricing models vary significantly across these alternatives, and the right choice depends on your workload patterns and cost predictability requirements.
Redshift offers on-demand pricing with per-node hourly rates, Reserved Instances for steady-state workloads at significant discounts, and a Serverless option that charges based on compute capacity used. Redshift Spectrum charges per number of bytes scanned when querying data in S3. Concurrency Scaling provides up to one hour of free credits per day.
Snowflake uses a consumption-based credit model. Credits are consumed based on virtual warehouse size and runtime, with per-second billing and auto-suspend to avoid paying for idle time. Storage is billed separately. All tiers (Standard, Enterprise, Business Critical, Virtual Private Snowflake) require contacting sales for current credit pricing.
Databricks charges via Databricks Units (DBUs), with rates varying by compute type and subscription tier. Jobs Compute carries lower DBU rates while All-Purpose Compute costs more due to the interactive notebook environment. Critically, Databricks charges are layered on top of your cloud provider infrastructure costs, meaning your actual bill combines DBU fees with underlying VM and storage charges.
Google BigQuery offers on-demand pay-per-query pricing and flat-rate capacity reservations for predictable costs. The on-demand model is ideal for sporadic or exploratory workloads.
Starburst provides a free tier for up to three clusters. Paid tiers use credit-based pricing starting at $0.50/credit for Pro and $0.75/credit for Enterprise, per their published pricing page.
SingleStore offers a free shared workspace tier for development. Paid workspaces use on-demand hourly pricing with reserved pricing available at approximately a 25% discount, according to their pricing calculator.
Trino and StarRocks are open source and free to self-host under permissive licenses. Managed cloud offerings are available for teams that prefer not to operate the infrastructure themselves.
Teradata and Vertica use usage-based pricing models typically negotiated through enterprise sales processes. Contact their sales teams for specific pricing.
TimescaleDB is free when self-hosted as a PostgreSQL extension. Cloud pricing is consumption-based and includes a free trial.
When to Consider Switching
Not every Redshift frustration warrants a migration. We recommend evaluating alternatives when specific patterns emerge in your organization.
Operational complexity is consuming too much engineering time. If your team spends significant hours on cluster sizing, node type selection, workload management queues, and performance tuning, platforms like Snowflake or BigQuery can eliminate most of that overhead. Snowflake's automatic optimization and BigQuery's fully serverless model let data teams focus on analysis rather than infrastructure.
Mixed workloads are causing contention. Redshift handles batch BI workloads well, but mixing ad-hoc exploration, real-time dashboards, and ETL pipelines on the same cluster often leads to queue contention and unpredictable performance. Snowflake's independent virtual warehouses and SingleStore's unified OLTP/OLAP engine address this directly.
You need a lakehouse architecture. If your organization is adopting open table formats like Apache Iceberg and Delta Lake and wants to query data in place without loading it into a proprietary warehouse, Databricks or Starburst provide more native support for this pattern than Redshift Spectrum.
Cost predictability is more important than raw performance. Redshift's cluster-based pricing can lead to overprovisioning when workloads are spiky. BigQuery's pay-per-query model and Snowflake's per-second billing with auto-suspend align costs more closely with actual usage.
You are moving beyond AWS. Redshift is tightly coupled to the AWS ecosystem. If your organization operates across multiple clouds, Snowflake, Databricks, and Teradata all offer multi-cloud support that avoids single-vendor lock-in.
Real-time analytics is a core requirement. If sub-second query latency and high-concurrency real-time workloads are central to your use case, SingleStore and StarRocks are purpose-built for these demands in ways that Redshift's batch-oriented architecture cannot match.
Migration Considerations
Migrating from Redshift requires careful planning across several dimensions.
SQL compatibility varies by platform. Redshift uses a PostgreSQL-compatible SQL dialect, which significantly lowers the barrier to platforms supporting standard ANSI SQL. Most SELECT queries, window functions, and common table expressions port with minimal changes. However, Redshift-specific features like DISTKEY, SORTKEY, DISTSTYLE, and certain system functions require rework since no competitor uses the same distribution model. Stored procedures and UDFs will need translation to each target platform's syntax.
Data transfer is often the most time-consuming step. Redshift's UNLOAD command exports to Parquet on S3, which Snowflake, BigQuery, Databricks, and Starburst all read natively. For teams already using Redshift Spectrum against S3 data lakes, Databricks and Starburst can query those same Parquet and Iceberg tables without any data movement. Most target platforms offer well-documented migration guides specifically for Redshift users.
ETL pipeline updates are critical. Any pipelines writing to Redshift will need reconfiguration. Tools like dbt, Airflow, and Fivetran generally support multiple warehouse backends, making this transition smoother than rewriting custom ETL code. Pipelines built on AWS Glue, Step Functions, or Lambda will need rearchitecting if you leave the AWS ecosystem entirely.
Access control and governance must be rebuilt on the target platform. Redshift's row-level security, column-level permissions, IAM role integration, and VPC configurations do not translate directly. Budget time for recreating these controls in the new platform's security model.
Performance validation should happen before cutover. Run your production query workload against both platforms in parallel to identify regressions. Pay particular attention to complex joins, window functions, and queries against large fact tables where performance characteristics differ between MPP engines.
Cost modeling is essential before committing. Run a proof-of-concept with realistic workloads on the target platform to compare actual costs rather than relying solely on published pricing. Factor in not just compute and storage but also data transfer, egress fees, and any platform-specific charges like Snowflake's cloud services layer or Databricks' underlying infrastructure costs.