Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Signal | Decision relevance |
|---|---|
Deployment | Fully managed service on AWS, Azure and GCP. |
Compute model | Independent virtual warehouses run SQL and Snowpark code in Java, Python and Scala. |
Core billing | Compute credits, storage and data egress are billed separately; ingress is free. Warehouses bill per second, with a 60-second minimum each time they start or resume. |
Trial | 30 days from sign-up, or until the free usage balance is used up, whichever comes first. |
Editor's take
Choose Snowflake if you want separate compute for separate workloads over one copy of your data, and if you share data with other Snowflake accounts. If your workloads run all day, model warehouse size and running time first, because that is what drives the bill.
Evaluate Snowflake
Popular comparisons
See 20 Snowflake comparisons
Where it stands out
Workload isolation. Each virtual warehouse is an independent compute cluster and does not affect the performance of other warehouses. Separate teams or jobs can run on separate compute over the same stored data.
Data sharing. Secure Data Sharing gives read-only access to selected objects without copying data. Shared data uses no storage in the consumer account. Consumers pay only for the compute they use to query it; providers keep paying for storage.
Data scope. Snowflake handles structured, semi-structured and unstructured data, and offers Snowflake tables, Apache Iceberg tables and hybrid tables.
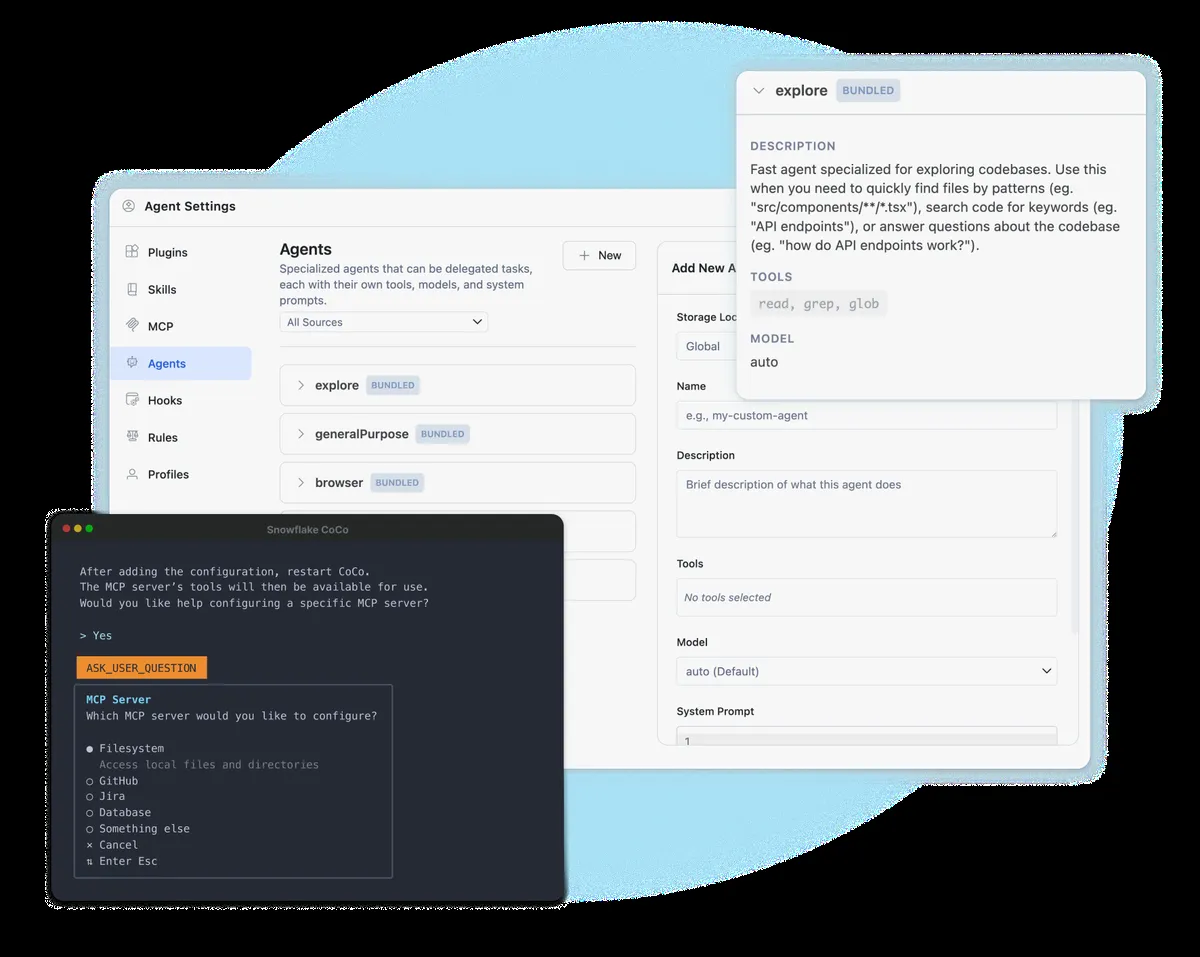
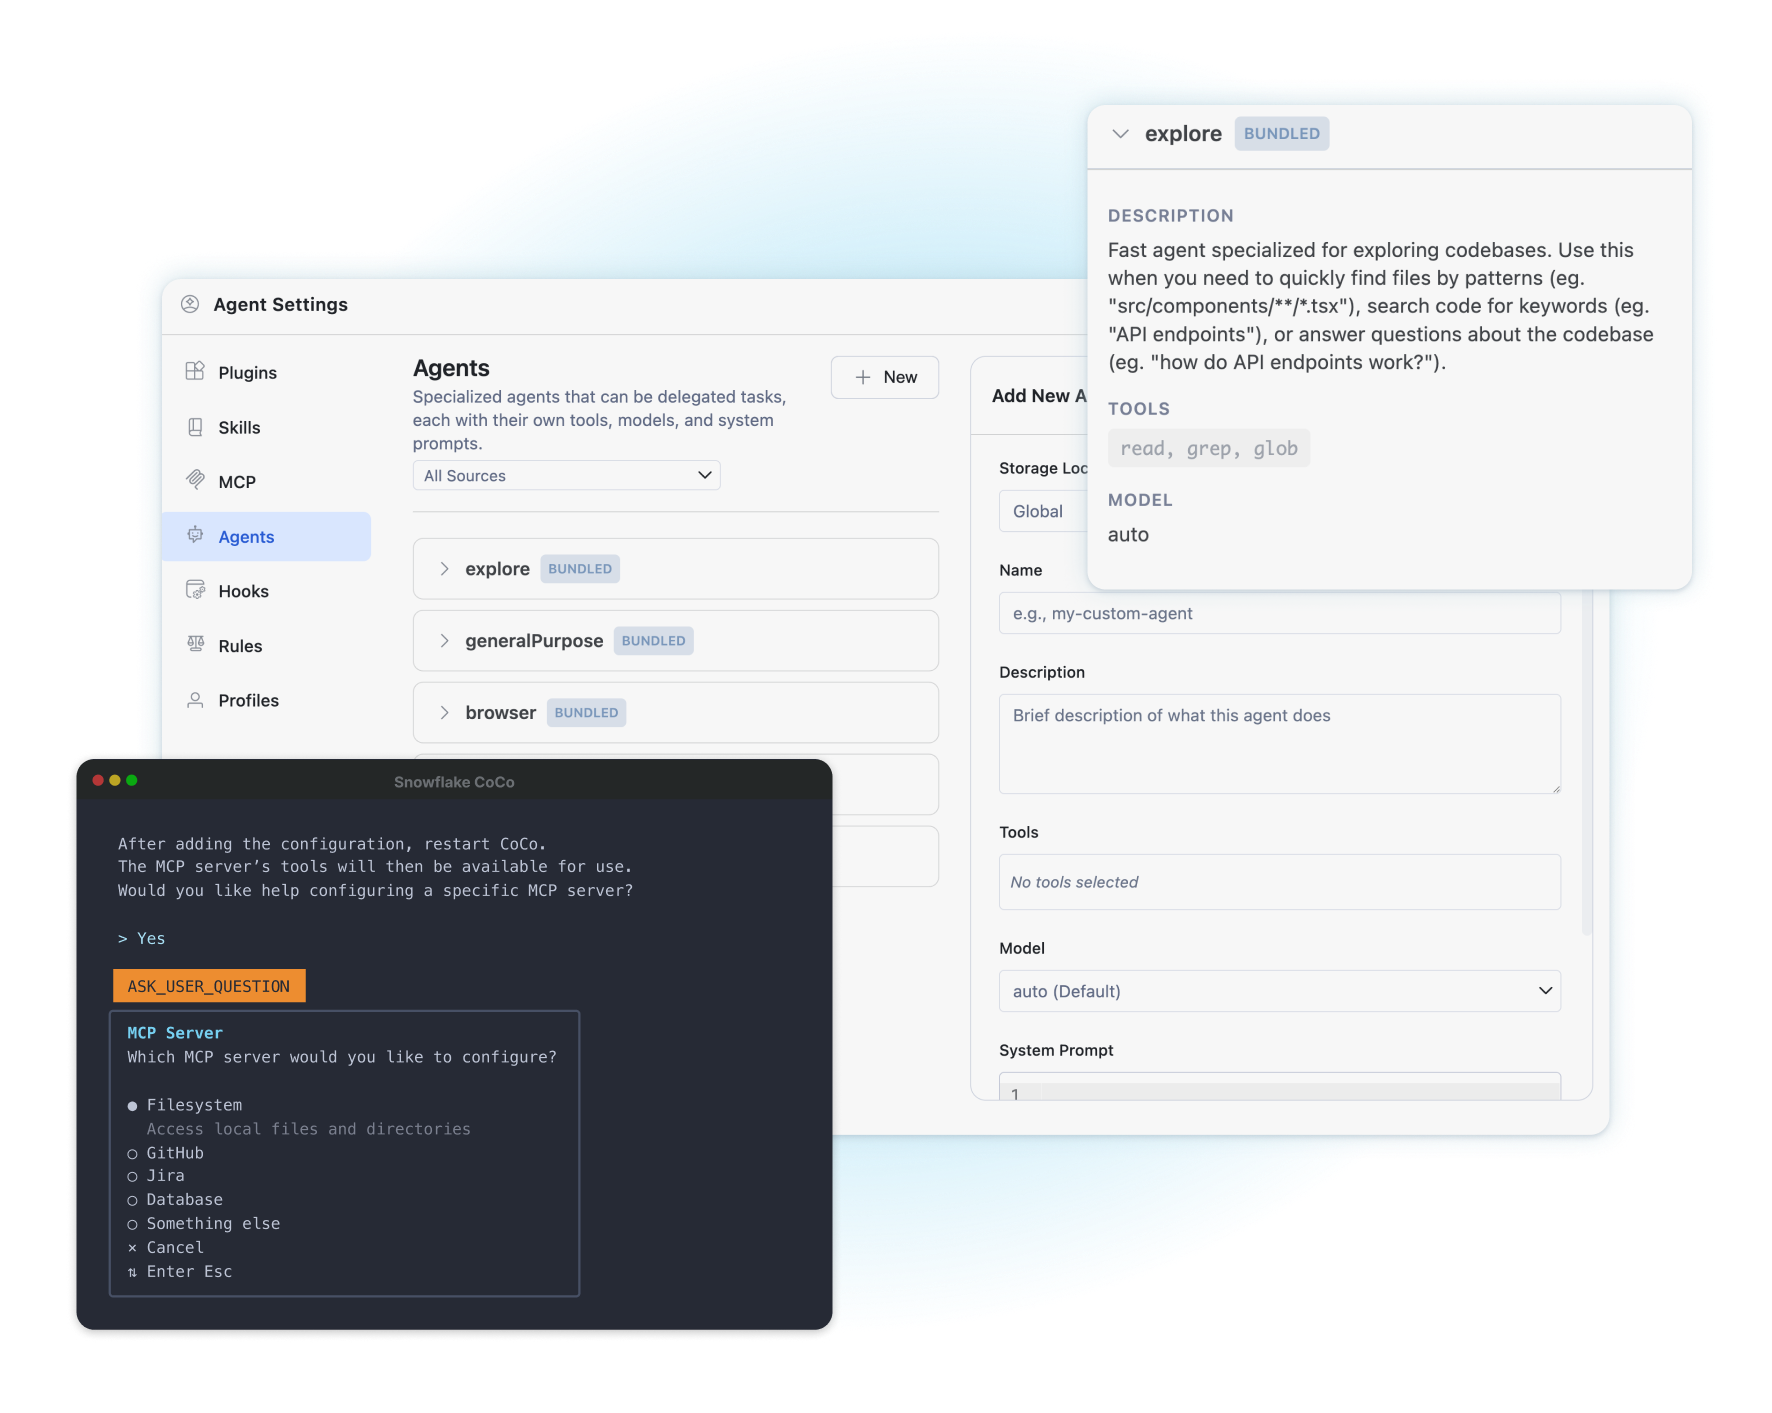
Product screenshot
Trade-offs to test
Warehouse settings are your job. Credits depend on how many warehouses run, for how long and at what size. Each larger size roughly doubles credits per hour, starting from 1 credit per hour for an X-Small Gen1 warehouse. A suspended warehouse uses no credits, but suspending and resuming within the first minute causes multiple charges.
The bill is more than warehouses. Serverless features, compute pools and cloud services also use credits. Cloud services are charged only when daily use exceeds 10% of daily warehouse use. Time Travel and Fail-safe history adds to storage.
Recovery needs affect edition choice. Standard Time Travel retention is 1 day; on Standard Edition it can be 0 or 1 day. On Enterprise Edition and higher, permanent objects can keep up to 90 days. After retention ends, a dropped object cannot be restored. Longer retention adds storage charges.
Direct sharing stays in one region. A direct share works only with accounts in the same region. Sharing across regions or clouds uses a listing with cross-cloud auto-fulfillment, which adds storage and other costs.
Pricing and cost controls
Compute cost is the credits you use multiplied by the price of a credit. Storage is a flat monthly rate per TB, based on the average bytes stored each day; the rate depends on account type (Capacity or On Demand) and region (US or EU). Moving data to another region or cloud adds a per-TB egress fee that depends on your account's region.
Snowflake's documentation gives a monthly total cost example for a Standard Edition account, using example rates of $2 per credit and $23 per TB. Its workload: a Small warehouse (2 credits/hr) loads data 24x7; a Large warehouse (8 credits/hr) runs 9 hours a day for 20 days; a Medium warehouse (4 credits/hr) runs 16 hours a day for 20 days; and a 2X-Large warehouse (32 credits/hr) runs 2 hours a day for 4 days. It stores 65 TB after compression. Compute is 4,464 credits, $8,928 a month; storage is 65 TB, $1,495 a month. The total billed cost of $10,423 a month covers only compute and storage.
The trial deducts warehouse credits, serverless and AI feature use, and storage at the standard On Demand rate from its free balance. When the trial ends, the account is suspended unless you upgrade.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
68 GitHub commits 90d733 GitHub stars0 vulnerabilities across 2 packagesOpenSSF score 4.3/10
See all signals from 8 sources
PyPI · snowflake-connector-python@5.2.0 · npm · snowflake-sdk@3.4.1
Alternatives to Snowflake
The reviewed substitutes for Snowflake among the cloud data warehouses, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Google BigQuery
- Both are cloud data warehouses bought for the same job: the central SQL analytics store. A team picks one.
- Amazon Redshift
- Both are cloud data warehouses bought for the same job. Redshift is the AWS-native answer to the same requirement.
- Teradata
- Two analytical warehouses serving the same central-store decision. They are compared for one budget, differ on pricing shape and deployment, and an organisation loads its data into one.Applies to: Choosing the warehouse that will hold the organisation's analytical data.
- Firebolt
- Two analytical warehouses serving the same central-store decision. They are compared for one budget, differ on pricing shape and deployment, and an organisation loads its data into one.Applies to: Choosing the warehouse that will hold the organisation's analytical data.
- Vertica
- Large SQL workloads for reporting and data science can run on Snowflake or on Vertica. Snowflake is a fully managed service on all major clouds with separate compute and storage. Vertica is columnar software a team operates itself, on-premises or in the cloud, which appeals to teams that want to keep control of their hardware.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Databricks
- Snowflake and Databricks are a warehouse-first and a lakehouse-first answer to the same analytics estate. Snowflake is a fully managed SQL platform with compute separated from storage, while Databricks builds on open lake storage, managed Spark and notebooks, so they are not drop-in substitutes.Applies to: Choosing the primary analytics platform, where the decision is warehouse-centric SQL against lakehouse-centric open storage and Spark.
- SingleStore
- Snowflake and SingleStore both run SQL analytics at scale. Snowflake is a managed warehouse for batch and interactive analysis across a company's data. SingleStore is a distributed database that also takes transactional writes, so it fits when the same system must serve live application data and fast analytics on it.Applies to: Serving fast analytical queries, and whether the central warehouse can also carry them.
- Starburst
- A warehouse that owns its storage and a lakehouse or federated engine that queries data in open formats reach the same analytics by different architectures. The decision is whether data is loaded into one platform or left in object storage and queried where it sits, which is why these appear together on central-store shortlists.Applies to: Deciding whether analytical data is loaded into one platform or queried in open formats where it sits.
- Trino
- A managed warehouse and a federated query engine answer the same analytical question by different architectures: Snowflake owns storage and compute, Trino queries data where it already sits. Third-party head-to-heads frame it as managed warehouse or federation, so the generated 'complementary' proposal understates a real either/or.Applies to: Analytics over data spread across several stores, where centralising is optional.
- Dremio
- A warehouse that owns its storage and a lakehouse or federated engine that queries data in open formats reach the same analytics by different architectures. The decision is whether data is loaded into one platform or left in object storage and queried where it sits, which is why these appear together on central-store shortlists.Applies to: Deciding whether analytical data is loaded into one platform or queried in open formats where it sits.
Head to head
See detailed alternatives analysis
If you are evaluating Snowflake alternatives, you are likely looking for a cloud data platform that better fits your architecture, pricing model, or workload profile. Snowflake is a fully managed cloud data warehouse that separates compute from storage and runs on AWS, Azure, and Google Cloud. It excels at SQL analytics with automatic scaling and near-zero maintenance. However, depending on your team's needs around data engineering, real-time analytics, open-source flexibility, or cost structure, several strong alternatives deserve consideration.
Top Alternatives Overview
We have identified ten alternatives that cover a range of architectures and use cases within the cloud data warehouse space.
Databricks takes a lakehouse approach, unifying data lake and data warehouse capabilities on a single platform built around Apache Spark. It is particularly strong for data engineering, machine learning, and teams that need both batch and streaming workloads in one environment. Users consistently praise its development environment for data science and its ability to handle complex queries on raw data at scale.
Amazon Redshift is AWS's native cloud data warehouse, delivering fast query performance through columnar storage and massively parallel processing. Teams already invested in the AWS ecosystem benefit from tight integrations with S3, Glue, SageMaker, and QuickSight. Redshift Serverless lets you run analytics without provisioning infrastructure.
Google BigQuery is a fully serverless data warehouse from Google Cloud with pay-per-query pricing and a generous free tier. It requires zero infrastructure management and scales automatically, making it a natural fit for teams already using Google Cloud Platform services.
SingleStore (formerly MemSQL) combines transactional and analytical workloads in a single distributed SQL database. It is designed for real-time analytics on operational data without requiring ETL pipelines, which makes it appealing for use cases that demand low-latency query responses.
Starburst, built on the Trino query engine, provides federated query access across data lakes, warehouses, and databases from a single point of entry. Its free-tier offering and credit-based pricing make it accessible for teams that need to query data in place without moving it.
Teradata Vantage is an enterprise analytics platform supporting hybrid multi-cloud deployments. It serves organizations with demanding compliance and governance requirements who need flexibility across on-premises and cloud environments.
Trino (formerly PrestoSQL) is an open-source distributed SQL query engine that can query data from multiple sources. Self-hosted under the Apache 2.0 license, it appeals to teams that want full control without vendor lock-in.
Elasticsearch is a distributed search and analytics engine built on Apache Lucene. While not a traditional data warehouse, it excels at search, logging, and observability workloads where full-text search and real-time indexing matter most.
Dremio is a data lakehouse platform enabling SQL analytics directly on data lakes using Apache Iceberg and Parquet formats, without requiring data movement. Its focus on eliminating ETL and delivering fast query performance on open formats makes it a strong option for lakehouse-first strategies.
Firebolt is a cloud data warehouse built for high-performance analytics, particularly within ad-tech and similar latency-sensitive domains. It emphasizes sub-second query speeds on large datasets with columnar compression.
Architecture and Approach Comparison
The fundamental architectural distinction among these alternatives lies in how they handle compute, storage, and data access patterns.
Snowflake pioneered the separation of compute and storage in cloud data warehousing, allowing each to scale independently. You pay for compute credits when warehouses run and for storage separately. This architecture delivers excellent concurrency handling and workload isolation through virtual warehouses.
Databricks takes a different path with its lakehouse architecture, storing data in open formats (Delta Lake) on cloud object storage while providing managed Apache Spark clusters for processing. This approach gives data engineering and ML teams native access to both structured and unstructured data without needing separate systems. The trade-off is that cluster management, while simplified, still requires more operational awareness than Snowflake's fully managed warehouses.
Amazon Redshift uses a traditional MPP (massively parallel processing) architecture with columnar storage. Its Serverless option eliminates capacity planning, but provisioned clusters still require sizing decisions. Redshift's deep integration with the AWS ecosystem, including zero-ETL connections with Aurora, DynamoDB, and Kinesis, gives it an edge for organizations already running workloads on AWS.
Google BigQuery is truly serverless, abstracting away all infrastructure. You submit queries and pay for data scanned (or reserve slots for predictable workloads). This removes operational overhead entirely but gives you less control over query execution compared to Snowflake's warehouse model.
Starburst and Trino represent the federated query approach. Rather than centralizing data into a single warehouse, they query data where it lives across multiple sources. This eliminates data duplication and movement but introduces dependency on network performance and source system availability.
Dremio and Firebolt focus on performance optimization at the storage layer. Dremio accelerates queries on open lakehouse formats like Apache Iceberg and Parquet, while Firebolt uses proprietary indexing and compression for sub-second analytics. Both target teams frustrated by the query performance limitations of general-purpose warehouses on specific workload patterns.
Pricing Comparison
Pricing models across these alternatives vary significantly in structure and predictability.
Snowflake uses consumption-based pricing measured in credits. The credit cost varies by edition: Standard, Enterprise, Business Critical, and Virtual Private Snowflake (VPS) editions each carry different per-credit rates. Storage is billed separately per compressed terabyte per month. All edition pricing requires contacting sales for a custom quote. Snowflake offers a free trial to get started.
Databricks also uses consumption-based pricing through Databricks Units (DBUs). DBU rates differ by compute type (Jobs, All-Purpose, SQL, Serverless, Model Serving) and by subscription tier (Standard, Premium, Enterprise). On top of DBU charges, you pay your cloud provider separately for the underlying VMs and storage. Databricks offers a free Community Edition for learning and a 14-day free trial.
Amazon Redshift offers both provisioned and serverless pricing. Provisioned clusters are billed by node-hour, while Redshift Serverless charges based on compute capacity used. AWS provides new Serverless accounts a $300 credit expiring after 90 days, not a free tier.
Google BigQuery provides on-demand pricing where you pay per terabyte of data processed, with the first terabyte each month free. For predictable workloads, flat-rate slot reservations are available. This model makes BigQuery particularly cost-effective for intermittent or exploratory analytics.
Starburst offers a free tier with up to three clusters, with paid tiers using per-credit pricing. Trino is free and open-source when self-hosted, though you bear the infrastructure and operational costs. A managed cloud version is also available.
SingleStore, Teradata, Dremio, and Firebolt each use variations of usage-based or capacity-based pricing. Contact their sales teams for current quotes, as pricing depends on deployment configuration and scale.
The key insight for cost planning: Snowflake's credit model can be straightforward for SQL-heavy analytics workloads, while Databricks' dual-layer cost structure (DBUs plus cloud infrastructure) requires more careful modeling. BigQuery's pay-per-scan model rewards query efficiency, and open-source options like Trino shift costs from licensing to infrastructure management.
When to Consider Switching
Switching from Snowflake makes sense under specific circumstances tied to workload requirements, team expertise, and cost dynamics.
Data engineering and ML focus. If your team spends more time building data pipelines, training models, and running streaming workloads than executing SQL queries, Databricks' native Spark environment and ML tooling (MLflow, Mosaic AI) provide a more natural workflow. Snowflake's Snowpark is improving here, but Databricks remains the stronger platform for engineering-heavy teams.
AWS-native strategy. Organizations that have standardized on AWS and want to minimize cross-service data movement may find Redshift's zero-ETL integrations with Aurora, DynamoDB, and Kinesis more efficient than routing data through Snowflake. The tight SageMaker integration also benefits ML-oriented AWS shops.
Cost sensitivity with intermittent usage. If your analytics workloads are sporadic rather than continuous, BigQuery's pay-per-scan model can be significantly cheaper than maintaining Snowflake warehouses, even with auto-suspend configured. You pay nothing when no queries run.
Multi-source federated access. Teams that need to query across multiple databases, data lakes, and SaaS applications without centralizing data into a single warehouse should evaluate Starburst or Trino. This approach avoids the ETL overhead and storage duplication that comes with loading everything into Snowflake.
Open-source and vendor independence. If avoiding vendor lock-in is a strategic priority, Trino and Dremio (built on open formats like Apache Iceberg) provide paths to keep your data in open, portable formats while still delivering strong SQL analytics.
Real-time operational analytics. For workloads that require sub-second query responses on live operational data, SingleStore's combined OLTP/OLAP engine or Firebolt's specialized indexing may outperform Snowflake's batch-oriented architecture.
Migration Considerations
Moving away from Snowflake requires careful planning across several dimensions.
SQL compatibility. Snowflake supports ANSI SQL with proprietary extensions. Most alternatives (Redshift, BigQuery, Databricks SQL, SingleStore) also support standard SQL, but syntax differences in window functions, semi-structured data handling (VARIANT type), and stored procedures will require query refactoring. Budget time for testing and rewriting complex queries.
Data format and transfer. Snowflake stores data in a proprietary internal format, so you will need to export data (typically to Parquet, CSV, or Avro) before loading into a new platform. For large datasets, use Snowflake's COPY INTO command to unload data to cloud storage, then load from there. Cross-cloud transfers incur network transfer costs that can add up for multi-terabyte datasets.
Feature parity gaps. Snowflake features like Time Travel, zero-copy cloning, secure data sharing, and the Snowflake Marketplace do not have direct equivalents in every alternative. Map your usage of these features and identify workarounds before committing to a migration. For example, Databricks offers Delta Lake versioning as a Time Travel equivalent, and BigQuery provides time-travel snapshots, but retention windows differ.
Ecosystem and tooling. Evaluate your BI tools, ETL pipelines, and orchestration systems for compatibility with the target platform. Most modern tools (dbt, Fivetran, Airbyte, Tableau, Looker) support multiple warehouses, but connector maturity and performance can vary across platforms.
Governance and security. If you rely on Snowflake's row-level security, dynamic data masking, or network policies, verify equivalent capabilities in the target platform. Regulated industries should pay particular attention to compliance certifications and encryption standards when evaluating Business Critical-tier feature equivalents.
Incremental approach. Rather than a full cutover, we recommend running the new platform alongside Snowflake for a transition period. Start by migrating lower-risk workloads like development and staging environments, measure performance and cost, and expand from there. This reduces risk and gives your team time to build expertise on the new platform before moving production systems.
Evidence
This review uses Snowflake documentation and product pages observed on October 16 and October 26, 2026. Rates vary by region, account type and edition; check them for your own deployment.