Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Apache Spark states |
|---|---|
License and cost basis | An open source project; the project counts over 2,000 contributors. You run it on your own single-node machines or clusters. |
Installation | Install with pip install pyspark, run the official Docker image (for example spark:python3), use a pre-built package, or build from source with Apache Maven. |
Where it runs | Locally with one thread ("local") or N threads ("local[N]"), on a standalone cluster through a spark:// URL, or on YARN. The repository also has a Kubernetes integration test. |
Languages | APIs in Scala, Java and Python, plus SQL. The R API is marked deprecated in the repository README. |
Built-in modules | Spark SQL for SQL and DataFrames, pandas API on Spark, MLlib for machine learning, GraphX for graph processing and Structured Streaming for stream processing. |
Hadoop storage | Spark uses the Hadoop core library to reach HDFS and other Hadoop-supported storage, and must be built against the same Hadoop version your cluster runs. |
Our take
Choose Apache Spark if your team wants one engine for batch, streaming, SQL and machine learning on large data, and can run and tune its own clusters. If no one on the team will own cluster operations, Spark is a poor default.
Evaluate Apache Spark
Popular comparisons
See all 7 Apache Spark comparisons
Where it stands out
Batch and streaming in one engine. Spark processes data in batches and in real-time streaming with the same engine, in Python, SQL, Scala or Java. Teams do not need a second processing system for each workload type.
Same code from laptop to cluster. According to the project, machine learning code trained on a laptop can scale, unchanged, to fault-tolerant clusters of thousands of machines. If that holds for your models, a prototype need not be rewritten to grow.
Analysis on full datasets. The project states you can run exploratory data analysis on petabyte-scale data without downsampling, which matters when a sample would hide the pattern you look for.
SQL that adapts at runtime. Spark SQL runs distributed ANSI SQL for dashboards and ad-hoc reports. Adaptive Query Execution changes the plan while the query runs, for example the number of reducers and the join algorithm. The project's own chart shows TPC-DS 1TB queries (no statistics) up to 8x faster with Adaptive Query Execution than without it.
Structured and unstructured data. Spark SQL works on structured tables and on unstructured data such as JSON or images.
Quick to try. The README shows a one-line count in ./bin/spark-shell or ./bin/pyspark, and ./bin/run-example SparkPi runs a sample program locally, so a team can test it before planning a cluster.
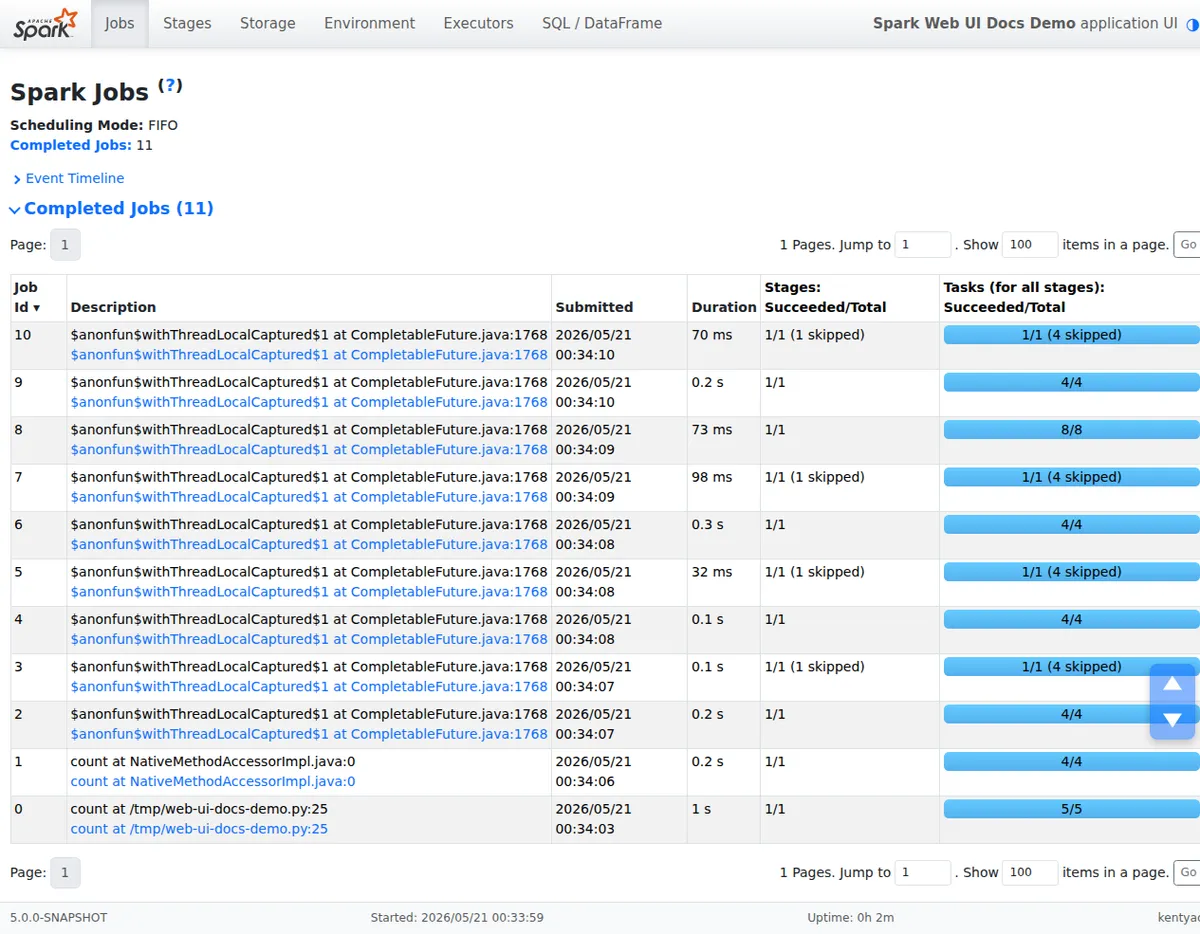
Product screenshot

Trade-offs to weigh
You own the cluster. The project ships the engine and cluster modes; capacity, configuration and upgrades are your team's job. Budget engineering time for this, as the open source license does not remove the cost of machines and people.
Hadoop version lock. Because Spark must match your cluster's Hadoop version, an upgrade on one side can force a rebuild or upgrade on the other.
R users should plan ahead. With the R API deprecated, teams that rely on SparkR should check its future before building new work on it.
Read speed claims carefully. The project says Spark SQL runs faster than most data warehouses. Treat that as the vendor's claim and test your own queries before moving work off a warehouse.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
1.4k GitHub commits 90d44.4k GitHub stars0 vulnerabilities across 1 packageOpenSSF score 5.6/10
See all signals from 8 sources
PyPI · pyspark@4.3.0
Alternatives to Apache Spark
The reviewed substitutes for Apache Spark among the data processing engines, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Apache Beam
- Two distributed processing engines or programming models for the same batch and streaming computation. They are compared directly on runtime portability, streaming semantics and operational cost, and a team builds on one.Applies to: Choosing the engine that will run distributed batch and streaming computation.
- Apache Flink
- Apache Spark and Apache Flink are open-source engines for processing large volumes of data across a cluster, in batch and as streams. Spark started from batch work and bundles SQL, machine learning and graph modules, while Flink was designed around stateful stream processing and includes a library for detecting event patterns.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Databricks
- Databricks and Apache Spark both process large volumes of data for engineering and machine learning with the Spark engine. Databricks sells that engine as a managed lakehouse platform with notebooks, Delta Lake storage and ML tooling, while open-source Spark fits teams ready to deploy, tune and upgrade their own clusters.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Apache Airflow
- Programmatically author, schedule and monitor workflowsApplies to: Whether a processing engine needs an orchestrator, or schedules its own work.
- Apache Kafka
- A streaming platform stores and delivers ordered events; a processing engine computes over them. The documented architecture runs the engine against the platform's topics, so the pair is a transport-and-compute pairing rather than a substitution.Applies to: Whether an event streaming platform can process events itself, or needs a compute engine.
- Prefect
- Python-native workflow orchestration with managed cloud control planeApplies to: Whether a processing engine needs an orchestrator, or schedules its own work.
- Fivetran
- The two sit at different layers of one system and the documented deployments run them together, so the reader's question is which job each one does rather than which to buy.Applies to: Whether these two do the same job, or different jobs in one pipeline.
- Dagster
- Asset-centric data orchestrator with built-in lineage, observability, and dbt integrationApplies to: Whether a processing engine needs an orchestrator, or schedules its own work.
Head to head
See detailed alternatives analysis
If you are exploring Apache Spark alternatives, you are not alone. While Spark remains one of the most widely adopted engines for large-scale data processing, teams often encounter scenarios where a different tool better fits their architecture, budget, or real-time processing requirements. Whether you need true event-by-event streaming, simpler workflow orchestration, or a managed data integration platform, the ecosystem offers compelling options worth evaluating.
Top Alternatives Overview
Apache Spark occupies a unique position as an open-source unified analytics engine supporting batch processing, SQL analytics, streaming (via micro-batching), and machine learning. It is written primarily in Scala, supports Python, Java, R, and SQL APIs, and has accumulated over 43,000 GitHub stars under the Apache-2.0 license. Its breadth makes it a go-to choice for organizations with diverse data workloads, but that same breadth can introduce complexity that more focused tools avoid.
Apache Flink is the leading alternative for teams that prioritize true real-time stream processing. Unlike Spark's micro-batch approach, Flink processes events individually as they arrive, delivering low latency for use cases like fraud detection, anomaly monitoring, and event-driven architectures. Flink provides exactly-once state consistency, sophisticated event-time processing with watermarks, and advanced windowing capabilities. It has earned a 9.0/10 rating on PeerSpot and holds over 25,000 GitHub stars. Flink treats batch processing as a special case of streaming (bounded streams), which gives it architectural elegance for teams building stream-first platforms.
Apache Beam offers a fundamentally different value proposition: a unified programming model that lets you write pipelines once and run them on multiple execution engines, including Flink, Spark, and Google Cloud Dataflow. Beam supports Java, Python, and Go SDKs, and its portability layer prevents vendor lock-in. Organizations like LinkedIn process trillions of events daily through Beam-based pipelines, and Booking.com uses it to scan over 2PB of data daily. With over 8,500 GitHub stars, Beam is particularly attractive when you want to decouple your pipeline logic from the underlying execution engine.
Apache Airflow serves a complementary but distinct role as a workflow orchestration platform rather than a data processing engine. Originally built at Airbnb, Airflow excels at scheduling, dependency management, and monitoring of batch-oriented DAG (Directed Acyclic Graph) workflows using Python. It has over 45,000 GitHub stars and an 8.7/10 PeerSpot rating across 58 reviews. Airflow is the right choice when your primary need is orchestrating multi-step pipelines that coordinate between various processing tools, databases, and cloud services rather than performing the heavy data transformations yourself.
Apache Kafka is the de facto standard for distributed event streaming. While Spark is a processing engine, Kafka is a message broker and streaming platform used by over 80% of Fortune 100 companies. With over 32,000 GitHub stars and an 8.6/10 PeerSpot rating across 151 reviews, Kafka excels at high-throughput, fault-tolerant data ingestion and real-time event distribution. Teams often use Kafka alongside Spark or Flink rather than as a direct replacement, but Kafka Streams and ksqlDB enable lightweight stream processing without a separate compute cluster.
Confluent builds on Kafka's foundation by offering a fully managed data streaming platform with enterprise features. Founded by Kafka's original creators, Confluent provides Confluent Cloud (managed Kafka), over 120 pre-built connectors, and integrated Apache Flink for stream processing. It holds a 9.2/10 PeerSpot rating across 27 reviews. Confluent is worth considering when you want Kafka's capabilities without the operational burden of managing clusters yourself.
Architecture and Approach Comparison
The fundamental architectural difference between these tools lies in their processing models. Apache Spark uses a micro-batch approach for streaming, where incoming data is collected into small batches (typically measured in hundreds of milliseconds to seconds) and processed using the same engine that handles batch workloads. Spark's core abstraction is the Resilient Distributed Dataset (RDD), though modern usage favors the higher-level DataFrame and Dataset APIs optimized by the Catalyst query optimizer and Tungsten execution engine. This unified engine approach means teams can reuse code between batch and streaming contexts, but it introduces inherent latency that true event-by-event systems avoid.
Apache Flink, by contrast, was built from the ground up as a native streaming engine. Every event is processed individually as it arrives, and batch processing is treated as a bounded stream. Flink's state management uses the Chandy-Lamport algorithm for distributed snapshots, enabling it to maintain large amounts of local state (often backed by RocksDB) while providing exactly-once processing guarantees. Flink provides layered APIs ranging from high-level SQL on both stream and batch data down to the low-level ProcessFunction for fine-grained control over time and state. This makes Flink the stronger choice for applications requiring very low latency, complex event processing, or large managed state.
Apache Beam sits at an abstraction layer above both Spark and Flink. Its portable pipeline model compiles down to whatever runner you choose, which means the same pipeline code can execute on Spark, Flink, Google Dataflow, or other supported backends. Beam pipelines define data transformations using PCollections and PTransforms that the chosen runner then executes. This portability comes with trade-offs: you may not be able to leverage runner-specific optimizations, and debugging can be more complex when issues arise in the translation layer between Beam and the underlying engine.
Apache Airflow operates at the orchestration layer rather than the processing layer. It does not process data itself but coordinates tasks across other systems using DAGs defined in Python. Airflow's scheduling model supports time-based triggers, dependency management between tasks, and monitoring through a web-based UI. In many production environments, Airflow orchestrates jobs that run on Spark, Flink, or other engines, making it complementary rather than competitive.
Kafka and Confluent focus on the data transport and ingestion layer. Kafka's distributed commit log architecture provides durable, ordered, and replayable streams of events. While Kafka Streams offers embedded stream processing within applications, it is designed for lighter workloads than what Spark or Flink handle. Confluent extends this with managed infrastructure, schema registry, governance features, and integrated Flink-based stream processing for heavier analytical workloads.
Pricing Comparison
Apache Spark, Flink, Beam, Airflow, and Kafka are all open-source projects released under the Apache License 2.0, meaning there are no software licensing fees. However, total cost of ownership varies significantly based on infrastructure, operational complexity, and whether you use managed services.
Self-hosted Spark clusters require investment in cluster management, tuning, and operations. Many teams opt for managed Spark offerings from cloud providers (such as Databricks, Amazon EMR, or Google Dataproc), where costs scale with compute and storage consumption. Similarly, self-hosted Flink and Kafka clusters demand significant operational expertise for proper resource allocation, checkpointing configuration, and high-availability setups.
Confluent offers tiered pricing for its managed platform: a Basic tier at no monthly commitment, Standard at a fixed monthly rate, and Enterprise and Freight tiers for larger deployments, with usage-based rates on top. This model suits teams that prefer predictable managed infrastructure over the operational overhead of running open-source Kafka and Flink themselves.
Airflow is free to self-host, but managed Airflow services (like Astronomer or Amazon MWAA) provide hosted environments with pay-as-you-go pricing. Beam itself has no cost, but costs depend entirely on the chosen runner: running on Google Cloud Dataflow incurs usage-based cloud charges, while running on self-hosted Spark or Flink carries the infrastructure costs of those engines.
For teams evaluating managed data integration rather than building processing infrastructure, tools like Fivetran and Hevo Data offer usage-based pricing models with free tiers. Fivetran provides a free tier for one user with Standard plans available, while Hevo Data offers a free tier covering initial data volumes with Pro plans for larger workloads. These can be more cost-effective for straightforward ELT workloads that do not require the full power of a distributed processing engine.
When to Consider Switching
Consider moving to Apache Flink if your workloads demand true real-time, event-by-event processing with low latency. Spark's micro-batch streaming introduces inherent delays that are unacceptable for fraud detection, real-time bidding, or IoT sensor monitoring where every millisecond matters. Flink's native streaming architecture, advanced state management, and exactly-once consistency guarantees make it the preferred choice for latency-sensitive applications.
Consider Apache Beam if you are concerned about execution engine lock-in. Beam's write-once, run-anywhere model allows you to switch between Spark, Flink, and cloud-native runners without rewriting pipeline logic. This provides long-term architectural flexibility, especially for organizations that operate across multiple cloud providers or anticipate changing their processing infrastructure.
Consider Apache Airflow if your primary challenge is workflow orchestration rather than data processing. If you are using Spark primarily to schedule and coordinate pipeline steps rather than for its distributed compute capabilities, Airflow provides purpose-built scheduling, dependency management, and monitoring with a mature web UI and extensive operator ecosystem.
Consider Apache Kafka or Confluent if your core need is reliable, high-throughput event streaming and data integration rather than heavy analytical processing. Kafka's lightweight stream processing (via Kafka Streams or ksqlDB) can handle many real-time use cases without the overhead of maintaining a separate Spark or Flink cluster. Confluent adds managed operations on top for teams that want to reduce infrastructure management.
Consider managed ELT platforms like Fivetran or Hevo Data if your data integration needs center on extracting data from SaaS applications and databases into a cloud warehouse. These tools handle connector maintenance and schema evolution automatically, removing the need to build and operate custom Spark-based ingestion pipelines.
Stay with Spark if you need a single engine that handles batch analytics, SQL queries, machine learning (via MLlib), and streaming in one unified framework, especially if your team already has deep Spark expertise and your latency requirements are measured in seconds rather than milliseconds.
Migration Considerations
Migrating away from Apache Spark requires careful planning around several dimensions. First, assess your current workload mix: Spark's unified engine means you may be using it for batch ETL, ad-hoc SQL queries, ML training, and streaming simultaneously. A migration may involve splitting these workloads across multiple specialized tools rather than finding a single replacement.
For teams moving streaming workloads to Flink, the transition involves learning Flink's DataStream API and its approach to state management, checkpointing, and watermarks. While the conceptual models share similarities (both use distributed parallel processing across clusters), Flink's event-at-a-time semantics require rethinking windowing logic and state handling. Flink's core APIs are Java-based, though PyFlink is maturing for teams with Python-heavy codebases. Teams report that Flink has a steeper initial learning curve but delivers better performance for latency-sensitive streaming.
If adopting Apache Beam, the migration path involves rewriting pipeline logic using Beam's SDK while choosing an appropriate runner. The advantage is that future migrations between runners become straightforward. However, some Spark-specific optimizations (like Adaptive Query Execution) may not have direct Beam equivalents, potentially affecting performance for complex batch workloads.
Moving orchestration responsibilities to Airflow is typically lower risk since Airflow can orchestrate Spark jobs as tasks within its DAGs. Many organizations adopt Airflow incrementally, starting by wrapping existing Spark jobs in Airflow operators before gradually refactoring the pipeline architecture.
Data format compatibility is generally not a barrier: Parquet, ORC, Avro, JSON, and CSV are supported across all these tools. Integration with storage systems like HDFS, S3, Azure Blob Storage, and cloud data warehouses is well supported by each alternative. The primary migration costs are in rewriting processing logic, retraining teams on new APIs and operational models, and rebuilding monitoring and troubleshooting procedures for the new tool's specific behavior.