Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What the project states |
|---|---|
License | Apache License 2.0. |
Installation | Build from source in a Unix-like environment (Linux, Mac OS X, Cygwin or WSL) with Git, the Maven wrapper and Java 11, 17 or 21; Java 17 is the default. The build takes about 10 minutes and installs Flink in build-target. |
Where it runs | The project says Flink is designed to run in all common cluster environments. It integrates with YARN, HDFS, HBase and other Apache Hadoop components, and the community releases a Flink Kubernetes Operator. |
APIs | Layered APIs: SQL on stream and batch data, the DataStream API, and ProcessFunction for control over time and state. |
Support | Community help on the mailing lists, an issue to open if you find a bug, and documentation on flink.apache.org or in the docs/ directory of the source code. |
Our take
Choose Apache Flink when your main workload is stateful processing of live event streams, such as event-driven applications or continuous analytics, and results must stay correct when events arrive late or a job fails. It fits best when your team can build, configure and run a distributed processing engine.
Evaluate Apache Flink
Comparisons
Where it stands out
Correct results on messy streams. Flink offers exactly-once state consistency, event-time processing and handling of late data. The DataStream API supports out-of-order processing based on the Dataflow Model, with windows by time, count, session or custom trigger in event time or processing time.
Built for large state and recovery. The project lists a scale-out architecture, support for very large state, incremental checkpoints, savepoints and a high-availability setup. Streaming programs also get natural back-pressure.
One engine for streams and batch. The runtime is streaming-first but also runs batch programs, so the same system can serve continuous queries on live streams and traditional batch queries on bounded data sets.
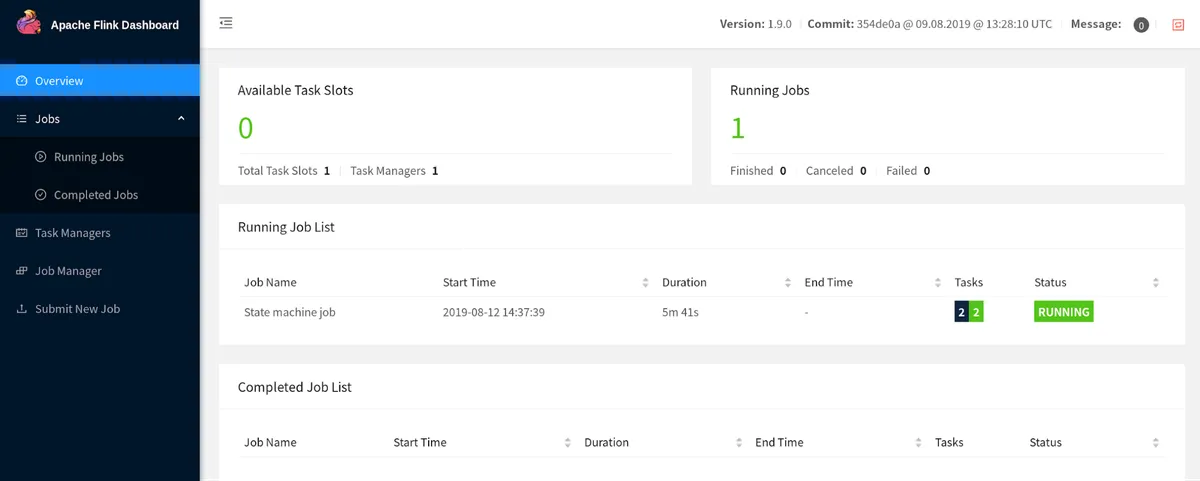
Product screenshot
Trade-offs to weigh
Graph and machine learning libraries target batch. The bundled libraries cover graph processing and machine learning on batch data, and complex event processing on streams. Check this before planning streaming graph or machine learning jobs.
Connectors live in separate repositories. Most Flink connectors, including Kafka, JDBC, Hive, Elasticsearch, MongoDB, Pulsar and AWS, are kept in individual Apache Software Foundation repositories, so each one is a separate project to track alongside Flink itself.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
507 GitHub commits 90d26.5k GitHub stars0 vulnerabilities across 1 package
See all signals from 7 sources
PyPI · apache-flink@2.3.0
Alternatives to Apache Flink
The reviewed substitutes for Apache Flink among the data processing engines, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Apache Beam
- Choose this if you want runner-agnostic pipelines that avoid vendor or engine lock-in.Applies to: Choosing the engine that will run distributed batch and streaming computation.
- Apache Spark
- Apache Spark and Apache Flink are open-source engines for processing large volumes of data across a cluster, in batch and as streams. Spark started from batch work and bundles SQL, machine learning and graph modules, while Flink was designed around stateful stream processing and includes a library for detecting event patterns.Applies to: Choosing between two products of the same kind for one job.
- Google Cloud Dataflow
- Apache Flink and Google Cloud Dataflow both process streaming and batch data with stateful, scalable pipelines. Flink is an open-source engine that teams deploy on their own clusters or through a managed service, while Dataflow is Google's fully managed, autoscaling service that runs Apache Beam pipelines on Google Cloud.Applies to: Choosing between two products of the same kind for one job.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Apache Kafka
- A streaming platform stores and delivers ordered events; a processing engine computes over them. The documented architecture runs the engine against the platform's topics, so the pair is a transport-and-compute pairing rather than a substitution.Applies to: Whether an event streaming platform can process events itself, or needs a compute engine.
- NATS
- Flink computes over streams that a broker transports; it is deployed alongside NATS rather than instead of it. A pipeline runs both -- NATS carries the events, Flink does the stateful processing -- so presenting either as an alternative to the other would misdescribe the architecture.Applies to: Stateful stream processing: NATS transports the events, Flink runs the windowed and stateful computation over them.
Head to head
See detailed alternatives analysis
If you are evaluating Apache Flink alternatives, you are likely looking for a stream processing or data pipeline tool that better fits your team's skill set, operational budget, or architectural requirements. Flink is a powerhouse for stateful stream processing with sub-millisecond latency and exactly-once semantics, but its steep learning curve and resource-intensive cluster management push many teams toward other options. We have reviewed the leading alternatives across open-source stream processors, managed platforms, and workflow orchestrators to help you make the right call.
Top Alternatives Overview
Apache Beam is a unified programming model that lets you write batch and streaming pipelines once and run them on Flink, Spark, or Google Cloud Dataflow without code changes. With 8,500+ GitHub stars and SDKs for Java, Python, Go, and Scala, Beam gives teams portability that Flink cannot match on its own. LinkedIn processes 4 trillion events daily through Beam-based pipelines, and Booking.com uses it to scan 2 PB+ of data daily with a reported 36x processing speedup. The tradeoff is that Beam adds an abstraction layer, which can reduce fine-grained control over state management. Choose this if you want runner-agnostic pipelines that avoid vendor or engine lock-in.
Apache Kafka is the industry-standard distributed event streaming platform, trusted by over 80% of Fortune 100 companies. Rated 8.6/10 across 151 reviews, Kafka handles trillions of messages per day at companies like Agoda (1.8 trillion events/day) and LinkedIn. While Flink is a processing engine, Kafka is fundamentally an event log and message broker with built-in stream processing via Kafka Streams. Kafka excels at high-throughput data ingestion, pub/sub messaging, and durable event storage with replay capability. Choose this if your primary need is reliable event transport and lightweight stream processing rather than complex stateful computations.
Confluent is the enterprise data streaming platform built by the original creators of Apache Kafka, rated 9.2/10 across 27 reviews. Confluent Cloud offers managed Kafka starting at $0/month (Basic tier) scaling to $895/month (Enterprise), with usage-based pricing at $0.14/GB for ingress. It bundles managed Apache Flink for stream processing, ksqlDB for SQL-based streaming, 120+ pre-built connectors, and a Schema Registry. The Standard tier provides 99.9% uptime SLA with autoscaling and infinite storage. Choose this if you want Kafka's power with managed operations and built-in Flink integration without running your own clusters.
Apache Airflow is the dominant open-source workflow orchestration platform with Python-based DAGs for scheduling and monitoring batch data pipelines. Airflow is the Apache Software Foundation project with a sizable contributor base and is available as managed services through Google Cloud Composer and Amazon MWAA. Unlike Flink's real-time stream processing, Airflow orchestrates discrete tasks on schedules -- it coordinates when jobs run rather than processing individual events. Choose this if your workloads are batch-oriented ETL/ELT jobs that need scheduling, dependency management, and a rich web UI for monitoring.
Prefect is a Python-native workflow orchestration platform designed as a modern alternative to Airflow, with an open-source self-hosted option under Apache-2.0 and managed cloud plans. Prefect handles data pipelines, ETL/ELT jobs, and ML workflows with a focus on developer experience and dynamic task graphs that do not require DAG pre-definition. It offers a managed control plane that eliminates the infrastructure management overhead common with Flink deployments. Choose this if you are a Python-heavy team that wants simpler orchestration without Airflow's scheduler complexity or Flink's JVM requirement.
Dagster is an asset-centric data orchestrator with built-in lineage tracking, observability, and dbt integration, available as open-source (Apache-2.0) with cloud plans starting at $10/month. Dagster treats pipelines as collections of data assets rather than just tasks, providing software-defined assets that make testing and debugging straightforward. With 12,000+ GitHub stars and native integrations for dbt, Spark, and major cloud warehouses, it offers a fundamentally different approach from Flink's event-driven model. Choose this if you need asset-level observability, strong testing capabilities, and a modern orchestration experience for analytics workflows.
Architecture and Approach Comparison
The core architectural divide among these alternatives falls into two categories: stream processors and workflow orchestrators. Apache Flink operates as a true per-event streaming engine using the Chandy-Lamport algorithm for distributed snapshots, achieving sub-millisecond latency with managed state backends like RocksDB that can handle terabytes of local state. Apache Beam sits one level above as an abstraction layer -- it compiles pipeline definitions down to whatever runner you choose, including Flink itself, Spark, or Dataflow.
Apache Kafka takes a fundamentally different architectural position as a distributed commit log. Kafka stores events durably in partitioned topics with configurable retention, while Kafka Streams provides a lightweight client library for stream processing that reads directly from Kafka topics without requiring a separate cluster. Confluent extends this by adding managed Flink on top of Kafka, creating a full streaming platform where Kafka handles transport and Flink handles computation.
Airflow, Prefect, and Dagster are workflow orchestrators, not stream processors. Airflow uses a scheduler-worker architecture with DAGs defining task dependencies, executing workloads on configurable executors (Celery, Kubernetes, Local). Prefect replaces Airflow's rigid DAG structure with dynamic task graphs and a hybrid execution model where the control plane is managed but execution happens in your infrastructure. Dagster introduces software-defined assets as the primary abstraction, where each asset declares its dependencies and materializations, enabling automatic lineage tracking across the entire data stack.
Pricing Comparison
Most Apache Flink alternatives in this category offer generous free tiers, but total cost of ownership varies significantly based on whether you self-host or use managed services.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Pricing Model | Starting Price | Key Cost Factor |
|---|---|---|---|
| Apache Flink | Open Source | $0 (self-hosted) | Cluster infrastructure + ops team |
| Apache Beam | Open Source | $0 (self-hosted) | Runner costs (Dataflow, Flink, Spark) |
| Apache Kafka | Open Source | $0 (self-hosted) | Broker infrastructure + storage |
| Confluent | Usage-Based | $0/mo (Basic) | $385/mo Standard, $895/mo Enterprise + usage |
| Apache Airflow | Open Source | $0 (self-hosted) | Cloud Composer ~$300-400/mo managed |
| Prefect | Freemium | $0 (self-hosted) | Cloud and enterprise plans with custom quotes |
| Dagster | Freemium | $10/mo (Solo) | $100/mo Starter, $1,200/mo Pro |
Flink itself is free, but running a production Flink cluster typically requires dedicated DevOps expertise and significant compute resources. Confluent offers the most transparent managed pricing, with ingress at $0.14/GB and egress starting at $0.05/GB on their Standard tier. For teams that only need batch orchestration, Dagster's $10/month Solo plan or Prefect's free self-hosted tier represent dramatically lower entry points than operating a Flink cluster.
When to Consider Switching
We recommend evaluating alternatives to Apache Flink in the following scenarios. If your workloads are primarily batch ETL with scheduled runs rather than continuous streams, Airflow, Prefect, or Dagster will be simpler to operate and cheaper to run. A Flink cluster sitting idle between batch windows wastes resources.
If your team lacks JVM expertise, Flink's Java/Scala-centric development model and complex tuning of memory, checkpoints, and parallelism become a bottleneck. Prefect and Dagster offer Python-native alternatives that most data teams can adopt in days rather than weeks.
If you need event transport more than event processing, Apache Kafka or Confluent may be the better foundation. Many teams adopt Flink for stream processing when Kafka Streams -- a lightweight library that runs as a regular application without a cluster -- would suffice for their filtering and aggregation needs.
If you want to avoid runner lock-in, Apache Beam lets you develop pipelines that can run on Flink today and migrate to Spark or Dataflow tomorrow. This matters when cloud strategy or cost optimization might shift your compute backend.
If operational complexity is your primary pain point, Confluent's managed Flink offering or a fully managed Beam runner like Google Cloud Dataflow eliminates cluster management while preserving stream processing capabilities.
Migration Considerations
Migrating away from Apache Flink requires careful planning around state management, API compatibility, and team retraining. The easiest migration path is to Apache Beam, since Beam already supports Flink as a runner. You can incrementally port Flink DataStream API code to Beam's PTransform model while continuing to run on a Flink backend, then switch runners when ready. Expect 2-4 weeks for a small pipeline migration and 2-3 months for complex stateful applications.
Moving from Flink to Kafka Streams means rearchitecting stateful computations. Flink's managed state with RocksDB and incremental checkpointing does not have a direct equivalent in Kafka Streams, which uses local state stores with changelog topics. Windowed aggregations and event-time processing are available in both, but Kafka Streams' single-partition ordering guarantees differ from Flink's global watermark propagation. Plan 3-6 months for complex migrations.
Switching to workflow orchestrators like Airflow, Prefect, or Dagster is only practical when replacing batch-oriented Flink jobs. These tools cannot replicate Flink's continuous stream processing. Data formats are generally not an issue since most pipelines read from standard sources (Kafka topics, S3, databases), but you will need to redesign real-time pipelines as scheduled batch jobs, accepting increased latency.
The learning curve varies significantly: Beam and Kafka Streams require distributed systems knowledge similar to Flink, while Prefect and Dagster can be productive within a week for Python developers. Confluent's managed Flink reduces operational complexity but uses the same Flink SQL and API, so existing Flink knowledge transfers directly.