Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Confluent states |
|---|---|
Deployment | Fully managed on any public cloud with Confluent Cloud, self-managed on-premises or in private cloud with Confluent Platform, or managed within your own cloud account through WarpStream. Confluent Private Cloud runs Kafka as a multi-tenant platform entirely on your private infrastructure. |
Connectors | 120+ pre-built connectors to databases, data warehouses, SaaS apps and cloud services. On Confluent Cloud, the Basic tier lists 80+ fully managed connectors. |
Stream processing | Apache Flink, offered as Confluent Cloud for Apache Flink and as Confluent Platform for Apache Flink, to filter, enrich and analyze streams. |
Security and compliance | Confluent Platform supports role-based access control, access control lists, OAuth/OIDC sign-in through identity providers, and TLS and mTLS for data in transit. Confluent lists SOC 2, ISO 27001 and PCI DSS certifications. |
Download terms | Confluent offers a free download. Downloading means accepting the Confluent License Agreement, and the download terms also reference the Confluent Community License Agreement. |
Our take
Choose Confluent when Apache Kafka is, or will become, shared infrastructure for several teams, and you want connectors, stream processing and schema governance from the same vendor, either fully managed or on your own infrastructure. On Confluent Cloud, pick the tier from latency, throughput, partition and networking needs rather than from the lowest starting cost.
Evaluate Confluent
Popular comparisons
See all 6 Confluent comparisons
Where it stands out
A path from the Kafka you already run. Confluent says it is fully compatible with Apache Kafka. Cluster Linking mirrors topics in real time, replicates data and metadata, and migrates existing workloads to Confluent without downtime; it also links Confluent Platform and Confluent Cloud clusters.
No cluster sizing in the cloud. Basic, Standard, Enterprise and Freight clusters autoscale. Elastic Confluent Units for Kafka (eCKUs) scale up for spikes and back down with the workload, with no user intervention.
Automation for self-managed Kafka. Confluent Platform adds Confluent for Kubernetes for day-2 work such as scaling, upgrades and disaster recovery, Ansible Playbooks, Self-Balancing Clusters that spread partitions across brokers, Tiered Storage that offloads latency-insensitive data to object storage, and Control Center, a graphical UI for Kafka operations.
Data contracts for streams. Schema Registry supports Avro, Protobuf and JSON Schema, enforces data contracts and checks compatibility as schemas evolve. It is part of Stream Governance, Confluent's fully managed governance suite.
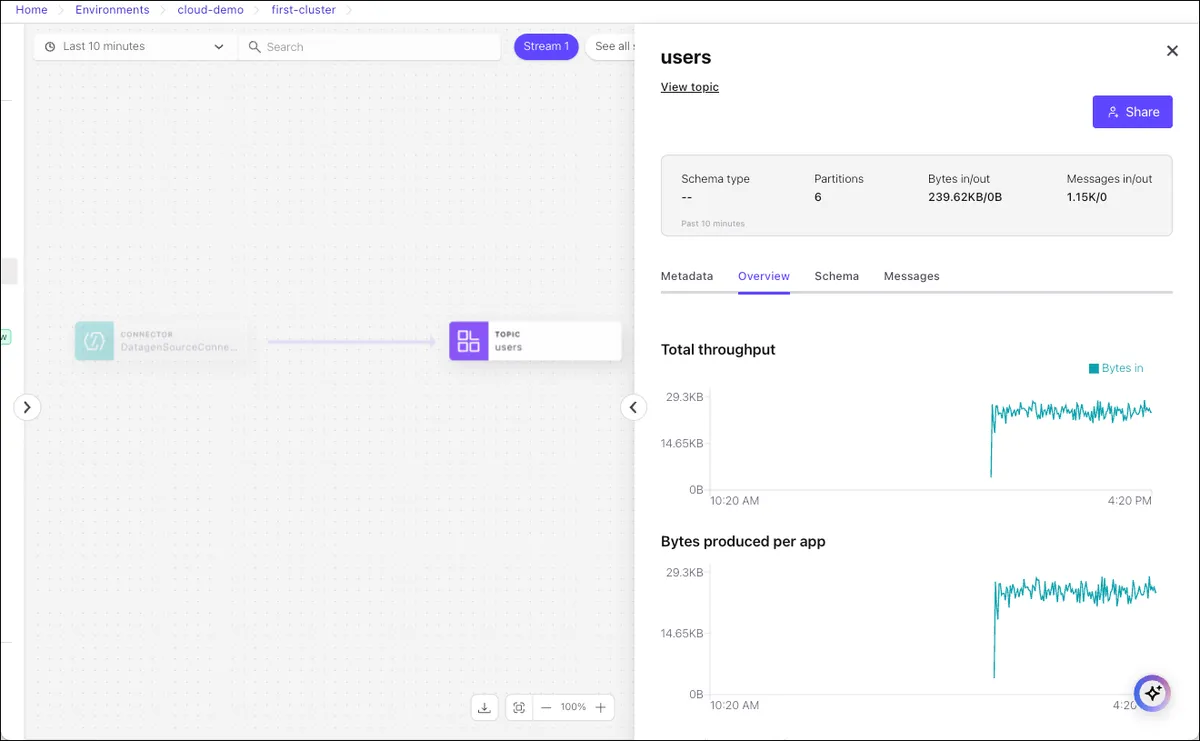
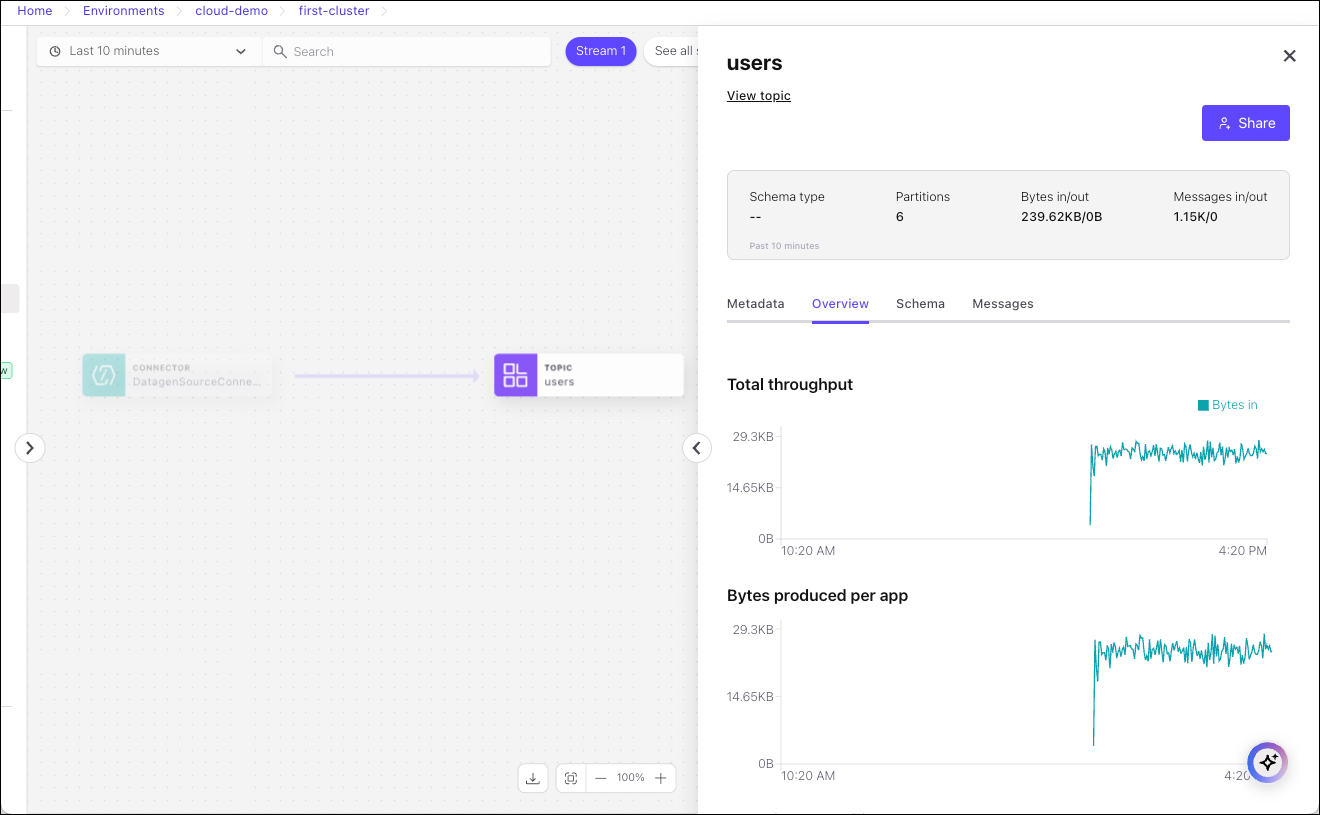
Product screenshot
Trade-offs to weigh
Marketplace billing ties you to one cloud. If you sign up through a cloud provider marketplace, data plane resources, including Kafka clusters, ksqlDB, Schema Registry, Stream Catalog and Flink, must run in that provider. You also cannot link a marketplace payment method to an organization that already runs resources in another cloud, so choose the marketplace before you sign up.
Usage bills need watching. Because eCKUs scale with demand, compute charges follow load. Each component accrues hourly and any part hour bills as a full hour, and your cloud provider may show Confluent usage only 6–24 hours after it occurs. Confluent offers a Cost Estimator and a Costs API to forecast and track spend.
Pricing and billing conditions
Confluent Cloud bills consumption. Kafka clusters are billed for eCKUs or CKUs per hour, networking per GB and storage. Connectors bill by throughput per GB plus a per-task hourly base price, Flink by CFUs per minute, Tableflow by topics per hour and data processed per GB, and Stream Governance per environment per hour. Prices are in US dollars, vary by cloud region and use binary gigabytes (2^30 bytes). Pay as you go directly or through the AWS, Google Cloud or Microsoft Azure marketplace, or sign an annual commitment: a minimum spend over a fixed term that brings volume discounts and can be applied across Kafka clusters, ksqlDB, connectors and Confluent Support; usage above it is charged at the discounted rate. Invoicing requires a minimum annual commitment. Dedicated clusters are sold by pre-provisioned capacity; contact Confluent for details. New Confluent Cloud sign-ups get $400 of free credit.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tier | Per eCKU-hour | Data in/out per GB | Stored per GB-month | Estimated monthly starting cost | Limits and plan features |
|---|---|---|---|---|---|
Basic | First eCKU free, then $0.14 | $0.05 | $0.08 | $0/month | Low latency; 99.5% uptime SLA; 250 / 750 MBps in/out; 1,500 partitions; 5 TB storage |
Standard | $0.75 | $0.035 - $0.050 | $0.08 | $385/month | Low latency; 99.9% SLA at 1 eCKU, 99.99% at 2+ eCKUs; 250 / 750 MBps; 2,500 partitions; infinite storage; everything in Basic, plus audit logs |
Enterprise | $1.75 - $2.25 | $0.020 - $0.050 | $0.08 | $895/month | Low latency; 99.9% SLA at 1 eCKU, 99.99% at 2+ eCKUs; 1,920 / 5,760 MBps; 96,000 partitions; infinite storage; everything in Basic and Standard, plus private networking |
Freight | $2.25, minimum 2 eCKUs | $0.014 – $0.030 | $0.03, an effective pre-replication price because Freight delivers direct to object storage | $2,300/month | Relaxed latency, for high-scale logging and observability; 99.99% SLA; 9,120 / 27,360 MBps; 50,000 partitions; infinite storage |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
39 GitHub commits 90d527 GitHub stars0 vulnerabilities across 2 packages
See all signals from 8 sources
PyPI · confluent-kafka@2.16.1 · npm · kafkajs@2.2.4
Alternatives to Confluent
The reviewed substitutes for Confluent among the event streaming platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Apache Kafka
- Two event streaming platforms carrying ordered, partitioned, replayable data for the same pipelines. They are compared directly on protocol, operations and commercial support, and a team runs one as its event backbone.Applies to: Choosing the event streaming platform that will carry the organisation's event data.
- Apache Pulsar
- Two event streaming platforms carrying ordered, partitioned, replayable data for the same pipelines. They are compared directly on protocol, operations and commercial support, and a team runs one as its event backbone.Applies to: Choosing the event streaming platform that will carry the organisation's event data.
- NATS
- For a team that wants a vendor-supported streaming backbone rather than one it operates alone, the choice is Confluent's managed Kafka against Synadia-backed NATS. Same decision, same buyer, different fabric underneath -- and the commercial relationship is the point in both cases.Applies to: A supported event backbone without running it unaided. Confluent stands in when Kafka compatibility and its managed ecosystem decide; NATS with Synadia stands in when a lighter fabric and lower operational cost matter more than Kafka's ecosystem.
- Redpanda
- Confluent and Redpanda both sell a Kafka-compatible streaming platform, as a managed cloud service or as software to self-host. Confluent comes from the original creators of Apache Kafka and adds a large set of pre-built connectors and Flink stream processing. Redpanda reimplements the Kafka API without ZooKeeper or the JVM, aiming at simpler operations and lower latency.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Azure Event Hubs
- Learn about Azure Event Hubs, a managed service that can ingest and process massive data streams from websites, apps, or devices.Applies to: managed Kafka and connector-heavy real-time integration workloads
- AWS Kinesis
- Collect streaming data, create a real-time data pipeline, and analyze real-time video and data streams, log analytics, event analytics, and IoT analytics.Applies to: managed Kafka-based streaming and connector-heavy data integration workloads
- Talend
- It handles fundamentally different use cases than Talend's traditional ETL approach, but increasingly replaces Talend in organizations moving toward event-driven architectures. **Confluent** is the enterprise data streaming platform built by the original creators of Apache Kafka.
Head to head
See detailed alternatives analysis
Organizations evaluating Confluent alternatives often find themselves balancing the power of a fully managed Kafka platform against growing cost complexity and operational overhead. Confluent, founded by the original creators of Apache Kafka, delivers a comprehensive data streaming platform with Confluent Cloud, Confluent Platform, 120+ pre-built connectors, and enterprise features like Schema Registry and stream processing via Apache Flink. However, as data architectures evolve, many teams are looking at alternatives that better fit specific use cases -- whether that means simpler operations, lower total cost of ownership, or a fundamentally different approach to data movement. This guide examines the leading Confluent alternatives across data streaming, event ingestion, and data integration categories.
Top Alternatives Overview
The alternatives landscape for Confluent spans several categories: open-source event streaming, managed cloud services, and ELT/ETL data integration platforms. Each offers distinct tradeoffs in terms of Kafka compatibility, operational complexity, and ecosystem breadth.
Apache Kafka is the open-source foundation upon which Confluent itself was built. With over 32,000 GitHub stars and an active contributor community, Apache Kafka remains the standard for distributed event streaming. It provides high throughput, low latency, and durable message storage -- but requires significant operational expertise to manage brokers, partitions, and cluster health. Teams with deep Kafka knowledge who want full control often run self-managed Kafka to avoid Confluent's commercial pricing entirely.
AWS Kinesis offers a fully managed, serverless streaming service tightly integrated with the AWS ecosystem. It eliminates Kafka operational overhead entirely, making it well-suited for teams already invested in AWS infrastructure. Kinesis handles provisioning, scaling, and patching automatically, though it uses a proprietary API rather than Kafka-compatible interfaces.
Azure Event Hubs provides a similar managed streaming experience within the Microsoft Azure ecosystem and notably offers a Kafka-compatible endpoint, allowing existing Kafka clients to connect with minimal code changes. This makes it an attractive option for organizations running hybrid Azure workloads.
AWS Glue takes a fundamentally different approach as a serverless data integration service focused on ETL/ELT workloads. Rather than event streaming, AWS Glue excels at discovering, preparing, and loading data for analytics using its built-in Data Catalog and visual pipeline designer.
Fivetran and Hevo Data are managed ELT platforms that automate data ingestion from hundreds of SaaS applications and databases into cloud warehouses. They target teams whose primary need is reliable data replication rather than general-purpose event streaming.
Matillion provides a cloud-native ETL/ELT platform with a visual job designer optimized for transformations within Snowflake, BigQuery, Redshift, and Azure Synapse. Prefect focuses on Python-native workflow orchestration for data pipelines and ML workflows, offering an open-source core with a managed cloud control plane.
Architecture and Approach Comparison
The most fundamental architectural distinction among Confluent alternatives is between event streaming platforms and data integration tools. Confluent and Apache Kafka operate as distributed event logs -- durable, replayable, and partition-based -- designed for real-time event-driven architectures, microservices communication, and streaming analytics. This architecture enables use cases like fraud detection, real-time personalization, and IoT data processing.
Apache Kafka uses a publish-subscribe model where producers write events to topics partitioned across a cluster of brokers. Consumers subscribe to these topics and process events in order. Confluent extends this with managed infrastructure, Schema Registry for data governance, ksqlDB for stream processing, and Cluster Linking for cross-environment replication. The tradeoff is that Confluent's fully managed approach abstracts operational complexity but introduces vendor-specific pricing layers.
AWS Kinesis uses a shard-based architecture rather than Kafka's partition model. Each shard provides fixed throughput capacity, and Kinesis Data Streams handles replication and durability automatically. While less flexible than Kafka for complex routing patterns, Kinesis integrates natively with Lambda, S3, Redshift, and other AWS services, making it efficient for AWS-centric streaming pipelines.
Azure Event Hubs employs a partitioned consumer model with built-in Kafka protocol support. Its architecture is optimized for high-throughput telemetry ingestion, supporting millions of events per second. The Kafka-compatible surface means teams can migrate workloads from Confluent or self-managed Kafka without rewriting client applications.
On the data integration side, AWS Glue, Fivetran, Hevo Data, and Matillion take a connector-driven approach. Rather than providing a general-purpose event bus, these platforms offer pre-built integrations to source systems (databases, SaaS apps, APIs) and deliver data into warehouses or lakes. This model prioritizes ease of use and operational simplicity over the low-latency, event-by-event processing that Kafka enables. Prefect sits in between, orchestrating the execution of arbitrary Python workflows including streaming and batch jobs.
Pricing Comparison
Pricing models vary significantly across these alternatives. Confluent Cloud uses usage-based pricing with a free Basic tier, Standard at $385/mo, Enterprise at $895/mo, and Freight at $2,300/mo, plus per-GB rates for ingress, egress, and storage. This multi-dimensional pricing can make cost forecasting challenging at scale.
Apache Kafka is open-source software available at no cost, though teams must budget for infrastructure, operations personnel, and monitoring tooling. The total cost of self-managed Kafka depends heavily on cluster size and team expertise.
AWS Kinesis uses usage-based pricing starting at $0.08 per GB of data ingested, with costs scaling based on shard hours and data volume. AWS Glue charges $0.44 per DPU-hour for ETL jobs, with a free tier covering the first million Data Catalog objects and accesses.
Fivetran offers a free plan for up to 500,000 monthly active rows, and its Standard, Enterprise, and Business Critical plans are priced on monthly active rows, with no per-plan price published. Hevo Data provides a free plan covering up to 1 million events per month, with its Starter plan at $299/mo ($265/mo billed annually). Matillion bills in consumption-based Matillion Credits across its Developer, Teams, and Scale editions and publishes no dollar rates.
Prefect's open-source core is available under the Apache-2.0 license at no cost, with cloud and enterprise managed plans available. Informatica PowerCenter and Azure Event Hubs both require contacting sales for pricing details. Rivery's Base edition costs $0.90 per BDU credit with monthly billing. Professional has no published numeric price; its trial ends after 14 days or 1,000 credits, whichever comes first. Pro Plus credit price not published; annual and Enterprise plans are arranged with Rivery.
When to Consider Switching
Several scenarios signal that evaluating Confluent alternatives is worthwhile. If your primary use case is data warehouse loading rather than real-time event streaming, ELT platforms like Fivetran or Hevo Data deliver that outcome with far less operational complexity. These tools handle connector maintenance, schema evolution, and incremental updates automatically, eliminating the need to manage Kafka clusters for what is essentially batch or micro-batch data movement.
Teams deeply embedded in a single cloud provider often benefit from native managed services. AWS-centric organizations may find that Kinesis paired with AWS Glue covers their streaming and integration needs without introducing a separate platform. Similarly, Azure-focused teams can leverage Event Hubs with its Kafka-compatible endpoint for streaming workloads alongside native Azure analytics services.
Cost predictability is another common driver. Confluent's multi-dimensional pricing model -- with separate charges for compute, storage, connectors, Schema Registry, and processing -- can produce unexpected bills at scale. Alternatives with simpler pricing models, such as Kinesis's per-GB ingestion pricing or Fivetran's per-connector approach, provide more predictable cost profiles.
If your team lacks dedicated Kafka expertise, the operational burden of even a managed Kafka service can be significant. Platforms like Matillion, Prefect, or Hevo Data abstract away distributed systems complexity entirely, letting data engineers focus on transformation logic rather than cluster management.
Conversely, if your architecture depends on Kafka's event-driven semantics -- replayable logs, exactly-once processing, complex event routing across microservices -- then Confluent or self-managed Apache Kafka remain the strongest choices. The alternatives in the ELT and managed streaming categories trade those capabilities for simplicity.
Migration Considerations
Migrating away from Confluent requires careful planning around data continuity, client compatibility, and downstream dependencies. For teams moving to self-managed Apache Kafka, the transition is relatively straightforward since Confluent is built on Kafka. Existing topics, consumer groups, and client configurations largely carry over, though teams must assume responsibility for cluster provisioning, monitoring, patching, and capacity planning.
Moving to Azure Event Hubs benefits from its Kafka-compatible protocol layer. Existing Kafka producers and consumers can often connect to Event Hubs by changing broker endpoints and authentication settings, without application-level code changes. This makes it one of the smoother migration paths for teams already operating in the Azure ecosystem.
Migrating to AWS Kinesis or non-Kafka platforms requires more substantial application changes. Kinesis uses a different API and data model (shards vs. partitions, sequence numbers vs. offsets), so producer and consumer code must be rewritten. The same applies to transitions toward ELT platforms like Fivetran or Hevo Data, which replace event streaming with connector-based ingestion -- a fundamentally different data movement paradigm.
Regardless of destination, teams should inventory all Confluent-specific features in use: Schema Registry schemas, ksqlDB queries, managed connectors, and Cluster Linking configurations. Each of these may require equivalent replacements or architectural redesign. Running parallel environments during migration -- producing to both the old and new systems simultaneously -- helps validate data integrity before cutting over.