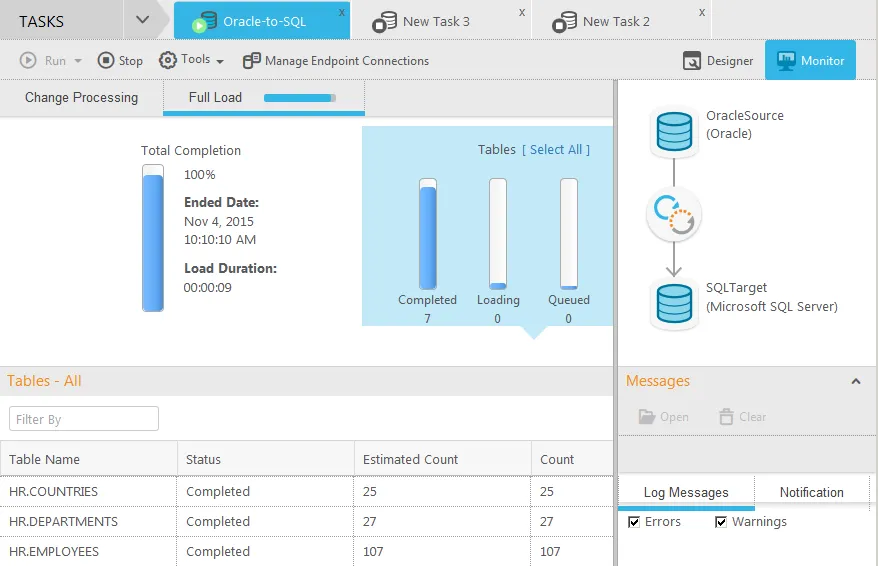
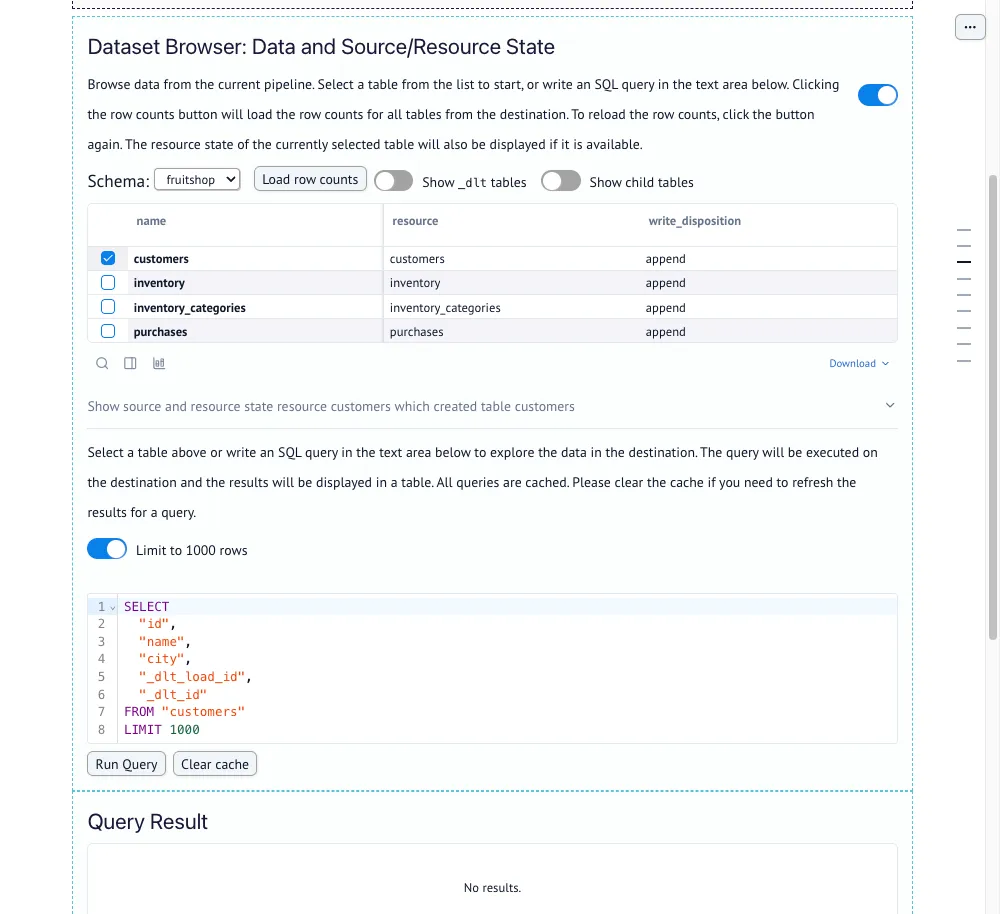
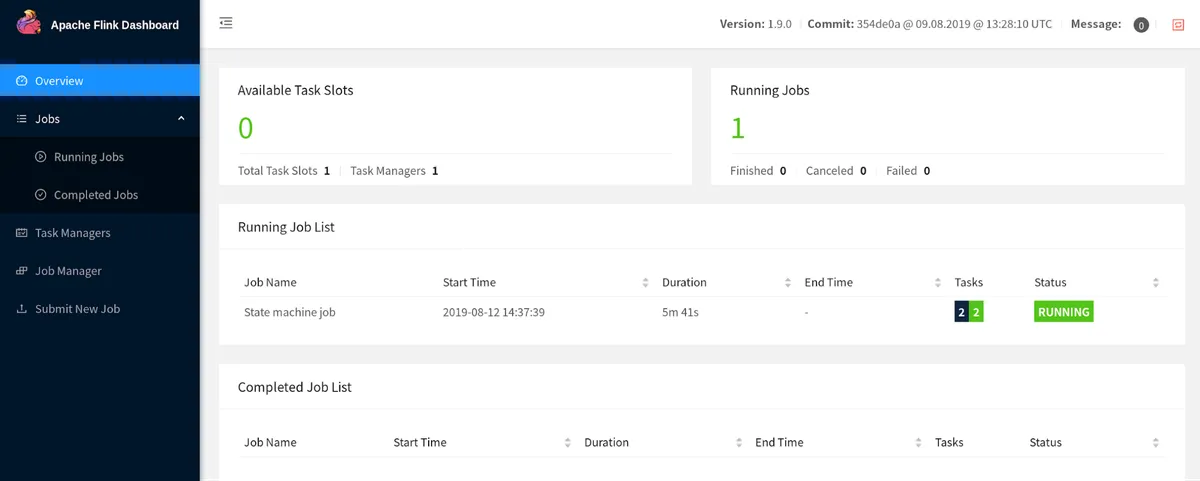
The best data pipeline & orchestration choice depends first on the work your platform must coordinate: moving data, transforming it, processing events, or operating durable distributed workflows. This category spans ELT and ETL platforms, workflow orchestrators, transformation frameworks, event streaming platforms, data processing engines, message brokers, object storage, customer data platforms, and durable execution tools. These products overlap at the edges, but they solve materially different architectural problems. We recommend selecting the primary execution model before comparing connectors, interfaces, or commercial terms.
How to Choose
Start with product type. A workflow orchestrator coordinates dependencies, schedules, and monitoring across tasks; Apache Airflow is the fit when teams want Python-based DAGs for complex workflows. An ETL platform moves and shapes data across cloud or hybrid estates; Azure Data Factory is designed for creating, scheduling, and managing ETL/ELT pipelines and includes more than 100 built-in connectors. An ELT platform focuses on loading data into a destination for downstream transformation; dlt is a Python library for declarative loading with schema inference, schema evolution, and incremental loading.
A transformation framework manages transformations inside the analytical environment. Dataform uses SQLX, extends SQL with JavaScript, and supports dependency management, data quality assertions, documentation, and Git-based version control. Choose an event streaming platform when records must flow continuously and durably rather than run as scheduled batches: Apache Kafka provides distributed, fault-tolerant event storage and stream processing. Choose a message broker when distributed services need lightweight real-time communication; NATS combines pub/sub, request/reply, queueing, key-value, and object storage in one system. For unified batch and streaming computations across execution environments, Apache Beam provides a portable programming model. Azure Data Lake Storage is the storage foundation when an Azure data lake needs hierarchical directories, ACLs, lifecycle policies, and analytics integration.
Then evaluate operating model and development fit. Airflow’s Python-based approach is compelling when data engineers want pipeline behavior represented as code and need extensibility; teams that prefer another orchestration model can assess Prefect as an alternative. Dataform is appropriate when SQL-first development and native BigQuery integration matter, but its published workflow focus is BigQuery, Snowflake, and Redshift rather than general-purpose orchestration.
Assess execution and latency requirements with concrete architecture requirements. Kafka supports stream processing with joins, aggregations, filters, event-time handling, and exactly-once processing, while its published capabilities include latencies as low as 2ms. NATS is the better fit for resource-constrained cloud, edge, or fleet deployments where sub-millisecond latency and minimal resource use are explicit requirements. Beam is useful when one pipeline definition must execute on Apache Flink, Apache Spark, Google Cloud Dataflow, or Hazelcast Jet.
Examine data management controls. dlt provides automatic schema inference, incremental loading, and built-in data contracts, which matters when source structures evolve. Dataform provides data quality assertions and automatic documentation, useful when transformation logic needs reviewable quality checks. Azure Data Lake Storage offers atomic directory operations through its hierarchical namespace and POSIX-compliant ACLs, which should matter where directory-oriented lake management and access boundaries are required.
Finally, model pricing against the actual service model. Airflow, Kafka, Beam, and NATS are open source. Dataform is free to use within Google Cloud, while BigQuery compute and storage consumption still incur charges. Azure Data Factory is usage-based, including $1 per 1,000 orchestration runs on Azure or Managed VNET integration runtime and $0.25 per DIU-hour for Azure integration runtime data movement. dlt’s managed dltHub service starts at $12,000.00 per month, while self-hosted dlt remains free under Apache-2.0.
Top Tools
Apache Airflow
Apache Airflow is an open-source workflow orchestrator for programmatically authoring, scheduling, and monitoring complex data pipelines through Python-based DAGs. Its Python-based, extensible, and scalable design makes it a strong fit when pipeline logic, dependencies, and operations need to live in an engineering workflow.
Best suited for: Data engineering teams that need code-defined scheduling and monitoring for complex, dependency-heavy workflows.
Pricing: Open Source
The central trade-off is that its defining interface is Python-based DAG authoring, so it is less appropriate when teams want a SQL-first transformation framework rather than a workflow orchestrator. Prefect is a reviewed alternative for teams evaluating a different orchestration option.
Azure Data Factory
Azure Data Factory is a cloud ETL platform for creating, scheduling, and managing ETL/ELT pipelines across Azure and hybrid environments. It provides more than 100 built-in connectors and separates orchestration, data movement, and pipeline activity charges.
Best suited for: Azure-oriented and hybrid data estates that need cloud-scale integration with built-in connectivity.
Pricing: Usage-Based
The trade-off is variable consumption pricing: orchestration is $1 per 1,000 runs on Azure or Managed VNET integration runtime, self-hosted orchestration is $1.50 per 1,000 runs, and Azure integration runtime data movement is $0.25 per DIU-hour. AWS Glue is a reviewed alternative for buyers comparing ETL platforms outside an Azure-centered architecture.
Dataform
Dataform is a free transformation framework for managing SQL-based data pipelines in BigQuery, Snowflake, and Redshift. It distinguishes itself with SQLX, JavaScript extensions to SQL, built-in dependency management, data quality assertions, automatic documentation, Git-based version control, and native BigQuery integration.
Best suited for: Analytics engineers managing tested, version-controlled SQL transformations, especially in BigQuery.
Pricing: Free
The limitation is scope: Dataform addresses transformation workflows rather than replacing an ETL platform, event broker, or general workflow orchestrator. dbt (data build tool) is a reviewed alternative for teams comparing SQL transformation frameworks.
dlt (data load tool)
dlt is an ELT platform delivered as an open-source Python library for declarative data loading. It supports custom data sources, schema inference and evolution, incremental loading, data contracts, and a fully customizable interface that can run anywhere.
Best suited for: Python teams building custom ingestion pipelines that need managed schema evolution and incremental loading.
Pricing: Freemium from $12000.00/mo
The key trade-off is commercial: self-hosted dlt is free, but the managed dltHub service starts at $12,000.00 per month with a 12-month minimum billed monthly. Airbyte is a reviewed alternative for teams comparing data-loading approaches.
Apache Kafka
Apache Kafka is an open-source event streaming platform for high-throughput, fault-tolerant pipelines, streaming analytics, data integration, and mission-critical applications. It provides durable distributed storage, ordering, high availability, stream processing with joins and aggregations, and exactly-once processing using event-time.
Best suited for: Architectures that need durable, high-throughput event streams and stream-processing capabilities.
Pricing: Open Source
The trade-off is that Kafka is an event streaming platform, not a substitute for scheduled workflow orchestration or warehouse SQL transformation management. NATS is a reviewed alternative when lightweight distributed messaging and edge operation are the primary requirements.
Apache Beam
Apache Beam is an open-source data processing engine with a unified programming model for batch and streaming pipelines. Its Java, Python, and Go SDKs can execute across Apache Flink, Apache Spark, Google Cloud Dataflow, and Hazelcast Jet, enabling portable pipeline definitions.
Best suited for: Data teams that need one programming model across batch and streaming execution environments.
Pricing: Open Source
Its trade-off is that Beam defines and runs processing pipelines; it does not provide the connector-oriented ETL service model described for Azure Data Factory. Apache Flink is a reviewed alternative for buyers focused on processing engines.
NATS
NATS is an open-source message broker and real-time communication fabric for distributed applications across cloud, on-premise, edge, and IoT environments. It provides pub/sub, request/reply, queueing, key-value, and object storage with minimal resource use and sub-millisecond latency.
Best suited for: Distributed and edge systems that require lightweight, asynchronous messaging across constrained environments.
Pricing: Open Source
The trade-off is architectural intent: NATS emphasizes real-time communication and distributed application connectivity, rather than Kafka’s durable event-streaming and built-in stream-processing model. RabbitMQ is a reviewed alternative for message-broker evaluations.
Azure Data Lake Storage
Azure Data Lake Storage is usage-based object storage for high-performance Azure analytics workloads. It includes a hierarchical namespace, atomic directory operations, POSIX-compliant ACLs, lifecycle policies, Microsoft Entra ID RBAC, encryption at rest, and integration with Azure Databricks, Synapse Analytics, HDInsight, and Power BI.
Best suited for: Azure data lake architectures that need directory semantics, access controls, and tiered storage.
Pricing: Usage-Based
The main trade-off is that it is storage infrastructure, not a scheduler, transformation framework, or event-processing engine. Its East US hierarchical-namespace price for the first 50 TB is $0.021 per GB-month for Hot LRS, with other tiers and replication options priced separately.
Comparison Table
The table compares the primary job each tool performs rather than treating all eight as interchangeable pipeline products. A practical stack may use several of these tools together: for example, object storage, streaming, processing, transformation, and orchestration address different layers.
| Tool | Type | Best For | Pricing | Key Strength |
|---|---|---|---|---|
| Apache Airflow | workflow orchestrator | Python-defined, dependency-heavy workflows | Open Source | Python-based DAGs for authoring, scheduling, and monitoring |
| Azure Data Factory | etl platform | Azure and hybrid ETL/ELT integration | Usage-Based | 100+ built-in connectors |
| Dataform | transformation framework | Tested SQL transformations in analytical platforms | Free | SQLX, assertions, documentation, and Git-based version control |
| dlt (data load tool) | elt platform | Custom Python ingestion pipelines | Freemium from $12000.00/mo | Schema inference, evolution, and incremental loading |
| Apache Kafka | event streaming platform | Durable, high-throughput event streams | Open Source | Exactly-once stream processing and durable distributed storage |
| Apache Beam | data processing engine | Portable batch and streaming processing | Open Source | Runs across Flink, Spark, Dataflow, and Hazelcast Jet |
| NATS | message broker | Lightweight real-time distributed messaging | Open Source | Sub-millisecond latency and cloud-to-edge operation |
| Azure Data Lake Storage | object storage | Azure data lakes with hierarchical controls | Usage-Based | Hierarchical namespace and POSIX-compliant ACLs |
Our Methodology
We evaluate data pipeline & orchestration tools using vendor documentation, published pricing information, documented product capabilities, public user-review signals, and editorial assessment of architectural fit. We prioritize concrete evidence: Airflow’s Python DAGs, Dataform’s SQLX and assertions, dlt’s schema evolution, Kafka’s exactly-once processing, Beam’s supported execution environments, NATS’s messaging patterns, and Azure Data Lake Storage’s hierarchical namespace are examples of verifiable product evidence.
Pricing is presented only where published terms are available and should be read as a service model, not as a total deployment cost. Usage-based services can vary with orchestration runs, integration runtime use, movement, storage tier, replication, and consumed compute. Public signals such as review counts or published claims can indicate visibility and user interest, but they do not prove enterprise adoption, implementation quality, reliability in a particular workload, or suitability for a regulated environment. Editorial recommendations therefore connect tools to defined requirements and trade-offs rather than asserting a universal winner.
Frequently Asked Questions
Should I choose an ETL platform or a workflow orchestrator?
Choose an ETL platform when the primary need is moving and integrating data. Azure Data Factory is built to create, schedule, and manage ETL/ELT pipelines across Azure and hybrid environments, with more than 100 built-in connectors. Choose a workflow orchestrator when coordinating complex dependencies and tasks is the central problem. Apache Airflow uses Python-based DAGs to author, schedule, and monitor those workflows.
When should we use Kafka instead of NATS?
Use Apache Kafka when you need durable distributed event streams, built-in stream processing, message ordering, and exactly-once processing. Kafka supports joins, aggregations, filters, and event-time processing, with published latencies as low as 2ms. Use NATS when the requirement is lightweight, real-time application communication across cloud, edge, or low-resource environments. NATS supports pub/sub, request/reply, queueing, key-value, and object storage in a unified system.
Is Dataform an orchestration replacement?
No. Dataform is a transformation framework for managing SQL-based pipelines in BigQuery, Snowflake, and Redshift. It offers dependency management, data quality assertions, automatic documentation, and Git-based version control. Those capabilities make it suitable for governed transformation development, but they do not make it an ETL integration service or a general distributed messaging platform. Pair it with other components when those responsibilities are required.
What does Azure Data Lake Storage add to a pipeline architecture?
Azure Data Lake Storage provides the storage layer rather than the pipeline scheduler or processing engine. Its hierarchical namespace supports atomic directory operations and POSIX-compliant ACLs, while lifecycle policies support tiered storage management. It integrates with Azure Databricks, Synapse Analytics, HDInsight, and Power BI. Pricing is usage-based; in East US, Hot LRS storage with hierarchical namespace costs $0.021 per GB per month for the first 50 TB.