Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Apache Beam states |
|---|---|
License and cost basis | Open source, with open, community-based development and support. |
Languages | The repository contains SDKs for Java, Python and Go; Beam also promotes multi-language pipelines. |
Where pipelines run | Locally with DirectRunner or PrismRunner; on Google Cloud Dataflow with DataflowRunner; on Apache Flink, Apache Spark, Hazelcast Jet or Twister2 clusters with their runners. |
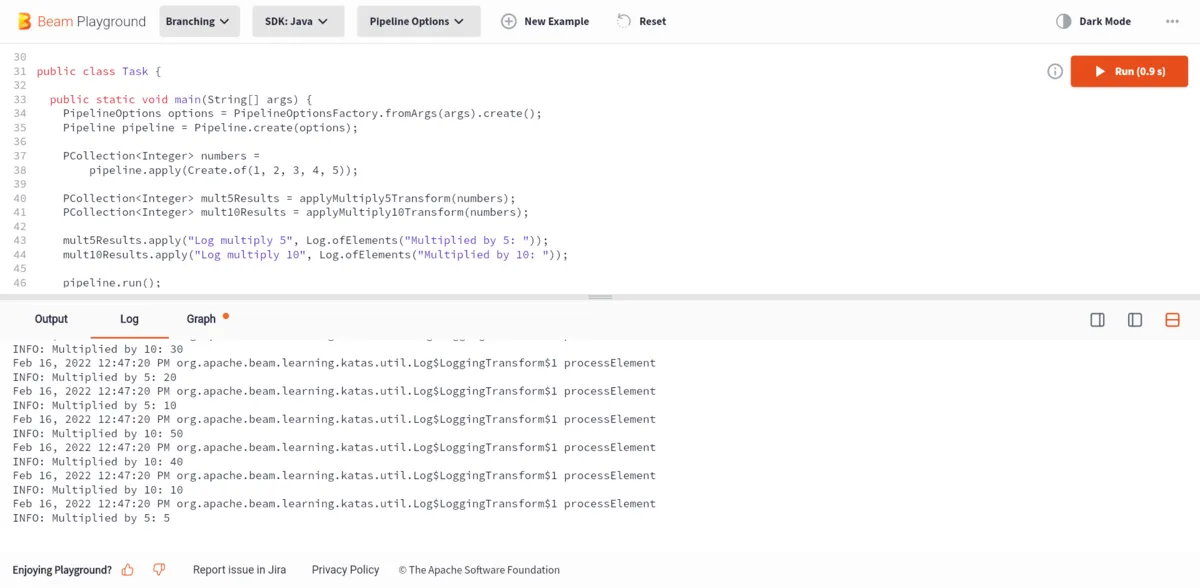
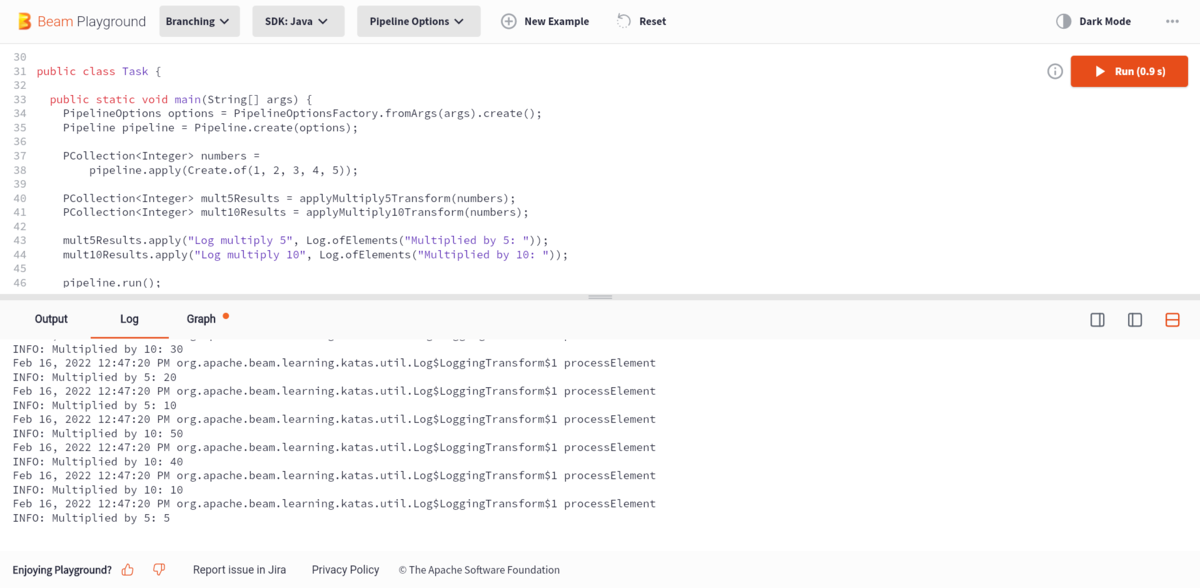
Installation | To use the Flink Runner from Java, declare its dependency in pom.xml or build.gradle; Python pipelines import apache_beam. Beam Playground lets you try transforms and examples without installing Beam. |
Support channels | Community channels: the user@beam.apache.org and dev@beam.apache.org mailing lists, the #beam channel on ASF Slack, and the issue tracker. |
Recent release | Apache Beam 2.77.0, announced on the Beam blog on 2026/10/07. |
Our take
Pick Beam when you want one codebase for batch and streaming logic and want to keep the option of moving it between engines such as Flink, Spark and Dataflow. If you are sure you will only ever run on one engine, compare Beam against writing for that engine directly before you add the runner layer.
Evaluate Apache Beam
Comparisons
Where it stands out
One model for batch and streaming. A PCollection can be bounded or unbounded, so the same PTransforms describe historical and real-time processing. Teams avoid keeping two codebases in step.
Runner portability. Beam describes running pipelines on multiple execution environments as a way to avoid lock-in. A pipeline is tied to the Beam model, and the PipelineRunner sets where and how it executes.
Streaming in Python. According to a case study on the Beam site, Yelp teams build custom streaming pipelines in Python without switching to Scala or Java.
Production use at large scale. Case studies on the Beam site say Beam processes 4 trillion events daily through 3K+ pipelines at LinkedIn and scans 2PB+ of data daily for Booking.com ad bidding. These are vendor-published customer stories, not independent benchmarks.
A base for other tools. TensorFlow Extended and Apache Hop are built on Beam; Hop adds visual pipeline development on top of it.
Product screenshot
Trade-offs to weigh
Runner details still matter. The Flink runner comes in a classic flavor that supports only JVM languages and a portable flavor for Java, Python and Go. Python pipelines on Flink need the portable runner and Docker in the execution environment.
Capabilities differ by runner. Beam keeps a separate capability matrix for the classic and the portable Flink runner, so check the matrix for the runner you plan to use before you rely on a feature.
Version lockstep with Flink. The Flink cluster must match the minor version the FlinkRunner uses. Beam tracks Flink community support, and when support for a Flink version is dropped, it may be deprecated and removed from Beam. Plan cluster upgrades alongside Beam upgrades.
Streaming safety needs configuration on Flink. Checkpointing is off by default. Sources such as PubSubIO rely on checkpoints being acknowledged, so set checkpointing_interval for unbounded pipelines. The LOOPBACK environment type is only for local testing and does not work on remote clusters.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
953 GitHub commits 90d8.7k GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
PyPI · apache-beam@2.77.0
Alternatives
Apache Flink. Flink is also one of Beam's runners. Beam's Flink runner docs describe Flink as a streaming-first runtime with exactly-once fault tolerance and natural back-pressure. Writing for Flink directly removes the Beam layer but also the option to switch runners.
Apache Spark. Beam runs on Spark clusters through the SparkRunner. Teams that run only Spark can weigh that against coding for Spark directly.
Google Cloud Dataflow. DataflowRunner submits Beam pipelines to Google Cloud Dataflow. The Beam model evolved from Google projects and was first known as the Dataflow Model.
Alternatives to Apache Beam
The reviewed substitutes for Apache Beam among the data processing engines, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Apache Flink
- Choose Flink if your workloads are streaming-first and you want a battle-tested engine without Beam's abstraction layer overhead.Applies to: Choosing the engine that will run distributed batch and streaming computation.
- Apache Spark
- Choose Spark if your team already invests in the Spark ecosystem, you need rich ML and SQL integration, or your streaming latency tolerance is above 500 ms.Applies to: Choosing the engine that will run distributed batch and streaming computation.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Dagster
- Dagster schedules and observes assets; Apache Beam is the processing model those jobs are written in, and Dagster commonly runs Beam jobs. Choosing Beam does not remove the need for an orchestrator.Applies to: Dagster orchestrates the Beam jobs; a Beam pipeline still needs scheduling, retries and lineage.
See detailed alternatives analysis
If you are evaluating Apache Beam alternatives, you are likely looking for a data processing or pipeline orchestration tool that better fits your team's skill set, latency requirements, or operational complexity budget. Apache Beam provides one API for batch and streaming pipelines across supported runners. That portability adds an abstraction layer, so teams should assess its learning curve and the runner-specific features they need. Below we break down the top alternatives, compare architectures and pricing, and outline when a switch makes practical sense.
Top Alternatives Overview
Apache Flink is an alternative for teams whose primary workload is real-time stream processing. Flink processes events with true per-event semantics and sub-second latency, backed by built-in exactly-once state management and savepoints for zero-downtime upgrades. It has 25,900+ GitHub stars, a 9/10 user rating, and native support for event-time windowing, watermarks, and complex event processing via FlinkCEP. Choose Flink if your workloads are streaming-first and you want a battle-tested engine without Beam's abstraction layer overhead.
Apache Spark is a widely used option for large-scale batch analytics. With 43,100+ GitHub stars, Spark offers Spark SQL, MLlib, GraphX, and Structured Streaming in a single distribution. Spark's micro-batch streaming model introduces latency in the hundreds-of-milliseconds range, which is acceptable for most analytics use cases. Choose Spark if your team already invests in the Spark ecosystem, you need rich ML and SQL integration, or your streaming latency tolerance is above 500 ms.
Apache Airflow is a workflow orchestrator with 46,000+ GitHub stars and an 8.7/10 user rating across 58 reviews. Airflow excels at scheduling, dependency management, and monitoring batch ETL/ELT jobs through its Python-based DAG definitions and rich web UI. It does not process data itself but orchestrates the tools that do. Choose Airflow if your challenge is coordinating multi-step pipelines across services rather than building a data processing engine.
Apache Kafka is a distributed event-streaming platform. Kafka handles high-throughput ingestion at millions of events per second with durable, partitioned log storage. Kafka Streams and ksqlDB add lightweight stream processing on top. Choose Kafka if your primary need is a reliable event backbone with built-in stream processing for moderate-complexity transformations.
Prefect is a Python-native workflow orchestration platform that modernizes the Airflow paradigm with a decorator-based API, automatic retries, and a managed cloud control plane. It is open source under Apache-2.0 with optional paid cloud tiers. Choose Prefect if you want Airflow-like orchestration with less boilerplate and a faster developer experience for Python-heavy teams.
Dagster takes an asset-centric approach to data orchestration, treating pipelines as collections of data assets with built-in lineage and observability. Its open-source tier is free (Apache-2.0), with cloud plans starting at $10/month. Choose Dagster if you want strong data lineage, testability, and native dbt integration for modern analytics engineering workflows.
Architecture and Approach Comparison
Apache Beam is fundamentally an abstraction layer: you write pipeline code once using the Java, Python and Go and execute it on any supported runner, including Flink, Spark, and Google Cloud Dataflow. This portability comes at the cost of an additional abstraction that can limit access to runner-specific optimizations. Beam's PCollection and PTransform model unifies batch and streaming under a single API, but debugging often requires understanding both the Beam layer and the underlying runner.
Apache Flink is a native execution engine, not an abstraction. It manages its own distributed state with RocksDB-backed checkpointing, supports event-time processing natively, and provides exactly-once guarantees without relying on an external runner. Flink's DataStream and Table APIs give direct access to low-level stream operations, which means less overhead but also tighter coupling to the Flink runtime.
Apache Spark treats everything as a distributed dataset (RDD) or DataFrame. Structured Streaming processes data in micro-batches, which simplifies fault tolerance but introduces inherent latency. Spark's strength lies in its unified analytics stack: SQL queries, ML training, graph processing, and streaming all share the same cluster resources and APIs.
Airflow, Prefect, and Dagster sit in a different architectural category entirely. They are orchestrators that schedule and monitor tasks but delegate actual data processing to external systems. Airflow uses DAGs with operator-based tasks, Prefect uses Python decorators and a task/flow model, and Dagster centers on software-defined assets. None of these tools process data at the engine level the way Beam, Flink, or Spark do.
Kafka operates as a distributed commit log and message broker. It provides durable event storage with configurable retention, partition-level parallelism, and consumer group coordination. Kafka Streams is a lightweight client library that processes data directly from Kafka topics without requiring a separate cluster, unlike Beam, Flink, or Spark which all need their own execution infrastructure.
Pricing Comparison
The main software projects in this comparison are open source and can be self-hosted. Costs therefore depend less on a license fee and more on the execution environment, storage, networking, managed-service terms, and the operational work required to run each system.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | License | Self-hosted option | Managed-service consideration |
|---|---|---|---|
| Apache Beam | Apache-2.0 | Yes | A runner such as Google Cloud Dataflow has provider-specific usage charges. |
| Apache Flink | Apache-2.0 | Yes | Managed Flink offerings price compute and service capacity differently by provider. |
| Apache Spark | Apache-2.0 | Yes | Databricks and cloud platforms publish their own compute and service rates. |
| Apache Airflow | Apache-2.0 | Yes | Managed orchestration services charge for scheduler and worker resources. |
| Apache Kafka | Apache-2.0 | Yes | Hosted Kafka costs depend on throughput, retention, and partitioning. |
| Prefect | Apache-2.0 | Yes | Cloud plans and included features should be confirmed with Prefect. |
| Dagster | Apache-2.0 | Yes | Cloud plans and included features should be confirmed with Dagster. |
For a fair total-cost comparison, model a representative workload with each provider's current calculator or sales team. Include worker capacity, persistent state, storage, egress, support, and engineering time. A self-hosted option can reduce direct service charges, but it transfers operations, upgrades, monitoring, and incident response to your team.
When to Consider Switching
Switch from Apache Beam to Apache Flink when your workloads are predominantly streaming, you need sub-second latency, and you find yourself fighting Beam's abstraction to access Flink-specific features like savepoints, queryable state, or FlinkCEP. Flink's native API eliminates the translation layer and gives you direct control over checkpointing and state backends.
Switch to Apache Spark when your team is already embedded in the Spark ecosystem, your workloads are batch-heavy with some streaming, and you need integrated ML pipelines via MLlib or SparkSQL for ad-hoc analytics. Spark has a large community and a broad set of libraries; evaluate the available connectors and the skills your team can support.
Switch to Apache Airflow or Prefect when you realize your problem is orchestration, not processing. If you are using Beam primarily to chain together extract-load steps rather than doing heavy transformations, a dedicated orchestrator with built-in scheduling, retries, and monitoring is a better fit. Airflow has a sizable community; Prefect offers a modern developer experience.
Switch to Dagster when data lineage, asset management, and testability are top priorities. Dagster's software-defined assets model gives you automatic dependency tracking and the ability to materialize individual assets on demand, which Beam does not natively support.
Switch to Kafka plus Kafka Streams when your transformation logic is simple (filtering, enrichment, aggregation) and your data already lives in Kafka topics. Running Kafka Streams as a lightweight library inside your application avoids the operational complexity of deploying and managing a separate Beam/Flink/Spark cluster.
Migration Considerations
Migrating away from Apache Beam requires evaluating three areas: SDK compatibility, runner dependencies, and pipeline complexity. If your Beam pipelines run on the Flink runner, migrating to native Flink is the lowest-friction path. Your PTransforms map to Flink DataStream operations, and most Beam IO connectors have Flink equivalents. Expect 2-4 weeks per major pipeline for a team familiar with both frameworks.
Moving to Spark requires rewriting pipeline logic from Beam's PCollection model to Spark DataFrames or RDDs. The conceptual mapping is straightforward for batch workloads: Beam's ParDo becomes Spark's map/flatMap, GroupByKey becomes groupBy, and CoGroupByKey becomes a join. Streaming pipelines require more work to adapt from Beam's windowing model to Spark's micro-batch triggers. Budget 4-8 weeks for complex pipelines.
Switching to an orchestrator like Airflow or Dagster means decomposing monolithic Beam pipelines into discrete tasks that can be scheduled independently. This often improves debuggability and operational visibility at the cost of losing Beam's unified in-memory execution model. The timeline depends heavily on pipeline count; teams with 10-20 pipelines typically complete migration within one quarter.
For Kafka Streams migration, the main constraint is that all source and sink data must flow through Kafka topics. If your Beam pipelines read from non-Kafka sources (databases, cloud storage, APIs), you will need to set up Kafka Connect connectors first. Once data is in Kafka, rewriting Beam transforms as Kafka Streams topologies is relatively fast for stateless operations but requires careful state store design for windowed aggregations.
Regardless of the target platform, maintain parallel running of old and new pipelines during migration. Compare output datasets row-by-row for at least two full processing cycles before decommissioning the Beam implementation. This catch-and-compare approach prevents silent data quality regressions that are common in pipeline migrations.