Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Google states |
|---|---|
Pipeline languages | Apache Beam SDKs, with Beam quickstarts for Java, Python and Go. |
Scale | Up to 4K workers per job, with autoscaling for batch and streaming pipelines. |
Typical sources and destinations | Streams from Pub/Sub, Kafka and CDC events into BigQuery, Cloud Storage, Spanner, Bigtable, SQL stores, Splunk and Datadog; reverse ETL from BigQuery to OLTP stores. |
Security and governance | Confidential VM support, customer-managed encryption keys, VPC Service Controls, an option to turn off public IPs, and audit logging. |
Google-provided templates | Apache-2.0 templates for import, export, backup, restore and bulk API tasks without a development environment, such as Kafka to BigQuery and JDBC to BigQuery. |
Our take
Choose Dataflow when your batch and streaming pipelines run on Google Cloud and you want Google to operate the workers. It suits teams that can write Apache Beam code for custom logic, or whose integration needs match the Google-provided templates.
Evaluate Google Cloud Dataflow
Comparisons
Where it stands out
One model for batch and streaming. Beam's unified model covers state and time, transformations and I/O connectors for both kinds of pipeline. Google says this makes workloads portable between clouds, on-premises environments and edge devices.
A way in without writing code. Templates are optimized for CDC and BigQuery integration, the job builder is a visual UI for building and running pipelines in the console, and a UDF builder adds custom logic to template jobs.
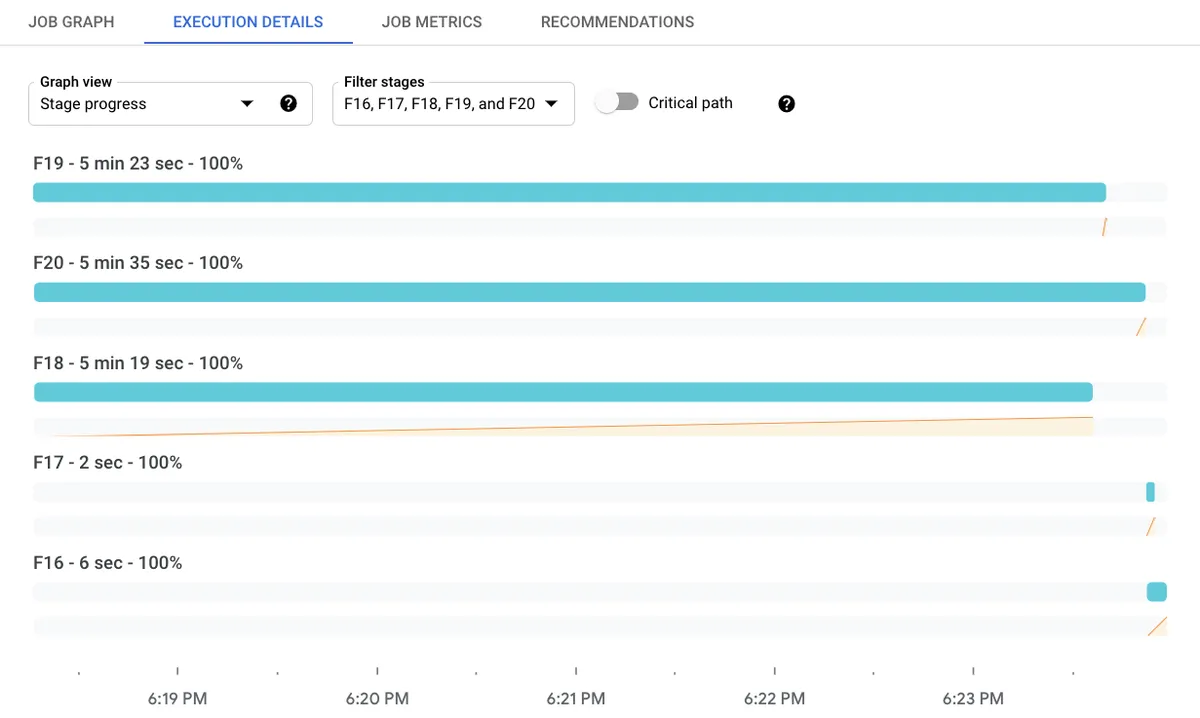
Diagnostics built in. Straggler detection finds bottlenecks, data sampling shows data at each step, Dataflow Insights recommends job improvements, and a job cost monitoring UI supports cost estimation.
Streaming ML features. RunInference, MLTransform, Enrichment for feature store lookups and dynamic GPU support bring inference and preprocessing into streaming pipelines.
Product screenshot

Trade-offs to weigh
Custom work means Beam code. Logic beyond templates, the UDF builder and the job builder is written with Beam transforms and I/O connectors, so teams new to Beam should plan for that skill.
The managed service is Google Cloud's. The Beam code can move, but Dataflow itself runs on Google Cloud infrastructure, and its templates target in-cloud data tasks.
Pricing and billing conditions
Dataflow's compute charges cover worker CPU and memory, Dataflow Shuffle data processed for batch workloads, Streaming Engine Compute Units and Streaming Engine data processed. Persistent Disk, GPUs and snapshots are billed for all jobs. Google's pricing calculator estimates monthly costs, including region-specific pricing and fees, and sales can provide a custom quote.
Committed use discounts: 20% off the on-demand rate for one year, or 40% for three years.
New customers: $300 in free credits to spend on Dataflow.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
284 GitHub commits 90d1.3k GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
Three-month score against stable baseline terms—not search volume or adoption.
npm · @google-cloud/dataflow@5.2.0
Alternatives to Google Cloud Dataflow
The reviewed substitutes for Google Cloud Dataflow among the data processing engines, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Apache Flink
- Apache Flink and Google Cloud Dataflow both process streaming and batch data with stateful, scalable pipelines. Flink is an open-source engine that teams deploy on their own clusters or through a managed service, while Dataflow is Google's fully managed, autoscaling service that runs Apache Beam pipelines on Google Cloud.Applies to: Choosing between two products of the same kind for one job.