Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Google states |
|---|---|
Deployment | Runs on Google Cloud; BigQuery Omni runs on-demand queries in listed AWS and Azure regions. |
Compute billing | On-demand (per TiB processed) by default; capacity pricing (slots) is turned on through reservations. |
Trying it | BigQuery sandbox without a credit card, kept within the free tier; use public datasets or your own data. |
Interfaces | ANSI-standard SQL via the console, bq CLI, client libraries (Python, Java, JavaScript, Go), REST and RPC APIs, ODBC and JDBC drivers. |
Getting data in | Streaming (Storage Write API); batch loads of Avro, Parquet, ORC, CSV, JSON and other formats; Data Transfer Service; Iceberg, Delta and Hudi table formats. |
Reliability and security | 99.99% uptime SLA, encryption by default, customer-managed encryption keys, Google Cloud IAM. |
Our take
Choose BigQuery if your data and BI tools already sit on Google Cloud and you want SQL analytics without running a cluster, provided someone owns byte limits and quotas before broad access opens. If finance needs a fixed compute bill, plan on capacity reservations from the start.
Evaluate Google BigQuery
Popular comparisons
See all 20 Google BigQuery comparisons
Where it stands out
No cluster to run. Compute and storage scale separately and you need not provision or scale resources by hand, so a small team focuses on queries.
Per-query cost guards. For on-demand queries, you can set user- and project-level cost controls and a maximum bytes billed per query, and failed queries and cached results are not charged.
A path from pay-per-use to reserved capacity. You can run editions fully on demand (reservation baseline 0, a set maximum) and let BigQuery autoscale. Enterprise and Enterprise Plus add one- or three-year slot commitments that can cost less than pay-as-you-go.
Machine learning inside the warehouse. BigQuery ML trains and deploys models with SQL or Python; BigQuery DataFrames gives a pandas-compatible API. Gemini in BigQuery features are included in BigQuery pricing models.
Query data where it lives. External tables and federated queries reach Cloud Storage, Bigtable, Spanner and Google Sheets, and Iceberg data is readable and writable from Spark and other engines. BI support covers Data Studio, Looker, Google Sheets, Tableau and Power BI.
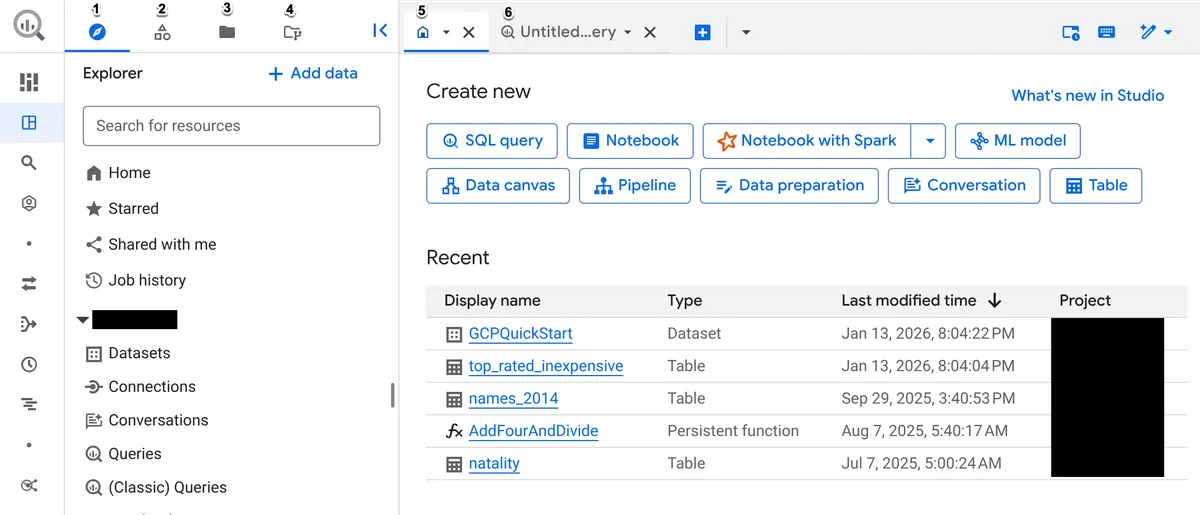
Product screenshot

Trade-offs to weigh
Wide queries cost money, even small ones. On-demand charges follow the columns you select, even with a LIMIT. Each query bills at least 10 MB per referenced table and per query, so queries on KB-sized tables can cost much more than an on-demand estimate suggests. Cancelling a running query might still cost the full query. Partitioning and clustering can reduce data scanned.
On-demand budget caps stop work. On-demand, the only way to restrict cost is a project- or user-level daily quota, and queries stop once it is reached.
On-demand capacity is shared. You generally get up to 2,000 concurrent slots shared by all queries in a project, fewer under contention.
Slot billing has rounding and lock-in. The autoscaler bills in multiples of 50 slots with a one-minute minimum unless you opt in to fluid scaling. Fixed reservations bill provisioned slots, not used ones. Commitments are regional, auto-renew unless set to cancel, and keep billing after the Reservations API is disabled.
Storage billing depends on settings. The billing model (logical or physical) is set per dataset. On the physical model, time travel (seven days by default) and frequent table overwrites add storage charges. A table or partition not modified for 90 consecutive days drops 50 percent in storage price, but changes to its data, metadata or schema can move it back.
Some features bill as edition slots. BigQuery Studio notebooks bill as Standard edition pay-as-you-go slots and Apache Spark procedures as Enterprise edition slots, whatever the project's compute model. Some BigQuery ML operations cost more per TB than ordinary queries.
Pricing and plan conditions
BigQuery bills compute and storage separately, and charges on top for operations such as BigQuery Omni, BigQuery ML, BI Engine and streaming reads and writes. Pricing models apply to the account, not single projects, unless stated otherwise. The free 10 GB of storage and up to 1 TB of queries each month are not charged against credits; new customers get $300 in credits for BigQuery and other Google Cloud products.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Item | Published price | Conditions |
|---|---|---|
On-demand queries | First 1 TiB free per month / account; then $6.25 / 1 TiB (USD) | Charged on data processed in the columns you select. Prices depend on location. |
Capacity compute (editions) | Starting at $0.04 per slot hour | Standard, Enterprise and Enterprise Plus editions; billed per second, one-minute minimum by default. 1- or 3-year commitments (Enterprise and Enterprise Plus, 50-slot minimum). |
Storage | Logical: starting at $0.01 per GiB. Physical: starting at $0.02 per GiB | Logical counts uncompressed bytes, physical counts compressed bytes. The first 10 GiB is free each month. |
Data ingestion | Batch loading: Free. Streaming inserts: $0.01 per 200 MiB. Storage Write API: $0.025 per 1 GiB | Batch loading is free when using the shared slot pool. Streaming inserts bill successful rows, 1 KB minimum per row. Storage Write API: first 2 TiB per month free. |
Data extraction | Batch export: Free. Streaming reads: starting at $1.10 per TiB read | Batch export is free when using the shared slot pool; streaming reads use the Storage Read API. |
BigQuery Omni on-demand | $9.125 / 1 tebibyte | Runs in AWS and Azure regions. |
Agents | $3 per million input tokens; $20 per million output tokens | Data Science Agent, Data Engineering Agent and Conversational Analytics Agent. |
Google's pricing calculator estimates monthly costs with regional prices and fees; sales gives custom quotes.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
38.6M PyPI weekly downloads6.9M npm weekly downloads0 vulnerabilities across 2 packages
See all signals from 6 sources
npm · @google-cloud/bigquery@9.5.0 · PyPI · google-cloud-bigquery@3.47.0
Alternatives to Google BigQuery
The reviewed substitutes for Google BigQuery among the cloud data warehouses, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Snowflake
- Both are cloud data warehouses bought for the same job: the central SQL analytics store. A team picks one.
- Amazon Redshift
- The two hyperscaler-native cloud data warehouses. A team standardising on one cloud evaluates its warehouse against the other's.
- Teradata
- The enterprise data warehouse behind company-wide reporting can run on Google BigQuery or on Teradata. BigQuery is fully managed and serverless on Google Cloud, with storage and compute scaled separately. Teradata Vantage can run on any major cloud, in hybrid setups or on-premises, which suits large firms with long-standing warehouse workloads.Applies to: Choosing between these two for the cloud data warehouses decision.
- Firebolt
- Two analytical warehouses serving the same central-store decision. They are compared for one budget, differ on pricing shape and deployment, and an organisation loads its data into one.Applies to: Choosing the warehouse that will hold the organisation's analytical data.
- MotherDuck
- Google BigQuery and MotherDuck are serverless SQL warehouses where nobody has to size or manage clusters. BigQuery is Google Cloud's managed warehouse and fits teams already built on Google services. MotherDuck is built on the open-source DuckDB engine and can run part of a query on the user's own laptop, which keeps it light for smaller data teams.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Databricks
- Google BigQuery and Databricks can each be the main platform where a company stores and analyses its data. BigQuery is a serverless SQL warehouse on Google Cloud and suits teams whose work is mostly SQL and BI. Databricks is a lakehouse on open storage formats with Spark, notebooks and ML tooling, and suits teams whose work is mostly data engineering and machine learning.Applies to: For teams choosing one main platform for both SQL analytics and data engineering or machine learning.
- Starburst
- A warehouse that owns its storage and a lakehouse or federated engine that queries data in open formats reach the same analytics by different architectures. The decision is whether data is loaded into one platform or left in object storage and queried where it sits, which is why these appear together on central-store shortlists.Applies to: Deciding whether analytical data is loaded into one platform or queried in open formats where it sits.
- SingleStore
- Analytical SQL on large data runs on Google BigQuery and on SingleStore. BigQuery is a serverless warehouse on Google Cloud for reporting and batch analysis. SingleStore is a distributed SQL database that handles transactions and analytics in one engine, so it fits when an application needs real-time analytics on live operational data.Applies to: When analytics must run with low latency on live operational data.
- DuckDB
- Google BigQuery and DuckDB both run analytical SQL over columnar data. BigQuery is a serverless cloud warehouse for shared, company-wide data on Google Cloud. DuckDB is an open-source engine that runs in-process on a laptop or inside an application, so quick queries on local files need no warehouse at all.Applies to: Serving fast analytical queries, and whether the central warehouse can also carry them.
- Apache Druid
- Google BigQuery and Apache Druid both answer analytical queries over large event data. BigQuery is a serverless general warehouse on Google Cloud for broad reporting and data science. Druid is an open-source real-time database that ingests streams and returns sub-second answers, which matters when dashboards must reflect events within seconds.Applies to: When dashboards must show streaming events within seconds of their arrival.
Head to head
See detailed alternatives analysis
If you are evaluating Google BigQuery alternatives, you are likely looking for a cloud data warehouse that better fits your team's architecture, pricing preferences, or multi-cloud strategy. BigQuery is a serverless, fully managed data warehouse from Google Cloud that separates storage from compute and charges primarily based on data scanned per query or reserved capacity through its Editions model. It offers a generous free tier and deep integration with the Google Cloud ecosystem, but teams with multi-cloud requirements, cost predictability concerns, or workloads outside the GCP ecosystem often explore other options.
Below is a detailed breakdown of the leading Google BigQuery alternatives across architecture, pricing, migration considerations, and use-case fit.
Top Alternatives Overview
Snowflake is a fully managed cloud data platform that runs on AWS, Azure, and Google Cloud. It uses a credit-based consumption model and separates storage from compute, allowing independent scaling of each layer. Snowflake is known for its ease of use, strong SQL support, and multi-cloud portability. It offers Standard, Enterprise, Business Critical, and Virtual Private Snowflake (VPS) tiers, each with different governance and security capabilities. Snowflake is a strong fit for teams that prioritize SQL-first analytics, cross-cloud flexibility, and predictable warehouse sizing.
Databricks is a unified analytics and AI platform built around the lakehouse architecture, combining data lake flexibility with data warehouse structure. Built on Apache Spark, Databricks provides collaborative notebooks, Delta Lake storage, managed Spark clusters, and integrated ML tooling. It uses a consumption-based pricing model centered on Databricks Units (DBUs), with rates varying by workload type, subscription tier (Standard, Premium, Enterprise), and cloud provider. Databricks is particularly strong for teams that need data engineering, machine learning, and SQL analytics on a single platform.
Amazon Redshift is a fully managed, petabyte-scale cloud data warehouse from AWS. It uses columnar storage and massively parallel processing (MPP) for fast query performance on large datasets. Redshift integrates deeply with the AWS ecosystem including S3, Glue, SageMaker, and QuickSight. It offers both provisioned clusters and a serverless option, making it a natural choice for organizations already invested in AWS infrastructure.
Starburst is an enterprise analytics platform built on Trino that enables federated queries across data lakes, warehouses, and databases without requiring data movement. It offers a free tier with up to three clusters, a Pro tier, and an Enterprise tier. Starburst is ideal for organizations that need to query data across multiple sources and formats from a single SQL interface.
MotherDuck is a cloud SQL analytics platform powered by DuckDB. It features a dual query execution architecture that runs queries across local machines and the cloud simultaneously. With a free Lite plan, a Business plan and a custom-priced Enterprise plan, MotherDuck targets analysts and smaller teams who want fast, low-cost SQL analytics without managing heavy infrastructure.
Firebolt is a cloud data warehouse focused on low-latency analytics and high concurrency for data-intensive applications. It uses columnar compression and is designed for workloads like ad-tech, gaming analytics, and real-time dashboards where sub-second query response times are critical.
Architecture and Approach Comparison
The core architectural distinction among these alternatives centers on how they handle the relationship between storage, compute, and data formats.
Google BigQuery uses a fully serverless model where storage and compute are entirely decoupled. You do not provision clusters or manage infrastructure. Under the hood, BigQuery relies on Google's Dremel execution engine, Colossus distributed file system, and Jupiter network fabric. This architecture enables automatic scaling and eliminates capacity planning, but it also means you have limited control over execution resources and are fully dependent on GCP.
Snowflake also separates storage and compute but gives users explicit control over virtual warehouse sizing. You choose warehouse sizes (from X-Small to 6X-Large) that consume credits at different rates, and you can spin up multiple warehouses for workload isolation. This model offers more predictable performance characteristics than BigQuery's shared slot pool while still avoiding infrastructure management. Snowflake runs natively on AWS, Azure, and GCP, providing genuine multi-cloud portability.
Databricks takes a fundamentally different approach with its lakehouse architecture. Data resides in open formats (Delta Lake, Apache Iceberg) on cloud object storage, and compute is provided through managed Apache Spark clusters. This means your data is never locked into a proprietary format. Databricks excels at combining batch processing, streaming, SQL analytics, and machine learning within a single platform, though it requires more technical expertise to operate effectively compared to BigQuery's serverless simplicity.
Amazon Redshift uses a massively parallel processing (MPP) architecture with columnar storage. Its provisioned mode requires you to select node types and cluster sizes, while Redshift Serverless offers an on-demand alternative. Redshift's deep integration with S3, Glue Data Catalog, and other AWS services makes it the natural warehouse choice within the AWS ecosystem, but it lacks the cloud-agnostic flexibility of Snowflake or Databricks.
Starburst operates differently from the others by providing a federated query layer rather than a standalone warehouse. Built on Trino, it runs queries across data wherever it lives -- in S3, HDFS, PostgreSQL, BigQuery, or other sources -- without requiring data movement or duplication. This architecture is particularly valuable for organizations with data spread across many systems that cannot or should not be consolidated.
MotherDuck brings a hybrid local-cloud approach powered by DuckDB, an in-process analytical database. Queries can execute on your local machine, in the cloud, or across both simultaneously. This architecture delivers fast iteration cycles for analysts working with moderate data volumes and significantly reduces cloud compute costs for exploratory work.
Pricing Comparison
Pricing models vary significantly across these platforms, and the best choice depends on your workload patterns and scale.
Google BigQuery offers on-demand pricing at $6.25 per TiB of data scanned, with the first 1 TB per month free. Storage is billed at $0.02 per GB per month for active data, with a lower rate for long-term storage on data untouched for 90 days. For predictable workloads, BigQuery Editions provide capacity-based pricing: Standard at $0.04 per slot-hour, Enterprise at $0.06 per slot-hour, and Enterprise Plus at $0.10 per slot-hour, with additional discounts available through one-year and three-year commitments.
Snowflake uses a credit-based consumption model where credit prices vary by edition and commitment level. Standard, Enterprise, and Business Critical tiers each carry different per-credit rates, with pre-purchase commitments offering lower rates than on-demand pricing. Storage is billed separately on a per-TB basis, with costs varying by region and payment model. Snowflake does not offer a permanent free tier, though a 30-day free trial is available.
Databricks charges through Databricks Units (DBUs), with rates depending on workload type and tier. Jobs Compute carries the lowest per-DBU rate, while All-Purpose Compute for interactive notebooks costs significantly more, and Serverless SQL includes compute costs in the DBU price. Critically, cloud infrastructure costs (VMs, storage, networking) from AWS, Azure, or GCP are billed separately and typically add substantially on top of DBU charges. Databricks offers a free Community Edition for learning and prototyping, plus a 14-day free trial.
Amazon Redshift offers new Serverless accounts a $300 credit that expires after 90 days, not a free tier. Redshift Serverless charges based on compute used, while provisioned clusters are billed by node-hour. Reserved instance pricing is available for one-year and three-year commitments with significant discounts over on-demand rates.
Starburst offers a free tier with up to three clusters. Its Pro tier starts at $0.50 per credit with flexible cluster execution, while the Enterprise tier starts at $0.75 per credit and includes advanced autoscaling and fine-grained access controls.
MotherDuck's Lite plan is free for up to 3 internal active users with 10 GB of storage, Business is $250 per organization per month plus usage, and Enterprise is custom priced.
When to Consider Switching
Several scenarios make it worthwhile to evaluate alternatives to Google BigQuery.
Multi-cloud or cloud-agnostic strategy. BigQuery is exclusively a GCP service. If your organization operates across AWS, Azure, and GCP, or wants to avoid vendor lock-in to a single cloud, Snowflake (which runs on all three major clouds) or Databricks (which also supports multi-cloud deployment) offer substantially more flexibility. Starburst's federated query approach can also bridge multiple cloud environments without requiring data consolidation.
Cost unpredictability with on-demand pricing. BigQuery's on-demand model ties costs directly to bytes scanned per query. Poorly optimized queries, unpartitioned tables, or broad SELECT patterns can cause cost spikes. If your team struggles with query cost management, Snowflake's warehouse-based model or Redshift's provisioned clusters may provide more predictable budgeting. Databricks' Jobs Compute pricing can also be more cost-efficient for scheduled production workloads.
Advanced data engineering and ML workflows. While BigQuery includes BigQuery ML for in-warehouse machine learning, Databricks offers a significantly deeper platform for end-to-end data engineering and machine learning, with native Spark processing, MLflow experiment tracking, and model serving. Teams with heavy ML or streaming workloads often find Databricks provides a more cohesive development experience.
AWS-native infrastructure. If your data already lives in S3 and your stack is built on AWS services, Amazon Redshift's tight integration with Glue, SageMaker, Lake Formation, and other AWS services often reduces friction and data transfer costs compared to moving data to GCP for BigQuery processing.
Federated query requirements. If you need to query data across many heterogeneous sources without centralizing everything into a single warehouse, Starburst's Trino-based federated engine is purpose-built for this pattern. BigQuery Omni offers some cross-cloud capability but is limited to Enterprise Plus edition and specific scenarios.
Cost sensitivity at smaller scale. For teams with moderate data volumes that need fast SQL analytics without enterprise-scale pricing, MotherDuck's DuckDB-powered platform or Firebolt's performance-focused architecture may deliver better price-performance at a modest absolute cost.
Migration Considerations
Moving away from Google BigQuery involves several practical factors that should be part of your evaluation.
SQL dialect differences. BigQuery uses GoogleSQL (formerly Standard SQL) with specific syntax for features like STRUCT and ARRAY types, MERGE statements, and table decorators. Snowflake, Redshift, and Databricks each have their own SQL variations. Google offers a BigQuery Migration Service with an interactive SQL translator that supports conversion to other dialects, which can accelerate the transition. However, complex queries with BigQuery-specific functions (like APPROX_COUNT_DISTINCT or SAFE_DIVIDE) will require manual review.
Data export and transfer. BigQuery data stored in Google Cloud Storage can be exported in Avro, Parquet, CSV, or JSON formats. Parquet is generally the most efficient format for migration to other columnar warehouses. Be aware of data transfer costs when moving large volumes out of GCP -- cross-cloud egress charges apply. For Databricks migrations, converting to Delta Lake or Apache Iceberg format during export can streamline ingestion on the target platform.
Ecosystem dependencies. Evaluate how deeply your workflows depend on GCP-specific services. If you use Looker Studio, Gemini Enterprise Agent Platform, Cloud Functions, or Pub/Sub alongside BigQuery, migrating the warehouse means rearchitecting these integrations as well. Organizations using BigQuery primarily as a standalone analytical engine will find migration simpler than those with deep GCP pipeline dependencies.
Access control and governance. BigQuery's IAM-based permissions model differs from Snowflake's role-based access control, Databricks' Unity Catalog, and Redshift's integration with AWS IAM and Lake Formation. Recreating fine-grained access policies is often one of the more time-consuming aspects of migration. Plan for a thorough audit of existing permissions and a mapping exercise to the target platform's security model.
Scheduling and orchestration. If you use BigQuery's scheduled queries, Data Transfer Service, or Cloud Composer (managed Airflow), identify equivalents on the target platform early. Snowflake Tasks, Databricks Workflows, and Redshift's native scheduling each have different capabilities and limitations. Third-party orchestrators like Apache Airflow or dbt Cloud can provide a platform-agnostic orchestration layer that simplifies future migrations.