Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What the Apache Pinot project states |
|---|---|
Best-fit workload | Low-latency OLAP queries, such as aggregations, on immutable data, possibly with real-time ingestion; works well for time series data with many dimensions and metrics |
Data ingestion | Real time from Apache Kafka, Apache Pulsar and AWS Kinesis; batch from Hadoop, Spark, AWS S3 and more; batch and streaming sources can be combined into a single table |
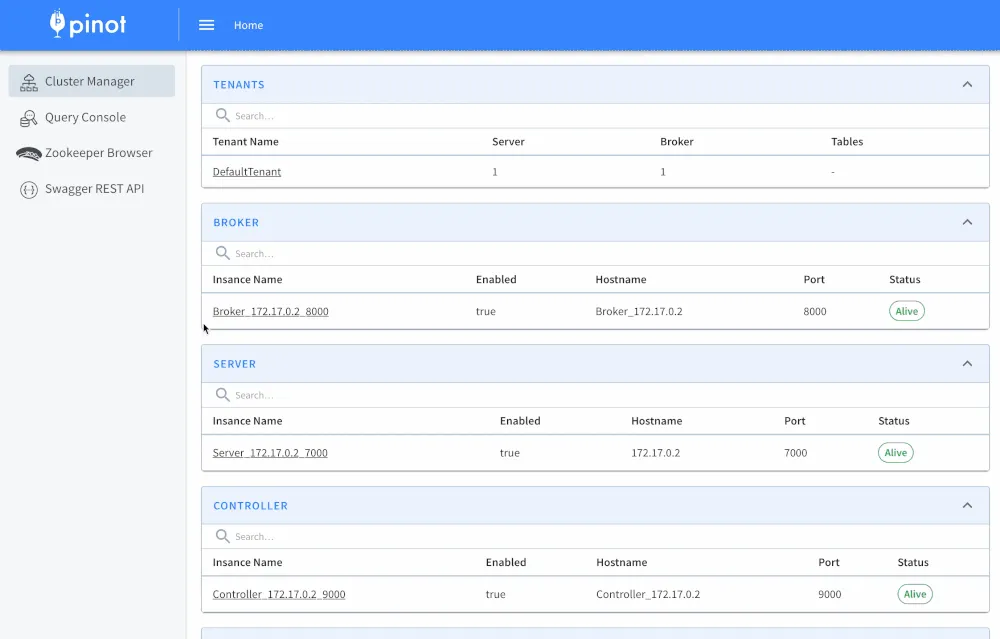
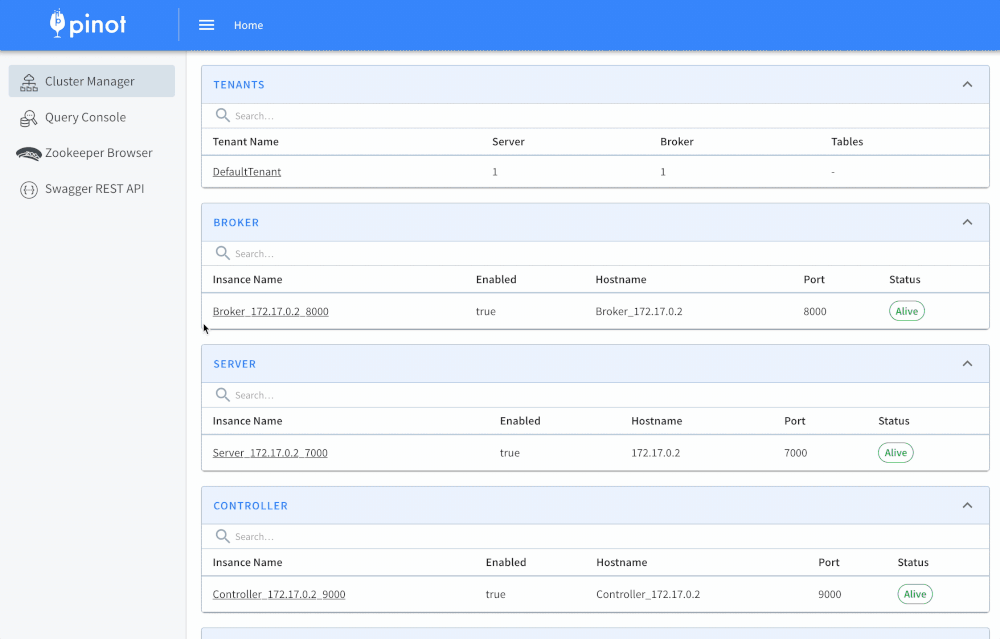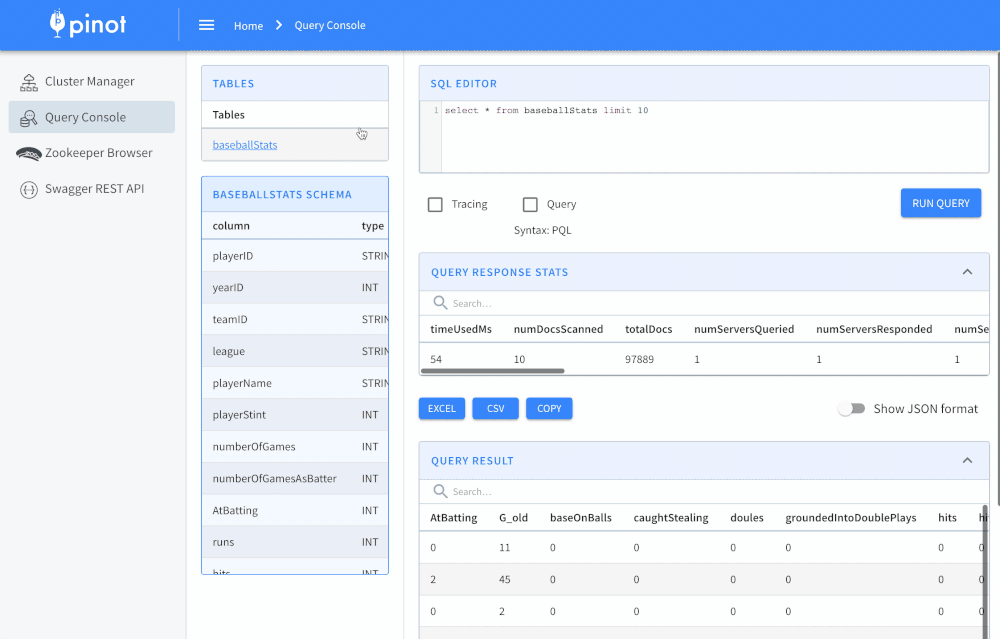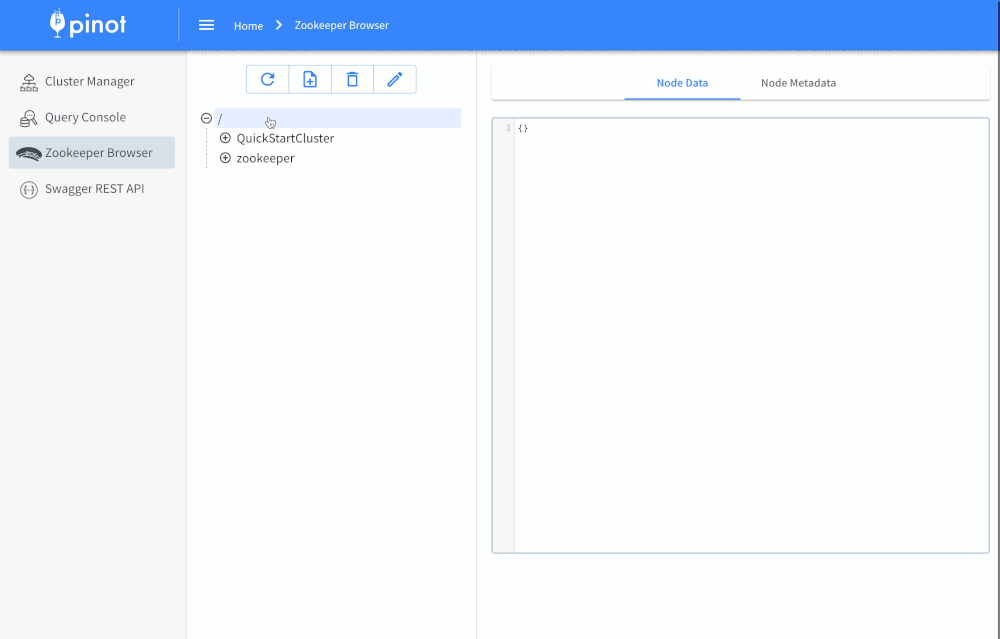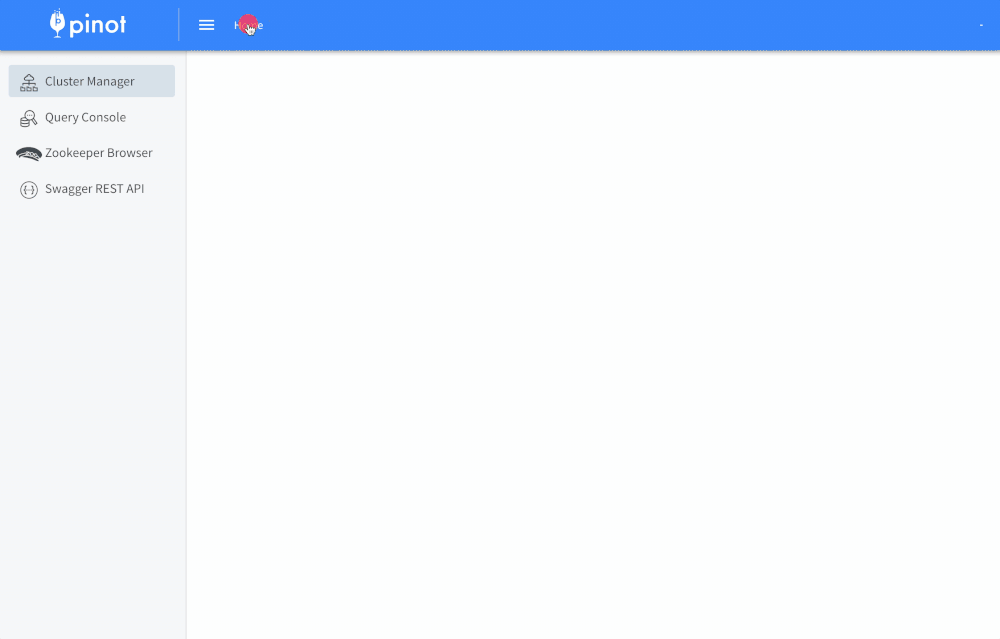
Query access | Standard SQL through a built-in query editor and a REST API |
Production deployment | Helm chart for a horizontally scalable, fault-tolerant clustered deployment on Kubernetes; Pinot services require JDK 25+ to build and run |
Current release | Apache Pinot 1.5.1 |
Help channels | Community: Apache Pinot Slack, the pinot-dev and pinot-user mailing lists, and a Meetup group |
Our take
Choose Apache Pinot if your product, your customers or your AI agents must query fresh event data interactively at high concurrency, and your team can run and tune a distributed database itself. If you mainly need scheduled reports for a few internal analysts, Pinot's strengths will not pay back the work of operating it.
Evaluate Apache Pinot
Popular comparisons
See all 6 Apache Pinot comparisons
Where it stands out
Latency for live screens. The project states it can filter and aggregate petabyte data sets with P90 latencies in the tens of milliseconds, fast enough to return live results in a UI. That is the target for embedded dashboards and metrics APIs.
Many readers at once. With applications and AI agents querying Pinot directly, the project says it can serve hundreds of thousands of concurrent queries per second.
Updates without batch reloads. Upserts let you ingest the same record many times and see only the latest value at query time; the project says they are built-in and production-tested since version 0.6.
Index choice per query pattern. Pluggable indexes include timestamp, inverted, StarTree, Bloom filter, range, text, JSON and geospatial, so you can match indexes to how users filter and search.
Joins and shared use. Pinot supports arbitrary fact/dimension and fact/fact joins on petabyte data sets, and built-in multitenancy manages and secures data in isolated logical namespaces for several teams or workloads.
Large production users. The Pinot site quotes Stripe tracking over $18.6B in transaction volume across 300M+ transactions during Black Friday-Cyber Monday with P99 latency of 70ms, and Walmart ingesting 14 million events per minute from Kafka with under 900ms lag.
Product screenshot
Trade-offs to weigh
Published numbers are not your numbers. The site says its performance figures come from production deployments at LinkedIn, Stripe, Uber and other users, and that results will vary based on hardware, schema design and query complexity. Plan a proof of concept with your own data and query mix.
Speed depends on design work. Many index types help only when your team knows its access patterns and keeps schemas and indexes aligned with them; that is ongoing engineering, not a setting.
Upgrades need planning. The project advises installing its Lucene recovery release on the intended rollback target before upgrading Lucene, and notes that rebuilding text and HNSW indexes adds CPU/I/O and segment-loading time.
You operate the cluster. Production use means running a clustered deployment, for example on Kubernetes with the Helm chart, so plan for engineers who can handle ingestion, indexing and incidents.
Pricing and plan conditions
You download Apache Pinot and run it yourself, so your cost comes from the infrastructure you run it on, such as Kubernetes capacity, storage and streaming sources, and from the engineering time to operate it. Query concurrency, ingestion rate and data volume drive how large that cluster needs to be.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Item | What the project states | What it means for a buyer |
|---|---|---|
License | Apache License, Version 2.0 | Open-source software you can run and modify under that license |
Local trial | Docker image apachepinot/pinot:1.5.1 with the QuickStart -type hybrid command, then the query console on localhost:9000 | A way to test queries before sizing a cluster |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
702 GitHub commits 90d6.2k GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
Three-month score against stable baseline terms—not search volume or adoption.
PyPI · pinotdb@9.2.2
Alternatives to Apache Pinot
The reviewed substitutes for Apache Pinot among the OLAP databases, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- ClickHouse
- Both are OLAP databases serving low-latency analytical queries over event data. The same requirement selects one.
- StarRocks
- Low-latency analytical queries on fresh data at scale are what StarRocks and Apache Pinot are built for. Pinot targets user-facing analytics with very high query rates and special indexes for that load. StarRocks is an MPP database that leans on ad-hoc SQL across many tables and on querying lakehouse tables in place.Applies to: Choosing between these two for the real time analytical databases decision.
- SingleStore
- SingleStore and Apache Pinot are real-time analytical databases that answer queries on fresh data in milliseconds. Pinot is an open-source distributed OLAP store built for user-facing analytics at very high query rates. SingleStore is a commercial database that adds transactions, JSON, full-text and vector workloads to its analytics engine.Applies to: Choosing between these two for the real time analytical databases decision.
- Apache Druid
- Apache Druid and Apache Pinot are open-source real-time OLAP databases built for the same job: sub-second aggregation over streaming event data for many concurrent users. Druid leans on time-series rollup at ingestion, while Pinot leans on strict low latency for user-facing analytics.Applies to: Choosing a real-time OLAP database for user-facing analytics over streaming events.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Databricks
- Databricks and Apache Pinot both answer analytical queries over large data. Databricks bundles data engineering, SQL and machine learning in a lakehouse on cloud object storage. Pinot is an open-source real-time OLAP store for low-latency, user-facing queries, and suits a team whose main need is fast answers rather than a platform that also runs ETL and ML.Applies to: Serving low-latency analytical queries, and whether one platform must also carry ETL and ML.
- Imply Cloud
- Apache Pinot is used rather than Imply Cloud for user-facing real-time analytics workloads that demand highly configurable indexing and very high query concurrency. We recommend Pinot for teams building interactive analytics experiences with high concurrency and strong indexing requirements.
- Google BigQuery
- Google BigQuery and Apache Pinot each answer analytical SQL over large volumes of event data. BigQuery is a serverless warehouse built for broad internal analysis on Google Cloud. Pinot is an open-source real-time OLAP store designed for very low latency at high query rates, which suits analytics shown to end users inside a product.Applies to: Serving fast analytical queries, and whether the central warehouse can also carry them.
- Snowflake
- Snowflake and Apache Pinot both run analytical queries over large volumes of data. Snowflake is the managed central warehouse for internal reporting and data teams. Pinot is an open-source real-time OLAP datastore built for low-latency queries at very high request rates, which is what analytics shown to customers inside an app needs.Applies to: Serving fast analytical queries, and whether the central warehouse can also carry them.
Head to head
See detailed alternatives analysis
If you are evaluating Apache Pinot alternatives, you are likely looking for a real-time analytics engine that better fits your specific workload, operational complexity tolerance, or budget. Apache Pinot is a powerful distributed OLAP datastore built for ultra-low-latency, high-concurrency analytics, originally developed at LinkedIn. However, depending on your use case—whether it is ad hoc querying, time-series workloads, embedded analytics, or lakehouse-style federation—other tools may serve you better. Below, we break down the top alternatives and help you decide which one fits your needs.
Top Alternatives Overview
ClickHouse is the most popular open-source column-oriented database for real-time analytics, with over 48,000 GitHub stars. It excels at high-speed analytical queries on large datasets using a columnar storage engine written in C++. ClickHouse supports both self-hosted and managed cloud deployments and is known for straightforward configuration and strong data replication capabilities.
Trino (formerly PrestoSQL) is a distributed SQL query engine designed for federated querying across multiple data sources. With over 12,700 GitHub stars, Trino lets you query data in place across Hadoop, S3, Cassandra, MySQL, and many other systems without moving it. Trino is available as a free community edition (self-hosted under Apache-2.0) alongside a managed cloud offering.
StarRocks is an open-source analytics engine (over 11,500 GitHub stars) purpose-built for sub-second query latency on complex multi-table joins. It supports real-time data updates and deletes without degrading query performance and can build analytics directly on open data formats without denormalization or data copying.
DuckDB takes a fundamentally different approach as an in-process, embedded OLAP database. With over 37,500 GitHub stars, DuckDB runs inside your application process—no server needed—making it ideal for local analytics, data science workflows, and single-node analytical workloads.
InfluxDB is a purpose-built time-series database with over 31,000 GitHub stars. If your primary workload is metrics, IoT sensor data, or monitoring, InfluxDB provides a specialized storage engine and query language optimized for time-series patterns.
Timescale extends PostgreSQL with time-series capabilities, giving you the full PostgreSQL ecosystem alongside optimized time-series storage and queries. SingleStore combines transactional and analytical workloads in a single distributed SQL database. Starburst builds on Trino to offer an enterprise data lakehouse platform with managed governance features. Dremio provides a lakehouse query engine with usage-based pricing focused on self-service analytics.
Architecture and Approach Comparison
The alternatives to Apache Pinot fall into distinct architectural categories, and understanding these differences is critical for making the right choice.
Apache Pinot uses a segment-based columnar storage architecture with a dedicated real-time ingestion layer. It ingests from streaming sources like Apache Kafka, Apache Pulsar, and AWS Kinesis in real time, and supports batch ingestion from Hadoop, Spark, and S3. Pinot's distributed architecture includes separate controller, broker, server, and minion components, along with a Zookeeper dependency for coordination. It features built-in upsert support (production-tested since version 0.6), rich pluggable indexing (including StarTree, inverted, Bloom filter, range, text, JSON, and geospatial indexes), and native multitenancy. Written in Java and licensed under Apache-2.0, the Apache Pinot 1.5.1 is available now..
ClickHouse also uses columnar storage but takes a different approach to ingestion and indexing. It relies on its MergeTree engine family for ordering, partitioning, and advanced compression (LZ4, ZSTD), and excels at batch-oriented analytical queries with vectorized execution for maximum CPU throughput. Newer versions replace the Zookeeper dependency with ClickHouse Keeper, simplifying operations.
Trino and Starburst operate as query engines rather than storage engines. They do not store data themselves but query data where it lives—across data lakes, databases, and object stores. Trino connects to over 50 data sources through its connector architecture. This federated approach avoids data duplication but means query latency depends on the underlying storage system.
StarRocks combines a native columnar storage engine with an MPP execution framework and a cost-based optimizer. It supports querying Apache Iceberg, Delta Lake, and Hudi tables directly without data copying, and its primary key table design handles real-time upserts at low freshness latency. StarRocks uses MySQL protocol compatibility, easing migration from MySQL-based stacks.
DuckDB operates entirely in-process with no client-server architecture at all. It uses vectorized columnar execution optimized for single-node analytical queries, embedding directly into Python, R, Java, or other applications. It is the right tool for single-machine analytics but not for distributed, multi-tenant workloads.
InfluxDB and Timescale are specialized for time-series data. InfluxDB uses a custom time-structured merge tree storage engine, while Timescale extends PostgreSQL with hypertables and automatic partitioning by time. Both are optimized for write-heavy, time-ordered ingestion patterns.
Pricing Comparison
Apache Pinot is free and open-source under the Apache License 2.0. You bear infrastructure and operational costs when self-hosting. A managed service (StarTree Cloud) is available with custom pricing.
ClickHouse is also free and open-source for self-hosting. A managed ClickHouse Cloud service is available with usage-based pricing.
Trino's community edition is free and self-hosted under Apache-2.0. A managed cloud version is also available.
StarRocks is free and open-source under Apache-2.0 for self-hosting. A managed offering (CelerData) provides enterprise support.
DuckDB is completely free and open-source as an embedded engine with no server costs whatsoever.
InfluxDB offers a free community edition for self-hosting.
Timescale offers a free tier and paid plans for its managed service.
SingleStore offers paid plans starting at its Starter tier. Pricing scales with storage and compute requirements.
Starburst provides a free tier with limited clusters and paid tiers with per-credit pricing.
Dremio uses usage-based pricing.
For teams considering managed offerings, the total cost of ownership varies significantly based on data volume, query concurrency, and whether you need real-time ingestion. Self-hosting any of the open-source options (Pinot, ClickHouse, Trino, StarRocks, DuckDB) eliminates licensing costs but requires engineering resources for operations, monitoring, and upgrades. Pinot's multi-component architecture (Zookeeper, controller, broker, server) typically demands a larger minimum production cluster than ClickHouse or StarRocks, which factors into infrastructure costs.
When to Consider Switching
Pinot remains the right choice when your primary requirement is P90 latencies in the tens of milliseconds served directly to end users at very high concurrency. If that matches your workload profile, Pinot is hard to beat.
Consider moving away from Apache Pinot when your primary workload does not require real-time, low-latency, high-concurrency analytics on streaming data. Pinot's architecture is purpose-built for that scenario, and if your needs differ, other tools may be simpler to operate and more cost-effective.
Switch to ClickHouse if your workload is primarily batch-oriented analytical queries on large datasets. ClickHouse delivers exceptional query performance with less operational complexity for scan-heavy OLAP patterns, and its sizable community (over 46,000 GitHub stars) means extensive ecosystem support, numerous third-party integrations, and substantial operational knowledge available.
Switch to Trino or Starburst if you need to query data across multiple heterogeneous sources without centralizing it. Pinot requires data ingestion into its own segment format, while Trino queries data in place across your existing systems—a single SQL query can join S3 data with a MySQL table and a Kafka topic.
Switch to StarRocks if you need real-time analytics with complex multi-table joins or direct querying of data lake formats like Apache Iceberg and Delta Lake. StarRocks provides sub-second latency on join-heavy queries and supports real-time updates through its primary key table, with MySQL protocol compatibility for easier integration.
Switch to DuckDB if your analytics are single-machine, developer-focused, or part of a data science pipeline. DuckDB requires zero infrastructure, runs embedded in your application, and eliminates the operational overhead of managing a distributed cluster.
Switch to InfluxDB or Timescale if your workload is primarily time-series data (metrics, IoT, monitoring). These purpose-built time-series databases handle time-ordered writes and time-range queries more efficiently than a general-purpose OLAP engine like Pinot.
Switch to SingleStore if you need both transactional and analytical capabilities in a single database (HTAP workload) without maintaining separate systems for OLTP and OLAP.
Migration Considerations
Migrating away from Apache Pinot requires planning around several key dimensions: data format, ingestion pipelines, query compatibility, and operational changes.
Data migration: Pinot stores data in a proprietary segment format. You will need to export data via Pinot's query interface or re-read from original source systems like Kafka topics or S3 buckets and reingest into the target system. For tools like ClickHouse or StarRocks that also use columnar storage, the data modeling concepts translate relatively well, though table schemas and indexing strategies will differ. For clusters handling petabytes, expect migration to take days or weeks with parallel ingestion pipelines.
Streaming ingestion: If you rely on Pinot's native Kafka, Pulsar, or Kinesis connectors for real-time ingestion, you will need equivalent connectors in the target system. ClickHouse, StarRocks, and InfluxDB all support Kafka ingestion, but configuration and semantics—particularly around upserts and late-arriving data—vary. StarRocks's primary key table offers the most direct migration path for Pinot's upsert functionality, while ClickHouse handles upserts through its ReplacingMergeTree engine with asynchronous deduplication during background merges.
Query rewriting: Pinot uses a SQL-like query interface, but it has specific extensions and limitations. Queries will generally need review and adjustment for the target system's SQL dialect, particularly around time functions, aggregation behavior, and join support. If your application layer already works around Pinot's historical join limitations, migrating to ClickHouse or StarRocks (which support arbitrary joins natively) may simplify your query layer.
Index strategy: Pinot's StarTree index, which pre-aggregates data for common query patterns, has no direct equivalent in other systems. You will need to replace it with materialized views in ClickHouse or asynchronous materialized views in StarRocks. Other Pinot indexes (inverted, text, geospatial) have varying levels of support across target systems and require re-evaluation based on your actual query patterns.
Operational changes: Moving from Pinot's multi-component architecture to a different operational model requires updated deployment scripts, monitoring dashboards, and alerting rules. We recommend running both systems in parallel during transition, routing read traffic gradually to the new system while validating query result consistency and performance before fully cutting over.