The best cloud data warehouses depend on the workload as much as the SQL interface. This category covers scalable analytics and reporting systems across cloud data warehouses, OLAP databases, lakehouse platforms, table formats, time series databases, query engines, relational databases, graph databases, key value stores, document databases, and search engines. A buyer choosing between these product types is choosing where data is stored, how it is queried, and whether real-time ingestion, transactions, relationships, or operational workloads matter most.
How to Choose
Start with product type. A cloud data warehouse, such as Teradata, is for governed analytical workloads across warehouse and lake environments. An OLAP database such as Apache Druid is designed for fast analytical queries over large, event-oriented data sets. A lakehouse platform such as Databricks combines data-lake storage with warehouse-style analytics and adds engineering and AI workflows.
Table formats solve a different problem: Apache Hudi brings ACID transactions, updates, incremental processing, and time travel to data stored in a lake. Query engines such as Amazon Athena query data where it resides—in Athena’s case, Amazon S3—without infrastructure setup. A time series database such as InfluxDB is purpose-built for timestamped operational data, while Neo4j models connected data as nodes and relationships. MySQL is a relational database for transactional application data, with HeatWave adding analytics and machine learning capabilities.
Then evaluate the architecture and operating model:
-
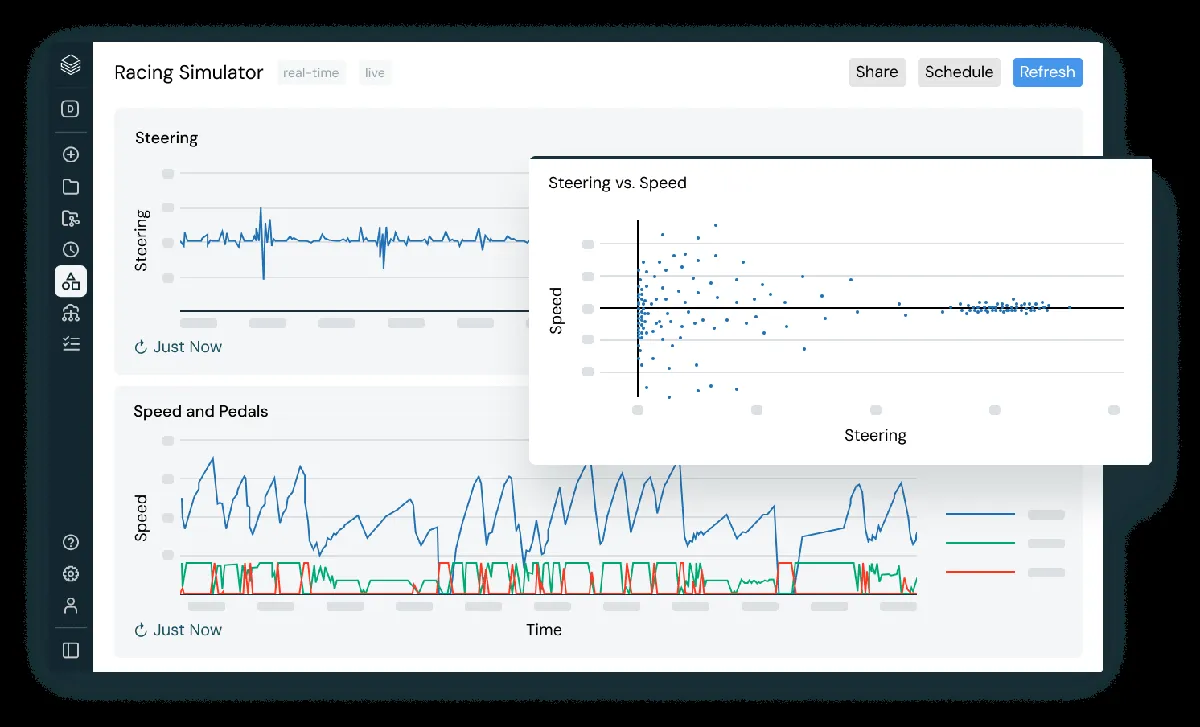
For streaming analytical data, assess ingestion and freshness. Apache Druid supports native Kafka and Kinesis ingestion and can query data on arrival at millions of events per second. Apache Hudi is a better fit when the core requirement is mutable data-lake tables with incremental processing and automatic clustering or compaction.
-
For data-science and engineering workflows, evaluate the programming environment alongside SQL. Databricks supports SQL, Python, Scala, and R in notebooks and jobs, with managed Apache Spark, managed MLflow, model serving, and Mosaic AI services. That breadth is useful when one team owns both production pipelines and model development.
-
For query-cost control, examine what drives billing. Amazon Athena charges $5 per TB scanned, with a 10 MB minimum per query, so table layout and data scanned directly affect cost. Its capacity reservations cost $0.30 per DPU-hour, billed per minute with a one-minute minimum.
-
For enterprise deployment requirements, assess where the platform can run and how capacity is purchased. Teradata Vantage supports public-cloud, hybrid, and multi-cloud environments. Its Fixed + Flex model combines committed baseline capacity with on-demand capacity, while listed storage starts at $23 per TB per month.
-
For relationship-heavy analysis, choose a graph model deliberately. Neo4j stores data as nodes and relationships rather than tables and rows, supports ACID transactions, and offers a dedicated query language. It is not a replacement for every reporting warehouse; it is for questions where traversing connections is central.
Top Tools
Databricks
Databricks is a lakehouse platform that combines data-lake and warehouse capabilities on cloud object storage. Delta Lake provides ACID transactions, schema evolution, and time travel on Parquet files, while Databricks SQL supplies an endpoint layer for BI workloads with Delta Engine optimizations. Its collaborative workspace, Delta Live Tables, Spark integration, and integrated ML tooling make it a broad engineering and AI environment.
Best suited for: Data engineering and data science teams that need shared SQL, Spark, pipeline, and ML workflows on cloud data.
Pricing: Paid — Consumption-based: billed per Databricks Unit (DBU) per second on top of your own cloud compute and storage charges, with no up-front cost and committed-use discounts available. Free Edition is available at no cost.
The main trade-off is that billing includes DBUs plus separate cloud compute and storage charges, and published per-DBU rates are not machine-readable from the vendor pricing page. Dremio is an alternative when the requirement is a reviewed direct alternative rather than Databricks’ integrated notebooks, Spark, MLflow, and Delta Live Tables environment.
Teradata
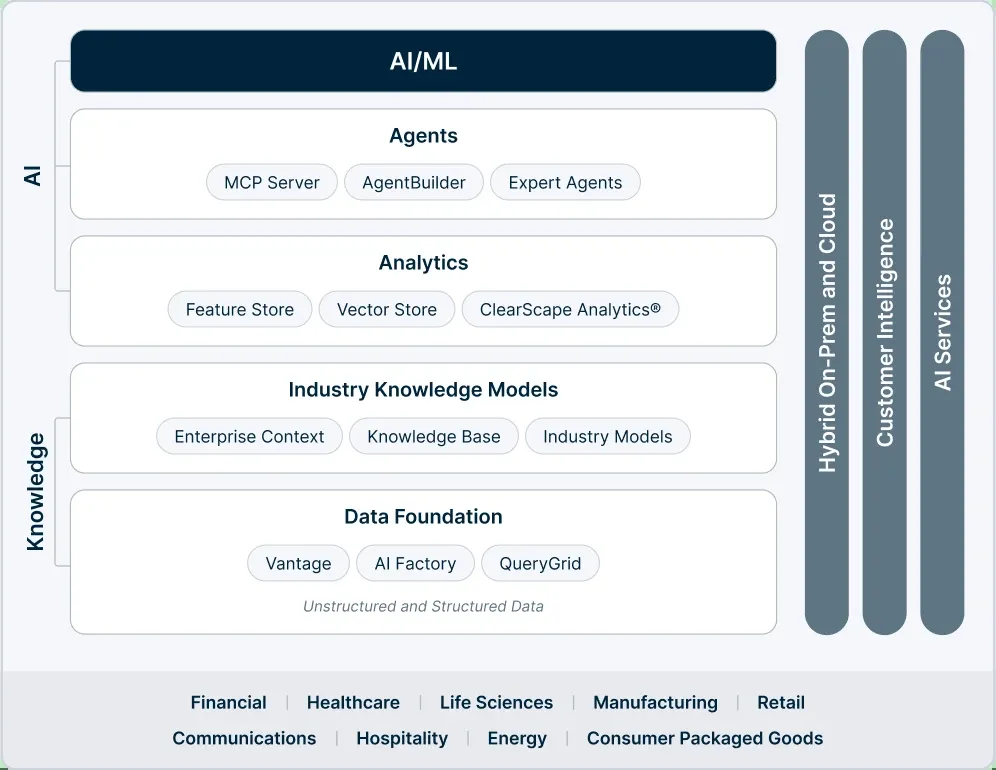
Teradata Vantage is a cloud data warehouse and analytics platform that unifies data lakes, data warehouses, analytics, and new data sources and types. It supports public-cloud deployments on AWS, Azure, and GCP as well as hybrid multi-cloud environments, and includes data fabric, ClearScape Analytics, in-database analytics, Bring Your Own LLM, and an Enterprise Vector Store.
Best suited for: Enterprises that require warehouse analytics across public-cloud and hybrid multi-cloud environments.
Pricing: Usage-Based — Teradata prices on a Fixed + Flex model in Teradata Units: committed baseline capacity plus on-demand capacity billed only for use. Storage starts at $23 per TB per month and packages start at $0.22 per minute, varying by cloud and region.
The trade-off is pricing variation by cloud and region, plus the need to plan both committed and flex capacity. Amazon Redshift is a reviewed alternative for warehouse workloads, while Teradata distinguishes itself here with hybrid multi-cloud deployment and in-database analytics.
Apache Druid
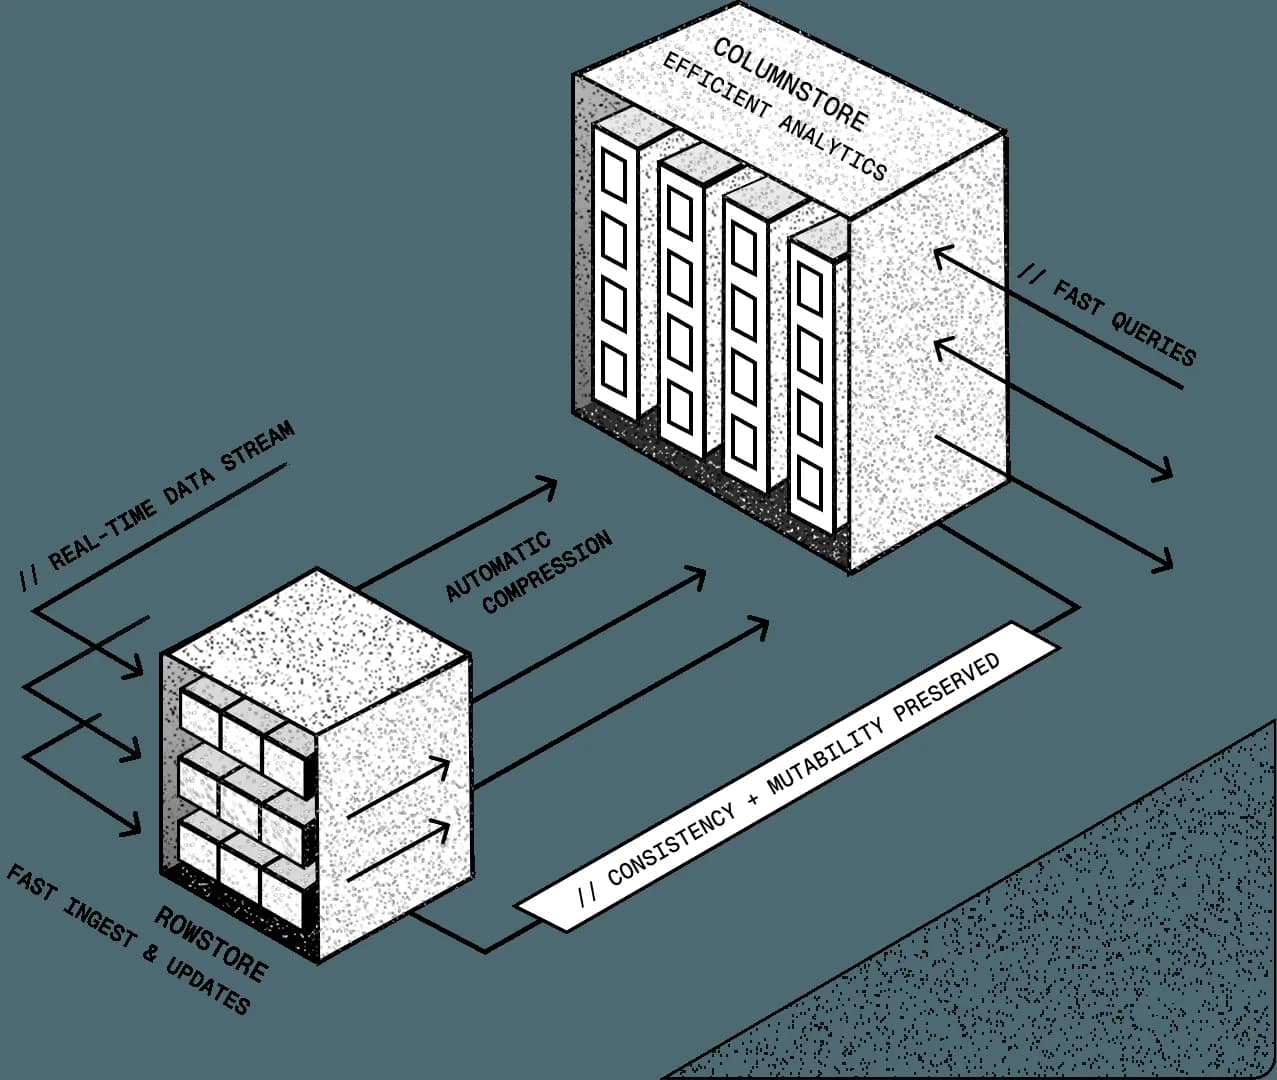
Apache Druid is an open-source OLAP database built for high-performance real-time analytics. Its scatter/gather execution supports sub-second queries on high-cardinality data sets with billions to trillions of rows, and its columnar storage uses automatic time-indexing, dictionary encoding, and type-aware compression. Native Kafka and Kinesis integration enables query-on-arrival ingestion.
Best suited for: Teams building real-time analytics over high-cardinality event data and requiring low-latency SQL access.
Pricing: Open Source — Free and open-source under the Apache License 2.0.
The trade-off is that it is a specialized real-time analytics datastore rather than a general-purpose transactional database. ClickHouse is a reviewed alternative; Druid differentiates itself with native Kafka and Kinesis ingestion, automatic time-indexing, and configurable workload tiering.
Apache Hudi
Apache Hudi is an open table format and data-lakehouse platform that brings database behavior to cloud data lakes. It supports ACID transactions, mutability across workload shapes, time travel, record-level indexing, and an incremental processing framework for low-latency analytics. Automatic table services handle clustering and compaction.
Best suited for: Data-lake teams that need upserts, incremental processing, and historical analysis on cloud storage.
Pricing: Open Source — Apache Hudi is free and open source under the Apache 2.0 license.
The trade-off is operational responsibility: running Hudi requires compute such as Spark or Flink plus object storage. Apache Iceberg is a reviewed alternative; Hudi is differentiated here by its stated focus on incremental processing, updates, and record-level indexing.
InfluxDB
InfluxDB is a time series database for real-time visibility into stacks, sensors, and systems. It is available as open source, a cloud DBaaS option, or an Enterprise subscription, and provides real-time querying with a Last Value Cache and high-volume ingestion with unlimited cardinality. Its cloud-native, diskless architecture is oriented toward operational time series data.
Best suited for: Observability and sensor-data teams that need real-time analysis of timestamped metrics and events.
Pricing: Open Source — InfluxDB Cloud Serverless charges $0.0025 per MB of data in, $0.012 per 100 query executions, $0.002 per GB-hour of storage, and $0.09 per GB of data out.
The trade-off is that these cloud charges are tied to ingestion, queries, storage, and data transfer rather than a single warehouse capacity measure. TimescaleDB is a reviewed alternative; InfluxDB distinguishes itself with its Last Value Cache and diskless cloud-native architecture.
Neo4j
Neo4j is a graph database that stores data as nodes and relationships rather than tables and rows. It supports complex graph queries, ACID transactions, cross-platform support, and a dedicated query language. Its stated use cases include fraud detection, knowledge graphs, and recommendation engines.
Best suited for: Teams whose analytical or application questions depend on traversing relationships across connected data.
Pricing: Freemium — AuraDB Free is $0. AuraDB Professional starts at $0.09 per GB per hour with a minimum 1 GB instance, and AuraDB Business Critical starts at $0.20 per GB per hour with a minimum 2 GB instance. Storage, IO, backup, and data transfer are included.
The trade-off is that graph modeling is purpose-built for connected-data questions, not a default replacement for tabular warehouse reporting. No reviewed direct alternative is listed in the available data.
Amazon Athena
Amazon Athena is a serverless query engine for interactive analytics over data in Amazon S3. It uses standard SQL to analyze data where it lives and requires no infrastructure setup. It is intended for petabyte-scale analysis, with charges tied to data scanned or reserved capacity.
Best suited for: AWS teams that want serverless SQL analysis of data already stored in Amazon S3.
Pricing: Usage-Based — SQL queries cost $5 per TB of data scanned, rounded up to the nearest MB with a 10 MB minimum per query. DDL statements and failed queries are free; canceled queries are billed for data scanned until cancellation. Capacity Reservations cost $0.30 per DPU-hour, billed per minute with a one-minute minimum.
The trade-off is that scan volume drives query cost, so teams need to monitor data scanned. No reviewed direct alternative is listed in the available data.
MySQL
MySQL is an open-source relational database management system for real-time transactional applications. MySQL HeatWave adds integrated analytics and machine learning, while MySQL AI adds integrated machine learning and generative AI. Its core positioning remains a relational database with high availability and data-security capabilities.
Best suited for: Application teams that need an open-source relational database for transactional workloads and may use HeatWave analytics.
Pricing: Open Source — MySQL Community Edition is open source under the GNU General Public License version 2 (GPLv2).
The trade-off is that its central role is transactional relational data rather than a dedicated analytical warehouse architecture. PostgreSQL is a reviewed alternative; MySQL differentiates itself here through the stated HeatWave and MySQL AI capabilities.
Comparison Table
The table compares one representative tool for each product type covered in the editorial profiles. Pricing reflects the available product data and should be validated against the vendor before procurement, especially where usage and regional deployment affect the bill.
| Tool | Type | Best For | Pricing | Key Strength |
|---|---|---|---|---|
| Databricks | lakehouse platform | Shared data engineering, BI, and ML workflows | Paid; consumption-based DBUs plus cloud compute and storage | Delta Lake ACID transactions, schema evolution, and time travel |
| Teradata | cloud data warehouse | Hybrid multi-cloud enterprise analytics | Usage-Based; storage starts at $23 per TB per month | In-database analytics and hybrid multi-cloud deployment |
| Apache Druid | olap database | Real-time, high-cardinality event analytics | Open Source | Sub-second scatter/gather queries and Kafka/Kinesis ingestion |
| Apache Hudi | table format | Mutable data-lake tables and incremental pipelines | Open Source | ACID guarantees, upserts, indexing, clustering, and compaction |
| InfluxDB | time series database | Observability and sensor data | Open Source; cloud usage rates apply | Last Value Cache and unlimited-cardinality ingestion |
| Neo4j | graph database | Fraud, knowledge graphs, and recommendations | Freemium; AuraDB Professional from $0.09 per GB per hour | Native nodes-and-relationships data model |
| Amazon Athena | query engine | Serverless Amazon S3 analytics | Usage-Based; $5 per TB scanned | Standard SQL without infrastructure setup |
| MySQL | relational database | Transactional applications | Open Source | Relational database with HeatWave analytics and ML |
Our Methodology
We assess cloud data warehouses tools using available vendor documentation, published pricing information, documented product capabilities, public review signals, and editorial comparison of the architecture each product serves. We look for concrete evidence such as Apache Druid’s Kafka and Kinesis ingestion, Databricks’ Delta Lake capabilities, or Athena’s published scan-based pricing rather than generalized vendor claims.
Public ratings and review counts can help identify recurring implementation themes: for example, the available data records Databricks at 8.8/10 from 109 reviews and MySQL at 8.3/10 from 990 reviews. Those are public signals, not proof of enterprise adoption, deployment scale, security posture, or suitability for a particular workload.
We also distinguish open-source availability from operational cost. Apache Hudi and Apache Druid have no software license cost under Apache 2.0, but operating them still requires infrastructure. Similarly, usage-based products require workload-specific cost modeling. Where the source data does not document a feature, integration, or price, we leave it out rather than infer it.
Frequently Asked Questions
How do I choose between a lakehouse platform and a cloud data warehouse?
Choose a lakehouse platform such as Databricks when data engineering, notebooks, Spark, SQL, and ML workflows need to operate in one environment. Databricks supports SQL, Python, Scala, and R, and Delta Lake adds ACID transactions and time travel on Parquet files in cloud storage. Choose a cloud data warehouse such as Teradata when the requirement is governed analytics across public-cloud and hybrid multi-cloud environments. Teradata Vantage also provides in-database analytics and data-fabric capabilities.
When is Amazon Athena a better fit than a warehouse?
Amazon Athena is appropriate when data is in Amazon S3 and the team wants serverless SQL without provisioning infrastructure. Its $5 per TB scanned pricing means it is important to understand scan volume; queries have a 10 MB minimum. Capacity Reservations are available at $0.30 per DPU-hour for steadier reserved query capacity. A warehouse platform is a different choice when its broader managed analytics environment is required.
Should we use Apache Druid or InfluxDB for real-time data?
Use Apache Druid for real-time analytical queries over high-cardinality event data, especially when native Kafka or Kinesis ingestion is part of the architecture. It supports sub-second queries across data sets with billions to trillions of rows. Use InfluxDB when the data is fundamentally time series from systems, stacks, or sensors and real-time visibility is the goal. InfluxDB provides a Last Value Cache and high-volume ingestion with unlimited cardinality.
Why use a graph database alongside tabular analytics?
Neo4j is useful when relationships are the primary object of analysis, such as fraud paths, knowledge graphs, or recommendation connections. It stores nodes and relationships directly and supports ACID transactions and graph queries. Tabular systems remain appropriate for many reporting and aggregation workloads. The decision is driven by the question being asked: relationship traversal calls for a graph model, while broad SQL reporting may call for a warehouse, lakehouse, or query engine.