Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What the Delta Lake project states |
|---|---|
License | Open source under the Apache License 2.0 |
How it is installed | As connectors and libraries for the engine you run, such as the Apache Spark connector, Delta Standalone for Scala and Java projects, and the Delta Rust API with Python and Ruby bindings; a Quick Start Guide covers Scala, Java and Python |
Where it runs | With any query engine on any cloud, on-prem, or locally, in the project's words |
Compute engines | Spark, PrestoDB, Flink, Trino, Hive, Snowflake, Google BigQuery, Athena, Redshift, Databricks and Azure Fabric |
Language APIs | Scala, Java, Rust, Ruby and Python |
Latest announced release | Delta Lake 4.4.0 on Apache Spark 4.2.0 |
Governance | Independent project, a sub-project of the Linux Foundation Projects since 2019, not controlled by any single company |
Support | Community channels: GitHub Issues for reported issues, a public Slack channel and a mailing list |
Our take
Delta Lake fits a team that wants versioned, transactional tables in storage it controls, under an open license and a project no single company controls. Choose it if the engines that write your tables have write support and your storage meets the project's requirements; check both before you commit.
Evaluate Delta Lake
Comparisons
Where it stands out
Serializable transactions. Delta Lake ensures serializability for concurrent reads and writes, which the project calls the strongest level of isolation. Readers and writers can share one table without coordinating by hand.
Time travel and audit history. You can access or revert to earlier versions of data for audits, rollbacks or reproducing results, and the log records all change details as an audit trail.
Schema enforcement and evolution. The project positions these checks as a way to prevent bad data from causing data corruption.
One table for batch and streaming. Exactly-once semantics cover ingestion, backfill and interactive queries.
Merge, update and delete. SQL, Scala/Java and Python APIs support these operations on datasets.
Scalable metadata. The project says Delta Lake handles petabyte-scale tables with billions of partitions and files.
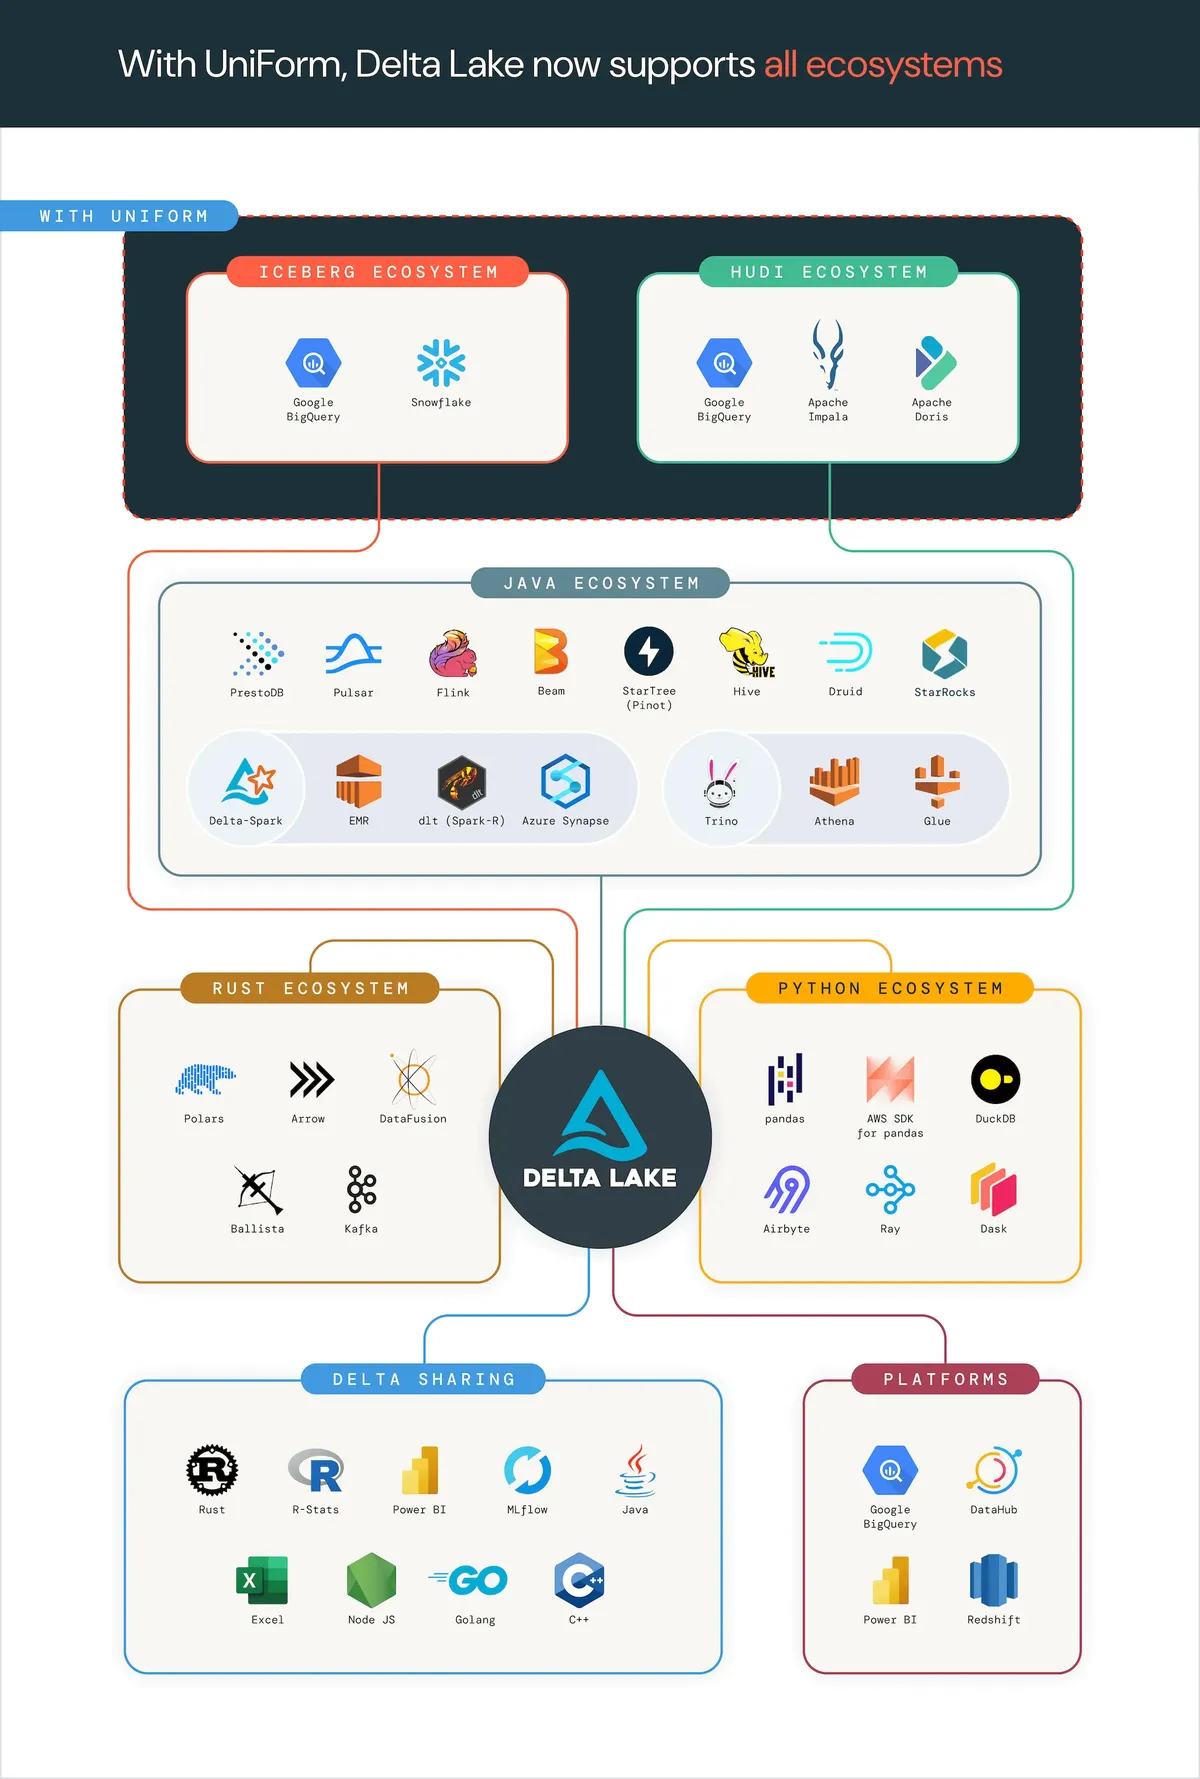
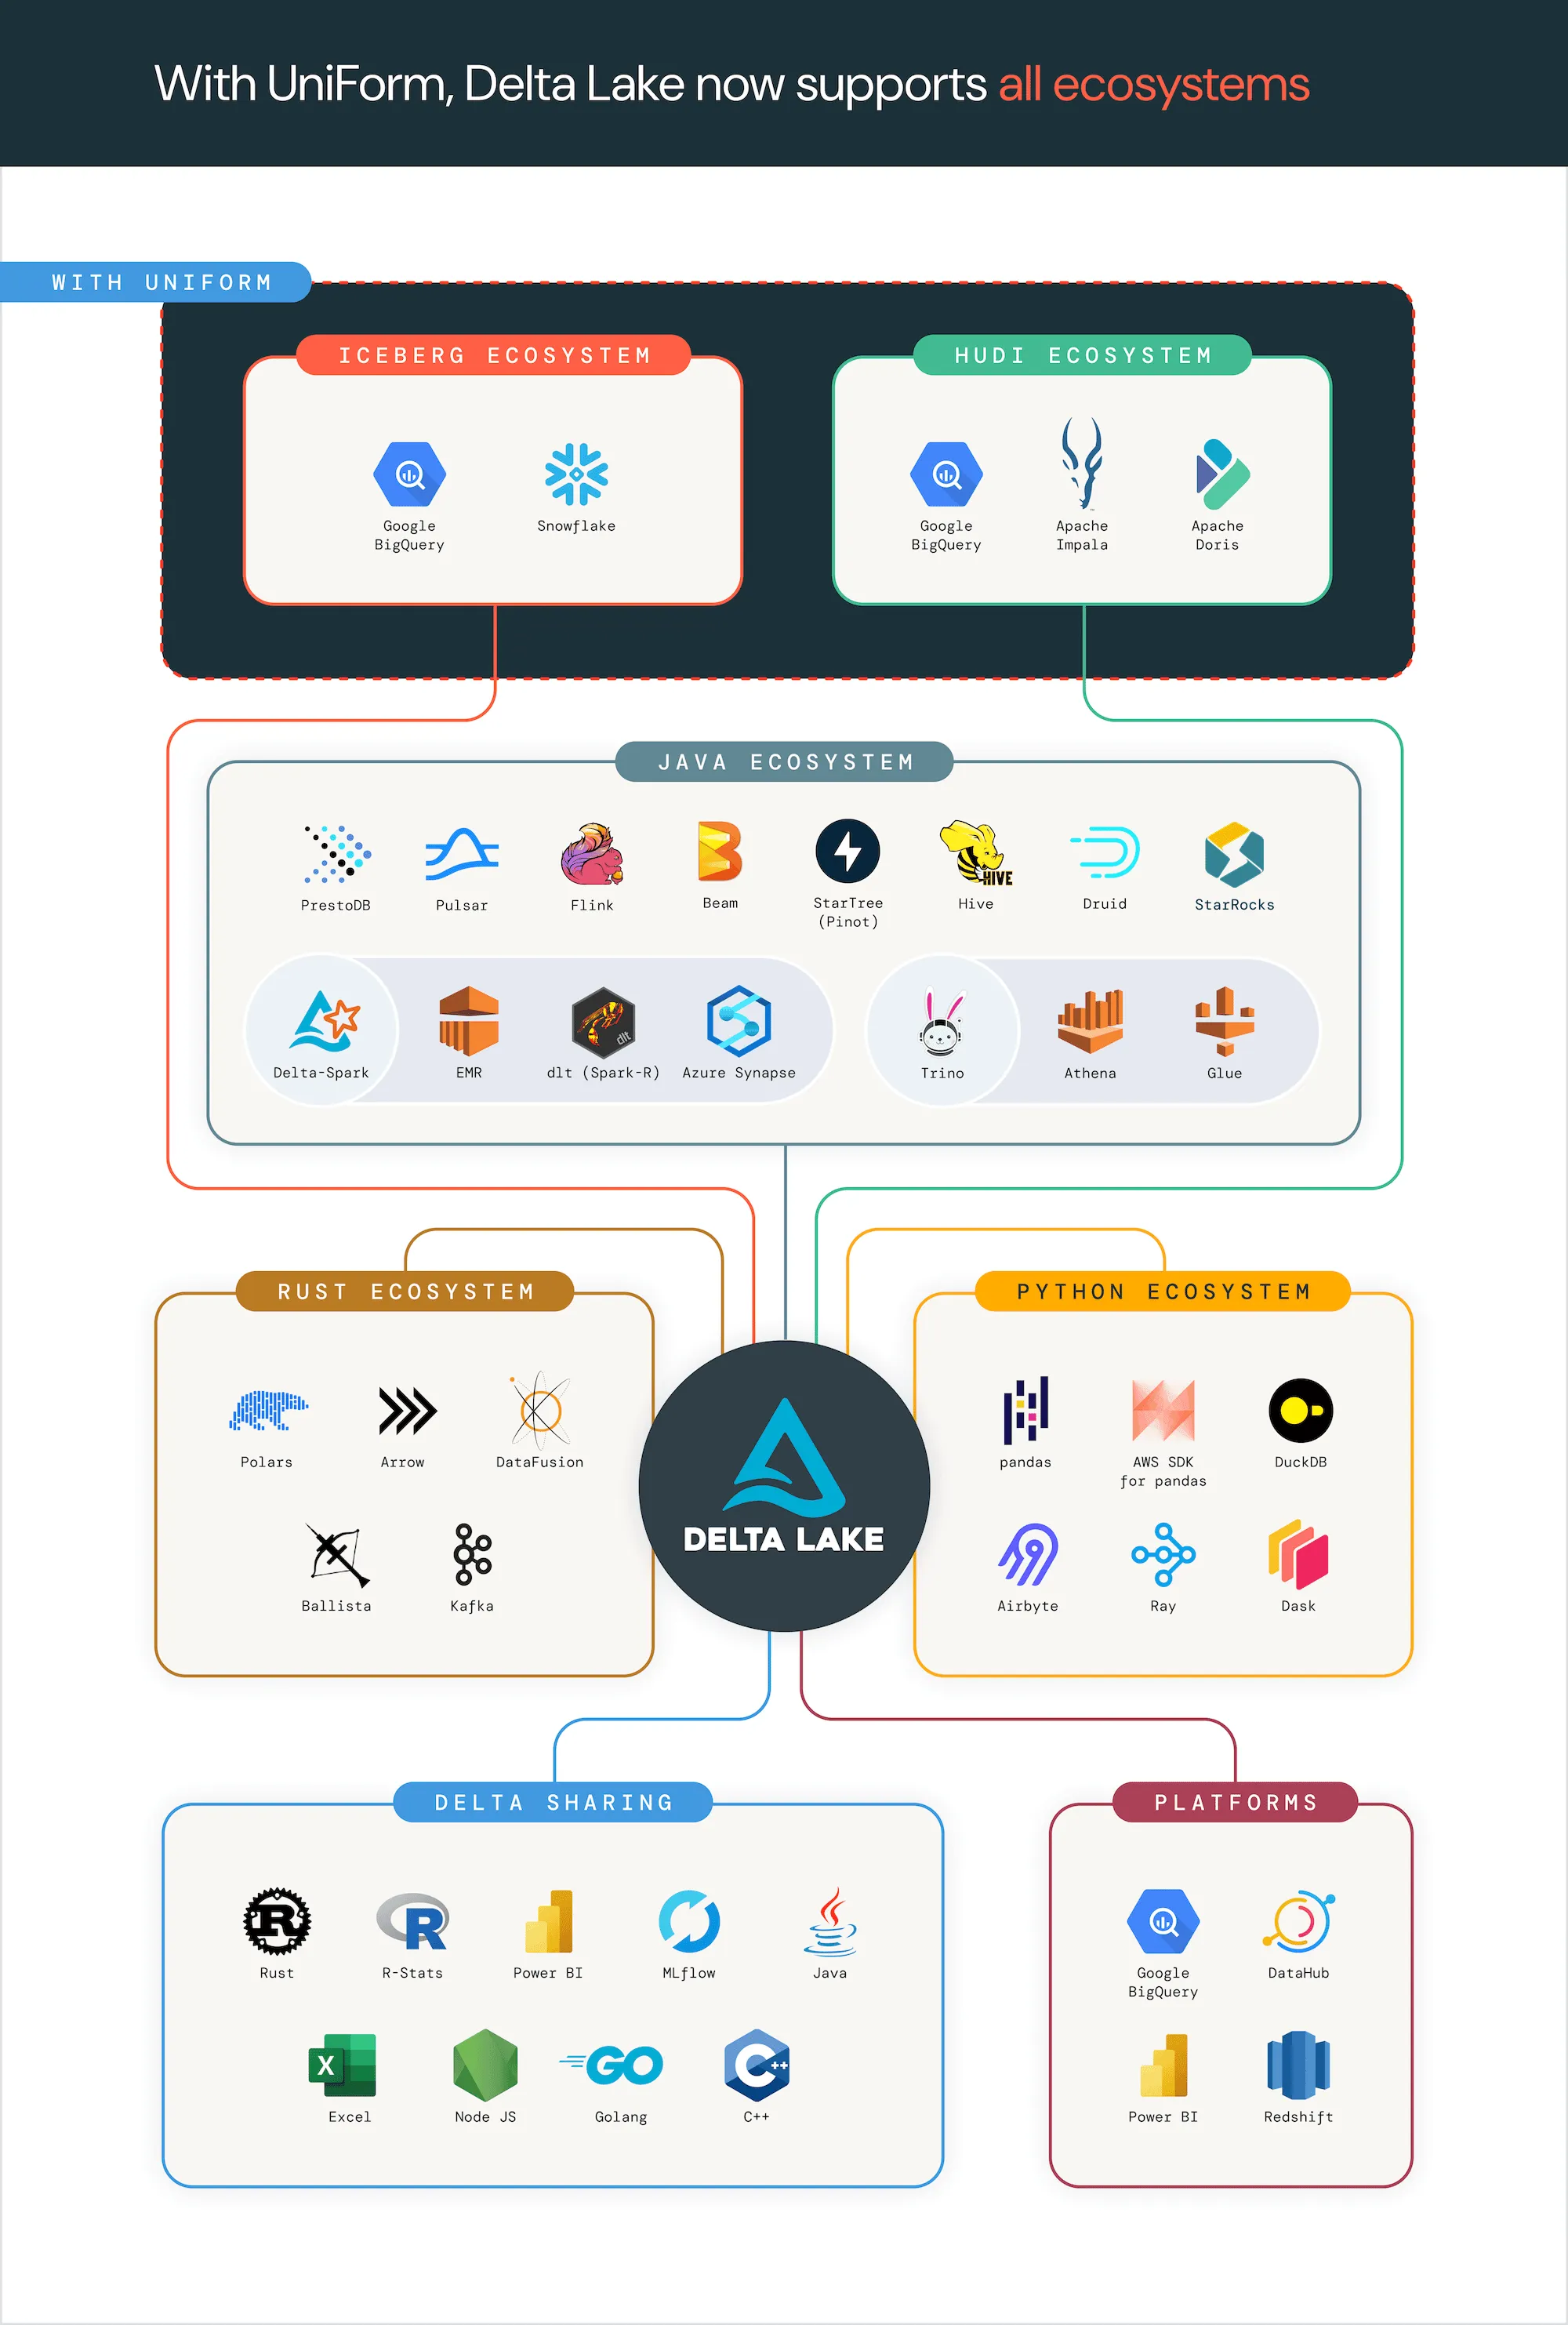
UniForm interoperability. With Delta Universal Format (UniForm), Iceberg and Hudi clients can read Delta tables, so readers built on those formats can still read your Delta tables.
Broad contributor base. The project says more than 190 developers from over 70 organizations support it, and that it is battle tested in over 10,000 production environments.
Product screenshot
Trade-offs to weigh
Engine support is not the same everywhere. The Spark and Trino connectors read and write; the Flink connector writes and is in Preview; the PrestoDB and Hive connectors only read. A team that writes from several engines needs to check each path.
Guarantees depend on your storage. Delta Lake's ACID guarantees rely on the storage system providing atomic visibility, mutual exclusion (only one writer can create or rename a file at the final destination) and consistent listing. Review the storage configuration documentation for your object store.
Forward compatibility can break. The project guarantees that newer versions of Delta Lake can always read tables written by older versions, but an older version may not read a table produced by a newer one when new protocol features are used. Mixed-version estates need upgrade planning.
Only documented APIs are stable. Classes outside the API docs are internal and may change across releases; Spark reader and writer options stay stable only within a major release.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
377 GitHub commits 90d9.1k GitHub stars0 vulnerabilities across 1 package
See all signals from 7 sources
PyPI · delta-spark@4.4.1
Alternatives
Apache Iceberg and Apache Hudi are the lakehouse storage systems that the project's own whitepapers compare with Delta Lake. Because UniForm lets Iceberg and Hudi clients read Delta tables, a mixed estate can keep Delta as the written format while those readers stay in use.
Alternatives to Delta Lake
The reviewed substitutes for Delta Lake among the open table formats, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Apache Hudi
- Apache Hudi and Delta Lake are open table formats that add ACID transactions and time travel to files on a data lake. Hudi leans toward streaming ingestion, with upserts, incremental processing and record-level indexes. Delta Lake started at Databricks and is the native format there, while engines such as Spark, Trino and Flink can also read it.Applies to: Choosing between two products of the same kind for one job.
- Apache Iceberg
- To get ACID tables, schema evolution and time travel on object storage, a team can adopt Apache Iceberg or Delta Lake. Delta Lake comes from Databricks and works most smoothly in Spark and Databricks. Iceberg is an Apache project with broad support across engines such as Trino, Flink and Snowflake.Applies to: Choosing between two products of the same kind for one job.