Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Elastic states |
|---|---|
Deployment | Self-managed (download and install, Docker, Helm Charts, Elastic Cloud on Kubernetes or Elastic Cloud Enterprise), Elastic Cloud Hosted on AWS, Google Cloud and Azure, or Elastic Cloud Serverless |
Who runs the cluster | Hosted: you keep control over hardware configuration, cluster size, node count and versions. Serverless: Elastic manages all of these and scales up and down with search and indexing load. Self-managed: you control location, hardware, orchestration, cluster size, node count and versions. |
Clouds and regions | Hosted: AWS, GCP, Azure, Alibaba and FedRamp, with 60 regions across AWS, Azure and GCP. Serverless: generally available in AWS, GCP and Azure. Self-managed: on-prem or in private or public cloud. |
License | The GitHub repository describes it as free and open source. The local start-local setup comes with a one-month trial license with all Elastic features, then reverts to Free and open - Basic. |
Our take
Elasticsearch fits teams that want search, vector retrieval and log or security analytics in one engine, and want to choose how much of the cluster they run themselves. If you only need a small search box and no one can own the cluster or relevance tuning, its breadth adds work you may not need.
Evaluate Elasticsearch
Popular comparisons
See all 6 Elasticsearch comparisons
Where it stands out
Keyword, vector and hybrid search in one engine. Elastic lists full-text search, semantic search with Jina models, and hybrid search with filters, ranking and reranking. RAG and product-search teams can keep both retrieval styles in one system.
Built-in failover. Clusters keep primary and replica shards; when a node leaves, a replica takes its place. Cross-cluster replication (Platinum and above on Cloud Hosted) can keep a secondary cluster as a hot backup.
Storage tiers for long retention. Data can move from a hot tier on local disks to searchable snapshots on object storage. On Cloud Hosted, using them in cold and frozen tiers needs the Enterprise level.
Wide ecosystem. Elastic cites 350+ integrations and clients for Java, Python, Go and more. JDBC and ODBC interfaces let BI tools such as Tableau Desktop and Microsoft Power BI Desktop use Elasticsearch SQL.
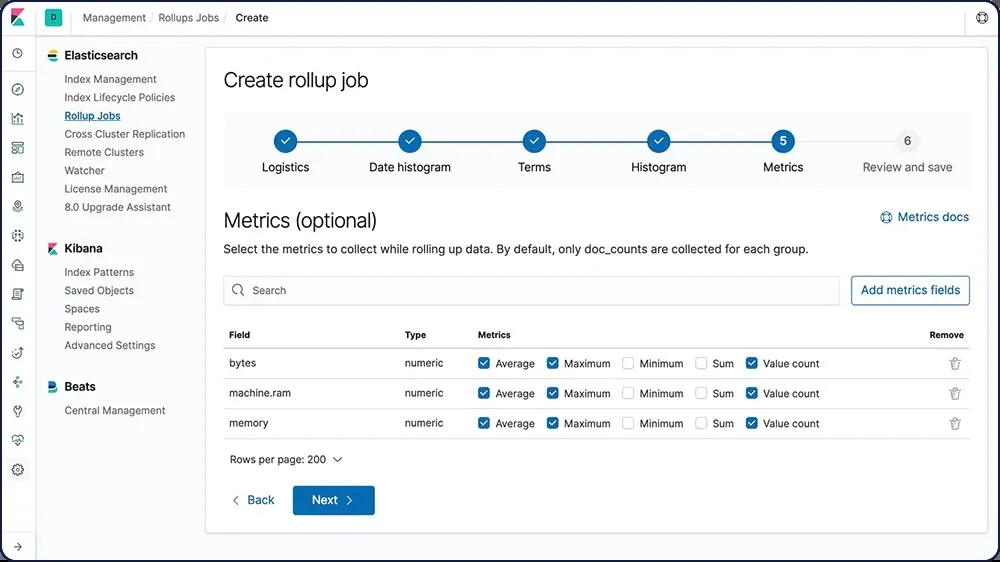
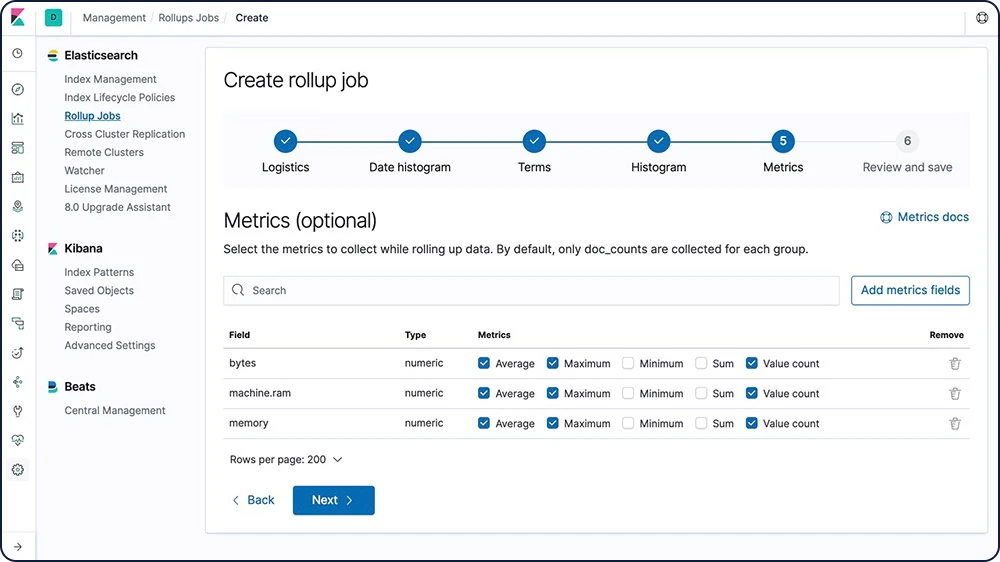
Product screenshot
Trade-offs to weigh
The Hosted level sets your features, not only your size. Each level adds features and support to the one below, so pick the level before sizing the cluster.
Serverless meters enriched data. Ingest and retention are metered on the uncompressed, normalized, fully enriched volume you ingest. Elastic warns this is much higher than the raw or compressed size.
Serverless search keeps a paid baseline. A baseline of search resources stays provisioned; idle periods are billed at a reduced rate. Switching Search Power from Performant (default) to On-demand lowers that baseline but makes query latency more variable.
Serverless is not yet the full product. Elastic lists most solution and platform capabilities, with traffic filtering and bring your own key still upcoming, in select cloud provider regions.
Self-managed means you own uptime and capacity. Elastic's uptime SLA does not apply because you run the infrastructure, and storage-based autoscaling is available only in ECE and ECK.
Pricing and plan conditions
Elastic bills each path on a different basis. Cloud Hosted is resource-based and Serverless is usage-based; both are pay as you go (monthly) or prepaid. Self-managed subscriptions are license-based, on the number of nodes and used RAM. Each Hosted "as low as" price below is based on a cloud production config with 120 GB storage in 2 zones, with instance type usage-based pricing.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Standard | As low as $99 per month | ES|QL, monitoring on by default with AutoOps. Limited Support: web-based, 2 support contacts, 3-business-day target response time (Elastic Cloud platform only). |
Gold | As low as $114 per month | Everything in Standard plus reporting, third-party alerting actions, Watcher, multi-stack monitoring and Enterprise Search. Base Support: business hours, phone and web, 6 support contacts, urgent target 4 business hours. |
Platinum | As low as $131 per month | Everything in Gold plus advanced Elastic Stack security features, machine learning (anomaly detection, supervised learning), cross-cluster replication, and semantic and vector search with ELSER and e5 models on Elastic ML nodes. Enhanced Support: 24/7/365, 8 support contacts, urgent target 1 hour. 99.95% monthly uptime SLA. |
Enterprise | As low as $184 per month | Everything in Platinum plus searchable snapshots in cold and frozen tiers, Elastic Maps Server, synthetic _source for storage reduction, GPU inference with Elastic Inference Service (additional charges apply), Agent Builder and Elastic Cloud SAML SSO. Premium Support: 24/7/365, urgent target 30 minutes. 99.95% monthly uptime SLA. |
Elasticsearch Serverless charges separately for compute and storage. Compute is in Virtual Compute Units (VCUs with 1GB RAM) of three types: ingest, search and machine learning. Storage is measured in GB. Managed LLM and Jina AI model usage is charged per million tokens. Elastic's illustrative examples: a dev environment with 2GB searchable data, 1% ingest utilization (15 minutes per day) and 8% search utilization (2 hours per day) is $24/month On-demand or $27/month Performant. A prod environment with 20GB searchable data, 5% ingest utilization (1 hour per day) and 33% search utilization (8 hours per day) is $190/month On-demand or $210/month Performant. Elastic says actual costs may vary.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Subscription level | Support charge | Support level |
|---|---|---|
Standard | Included | Limited |
Gold | 5% of charge | Base |
Platinum | 10% of charge | Enhanced |
Enterprise | 15% of charge | Premium |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
4.1k GitHub commits 90d78.5k GitHub stars0 vulnerabilities across 2 packagesOpenSSF score 6.0/10
See all signals from 10 sources
npm · @elastic/elasticsearch@9.5.1 · PyPI · elasticsearch@9.5.1
Alternatives to Elasticsearch
The reviewed substitutes for Elasticsearch among the search engines, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- MongoDB
- Choose this if you already use MongoDB for your application data and want integrated search without maintaining a separate Elasticsearch cluster.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
- ClickHouse
- Choose this if your primary workload is log analytics or dashboards over structured data rather than free-text search.Applies to: Whether the workload is aggregation over events or search and relevance over documents.
- Datadog
- Datadog and Elasticsearch can both store and query log data at scale. Elasticsearch is a distributed search and analytics engine, built on Apache Lucene, that a team can run and tune itself, while Datadog is a managed monitoring service that keeps logs beside infrastructure and application metrics, so the decision is whether logs live in a system you operate or a platform you buy.Applies to: Where log data is stored and searched, and whether that system is operated or bought.
- Imply Cloud
- A columnar analytical database and a search engine both answer questions over large volumes, one by aggregation and one by search and relevance ranking. The overlap on log and event analytics is real, which is why they are compared, and the decision follows whether the workload is aggregation or retrieval.Applies to: Whether the workload is aggregation over events or search and relevance over documents.
- Grafana Loki
- Loki indexes only the labels on a log stream and keeps the log bodies as compressed chunks in object storage, which is what makes it cheap to run at scale and what makes full-text search across bodies slower and more compute-hungry at query time. Every pair below turns on that one design choice. Elasticsearch is the direct counter-design: it full-text indexes the log bodies, which is why reviewers recommend it for fast search over unstructured logs and why it costs more to store and operate at the same volume. A team picks the index strategy, and the rest follows.
- Splunk
- Elasticsearch and Splunk both index log and machine data at scale and give teams search, charts and alerts over it. Elasticsearch is a distributed search engine built on Apache Lucene that a team can operate itself, while Splunk is a commercial platform with its own search language, dashboards and security tools, so the choice is between operating a system and buying one.Applies to: Where log data is stored and searched, and whether that system is operated or bought.
- Typesense
- Both serve keyword and faceted search; Typesense trades Elasticsearch's breadth for typo-tolerant search-as-you-type and simpler operation.Applies to: Keyword and faceted search behind a product's search box.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Neo4j
- A graph database and a search engine answer different questions, and the documented pattern uses both: Elasticsearch for full-text and vector search over documents, Neo4j for relationship traversal and knowledge graphs. Published guides cover graph-powered search built on the pair rather than a choice between them.Applies to: Whether connected data needs a graph store, or whether search over documents is enough.
Head to head
See detailed alternatives analysis
Organizations looking for Elasticsearch alternatives typically need a different balance of search capability, analytics performance, and operational cost. Elasticsearch dominates full-text search with an 8.7/10 user rating across 217 reviews and 76,550 GitHub stars, but its resource-heavy architecture, complex cluster management, and tiered pricing starting at $99/month push many teams toward specialized tools. Whether you need faster columnar analytics, lower operational overhead, or purpose-built time-series storage, several strong alternatives exist in 2026.
Top Alternatives Overview
ClickHouse is a column-oriented OLAP database built for real-time analytical reports using SQL. It handles trillions of rows and petabytes of data with linear scalability, and its open-source core means zero licensing cost. ClickHouse Cloud offers a serverless option for teams that want managed infrastructure. Where Elasticsearch excels at full-text search, ClickHouse crushes it on aggregation-heavy analytical queries with 10-100x better performance on large scans. Choose this if your primary workload is log analytics or dashboards over structured data rather than free-text search.
Apache Druid is an open-source distributed data store that merges ideas from data warehouses, time-series databases, and search systems. It ingests streaming data from Kafka and delivers sub-second OLAP queries at high concurrency. Druid uses a segment-based storage format with automatic tiering from hot to historical nodes. Licensed under Apache 2.0, it costs nothing to run self-hosted. Choose this if you need real-time ingestion from event streams combined with sub-second slice-and-dice analytics.
MongoDB is a document-oriented NoSQL database with Atlas search capabilities built on Apache Lucene, the same foundation as Elasticsearch. MongoDB Atlas starts free and scales with dedicated clusters from $0.08/hour. With Atlas Search, MongoDB combines document storage and full-text search in a single platform, eliminating the need to sync data between a primary database and a separate search engine. Choose this if you already use MongoDB for your application data and want integrated search without maintaining a separate Elasticsearch cluster.
Apache Pinot is a real-time distributed OLAP datastore powering user-facing analytics at LinkedIn, Uber, and Stripe. It delivers consistent sub-second query latency even at millions of events per second ingestion rates. Pinot is fully open source under Apache License 2.0 and designed specifically for low-latency analytics on freshly ingested data. Choose this if you build customer-facing analytics dashboards that must respond in under a second at high concurrency.
ClickHouse and Firebolt both target the analytical query space, but Firebolt differentiates with its proprietary F3 storage format and specialized indexes that deliver sub-second performance on terabyte-scale datasets. Firebolt offers a free self-hosted Core edition and a managed cloud service billed per second, where one Small node costs $0.92 per hour. Its Postgres-compatible SQL, ACID transactions, and native Iceberg support make it a modern drop-in for analytical workloads. Choose Firebolt if you need extreme low-latency analytics for customer-facing applications and want a fully managed cloud experience.
InfluxDB is a purpose-built time-series database from InfluxData, available as open-source Community Edition or as a cloud DBaaS starting at $250/month. It stores, queries, and visualizes time-stamped data with native support for downsampling, retention policies, and continuous queries. Where Elasticsearch requires careful index lifecycle management for time-series data, InfluxDB handles it natively. Choose this if your workload is predominantly metrics, IoT sensor data, or infrastructure monitoring.
Architecture and Approach Comparison
Elasticsearch uses an inverted index architecture built on Apache Lucene, which makes it unbeatable for full-text search but expensive for pure analytical aggregations. Every document is indexed at write time, creating significant storage overhead and memory consumption. Elasticsearch clusters require careful shard management, replica tuning, and JVM heap sizing to remain stable.
ClickHouse and Apache Druid take a columnar storage approach. ClickHouse stores data in compressed column files and uses vectorized query execution, meaning analytical queries scan only the columns they need. Druid adds a segment-based architecture with automatic data tiering from real-time to historical nodes. Both deliver 10-100x better throughput on aggregation queries compared to Elasticsearch.
MongoDB Atlas Search embeds Lucene-based search directly into the database layer, removing the synchronization problem that plagues Elasticsearch deployments where data lives in one database and search indexes in another. Apache Pinot uses a star-tree index structure for pre-aggregated analytics, enabling constant-time queries regardless of data volume.
InfluxDB uses a purpose-built time-structured merge tree (TSM) storage engine optimized for sequential writes and time-range queries. This architecture delivers 5-10x better compression and query performance on time-series workloads compared to Elasticsearch's general-purpose inverted index.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Model | Starting Price | Self-Hosted Option |
|---|---|---|---|
| Elasticsearch | Freemium/Tiered | $99/mo (Standard) to $184/mo (Enterprise) | Yes (open source) |
| ClickHouse | Open Source | Free (Cloud available) | Yes (Apache 2.0) |
| Apache Druid | Open Source | Free | Yes (Apache 2.0) |
| MongoDB Atlas | Freemium | Free tier, Dedicated from $0.08/hour | Yes (Community) |
| Apache Pinot | Open Source | Free | Yes (Apache 2.0) |
| Firebolt | Freemium | Free Core, Cloud from $0.92/hr (Small node) | Yes (Core edition) |
| InfluxDB | Open Source | Free (Cloud from $250/mo) | Yes (Community) |
| Trino | Open Source | Free (Cloud from $12/mo) | Yes (Apache 2.0) |
| Dremio | Usage-Based | $0.20 per query unit | Yes (Community) |
Elasticsearch's managed Elastic Cloud Hosted pricing starts at $99/month for Standard and $184/month for Enterprise features like searchable snapshots and machine learning, for Elastic's production setup with 120 GB of storage in 2 zones. The open-source alternatives -- ClickHouse, Druid, Pinot -- eliminate licensing costs entirely, though operational overhead for self-hosting remains.
When to Consider Switching
Switch to ClickHouse or Apache Druid when your Elasticsearch cluster spends 80%+ of its resources on aggregation queries rather than full-text search. Teams running log analytics dashboards often discover that Elasticsearch's inverted index architecture wastes compute on workloads that columnar databases handle natively.
Switch to MongoDB Atlas Search when you maintain a separate Elasticsearch cluster solely to search data that already lives in MongoDB. The dual-system architecture creates synchronization bugs, doubles infrastructure costs, and adds operational complexity that Atlas Search eliminates.
Switch to Apache Pinot when you need guaranteed sub-second query latency for user-facing analytics at scale. Elasticsearch's query latency becomes unpredictable under high concurrency, while Pinot's star-tree indexes deliver consistent performance regardless of concurrent query load.
Switch to InfluxDB when time-series data represents your dominant workload. Elasticsearch's index lifecycle management requires constant tuning for time-based data, while InfluxDB handles retention, downsampling, and time-range queries as first-class operations.
Switch to Firebolt when you need cloud-managed analytics with sub-second response times on terabyte-scale datasets and want Postgres SQL compatibility without managing infrastructure.
Migration Considerations
Moving from Elasticsearch to a columnar database like ClickHouse requires restructuring your data model. Elasticsearch's nested JSON documents must be flattened into relational tables with explicit schemas. ClickHouse supports JSON columns, but optimal performance demands denormalized, typed columns. Plan for 2-4 weeks of schema redesign and ETL pipeline rebuilding.
MongoDB Atlas Search offers the smoothest migration path for teams already on MongoDB, since no data movement is required -- you add search indexes to existing collections. For teams not on MongoDB, the migration involves both data migration and application rewrite.
Apache Druid and Pinot require rewriting ingestion pipelines to use their native real-time ingestion APIs or Kafka connectors. Both support SQL queries, so application-layer query translation is straightforward, but neither supports Elasticsearch's Query DSL or full-text search syntax.
InfluxDB migration requires converting Elasticsearch's JSON documents into InfluxDB's line protocol format with explicit timestamps, measurement names, and tag/field distinctions. The data model shift is fundamental but well-documented.
The learning curve varies significantly: MongoDB Atlas Search is the easiest transition (1-2 weeks), ClickHouse and Trino have moderate learning curves (2-4 weeks), while Druid and Pinot require deeper operational expertise (4-8 weeks). All alternatives except Firebolt and Dremio offer fully open-source deployments, reducing vendor lock-in compared to Elastic's increasingly restrictive licensing.