Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What dltHub states |
|---|---|
License | dlt is open source under Apache 2.0, commercial use included; no license key, no seat count, no call with sales |
Where dlt runs | Wherever Python runs: a laptop, a notebook, Airflow, Dagster, a Lambda or a container. No backend, no agent to install, no data leaving your infrastructure |
Installation | pip install dlt, plus extras per source or destination (for example dlt[duckdb]); supports Python 3.10 through 3.14, with 3.14 support experimental because some extras are not yet available for it |
Managed option | dltHub runs dlt pipelines on infrastructure dltHub runs; one command promotes a local pipeline to managed production |
Destinations | Snowflake, BigQuery, Databricks, Redshift, Postgres, DuckDB, ClickHouse, Athena, MotherDuck, a filesystem lake or a vector store |
Our take
If your team writes Python and wants to own its ingestion code, start with the free dlt library: it runs inside your own infrastructure and nothing about it commits you to the paid platform. Consider dltHub when you would rather pay it to run, schedule and govern those same pipelines than do that work yourself.
Evaluate dlt (data load tool)
Popular comparisons
See all 6 dlt (data load tool) comparisons
Where it stands out
Pipelines are plain Python files you own. You declare the endpoints and the auth; dlt handles pagination, rate limits, retries with backoff, and incremental cursors persisted between runs. Nested JSON is unnested into typed, related tables.
Schema contracts at the gate. dlt infers the schema and evolves it when a source adds a field. Contracts have three modes: evolve, freeze (reject the record) and discard (drop the offending row or column), applied separately to tables, columns and data_type.
Broad source coverage from one library. The SQL source reads any of 100+ engines with merge or SCD2 history, using Arrow and ConnectorX backends. The filesystem source reads S3, GCS, Azure or SFTP and can write Parquet, Delta or Iceberg.
Change destination without rewriting. Changing one argument moves a pipeline from DuckDB to Snowflake, BigQuery, Databricks, Postgres, Iceberg or a vector store.
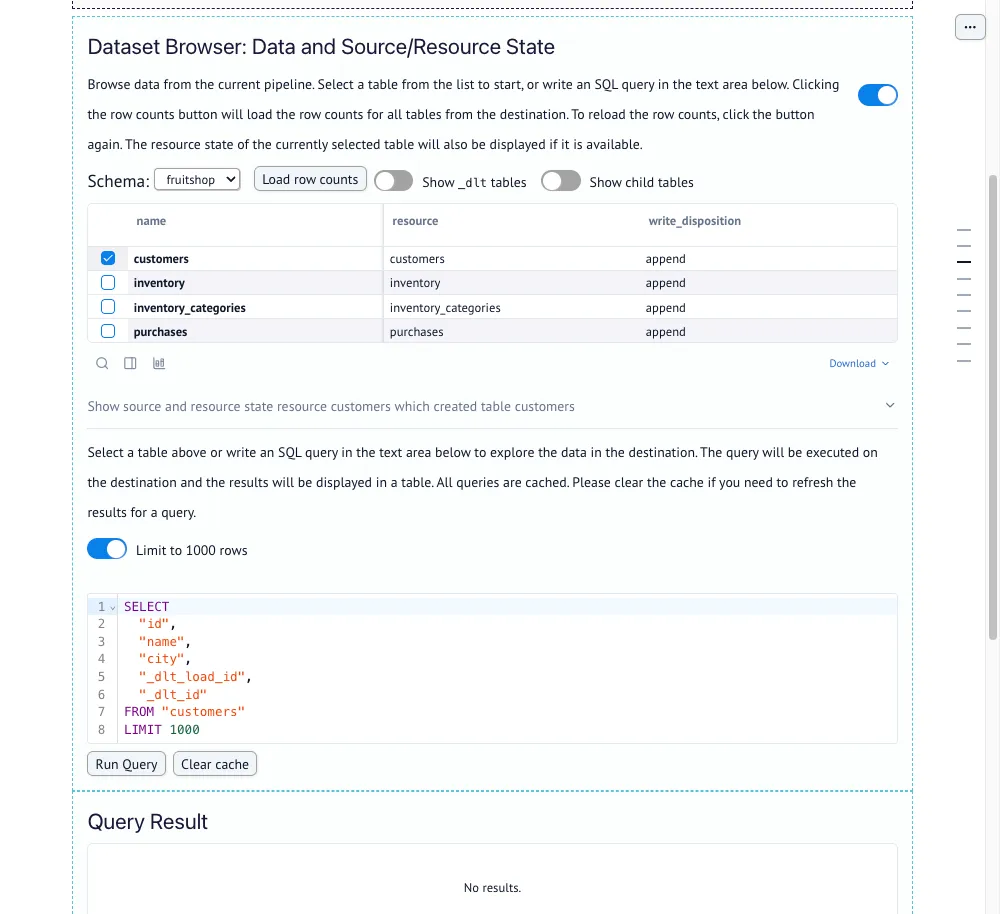
Product screenshot

Trade-offs to weigh
With the free library, operations stay with you. dltHub's own split is that writing a pipeline takes an afternoon while keeping it healthy for two years takes a team. Scheduling, retries, backfills, alerts and run history are what dltHub takes over, so without it you build them on your own orchestrator.
Production use of some features is licensed under a paid subscription. Every paid dltHub subscription includes a license for production use of its source-available capabilities: the AI workbench, change data capture (CDC), Apache Iceberg support and in-pipeline transformations. The code is public; the dlt library stays Apache 2.0.
The free dlt plan lists limited verified OSS connectors. For a missing source, start from a verified source and customize it, generate one from an OpenAPI spec, or write your own; a generator function is a dlt source.
Minor releases can change behavior. dlt follows semantic versioning, and minor versions bring new features and sometimes automatic migrations. The project suggests allowing only patch updates automatically, for example with dlt~=1.23.0.
Pricing and plan conditions
dltHub bills in credits. One USD credit covers one hour of runtime at the standard rate, for batch jobs such as pipelines and interactive jobs such as notebooks; you pay only for hours run. Every sandbox has at least 2 vCPUs and 4GB of memory. Included credits do not roll over month to month; purchased bundle credits do. Usage above the included credits is billed in the volume tiers below. An annual commitment adds a further 5% off the per-credit rate, locks that rate for 12 months and is paid upfront; unused credits roll within the term and expire at renewal.
dltHub says pipelines do not pause automatically today. At launch, admins are alerted within 72 hours when usage reaches 80% and 100% of included credits, so they can buy a top-up bundle. During Phase I, top-up bundles (100 credits for $100 up to 12,800 credits for $9,920) are issued by invoice through your account team or sales@dlthub.com.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
dlt | Free (Apache 2.0) | Open-source, code-first ingestion library for teams that want full infrastructure ownership; reliable ingestion and loading; limited verified OSS connectors; AI help and community support |
Hub | $12,000 per month; 12-month minimum, billed monthly | Everything in dlt, plus: AI Harness (Claude Code, Codex, Cursor), managed runtime for ingestion, transformations and data apps, data quality metrics and checks, observability dashboard, collaboration workflows for teams, migration to dltHub included. 5,000 credits per month included; 14-day free trial with $30 in credits, no card required |
Enterprise | Custom | Custom credits and volume pricing, enterprise security and governance controls, role-based access control (RBAC) and audit logs, SLA and tailored support options, custom onboarding and architecture guidance |
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Credits beyond included | Price |
|---|---|
First 100 credits over included | $1.00 / credit |
Next 100 credits | $0.95 / credit |
Next 200 credits | $0.90 / credit |
Next 400 credits | $0.875 / credit |
Next 800 credits | $0.85 / credit |
Next 1,600 credits | $0.825 / credit |
Next 3,200 credits | $0.80 / credit |
Over 6,400 credits beyond included | Contact sales for custom pricing |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
115 GitHub commits 90d6.1k GitHub stars0 vulnerabilities across 1 package
See all signals from 4 sources
PyPI · dlt@1.32.0
Alternatives
Fivetran, Airbyte or custom pipelines. dltHub positions itself as a replacement: its engineers rebuild Fivetran, Airbyte or custom pipelines as dltHub code with their own AI tools, and Hub includes migration to dltHub.
A hand-written Python script. dltHub says dlt adds schema inference, incremental state, normalization and loading to a script that calls the requests library, while keeping plain Python.
Alternatives to dlt (data load tool)
The reviewed substitutes for dlt (data load tool) among the ELT platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Airbyte
- Airbyte and dlt (data load tool) both load data from APIs, databases and files into warehouses and lakes. Airbyte is a platform with a catalogue of ready connectors, a user interface and a cloud service, while dlt is an open-source Python library that a data engineer writes pipelines with, using schema inference and incremental loading.Applies to: Choosing how data gets from sources into the warehouse.
- Fivetran
- Fivetran and dlt (data load tool) both move data from sources into a warehouse with incremental loading and schema handling. Fivetran is a managed service where connectors are configured rather than written, while dlt is an open-source Python library that engineers use to write their own pipelines in code.Applies to: Choosing how data gets from sources into the warehouse.
- Meltano
- Meltano and dlt (data load tool) are open-source projects for engineers who build ingestion as code, loading data from APIs and databases into a warehouse. Meltano manages pipelines from a command line around Singer connectors, while dlt is a Python library that infers schemas and loads data incrementally from inside any script.Applies to: Choosing between these two for the managed open elt decision.
- Rivery
- Rivery and dlt (data load tool) load data from business applications and APIs into a warehouse. Rivery is a managed SaaS platform with ready-made connectors and automated pipelines, while dlt is an open-source Python library where engineers declare sources in code and get schema inference and incremental loads.Applies to: Choosing between these two for the managed open elt decision.
- Stitch
- Stitch and dlt (data load tool) copy data from SaaS apps and databases into a cloud warehouse. Stitch is a hosted service that teams set up from a web interface, while dlt is an open-source Python library that engineers run in their own code and orchestration.Applies to: Choosing between these two for the managed open elt decision.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- CloudQuery
- dlt (data load tool) and CloudQuery are open-source, code-first tools for extracting data from APIs and loading it into databases. dlt is a general Python library with schema inference, incremental loading and data contracts, while CloudQuery ships ready-made plugins aimed at cloud infrastructure, security and compliance data.Applies to: For teams that want ready-made plugins for cloud infrastructure and security data instead of writing Python pipelines.
- Hevo Data
- dlt (data load tool) is used rather than Hevo Data for custom Python-based ingestion workloads with bespoke sources and data-contract requirements. **dlt (data load tool)** is an open-source Python library for declarative data loading, with automatic schema inference, incremental loading, and built-in data contracts.
- Kleene.ai
- dlt (data load tool) and Kleene.ai both get data from operational sources into a warehouse ready for reporting. dlt is an open-source Python library that engineers build pipelines with, while Kleene.ai is a managed service that also models the data, delivers BI and includes implementation help from its own team.Applies to: When a company is deciding whether to build its own pipelines or buy them as a managed service.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Prefect
- Python-native workflow orchestration with managed cloud control planeApplies to: Whether a managed or code-first ingestion tool removes the need for an orchestrator, or runs inside one.
Head to head
See detailed alternatives analysis
If you are evaluating dlt (data load tool) alternatives, you are likely looking for a data pipeline solution that fits your team's specific requirements around deployment flexibility, pricing model, connector coverage, or level of managed infrastructure. dlt is an open-source Python library (Apache-2.0) that takes a code-first approach to data loading, with automatic schema inference, incremental loading, and built-in data contracts. While dlt excels at giving Python-first teams full control, there are compelling reasons to explore other tools in the Data Pipeline & Orchestration space depending on your use case.
Top Alternatives Overview
Airbyte is an open-source ELT platform with a managed cloud option and one of the largest connector ecosystems in the industry. With over 600 pre-built connectors and 21,000+ GitHub stars, Airbyte provides both a self-hosted open-source edition and a managed Cloud offering. Airbyte is well-suited for teams that want broad connector coverage without writing custom extraction code. Its connector development kit (CDK) also allows building custom connectors. Airbyte recently introduced an Agent Engine for powering AI agents and real-time systems alongside its traditional batch data replication engine.
Fivetran is a fully managed ELT platform that automates data ingestion from SaaS applications, databases, and event streams. Fivetran offers 700+ fully managed connectors with features like automated schema evolution, incremental updates, and built-in security certifications (SOC 1, SOC 2, GDPR, HIPAA, ISO 27001, PCI DSS). It targets teams that want a hands-off, zero-maintenance approach to data movement. Fivetran provides a free tier with 500,000 monthly active rows (MAR) and paid plans for increased volumes.
Meltano is a fully open-source, CLI-first data movement tool built for data engineers who want complete control over their pipelines. With approximately 2,400+ GitHub stars and an open-source core, Meltano emphasizes DevOps best practices and integrates with the Singer ecosystem of taps and targets. It is best for engineering-led teams comfortable managing infrastructure and CLI-based workflows.
CloudQuery is an open-source ELT framework (MPL-2.0 license, 6,300+ GitHub stars) that specializes in extracting data from cloud APIs. Written in Go, CloudQuery focuses on cloud asset inventory, security posture management (CSPM), FinOps, and compliance use cases. It supports AWS, GCP, Azure, Kubernetes, and 50+ additional integrations, making it the strongest choice for platform engineering and governance teams rather than general-purpose data pipeline workloads.
Hevo Data is a no-code, fully managed data pipeline platform focused on simplifying ETL, ELT, and Reverse ETL workflows. Hevo provides pre-built connectors, auto schema mapping, and real-time data synchronization. It targets teams that want reliable pipelines without engineering overhead and offers a free tier along with paid plans.
Prefect is a Python-native workflow orchestration platform with 23,000+ GitHub stars and an Apache-2.0 license. While not a data integration tool per se, Prefect provides the orchestration layer that many teams pair with libraries like dlt for scheduling, monitoring, and managing pipeline execution. It offers both a self-hosted open-source edition and a managed cloud control plane.
Architecture and Approach Comparison
The fundamental architectural difference among these tools lies in the spectrum between code-first libraries and fully managed platforms. dlt sits firmly on the code-first end: it is a Python library you import into your scripts, notebooks, or orchestrators. There is no separate backend or container to run. This makes dlt extremely lightweight and flexible -- it runs wherever Python runs, including Airflow, serverless functions, and Jupyter Notebooks.
Airbyte takes a containerized microservices approach. Each connector runs as a Docker container, providing process isolation between sync jobs. The Airbyte Protocol (a JSON stream format) decouples source and destination logic, enabling interoperability between any connector pair. This architecture is powerful for running many concurrent syncs but requires more infrastructure overhead than a simple Python library import.
Fivetran operates as a fully managed SaaS platform where all infrastructure, connector maintenance, and schema management are handled by Fivetran's team. This eliminates operational burden but also reduces customization options. Fivetran's Hybrid Deployment model offers a middle ground, allowing data movement within your own environment for security-sensitive workloads.
Meltano follows a plugin-based architecture with a CLI interface, leveraging the Singer specification for its connector ecosystem. Pipelines are defined as configuration files and managed through command-line tools, making Meltano especially appealing for teams that want Git-based version control and CI/CD integration for their data pipelines.
CloudQuery uses a plugin-based Go architecture optimized for syncing cloud infrastructure data. Its source plugins extract from cloud provider APIs, and destination plugins load into databases and data warehouses. CloudQuery is priced based on rows synced per year and offers a composable CLI alongside a fully managed platform.
A key consideration is connector breadth versus depth. Fivetran and Airbyte offer the widest connector catalogs (700+ and 600+ respectively), while dlt focuses on giving developers the tools to build any connector quickly through its REST API source toolkit and verified sources. dlt currently offers 60+ verified sources with the ability to build custom sources from any Python data structure, and its AI-native context assets support generating pipeline code from API specifications.
Pricing Comparison
dlt is a free, open-source, code-first ingestion library licensed under Apache 2.0, including for commercial use. It is intended for teams that want full infrastructure ownership and provides reliable ingestion and loading, limited verified OSS connectors, and AI help and community support.
dltHub is the managed option for production data teams. It is listed at $12,000 a month with 5,000 credits included, on a 12-month minimum billed monthly. The subscription includes managed runtime, hosted Marimo notebooks, AI Workbench, data quality metrics and checks, an observability dashboard, and collaboration workflows. A 14-day free trial includes $30 in credits and does not require a card.
Additional dltHub usage beyond the included credits is billed in volume tiers. Enterprise is custom, with custom credits and volume pricing plus security, governance, RBAC, audit logs, SLA, and tailored support options.
This comparison does not list current prices for the alternative tools, so check each vendor's pricing before comparing costs like for like. The available dltHub pricing distinguishes the free self-managed dlt library from a managed platform that adds runtime, observability, data quality, and collaboration capabilities.
When to Consider Switching
Consider moving away from dlt if your team needs a fully managed, no-code experience. dlt requires Python knowledge and infrastructure management for deployment. If your organization prefers a graphical interface for pipeline configuration and monitoring, platforms like Fivetran, Airbyte Cloud, or Hevo Data provide that out of the box without custom code.
Teams that need the broadest possible pre-built connector coverage may benefit from Fivetran or Airbyte. While dlt provides a powerful framework for building any source connector and supports 60+ verified sources, teams that need immediate access to hundreds of SaaS, database, and API connectors without writing code may find Fivetran's 700+ or Airbyte's 600+ managed connectors more practical.
If your primary use case is cloud infrastructure visibility and security posture management rather than general data movement, CloudQuery is purpose-built for that domain with deep integrations across AWS, GCP, Azure, and security tooling.
Conversely, teams should stick with dlt when they value lightweight deployment, full Python control, and the ability to run pipelines anywhere without external infrastructure dependencies. dlt's approach of running as a library rather than a service makes it uniquely suitable for embedding in existing Python workflows, AI/ML pipelines, and notebook-based analysis. Its declarative interface with automatic schema inference and evolution also reduces maintenance burden compared to hand-coding pipeline logic. The growing dltHub Context platform, which provides AI-native context assets for generating pipelines from API specifications, further lowers the barrier to building new sources.
Migration Considerations
Migrating from dlt to another platform typically involves re-implementing your source extraction logic using the target platform's connector framework. Since dlt pipelines are Python code, the business logic is portable even if the specific dlt API calls are not. Document your current schema configurations, incremental loading cursors, and any data contract definitions before migrating.
Moving to Airbyte from dlt is relatively straightforward for standard sources, as Airbyte's pre-built connectors handle most common APIs and databases. For custom sources built with dlt's REST API toolkit, you would need to rebuild them using Airbyte's CDK. Both tools support similar destination targets including Snowflake, BigQuery, DuckDB, and PostgreSQL.
Migrating to Fivetran means trading code-first flexibility for fully managed operations. Verify that Fivetran has connectors for all your current data sources before committing. Fivetran's schema evolution handling is automatic, which may differ from how you configured dlt's schema contracts.
If moving to Meltano, the transition is smoother since both tools are Python-ecosystem tools with similar philosophies around open source and developer control. Meltano's Singer-based connectors may cover your needs, and pipeline definitions move from Python code to YAML configuration files.
Regardless of the target platform, plan for a parallel-run period where both the old dlt pipelines and new platform run simultaneously. Compare output data to ensure consistency before cutting over. Pay attention to how each tool handles schema evolution, null values, nested data structures, and incremental loading state, as differences in these areas can cause subtle data quality issues. Budget for duplicate compute and storage costs during this validation window.