Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Better Stack states |
|---|---|
Instrumentation | OpenTelemetry- and Prometheus-native. eBPF and OpenTelemetry gather traces, logs and metrics from clusters with no code change; error tracking accepts Sentry SDKs for 100+ platforms. |
Data location | EU regions by default, in ISO/IEC 27001-certified data centers. Enterprise accounts can ask for a custom data location, and custom cluster deployment for logs and metrics is an enterprise option. |
Security | SOC 2 Type 2 and GDPR compliant; data encrypted at rest (AES-256) and in transit. |
Automation | REST API, an MCP server, and a Terraform provider for Better Stack Uptime published under Apache-2.0. |
Our take
Choose Better Stack when one vendor should cover uptime checks, on-call, status pages and telemetry, and your team resolves incidents in Slack or Microsoft Teams.
Evaluate Better Stack
Popular comparisons
Where it stands out
Incidents handled in chat. Teams can resolve incidents without leaving Slack or Microsoft Teams, and Slack-based incident management uses templated workflows. Ten incidents created at once can be acknowledged with one tap, and AI writes post-mortems from the incident timeline and Slack.
Context when a check fails. Uptime monitoring records API errors, takes a screenshot of the app being down and runs edge-based traceroute and MTR on timeouts. Playwright transaction checks run in a real Chrome browser.
Log volume you can control. Logs marked as spam are excluded and not charged. Hosting data in your own bucket costs $250 per month ($208 annually) and removes the need to rehydrate logs from S3. Query logs with SQL, PromQL or drag and drop.
An AI SRE that uses your telemetry. The Slack-native agent investigates incidents using logs, metrics, traces, errors and web events. Better Stack says a human is always in charge.
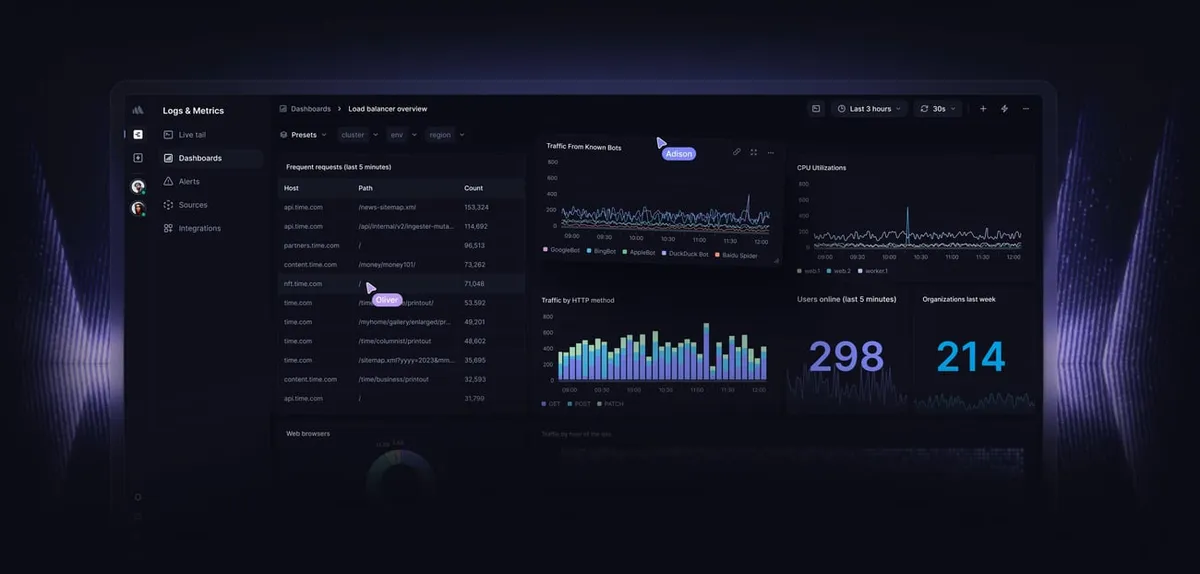
Product screenshot
Trade-offs to weigh
The license is not the whole bill. Responder licenses cover on-call and alerting, but advanced chat workflows, enterprise identity and audit features, and several status page features cost extra. Price the features you need, not just the number of responders.
No HIPAA. Better Stack says it is currently not HIPAA compliant and asks teams that need HIPAA to contact it, so regulated health workloads should settle this before buying.
Pricing and plan conditions
Pricing combines responder licenses for monitoring and incident management with telemetry priced by volume. Team members cost $0 and get free access to telemetry, although reporting is priced per member and Azure or Okta SSO per user. Annual billing gives about two months free, and Better Stack offers a 60-day money-back guarantee.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan or add-on | Published price | What it includes |
|---|---|---|
Free (personal projects) | $0 per month | 10 monitors and heartbeats, 1 status page, Slack and e-mail alerts, 100,000 exceptions and 5,000 session replays a month, 3 GB each of logs, traces and web events kept for 3 days, and 30 GB of metrics. |
Responder license | $34 per license per month, or $29 with annual billing | Uptime monitoring, incident management, on-call and status pages, with unlimited phone call and SMS alerts. |
Telemetry bundles | Start at $25 per month billed yearly, or $30 monthly (Nano) | Nano: 40 GB each of traces, logs and metrics. Micro, Mega and Tera raise this to 160, 340 and 700 GB. All bundles include 30-day log retention. The same sizes are also listed at higher prices (Nano at $38 or $88 per month billed yearly), so confirm which price applies to you. |
AI SRE | Consumption-based, with per-model prices shown in the app | Choice of models from Anthropic, OpenAI, DeepSeek, GLM, Gemini, Kimi and more. |
Slack & Teams workflows | $9 per responder license per month | Channel- and thread-based workflows; a basic single-channel integration is included without it. |
Status page add-ons | Extra public page $15 per month ($12 annually) | One page and 1,000 subscribers included; 1,000 more subscribers cost $40 per month. Monthly prices per page: custom CSS and JavaScript $15, password protection $50, and white-labeling, IP allowlisting or SSO $250 each; annual billing lowers these. |
Call routing | $250 per phone number per month ($208 annually) | Routes incoming calls to the current on-call person and creates incidents; numbers in the USA, CA, EU and UK. |
Monitoring add-ons | 50 more monitors $25 per month ($21 annually); 10 more heartbeats $20 ($17); 100 Playwright minutes $1 | 10 monitors, with checks up to every 30 seconds, and 10 heartbeats included. |
Security and reporting | Azure or Okta SSO $5 per user per month; audit logs $250 per month ($208 annually); reporting $5 per member per month ($4 annually) | Google SSO is included; generic SAML SSO is an enterprise option. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
17 GitHub commits 90d77 GitHub stars0 vulnerabilities across 2 packages
See all signals from 5 sources
npm · @logtail/node@0.5.12 · PyPI · logtail-python@0.5.2
Alternatives to Better Stack
The reviewed substitutes for Better Stack among the observability platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Datadog
- Datadog and Better Stack both monitor production systems, collecting logs and metrics and alerting the team when something breaks. Datadog is a broad platform covering infrastructure, APM, logs and security, while Better Stack focuses on logs, uptime checks, incident alerts and status pages in one product.Applies to: Choosing the observability backend that will receive OpenTelemetry data and carry on-call.
- Observe
- Observe and Better Stack each offer an AI SRE that helps engineers find the cause of incidents faster. Observe is built on a data lake and context graph for searching and correlating large volumes of telemetry, while Better Stack bundles logs, traces, on-call, incident management and status pages in one service.Applies to: Choosing between these two for the apm observability decision.
- Uptrace
- Uptrace and Better Stack offer tracing, metrics, logs and alerting for teams watching their own services. Uptrace is built on OpenTelemetry and ClickHouse and can be self-hosted, while Better Stack is a hosted service that extends monitoring into on-call, incident response and public status pages.Applies to: Choosing between these two for the apm observability decision.
- AppDynamics
- Engineering teams pick Better Stack or AppDynamics to see how their applications perform and to respond when they fail. Better Stack bundles logs, traces, error tracking, on-call and status pages in one hosted service, while AppDynamics is Cisco's enterprise APM platform with business transaction tracing for cloud and on-prem systems.Applies to: Choosing between these two for the apm observability decision.
- Coralogix
- Better Stack and Coralogix each collect logs, metrics and traces so teams can troubleshoot production. Better Stack adds incident management, on-call scheduling and status pages to the same product, while Coralogix puts its weight on in-stream log analytics and cost-optimized data handling, with security monitoring as well.Applies to: Choosing between these two for the apm observability decision.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Checkly
- Observability platforms include synthetic checks, and dedicated synthetic monitoring goes deeper on browser flows and API journeys. The decision is whether the platform's built-in checks cover the need or a specialist tool is worth a second vendor.Applies to: Whether synthetic checks come from the observability platform or a dedicated tool.
Head to head
See detailed alternatives analysis
Why Look for Better Stack Alternatives
Better Stack positions itself as an AI-native observability stack that bundles uptime monitoring, log management, incident management, tracing, infrastructure monitoring, error tracking, and status pages into a single platform. Its free and paid tiers package several operational functions together. However, that bundled approach can be a mismatch for teams that only need one or two observability functions, already have an incident-management workflow, or prefer to assemble specialized tools. Organizations running open-source toolchains may also prefer a more direct OpenTelemetry or Prometheus-native workflow. Teams needing deep code profiling, specialized distributed tracing, or particular enterprise controls should compare those requirements directly. Per-seat and usage-based costs also deserve a workload-specific estimate before choosing a platform.
Top Better Stack Alternatives
Prometheus
Prometheus is the open-source monitoring standard for cloud-native environments, with over 65,000 GitHub stars and an Apache 2.0 license. It uses a pull-based metrics collection model with PromQL, a powerful query language for correlating and transforming time series data. Prometheus servers operate independently on local storage, making deployment straightforward since the Go-based binaries are statically linked. It integrates natively with Kubernetes through service discovery and is a CNCF graduated project. Prometheus is best for teams that want full control over their metrics pipeline without any licensing costs. The tradeoff is that you must self-host and manage storage, alerting (via Alertmanager), and visualization separately.
Pricing: Free and open source.
Elastic Observability
Elastic Observability is a full-stack observability solution built on the Elastic Stack (ELK). It covers log analytics, APM with native OpenTelemetry support, infrastructure monitoring across cloud and Kubernetes, AIOps with zero-config anomaly detection, LLM observability, and digital experience monitoring. The platform can handle petabytes of data with cost-efficient storage using logsdb index mode and TSDB, reducing data footprint by up to 65%. Elastic is standardized on OpenTelemetry and offers AI-driven log processing with Streams. It was named a Leader in the 2025 Gartner Magic Quadrant for Observability Platforms. Available as self-managed, hosted, or serverless deployment.
Pricing: Elastic Cloud Hosted Standard from $99/month, Gold from $114/month, Platinum from $131/month, Enterprise from $184/month, based on a production setup with 120 GB storage in 2 zones.
Sentry
Sentry focuses on application monitoring and error tracking, serving millions of developers at companies like Disney, Anthropic, Instacart, and Lyft. It connects errors, logs, replays, spans, profiles, and metrics through unified traces, letting teams go from issue to context to fix in a single workflow. Sentry's AI debugger, Seer, analyzes logs, commits, traces, and stack traces to generate merge-ready patches. Integration takes five lines of SDK code with no agents to install. It supports over 25 platforms including Next.js, Python, Go, React Native, and .NET. Sentry also offers AI code review to catch regressions before they ship and an MCP server for coding agent integrations.
Pricing: Free Developer tier with 5K errors/month. Team from $26/month, Business from $80/month, Enterprise custom.
Azure Monitor
Azure Monitor provides end-to-end observability for applications, infrastructure, and networks across Azure, multicloud, and hybrid environments. It offers fast onboarding backed by Azure SLAs and integrates deeply with the Microsoft ecosystem. Azure Monitor uses capacity reservation tiers that can save up to 36% on data ingestion costs compared to pay-as-you-go pricing. It is purpose-built for organizations already invested in the Azure cloud, providing native integration with Azure services, Application Insights for APM, and Log Analytics workspaces for centralized querying.
Pricing: Usage-based, starting at $0 with a free tier. Pay-as-you-go or capacity reservation tiers.
Amazon CloudWatch
Amazon CloudWatch is AWS's native monitoring service built for DevOps engineers and SREs. It provides complete visibility into performance, availability, and security across AWS workloads. CloudWatch includes metrics collection, log aggregation, alarms, dashboards, and anomaly detection. For teams running primarily on AWS, CloudWatch offers tight integration with EC2, Lambda, ECS, RDS, and other AWS services without additional agent configuration. The free tier includes basic monitoring for EC2 instances and limited custom metrics.
Pricing: Freemium with usage-based billing. Costs start at $0.01/metric for detailed monitoring, $0.30/GB for log ingestion, $10.50/dashboard/month.
Dynatrace
Dynatrace is an AI-powered observability leader offering automatic discovery, baselining, and root cause analysis through its Davis AI engine. The platform covers APM, infrastructure monitoring, digital experience management, and application security in a single solution. Dynatrace uses OneAgent technology for automatic instrumentation with no manual configuration. It supports AI observability for generative AI applications and LLM agents. Dynatrace holds an 8.4/10 rating across 617 reviews, reflecting strong enterprise adoption.
Pricing: Usage-based. Full-Stack Monitoring from $58/month per 8 GiB host. Infrastructure Monitoring from $29/month per host. Log management from $0.20/GB ingested.
Honeycomb
Honeycomb is built for AI-era software engineering with sub-second query speeds across high-cardinality data. It uses a purpose-built columnar data store optimized for observability, supporting unified telemetry analysis and LLM observability for debugging GenAI behavior. Honeycomb's BubbleUp feature helps visually identify outliers in distributed traces. The platform is trusted by Slack, Intercom, and Dropbox for investigating complex distributed system issues.
Pricing: Free tier with 20 million events/month and 60-day retention. Pro from $150/month. Enterprise custom.
SigNoz
SigNoz is an open-source, OpenTelemetry-native observability platform that combines traces, metrics, and logs in a unified interface. It positions itself as an open-source alternative to Datadog and New Relic with simple usage-based pricing and no proprietary lock-in. SigNoz can run on its cloud or on your own infrastructure, giving teams full control over their telemetry data. The Community Edition is free under the Apache 2.0 license for self-hosting.
Pricing: Community Edition free and open source. Cloud Teams at $49/month including $49 of ingestion credits. Paid cloud from $0.30/GB for logs and metrics ingested.
Architecture and Deployment Comparison
Better Stack operates as a fully managed SaaS platform where all components -- uptime monitors, log storage, incident workflows, and dashboards -- run on Better Stack's infrastructure. This contrasts sharply with open-source alternatives like Prometheus, Grafana Loki, and SigNoz, which require self-hosted deployment on your own Kubernetes clusters or VMs, giving you full data sovereignty but adding operational overhead. Cloud-native options like Azure Monitor and Amazon CloudWatch are tightly coupled to their respective cloud providers, making them natural fits for single-cloud environments but problematic for multi-cloud strategies. Elastic Observability and Dynatrace offer hybrid deployment models: self-managed, hosted, or serverless. Honeycomb and Sentry are SaaS-only, similar to Better Stack. Teams prioritizing OpenTelemetry standardization should note that SigNoz, Elastic, and Honeycomb are fully OTel-native, while Better Stack supports OpenTelemetry but also uses its own eBPF-based instrumentation layer for service mapping.
Pricing Comparison
Better Stack’s official pricing page offers a free personal-project tier at $0 per month, including 10 monitors and heartbeats, one status page, Slack and e-mail alerts, 3 GB of logs retained for three days, 3 GB of traces retained for three days, and 30 GB of metrics.
For telemetry bundles, Nano is listed at $30 per month on monthly billing or $25 per month billed yearly. The Nano bundle includes 40 GB each of traces, logs, and metrics, and bundles include 30-day logs retention. Better Stack also lists its Responder plan at $34 per license per month on monthly billing or $29 per license per month on annual billing; it includes a single responder with unlimited phone-call alerts, while unlimited team members are listed separately.
The public documentation does not provide current official pricing, free-tier terms, or pricing models for the other tools previously shown in this comparison. A like-for-like price comparison therefore is not supported here. Buyers should confirm which Better Stack components they need, whether Responder licenses are required, their telemetry volumes and retention needs, and whether monthly or annual billing applies.
When to Switch from Better Stack
Reassess Better Stack when its disclosed plans and usage allowances no longer fit your requirements. The free personal-project tier includes 10 monitors and heartbeats, one status page, 3 GB of logs retained for three days, 3 GB of traces retained for three days, and 30 GB of metrics. Telemetry bundles include 30-day logs retention; the Nano bundle is listed at $30 per month on monthly billing or $25 per month billed yearly and includes 40 GB each of traces, logs, and metrics.
For incident-response needs, Better Stack lists Responder at $34 per license per month on monthly billing or $29 per license per month on annual billing. It includes a single responder with unlimited phone-call alerts, while unlimited team members are listed separately. Review the number of required responder licenses alongside telemetry volume, retention, monitoring, status-page, and security requirements before deciding whether the service remains suitable.
The public documentation does not provide comparable alternative-product pricing or capability details, so it cannot support a like-for-like recommendation to switch to a particular competing tool.
Migration Considerations
Migrating away from Better Stack requires planning across several dimensions. First, export your existing uptime monitor configurations, alert rules, and on-call schedules, as these are proprietary to Better Stack's workflow engine and must be manually recreated in the target platform. For log data, Better Stack supports storing logs in your own S3 bucket, which simplifies historical data portability -- enable this feature before migration to retain access to archived logs. If your team uses Better Stack's Slack-based incident management workflows, map those templates to equivalent configurations in the target tool's incident management system. OpenTelemetry-instrumented services can typically redirect their OTLP endpoints to a new backend with a configuration change, but any eBPF-based service maps generated by Better Stack's agents will need replacement with the new platform's discovery mechanism. Plan for a parallel-run period of two to four weeks where both systems ingest data simultaneously, allowing you to validate alert parity and dashboard accuracy before cutting over completely.