Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What New Relic states |
|---|---|
Billing basis | Usage-based: users and data ingest, or compute and data ingest |
Edition rule | A customer can have only a single edition at a time (Standard, Pro or Enterprise), so all full platform users are on the same edition |
Data sources | OpenTelemetry, Prometheus, StatsD, eBPF and existing telemetry pipelines |
User types | Basic (free), core and full platform; platform access depends on user type unless you are on the Compute model |
Agent license | New Relic Agent Control is licensed under the New Relic Software License |
Special programs | Observability for Good for nonprofits; New Relic for Startups for early-stage startups |
Our take
New Relic is a good fit if you want application, infrastructure, log, digital-experience and AI monitoring in one platform, and someone on the team will watch data ingest and full platform user counts each month. If nobody can own that cost, keep the evaluation on the free tier until someone can.
Evaluate New Relic
Popular comparisons
See all 15 New Relic comparisons
Where it stands out
No host counting. New Relic says unlimited hosts, agents, containers, devices, AWS Fargate tasks and cloud functions are included at no additional cost. Adding servers or containers does not add a per-host fee.
Free viewers. Basic users cost $0 and can access custom dashboards, queries, alerts and instrumentation. Product managers and executives who only need shared dashboards or alert status do not need a paid seat.
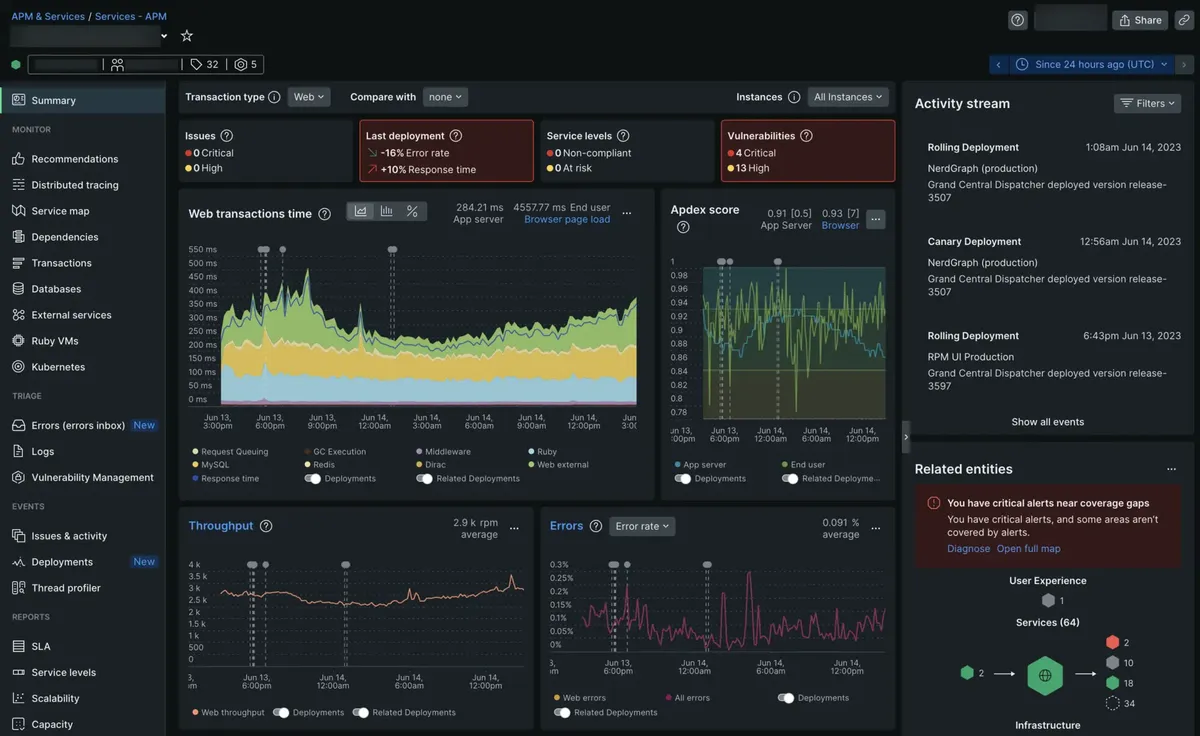
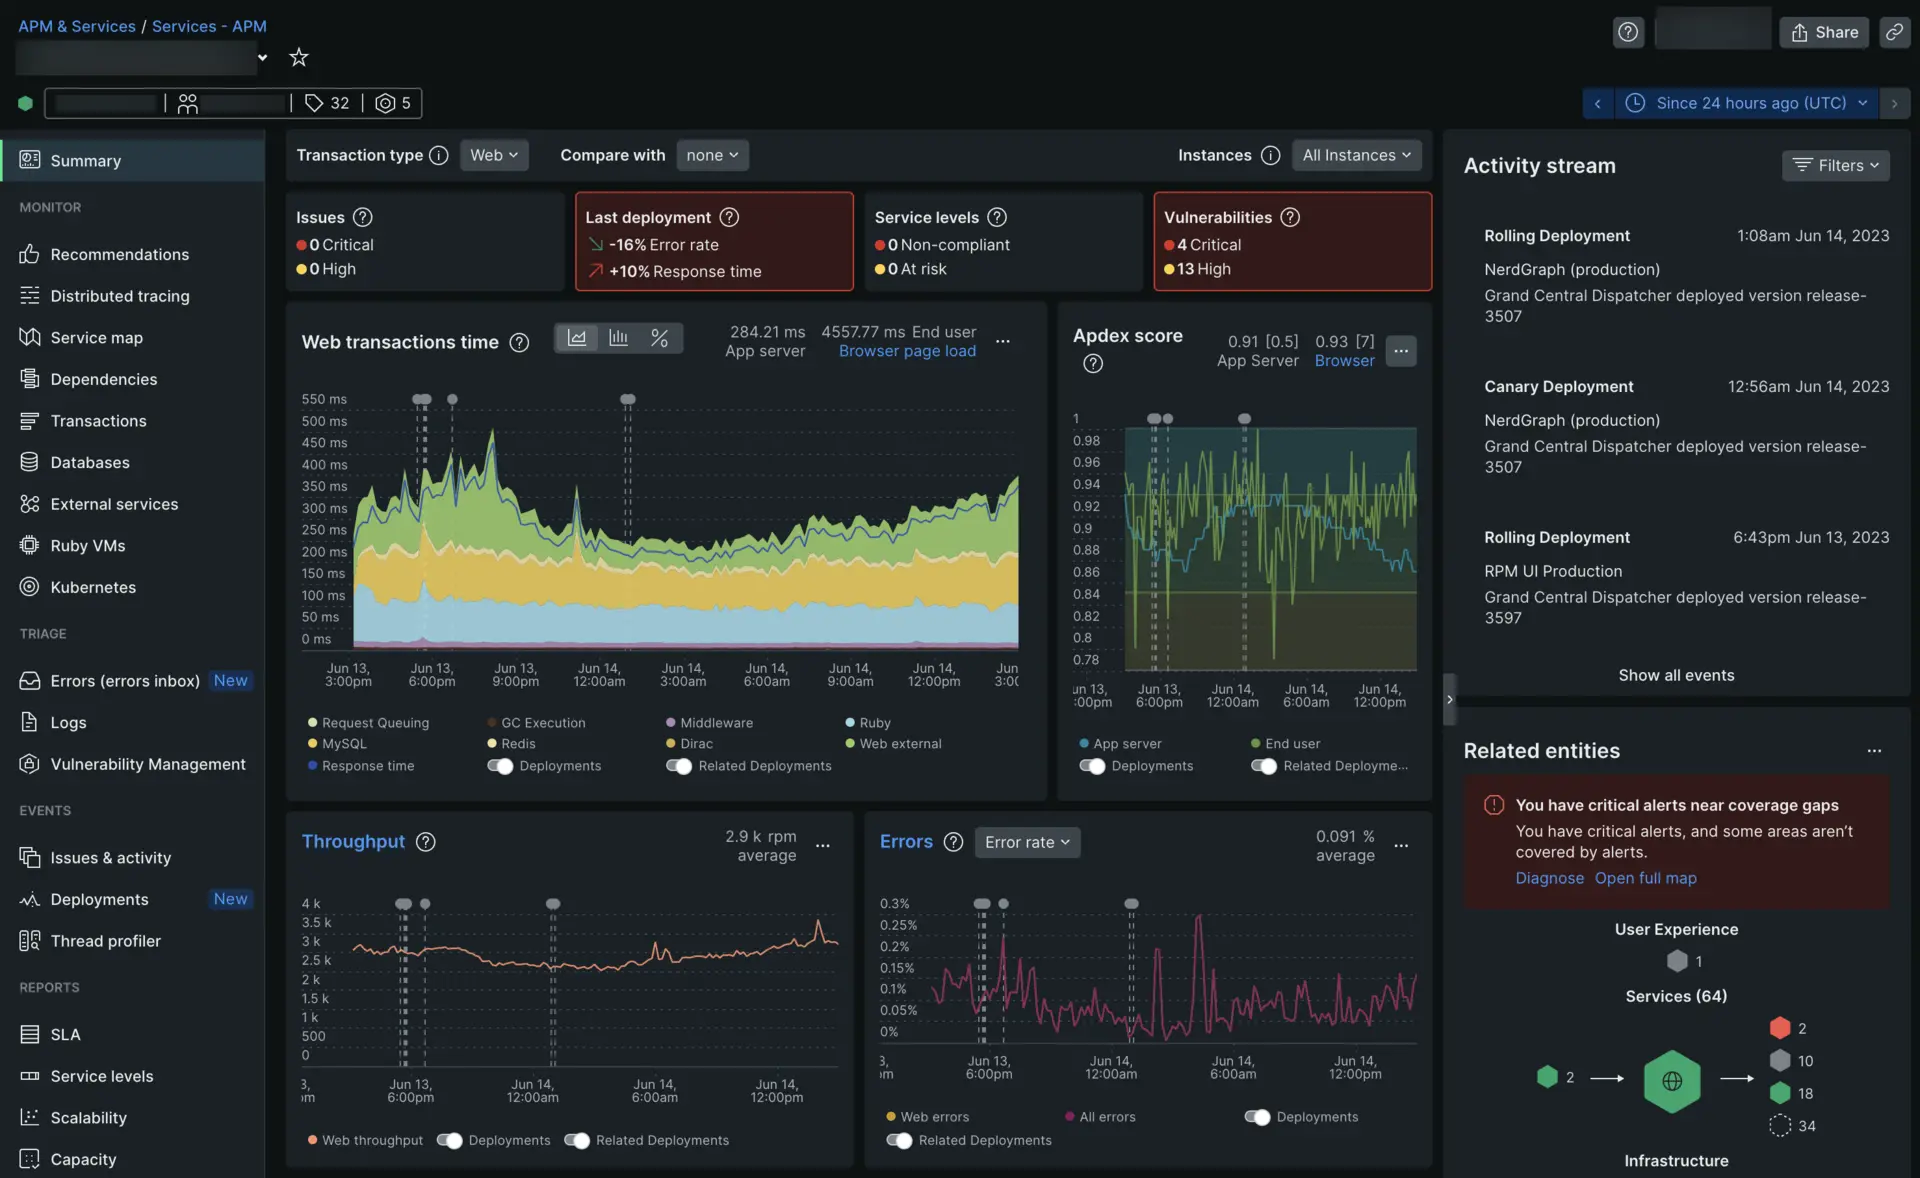
Code-level and user-facing views. Application Performance Monitoring covers APM 360, distributed tracing, service maps, an errors inbox and code-level metrics. Digital Experience covers browser and mobile monitoring, synthetic checks, session replay and Core Web Vitals.
AI and agent monitoring. AI Monitoring tracks model performance, prompt analytics, cost tracking, response quality and agent traces. New Relic also offers an SRE Agent it positions as automated remediation, and AI analysis of session replays to find friction points.
Analysis without moving data. New Relic says it can analyze telemetry across warehouses and lakes without moving data, and it lists Federated Logs and Cloud Cost Intelligence on the platform. This matters for data teams that already keep telemetry in a warehouse or lake.
Product screenshot
Trade-offs to weigh
The free tier stops hard. When you exceed the free 100 GB of data ingest in a month, data ingest stops and you lose access to the platform until you upgrade to a paid edition or the month ends. New Relic sends an email and an in-platform alert at 85% of the allowance.
A sixth engineer changes the edition. Standard is limited to 5 full platform users, and all full platform users must be on one edition. A team that needs a sixth full user moves everyone to Pro or Enterprise.
Ingest is the variable cost. Data ingest is billed on the volume saved after processing, including your transformation and trimming rules. Advanced Compute features such as Transaction 360 and New Relic AI add charges on top when enabled; Feature Control Manager lets you switch capabilities on or off.
Compliance needs two purchases. FedRAMP Moderate and HIPAA eligibility requires both the Enterprise edition and the Data Plus data option.
Commitments are binding. On a buying program with a term commitment fee, you still owe the fee if you stop using New Relic. With pay-as-you-go, you can cancel any time and pay only for usage before cancellation.
Pricing and plan conditions
Core users start at $49 per user and add IDE telemetry through CodeStream, error tracking and logs to basic access. The Compute model charges only for the compute you use, with no user fees.
Pay-as-you-go is open to Standard and Pro: billing happens at the end of each calendar month, with no commitment past the current month. Pro and Enterprise can sign commitment contracts with volume and savings plans; with a savings plan, unused funds roll over for up to 12 months.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Free | $0, with 100 GB/month of data ingest included | One free full platform user; unlimited basic users; automatic logs obfuscation; default data retention of at least 8 days; no credit card required |
Standard | Full platform users: $10 for the first user, $99 per additional user | Limited to 5 full platform users; ticketed support with a 2 business days support response SLA; SAML single sign-on |
Pro | Full platform users: $349/user (for annual commitments) or $418.80/user (for monthly pay as you go) | Unlimited full platform users; commitment options; 2-hour critical initial support response SLA; Data Plus eligibility; optional full consumption pricing with no user licenses |
Enterprise | Custom pricing | Everything in Pro plus: FedRAMP Moderate and HIPAA eligibility with Data Plus; priority ticket routing; 1-hour critical initial support response SLA |
Original data option | Standard and Pro: $0.40/GB beyond the free 100 GB each month; Enterprise: contact sales | Default data retention for each data type |
Data Plus option | Standard and Pro: $0.60/GB beyond the 100 GB free each month; Enterprise: contact sales | Up to 90 days of extra retention for most data types over the default; FedRAMP Moderate and HIPAA eligibility for Enterprise edition customers; advanced logs obfuscation; enhanced streaming and historical-data export |
EU data center | Additional $0.05/GB per month | Stores data in the European Union data center |
Extra synthetic checks (add-on) | $0.005 per check | Synthetic checks beyond the amount included in your edition |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
338 GitHub commits 90d11 GitHub stars0 vulnerabilities across 2 packages
See all signals from 8 sources
npm · newrelic@14.11.0 · PyPI · newrelic@14.2.0
Alternatives to New Relic
The reviewed substitutes for New Relic among the observability platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Datadog
- Choose Datadog if you need the broadest integration ecosystem and want AI-powered anomaly detection across all telemetry types without manual configuration.
- Dynatrace
- Choose Dynatrace if you need automated root cause analysis and want a platform that maps your entire application topology without manual configuration.Applies to: Choosing between two products of the same kind for one job.
- AppDynamics
- New Relic and AppDynamics are established APM products that diagnose slow code and failing transactions in web and mobile applications. New Relic is a SaaS platform that correlates telemetry across the stack with code-level diagnostics, while AppDynamics, from Cisco, centers on business transaction tracing and also serves on-prem environments.Applies to: Choosing between these two for the apm observability decision.
- Better Stack
- New Relic and Better Stack both ingest traces, metrics and logs, alert on them and help engineers debug production issues. New Relic is a broad SaaS platform with deep application performance monitoring, while Better Stack joins log management with uptime monitoring, incident alerts and status pages in one product.Applies to: Choosing the observability backend that will receive OpenTelemetry data and carry on-call.
- Coralogix
- New Relic and Coralogix both correlate metrics, logs and traces to help teams isolate the root cause of incidents. New Relic grew from application performance monitoring and offers code-level diagnostics, while Coralogix grew from log analytics, with in-stream processing and cost-optimized data storage.Applies to: Choosing between these two for the apm observability decision.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Grafana Cloud
- Choose Grafana Cloud if your team values open-source foundations, already uses Prometheus, and wants the flexibility to move between self-hosted and managed deployments.Applies to: Managed observability for a team starting on a free tier and growing into usage-based billing.
- Elastic Observability
- Choose Elastic Observability if you need fast full-text search across massive log volumes and want the option to self-host your entire observability stack.Applies to: SaaS-based application performance management workloads needing code-level diagnostics
- Observe
- Choose Observe if you need cost-efficient observability at high data volumes and want a data-lake-native architecture that avoids per-user pricing.Applies to: application performance management workloads requiring code-level diagnostics across cloud, datacenter, or hybrid environments
- Splunk
- Choose Splunk if your primary driver is security observability and log analytics, or if you need on-premises deployment options for compliance reasons.Applies to: Storing, searching and alerting on logs and monitoring data. Splunk stands in where log search and analysis lead; New Relic stands in where application performance monitoring leads and logs are read in that context.
- Prometheus
- New Relic and Prometheus both measure how services behave and alert teams when they degrade. New Relic is a SaaS platform with code-level diagnostics that correlates telemetry across the whole stack, while Prometheus is open-source metrics software that a team deploys, scales and wires into dashboards itself. That trade between buying a platform and running open-source parts decides the pick.Applies to: Whether monitoring is assembled from open-source components or bought as a platform.
- Grafana
- Choose Grafana Cloud if your team values open-source foundations, already uses Prometheus, and wants the flexibility to move between self-hosted and managed deployments.Applies to: For teams that want application and infrastructure telemetry on dashboards with alerts.
Head to head
See detailed alternatives analysis
New Relic is a full-stack observability platform offering APM, infrastructure monitoring, distributed tracing, log management, and its proprietary NRQL query language across a unified telemetry data platform. Teams searching for New Relic alternatives typically cite pricing unpredictability from the usage-based billing model, a steep learning curve for non-technical users, and the desire for either deeper AI-driven automation or greater control through open-source tooling. While New Relic's perpetual free tier (100 GB/month data ingest, 1 full-platform user) lowers the barrier to entry, costs scale sharply as data volumes and team sizes grow.
Top Alternatives Overview
Datadog is the most direct competitor to New Relic, offering a unified platform that spans APM, infrastructure monitoring, log management, real user monitoring, synthetic testing, and security monitoring. Datadog's strength is its 800+ integrations and pre-built dashboards that deliver instant visibility across virtually any technology stack. The platform's Watchdog AI automatically detects anomalies across metrics, traces, and logs without requiring manual alert configuration. Datadog's notebook-style investigation workflows and correlated views across telemetry types make incident response faster. Choose Datadog if you need the broadest integration ecosystem and want AI-powered anomaly detection across all telemetry types without manual configuration.
Dynatrace differentiates through its Davis AI engine, which performs deterministic root cause analysis across the full application stack automatically. Unlike statistical anomaly detection, Davis traces causality chains from business impact down to the offending code deployment, container, or infrastructure change. Dynatrace's OneAgent technology deploys a single agent per host that auto-discovers and instruments all processes, services, and dependencies without code changes. The platform's Software Intelligence Hub supports over 600 technologies. Dynatrace excels in large enterprise environments with complex microservice architectures. Choose Dynatrace if you need automated root cause analysis and want a platform that maps your entire application topology without manual configuration.
Grafana Cloud provides an open-source-first observability stack built on Prometheus (metrics), Loki (logs), Tempo (traces), and Grafana (visualization). This architecture avoids vendor lock-in since each component uses open standards and open-source data formats. Grafana Cloud handles the operational burden of running these components at scale while preserving full compatibility with self-hosted deployments. The platform's alerting system supports multi-dimensional alert rules with notification routing to Slack, PagerDuty, OpsGenie, and custom webhooks. Grafana's dashboard builder is widely considered the most flexible in the observability market. Choose Grafana Cloud if your team values open-source foundations, already uses Prometheus, and wants the flexibility to move between self-hosted and managed deployments.
Observe is built on a streaming data lake architecture that stores all telemetry (logs, metrics, traces) in a unified data model using the O11y Context Graph. This graph structures telemetry as entities with semantic relationships, enabling cross-signal correlation without pre-defined indexes. Observe's data lake approach delivers up to 60% reduced costs compared to traditional observability platforms by using low-cost cloud storage with 10x compression. The platform charges purely on data volume ($0.49/GiB for logs, ~$0.008/DPM for metrics) with unlimited users, alerts, and dashboards. Choose Observe if you need cost-efficient observability at high data volumes and want a data-lake-native architecture that avoids per-user pricing.
Splunk is the established leader in log analytics and security information and event management (SIEM), with powerful search processing language (SPL) capabilities that enable complex log queries and correlations. Splunk's strength is in security observability, compliance reporting, and handling massive unstructured log volumes. The platform supports on-premises, cloud, and hybrid deployments, giving enterprises flexibility in where their data resides. Splunk's ecosystem includes over 2,800 apps and add-ons on Splunkbase. Choose Splunk if your primary driver is security observability and log analytics, or if you need on-premises deployment options for compliance reasons.
Elastic Observability leverages the Elasticsearch engine to provide unified APM, infrastructure metrics, uptime monitoring, and log analytics. The platform's query performance on large datasets is exceptional, powered by Lucene-based inverted indexes and columnar storage. Elastic supports both self-managed deployments and Elastic Cloud, and the core components are available under a server-side public license. The platform's machine learning features detect anomalies in time-series data and forecast capacity trends. Choose Elastic Observability if you need fast full-text search across massive log volumes and want the option to self-host your entire observability stack.
Architecture and Approach Comparison
New Relic stores all telemetry in its proprietary NRDB (New Relic Database), a custom-built time-series database that powers NRQL queries across all data types. This unified storage model means metrics, events, logs, and traces share the same query engine, enabling cross-signal analysis through a single query language.
Datadog uses a multi-backend architecture with separate optimized storage engines for metrics (time-series), logs (indexed search), and traces (sampled storage). The platform correlates across these backends through shared tags and service identifiers.
Dynatrace's Grail data lakehouse provides a unified storage layer with a causal AI engine that builds a real-time topology model (Smartscape) of all monitored entities and their dependencies. This topology enables Davis AI to trace root causes automatically.
Grafana Cloud's architecture is intentionally unbundled: Mimir handles metrics, Loki handles logs, and Tempo handles traces, each optimized for its data type. Grafana unifies these backends at the visualization layer, using exemplars and trace-to-log links for cross-signal navigation.
Observe's streaming data lake ingests all telemetry into a single data model and materializes views incrementally, enabling ad-hoc exploration across the full dataset without pre-indexing. This architecture trades query-time flexibility for lower storage costs.
Splunk and Elastic both rely on search-engine-based architectures with inverted indexes for fast text search, though Splunk's SPL and Elastic's KQL/EQL provide different query paradigms.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Platform | Free Tier | Data Ingest Cost | User Pricing | Enterprise |
|---|---|---|---|---|
| New Relic | 100 GB/mo + 1 full-platform user | $0.40/GB beyond 100 GB free | Basic: free; Core: $49/user/mo; Full: $99-349/user/mo | Custom |
| Datadog | 14-day trial | Logs: $0.10/GB ingested + $1.70/million events indexed | Infrastructure: from $15/host/mo | Custom |
| Dynatrace | 15-day trial | DPS (Davis Data Units) based pricing | Included in DPS | Custom |
| Grafana Cloud | Generous free tier | Logs: $0.50/GB; Metrics: $8/1k series/mo | Included | Custom |
| Observe | None | Logs: $0.49/GiB; Metrics: ~$0.008/DPM | Unlimited users included | Custom |
| Splunk | 500 MB/day (Splunk Cloud trial) | Workload-based pricing (SVCs) | Included | Custom |
| Elastic Observability | Self-hosted free | Cloud: from $95/mo | Included | Custom |
When to Consider Switching
Pricing surprises are the top reason teams leave New Relic. The usage-based model charges separately for data ingest and full-platform users, and costs escalate quickly when engineering teams grow or when a new data source starts shipping telemetry. Teams that cannot accurately predict their monthly data volume face bill shock.
New Relic's learning curve is a documented pain point. NRQL is powerful but requires dedicated training, and the platform's UI -- while comprehensive -- presents a steep onboarding ramp for teams new to observability. Reviewers consistently flag the interface as less intuitive than competitors like Datadog.
Teams that need automated root cause analysis beyond statistical anomaly detection find New Relic's AI capabilities trailing Dynatrace's deterministic causal AI. New Relic's AI assistant helps with queries and alert creation, but it does not automatically trace root causes through dependency chains.
Organizations committed to open-source observability standards (OpenTelemetry, Prometheus) and wanting to avoid vendor lock-in find Grafana Cloud or Elastic Observability more aligned with their philosophy. While New Relic supports OpenTelemetry ingestion, the platform's value is concentrated in its proprietary query and visualization layer.
Migration Considerations
Migrating from New Relic requires re-instrumenting applications if you rely on New Relic's proprietary agents. The smoothest path is switching to OpenTelemetry instrumentation first -- New Relic supports OTLP natively, so you can validate your OTel instrumentation while still sending data to New Relic, then redirect the OTLP endpoint to your new platform.
NRQL queries and custom dashboards do not transfer to any other platform. Teams with extensive NRQL-based alerting and dashboards face the largest migration effort. Document your critical queries and alert conditions before starting the migration, then recreate them in the target platform's query language (PromQL for Grafana, DQL for Dynatrace, SPL for Splunk).
New Relic's custom events and attributes need mapping to the new platform's data model. Datadog uses tags, Dynatrace uses entity attributes, and Grafana Cloud uses Prometheus labels -- each has different cardinality constraints and naming conventions.
Plan for a parallel-run period of 2-4 weeks where both platforms ingest the same data. This validates completeness, verifies alert parity, and lets teams build confidence in the new platform before decommissioning New Relic.
For teams that need the broadest integration coverage with strong AI features, we recommend Datadog. For enterprises requiring automated root cause analysis in complex microservice environments, Dynatrace is the best fit. For cost-sensitive teams with high data volumes, Observe delivers the most predictable pricing.