Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Checkly states |
|---|---|
Where checks run | Checkly cloud: Hobby and Starter use 6 locations (max 3 per check); Team and Enterprise use all 22 and add private locations inside your own network for internal APIs and staging environments |
How monitors are defined | TypeScript or JavaScript with the Checkly CLI, or the Terraform and Pulumi providers; changes go through pull requests and CI/CD |
Check types | Uptime monitors (URL, TCP, DNS, ICMP, SSL, gRPC, traceroute and heartbeat), API checks, Playwright browser checks and Playwright Check Suites |
What you pay for | Uptime monitors are counted per monitor; API and browser checks are billed by monthly runs. Every executed browser script is one run, and a Playwright Check Suite uses one run per 30 seconds it runs |
CLI license and install | The checkly-cli repository is Apache-2.0; install with npm install --save-dev checkly or start with npm create checkly@latest |
Security | SOC 2 Type II certified |
Our take
If your team already writes Playwright tests and wants monitors reviewed and shipped like application code, Checkly is a strong choice. If you would rather click monitors together in a UI, you get less from its main design choice.
Evaluate Checkly
Comparisons
Where it stands out
Playwright tests become monitors. Browser checks are standard
*.spec.tsfiles written with@playwright/test. Playwright Check Suites run whole test suites natively, with custom dependencies and shared storage state. On every plan, browser and API checks can run in parallel across locations.Test before you deploy.
npx checkly testruns checks from your machine or in CI, andnpx checkly deploythen pushes them to the Checkly cloud to run around the clock.Catches silent job failures. Heartbeat monitors alert when a cron job or worker does not check in, which a URL poll cannot detect.
Less alert noise. Checkly confirms failures from multiple locations before alerting, with retries, thresholds and maintenance windows. Uptime monitors retry once on Hobby and Starter, several times on Team and Enterprise. PagerDuty and Opsgenie need Team or Enterprise.
High-frequency and multistep API checks. Team and Enterprise list an option to run checks as often as every 10 seconds, and a 1-second API check interval is available on request. Team's plan summary gives 30 seconds as its maximum, so confirm this with Checkly. Multistep checks chain several API calls to test a workflow.
AI help with failures. Rocky AI gives summaries and analysis of check runs, and root cause analysis can start automatically when a check fails. Confirm which plans include it.
Works with AI coding assistants. A Checkly skill (
npx skills add checkly/checkly-cli) gives assistants CLI documentation and examples for creating API checks, browser checks and alert channels.
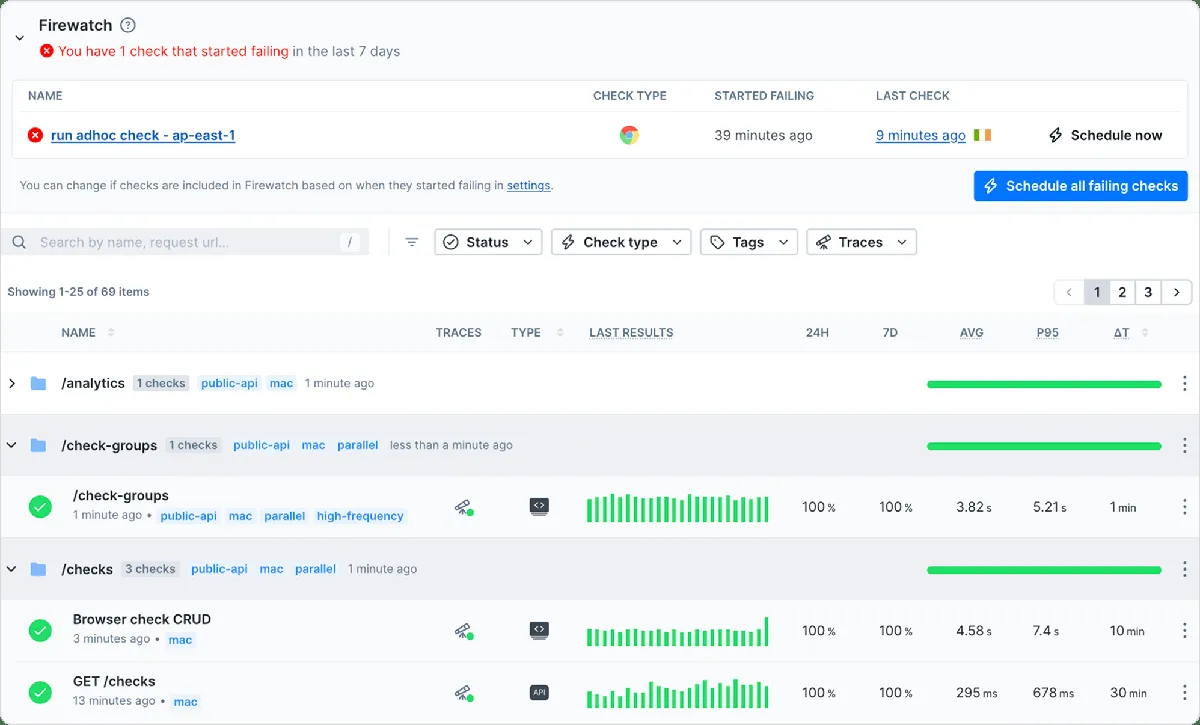
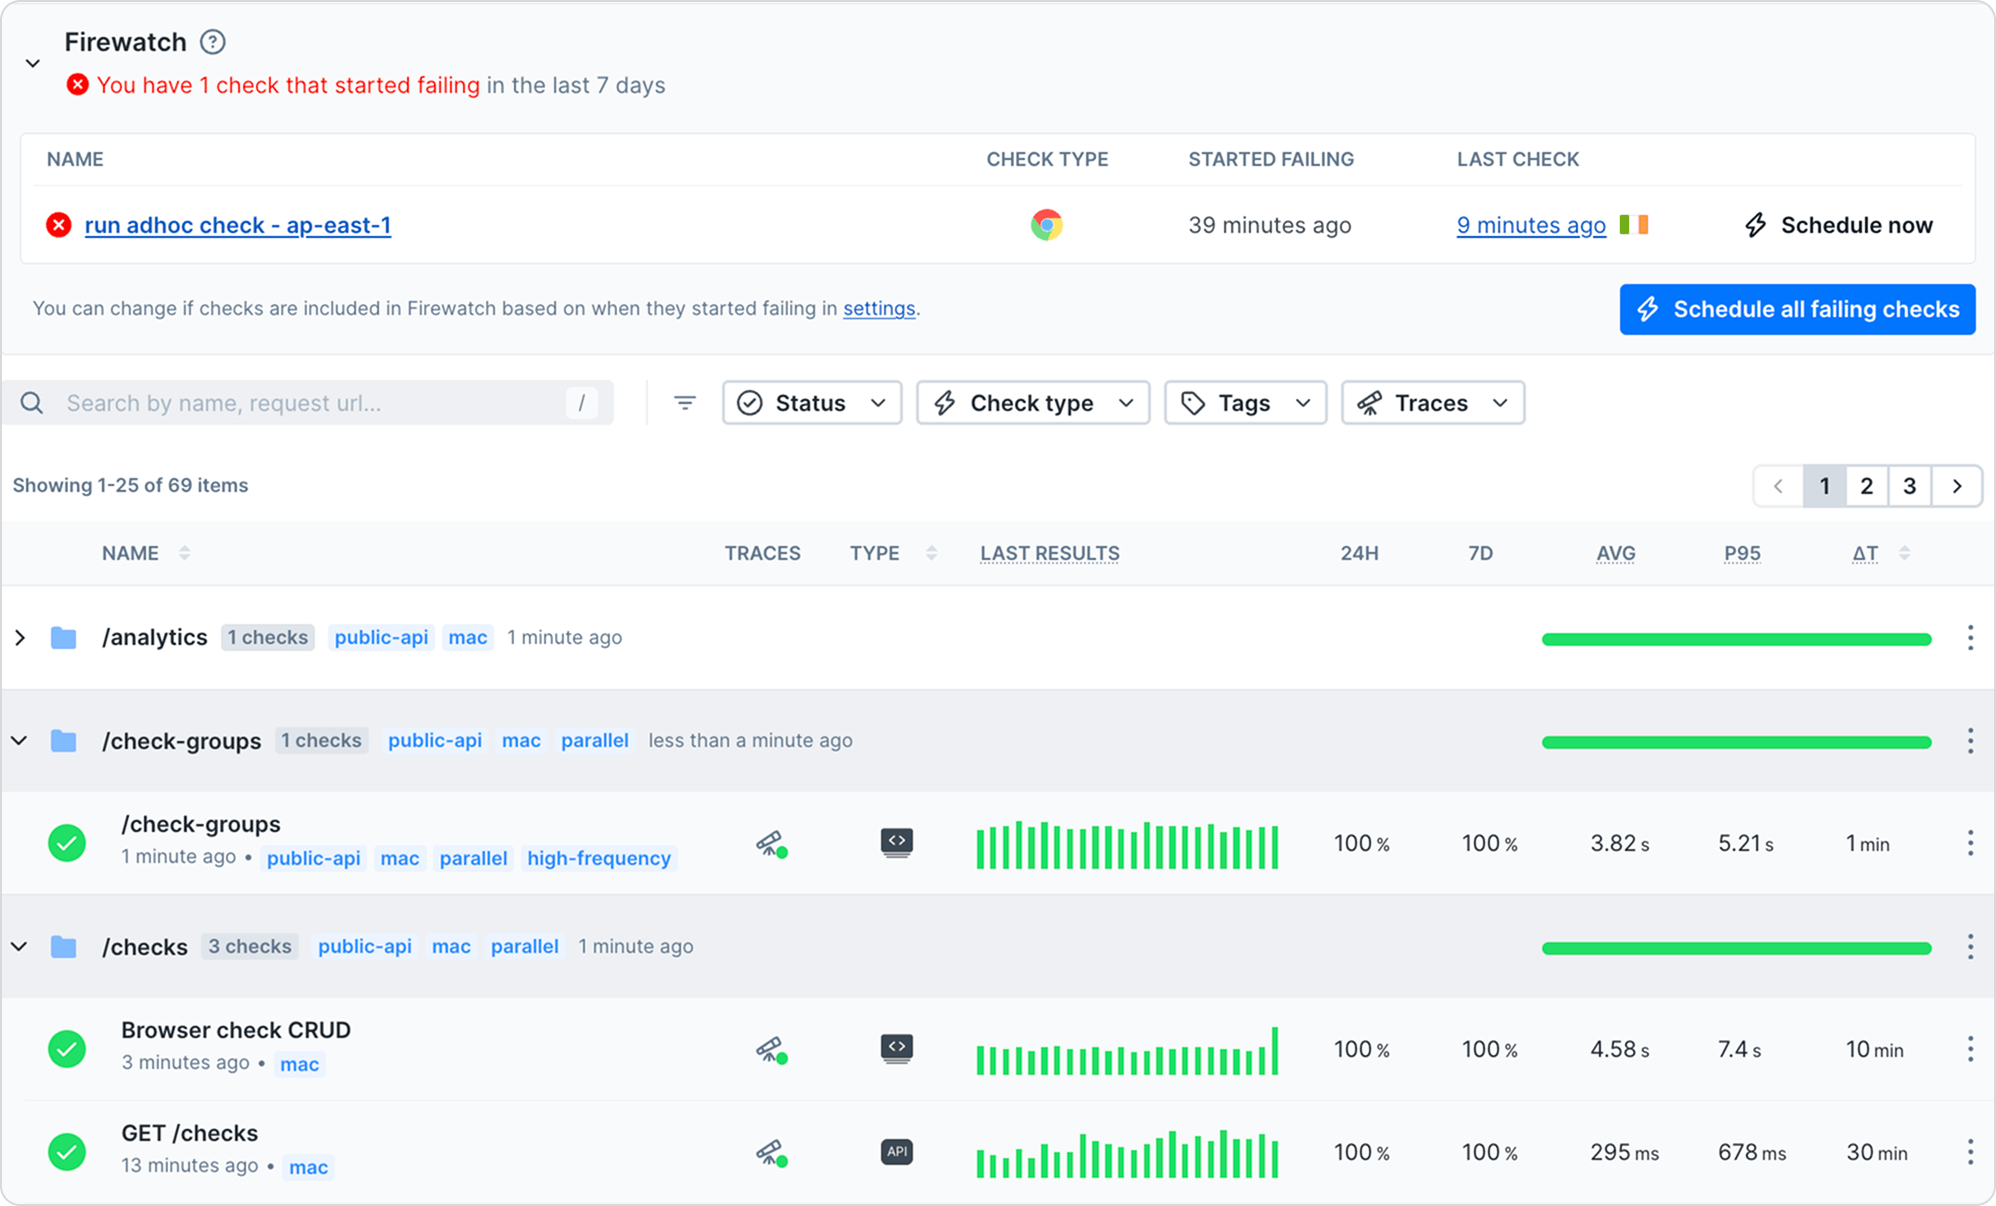
Product screenshot
Trade-offs to weigh
No real user monitoring. Checkly tests from the outside. If you need performance data from real user traffic, Checkly states it does not do that.
Uptime checks do not prove journeys work. A login page can return 200 while login is broken. Covering login or checkout needs browser checks, which draw on the browser-run allowance, not the uptime monitor count.
Long suites use more runs. Checkly's own example: a 45-second Playwright Check Suite consumes 2 runs. Browser check runs time out at 4 minutes.
Browser checks mean Playwright. Browser checks are Node.js scripts on the Playwright framework, so suites written for other test frameworks would need to be rewritten first.
Pricing and plan conditions
Paid prices below are per month, billed annually; annual billing saves up to 20%. Hobby needs no credit card. You can move between Hobby, Starter and Team in the self-serve billing portal: upgrades are charged pro-rated for the rest of the cycle, and downgrades take effect at the end of the current cycle. Enterprise changes go through sales.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it includes |
|---|---|---|
Hobby | $0 per month | 1 team member; 10 uptime monitors; 1,000 browser and 10,000 API check runs per month; 2-minute maximum frequency; 6 locations (N. Virginia, N. California, Frankfurt, London, Singapore, Sydney), max 3 per check; check results kept 7 days, aggregated metrics 30 days; email, Slack and webhook alerts; no add-on purchases |
Starter | $24 per month, billed annually | 3 team members; 50 uptime monitors; 3,000 browser and 25,000 API check runs per month; 1-minute maximum frequency; same 6 locations, max 3 per check; check results kept 7 days, aggregated metrics 30 days; adds SMS alerts |
Team | $64 per month, billed annually | 10 team members; 75 uptime monitors; 12,000 browser and 100,000 API check runs per month; 30-second maximum frequency; all 22 locations; private locations; visual regression (screenshot comparison); incident management integrations such as PagerDuty and Opsgenie; traces; check results kept 30 days, aggregated metrics 1 year |
Enterprise | Custom quote | Custom team members and limits; all 22 locations; private locations; screenshot comparison; traces; 1-second maximum frequency; Round Robin and Parallel scheduling for uptime monitors; SAML SSO; 99.9% uptime SLA; priority support, guided onboarding, a dedicated Checkly engineer and 24/7 phone escalation; custom contracts and invoicing; check results kept 180 days, aggregated metrics 25 months; status pages as add-ons purchased separately |
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Add-on | Published rate |
|---|---|
Extra uptime monitors | Starter and Team: $8 per block of 25 |
Extra browser check runs | Starter and Team: $4.00 per 1k purchased; runs beyond what you bought are charged automatically at $6.50 per 1k on Starter and $6.25 per 1k on Team |
Extra API check runs | Starter and Team: $1.80 per 10k purchased; runs beyond what you bought are charged automatically at $2.60 per 10k on Starter and $2.50 per 10k on Team |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
133 GitHub commits 90d96 GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
npm · checkly@9.5.0
Alternatives to Checkly
The reviewed substitutes for Checkly among the synthetic monitoring, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Datadog
- Observability platforms include synthetic checks, and dedicated synthetic monitoring goes deeper on browser flows and API journeys. The decision is whether the platform's built-in checks cover the need or a specialist tool is worth a second vendor.Applies to: Whether synthetic checks come from the observability platform or a dedicated tool.
- Better Stack
- Best for small-to-mid-size engineering teams that want monitoring plus incident management without managing multiple vendors.Applies to: Whether synthetic checks come from the observability platform or a dedicated tool.
- Grafana Cloud
- Observability platforms include synthetic checks, and dedicated synthetic monitoring goes deeper on browser flows and API journeys. The decision is whether the platform's built-in checks cover the need or a specialist tool is worth a second vendor.Applies to: Whether synthetic checks come from the observability platform or a dedicated tool.
See detailed alternatives analysis
Checkly alternatives are worth evaluating if your team needs broader observability beyond synthetic monitoring, or if Checkly's pricing model does not fit your budget as monitor counts grow. Checkly is a monitoring-as-code platform built around Playwright and JavaScript/TypeScript test scripts, offering synthetic monitoring with CI/CD-native workflows. The Hobby tier is free with 10 monitors and 1K browser checks per month, while the Starter plan costs $24/month for 50 monitors and the Team plan runs $64/month for 75 monitors with visual regression testing. The observability market in 2026 includes several platforms that overlap with or extend Checkly's synthetic monitoring capabilities in different directions.
Top Alternatives Overview
Datadog is a full-stack observability platform that includes Synthetic Monitoring as one module within a broader suite covering APM, infrastructure monitoring, log management, and security. Datadog's synthetic checks support API tests, browser tests, and multi-step API tests with locations across 100+ global regions. The key advantage over Checkly is consolidation: teams already using Datadog for traces and logs can add synthetic monitoring without managing a separate vendor. Usage-based pricing starts at $0.75 per host per month for infrastructure monitoring, with synthetic tests priced separately per test run. The trade-off is cost unpredictability at scale and no native Playwright integration. Datadog is the strongest choice for organizations that need synthetic monitoring, APM, and log analytics unified under one billing umbrella.
Better Stack combines uptime monitoring, incident management, and a hosted status page into a single product. Better Stack's Uptime product comes with its Responder license at $34 per month, or $29 a month billed annually, and includes HTTP, ping, and browser checks alongside integrated on-call scheduling and public status pages. The differentiator is operational simplicity: instead of stitching together separate tools for monitoring, alerting, and status communication, Better Stack handles all three. Better Stack's telemetry bundles for centralized log management start at $30/month, or $25 a month billed yearly. Unlike Checkly, Better Stack does not support Playwright-based browser scripts or monitoring-as-code workflows, making it better suited for teams that prioritize incident response speed over deep synthetic testing. Best for small-to-mid-size engineering teams that want monitoring plus incident management without managing multiple vendors.
Grafana Cloud provides a free tier with managed Prometheus, Loki, and Tempo backends, plus Grafana's synthetic monitoring module built on the open-source Grafana Agent. Grafana Cloud synthetic checks support HTTP, DNS, TCP, and multi-step scripted checks with configurable probe locations. The platform uses PromQL, LogQL, and TraceQL as native query languages and supports OpenTelemetry ingestion natively. For teams already running a Prometheus/Grafana observability stack, adding synthetic monitoring requires zero vendor switching. Grafana Cloud's pricing is consumption-based with no per-host fees, making costs predictable for monitoring-heavy workloads. The limitation compared to Checkly is that Grafana synthetic monitoring lacks native Playwright browser automation and CI/CD pipeline integration depth.
Sentry focuses on error tracking and performance monitoring for frontend and backend applications. The Developer tier is free with 5K errors per month, while the Team plan starts at $26/month and Business at $80/month with event-based billing. Sentry captures JavaScript errors, stack traces, session replays, and performance spans, providing visibility into what breaks in production. Sentry complements rather than replaces Checkly: where Checkly proactively checks if pages load correctly, Sentry reactively captures errors when real users hit problems. Teams running both get proactive and reactive coverage. Sentry is the best fit for frontend-heavy teams that need deep error diagnostics with source map support and release tracking.
New Relic delivers full-stack observability with 50+ capabilities including synthetic monitoring, APM, infrastructure monitoring, and AI-powered anomaly detection. New Relic's synthetic monitors support scripted browsers, API tests, and step monitors across managed global locations. Standard is $10 for the first full platform user and $99 per additional user a month, with 100 GB of free data ingest per month and $0.40 per GB beyond it. New Relic supports OpenTelemetry natively and provides NRQL, a SQL-like query language, for ad hoc data exploration. The platform is the most direct enterprise-grade alternative to Checkly for teams that need synthetics bundled with distributed tracing, log correlation, and vulnerability management. New Relic is best for large organizations that want a single platform consolidating synthetic checks, APM traces, and infrastructure metrics.
SigNoz is a self-hosted, open-source observability platform built natively on OpenTelemetry. SigNoz Community Edition is free under Apache 2.0, while SigNoz Cloud offers a paid Teams plan at $49/month including $49 of ingestion credits and paid plans starting at $0.30 per GB for logs and metrics ingestion. The platform provides metrics, traces, and logs in a single UI with ClickHouse as its storage backend. SigNoz does not include built-in synthetic monitoring, but teams can feed Playwright test results into SigNoz via OpenTelemetry spans for end-to-end visibility. The primary advantage is zero vendor lock-in: all data stays in your infrastructure with full query access. SigNoz is the best choice for engineering teams that want complete data ownership and are comfortable self-hosting their observability stack.
Honeycomb specializes in distributed tracing and high-cardinality event analysis. The free tier includes 20 million events per month with 60-day retention, and the Pro plan starts at $150/month for higher volumes and longer retention. Honeycomb's query engine excels at slicing trace data across arbitrary dimensions without pre-defined indexes, making it powerful for debugging complex microservice architectures. Unlike Checkly's outside-in synthetic approach, Honeycomb provides inside-out observability by analyzing actual production traffic patterns. Honeycomb supports OpenTelemetry natively and is the strongest option for teams debugging latency issues, cascading failures, or intermittent errors across distributed systems where traditional synthetic checks cannot replicate real traffic complexity.
Architecture and Approach Comparison
Checkly pioneered the monitoring-as-code approach, where synthetic checks are defined as Playwright test scripts stored in version control and executed through CI/CD pipelines. This developer-centric model contrasts sharply with the traditional dashboard-driven approach used by Datadog, New Relic, and Better Stack, where monitors are configured through a web UI. Grafana Cloud bridges both worlds with Terraform providers and API-driven configuration alongside its Grafana dashboard interface. SigNoz and Honeycomb take a fundamentally different architectural stance: instead of synthetic probes, they instrument actual application traffic using OpenTelemetry SDKs and analyze real production data. SigNoz uses ClickHouse for columnar storage optimized for time-series queries, while Honeycomb uses a custom column-oriented storage engine built for high-cardinality trace analysis. The core trade-off is proactive versus reactive: Checkly and Datadog synthetics detect problems before users do, while Honeycomb and SigNoz surface issues from real user traffic after they occur.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Free Tier | Paid Plans | Key Differentiator |
|---|---|---|---|
| Checkly | Hobby: 10 monitors, 1K browser checks | Starter $24/mo, Team $64/mo | Monitoring-as-code with Playwright |
| Datadog | Free for up to 5 hosts | Infrastructure Pro $15 per host per month billed annually ($18 on demand) | Full-stack APM + synthetics unified |
| Better Stack | Free monitoring tier | Responder $34/mo ($29 billed annually), telemetry from $30/mo | Status page + monitoring + incidents |
| Grafana Cloud | Yes (generous free tier) | Consumption-based, no per-host fees | Open-source Prometheus/Loki/Tempo stack |
| Sentry | 5K errors/mo free | Team $26/mo, Business $80/mo | Error tracking + session replay |
| New Relic | 100 GB ingest free | Standard from $10 for the first full platform user; $99 per additional user | 50+ capabilities, NRQL query language |
| SigNoz | Open source self-hosted | Cloud from $0.30/GB | OpenTelemetry-native, ClickHouse backend |
| Honeycomb | 20M events/mo free | Pro from $150/mo | High-cardinality distributed tracing |
When to Consider Switching
Switch to Datadog or New Relic if your team needs synthetic monitoring combined with APM, logs, and infrastructure metrics under one vendor and can absorb usage-based pricing. Choose Better Stack if uptime monitoring with integrated incident management and status pages matters more than scripted browser testing. Move to Grafana Cloud if you are invested in the Prometheus ecosystem and want to avoid proprietary lock-in while keeping observability costs consumption-based. Pick SigNoz if data sovereignty and self-hosting are non-negotiable requirements for your compliance posture. Use Sentry alongside Checkly rather than replacing it, since the two cover different failure modes — proactive synthetic checks versus reactive error capture. Select Honeycomb when debugging distributed system performance across microservices is the primary use case and traditional dashboard-based monitoring falls short.
Migration Considerations
Checkly tests are Playwright scripts, which means they are portable JavaScript/TypeScript code that can be version-controlled and reused outside Checkly's platform. Migrating to Datadog or New Relic synthetics requires rewriting tests in each platform's proprietary scripted browser format, since neither supports raw Playwright natively. Grafana Cloud synthetic checks use a different scripting model based on k6 browser. Export your Checkly alert channel configurations and notification rules before switching, since alerting integrations with Slack, PagerDuty, and OpsGenie need full reconfiguration on any new platform. Plan a 2-4 week parallel-run period where both Checkly and the new platform monitor the same endpoints, comparing alert accuracy and response latency before cutting over completely. Budget additional time for re-creating dashboard layouts and SLA reporting if your team relies on Checkly's analytics features.