Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What HelixDB states |
|---|---|
License | Apache License 2.0 for the helix-db repository |
Deployment | Embedded in a Rust, TypeScript or Python process; a single-node local server in Docker or Podman on memory, disk or S3-compatible storage; or Helix Cloud, the managed, highly available option |
Query interface | Official SDKs for Rust, TypeScript, Python and Go; queries are built with typed SDK builders or written as JSON and sent to POST /v2/query, with no compile or deploy step |
Transactions | Each request runs as one ACID transaction with serializable snapshot isolation; a write batch commits or rolls back as a whole, and conflicting writes fail at commit |
Helix Cloud access | Read-only or read-write API keys for direct gateway requests; WorkOS sign-in or scoped service credentials for MCP and CLI; TLS in transit and the object-storage provider's server-side encryption at rest |
Our take
HelixDB is worth a proof of concept if your application needs to walk relationships and then rank results by meaning or keywords inside that set, such as agent memory scoped to one user or retrieval limited to the records a user may see. If your search does not depend on relationships between records, its main design choice gives you little.
Evaluate HelixDB
Where it stands out
Traverse, then search, in one request. A graph traversal or an indexed tenant property defines the exact candidate set, and vector or BM25 ranking runs only inside it in the same request. Nothing outside that set is returned, and vector and text indexes can be partitioned per tenant, which suits permission-aware retrieval.
One store instead of three. Data is one labeled property graph, and vector, text and secondary indexes are access paths over its node and edge properties. HelixDB says there is no separate graph store, vector store or search cluster to keep in sync, and relationships are searchable as well as entities.
A worked pattern for agent memory. HelixDB's guidance is to store memories as nodes with indexed tenant and lifecycle fields such as isLatest or expiresAt, use edges for provenance and version history, and recall by traversing to allowed memories before running vector and BM25 search, all in one transaction.
Built for coding agents. The helix chef command installs the HelixDB query skills and docs MCP, scaffolds a project, starts a local instance and hands off to a coding agent. On Helix Cloud, agents can query through one MCP endpoint where every write and admin change needs a confirmation step.
Start small, move to managed later. Every deployment mode runs the same queries through the same SDKs, so a team can prototype embedded or in Docker and later point the same code at Helix Cloud. On Helix Cloud, object storage is the durable system of record, a single writer commits every transaction, and reader nodes auto-scale with query load.
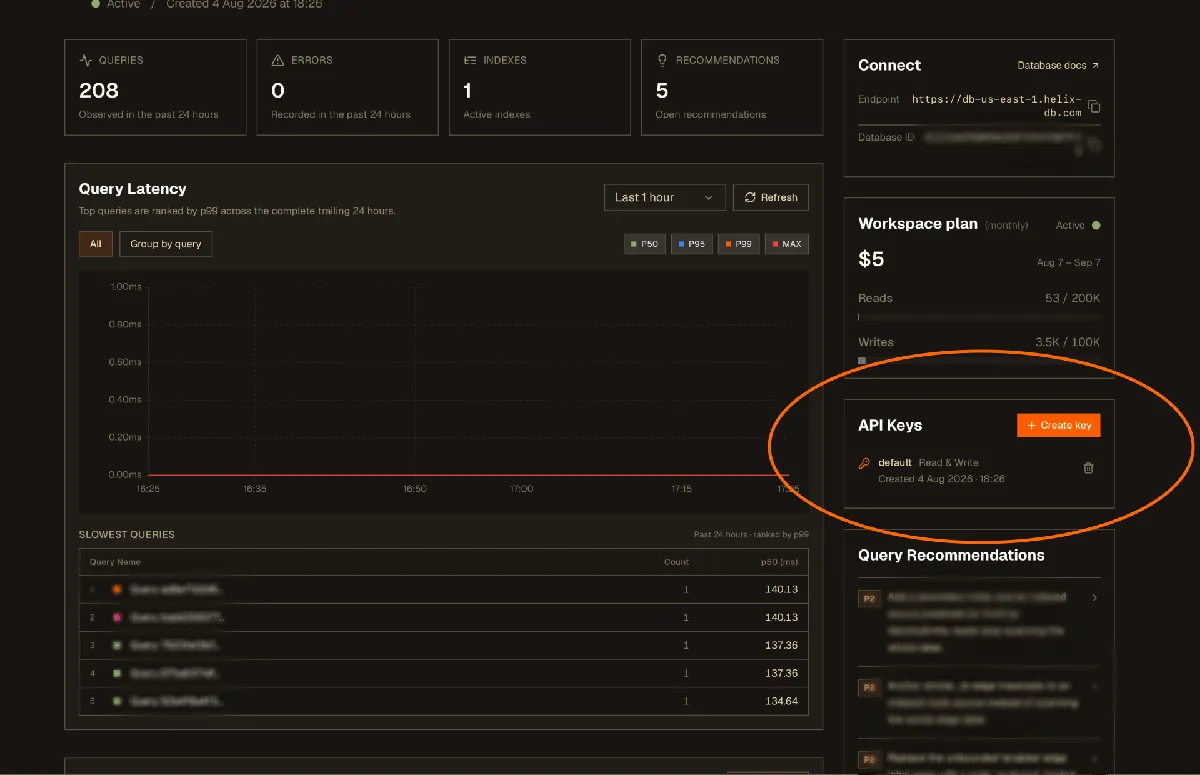
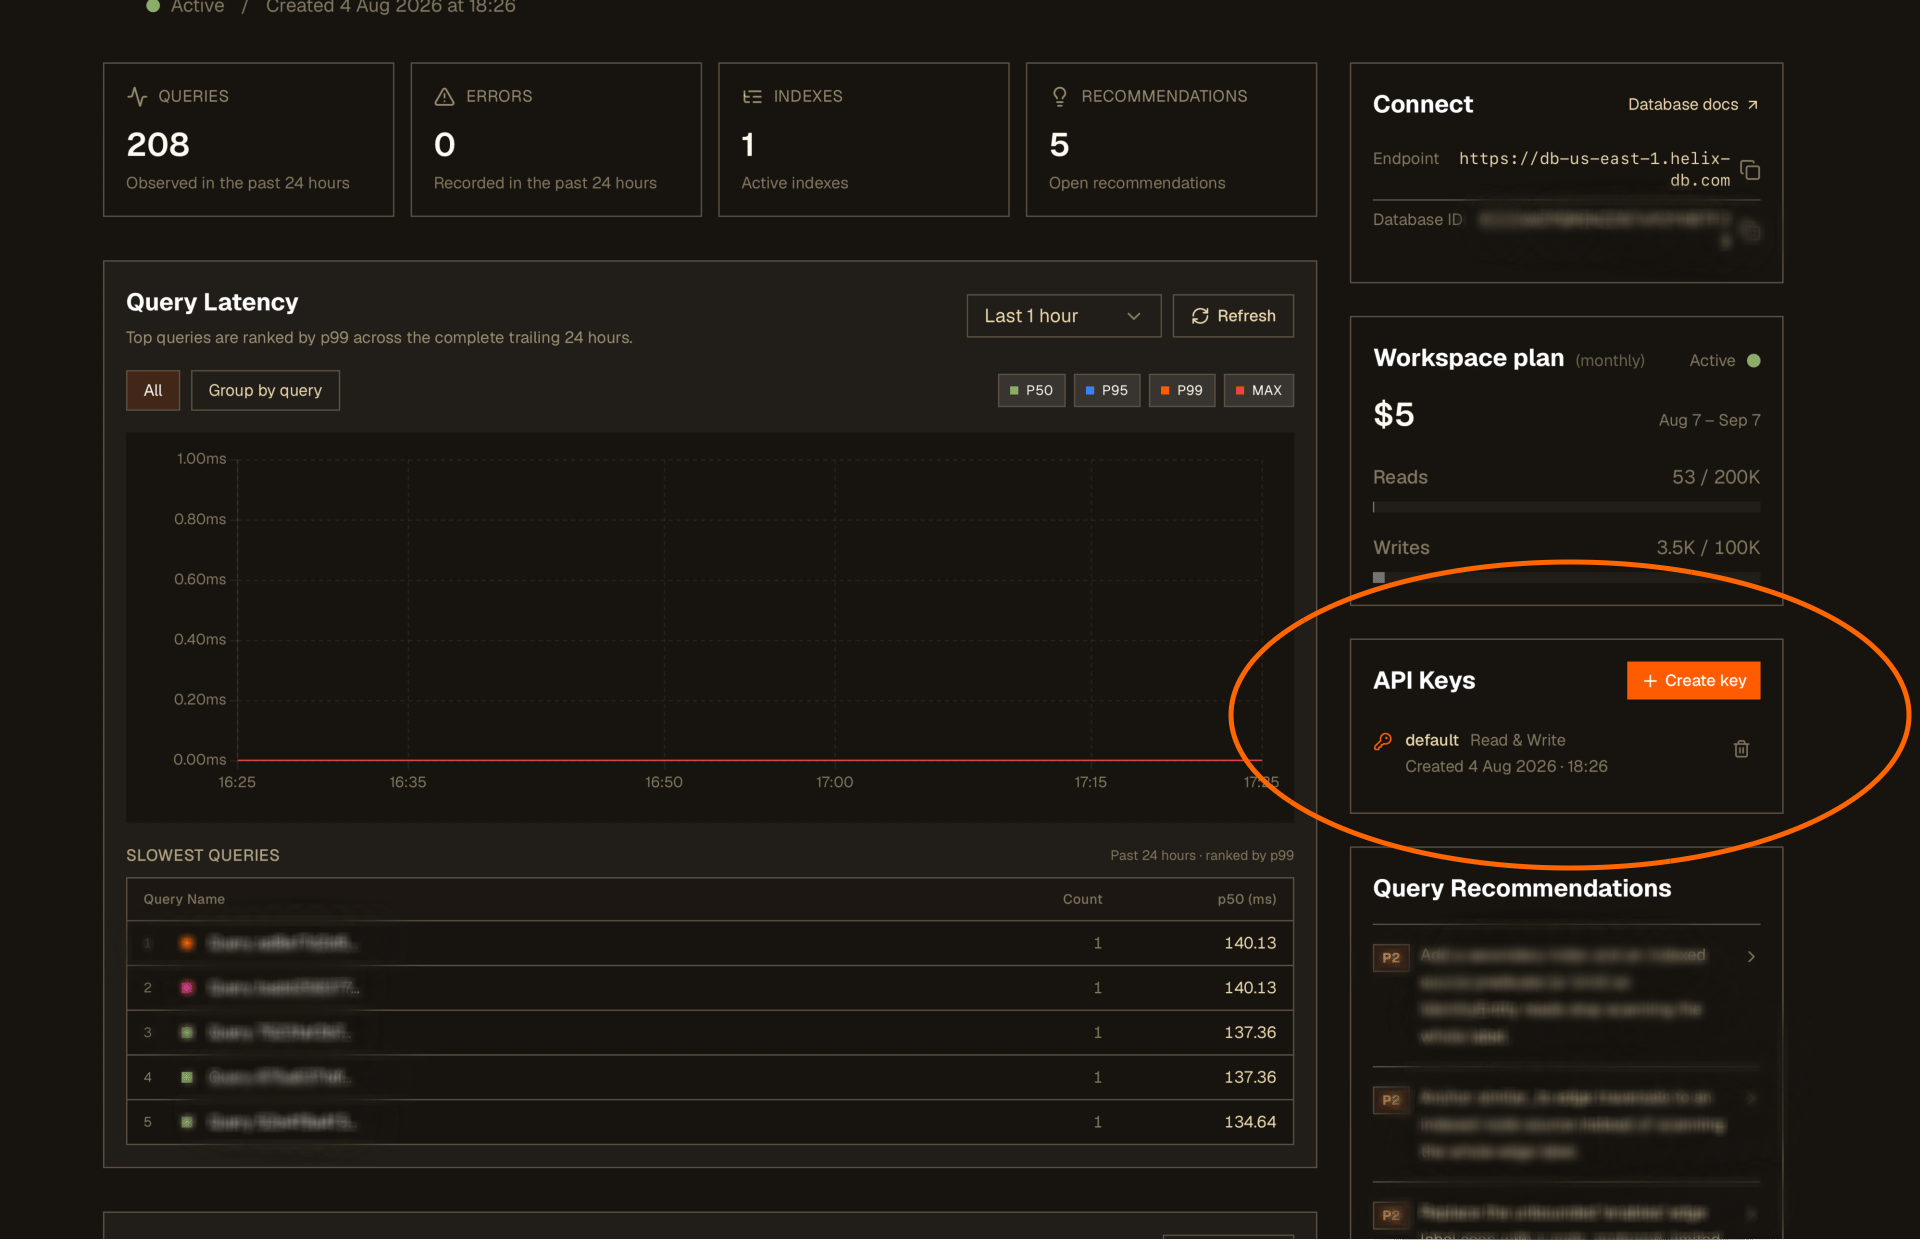
Product screenshot
Trade-offs to weigh
Your application owns embeddings and ranking fusion. HelixDB does not generate embeddings or rerank results. Your code computes embeddings and, if it runs both searches, combines the vector and BM25 results, so plan for an embedding pipeline alongside the database.
Replica reads can lag on Helix Cloud. Reads served by reader nodes can briefly lag the writer. Workloads that read their own writes, such as saving and then recalling a memory, need to send a writer-only request.
Enterprise controls are still on the roadmap. HelixDB lists SSO/SAML, role-based access, audit logs and AWS PrivateLink as roadmap items for Helix Cloud, which matters if your security review requires them before purchase.
The query interface has changed. The earlier HelixQL (HQL) language is archived, so older examples and code written in it need rework. Cypher reads and CRUD are supported only in source builds, through POST /v2/cypher, embedded clients and helix cypher.
Some deployment paths are not ready yet. Bring-your-own-cloud (BYOC) and cloud marketplace deployments are marked coming soon, and the Go SDK connects over HTTP only rather than running embedded.
Pricing and plan conditions
Self-hosted and embedded deployments cost only the infrastructure you run them on. Helix Cloud is the paid managed service, and its entry price is tied to read and write volume rather than to storage.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Self-hosted or embedded (Apache 2.0) | Free | The open-source engine, run embedded or as your own single-node server |
Helix Cloud (entry plan) | From $5/month | 200K reads and 100K writes, unlimited storage and opt-in overage |
Helix Cloud Growth | Billed by the hour | A dedicated cluster |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
1.6k GitHub commits 90d6.3k GitHub stars0 vulnerabilities across 2 packages
See all signals from 5 sources
npm · @helix-db/helix-db@3.2.0 · PyPI · helix-db@0.3.4
Alternatives to HelixDB
The reviewed substitutes for HelixDB among the vector databases, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Pinecone
- Pinecone is the managed-SaaS answer to the same retrieval job, so the decision reads as self-hosted HelixDB against Pinecone's consumption pricing and zero operations. Both are bought to do one thing -- store embeddings and return nearest neighbours -- and a team picks one.Applies to: Production vector search. Pinecone stands in when nobody wants to operate a database and consumption pricing is acceptable; HelixDB stands in when the data must stay on your own infrastructure or the graph model matters.
- LanceDB
- LanceDB is the other Rust-built embedded vector store competing for the same single-binary, low-latency developer deployment: no server to run, storage on local disk or object storage, open source. Two products solving one problem the same way.Applies to: Embedding search inside an application with no separate database to operate. LanceDB stands in when the columnar format and object-storage backing decide; HelixDB stands in when the graph model is wanted alongside the vectors.
- Zilliz
- Zilliz Cloud is the fully managed path for the same enterprise vector workload, competing directly with HelixDB's pitch to buyers who want availability and scale without operating the engine. Same job, opposite operating model.Applies to: Enterprise-scale vector search. Zilliz stands in when a managed service with an availability guarantee is the requirement; HelixDB stands in when the workload is self-hosted or the graph traversal is central.
- ChromaDB
- The AI-native open-source embedding database for LLM applications
- Milvus
- Milvus is the incumbent open-source choice for production vector search at scale, so it is the benchmark any self-hosted evaluation puts HelixDB against. Same licence model, same deployment question, one of them gets installed.Applies to: Self-hosted vector search at production scale. Milvus stands in when proven scale and ecosystem maturity decide; HelixDB stands in for a smaller footprint and the graph model.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- pgvector
- Teams already running Postgres frequently add pgvector rather than adopt a dedicated engine, trading recall and latency ceilings for one fewer system to operate. That is a real substitution but only under that condition: without an existing Postgres, pgvector is not a candidate at all.Applies to: Moderate-scale similarity search over data already in a Postgres OLTP database, where relational joins matter more than peak ANN throughput or graph traversal. pgvector stands in for HelixDB there; HelixDB stands in once scale, latency or the graph model outgrow it.
- FAISS
- FAISS is raw in-process approximate-nearest-neighbour indexing with no persistence, no CRUD and no server, so it substitutes only where the application already supplies its own storage layer and just needs the index. Where that holds it removes the reason to run a database at all; where it does not, it is not comparable.Applies to: Batch or read-mostly similarity search over a largely static embedding set inside one process or an offline pipeline. FAISS stands in for HelixDB there; HelixDB stands in as soon as updates, persistence or concurrent access are required.
- MongoDB Atlas Vector Search
- Atlas folds vector search into a document database a team may already run, which substitutes for a dedicated engine when the operational data is in MongoDB and nobody wants a second store to operate and keep in sync. The condition is that prior commitment; without it the comparison does not arise.
See detailed alternatives analysis
If you are evaluating HelixDB alternatives, you are likely looking for a database or developer tool that can handle graph traversals, vector similarity search, or both within a single system. HelixDB is an open-source graph-vector database written in Rust under the AGPL-3.0 license, with over 4,000 GitHub stars and a focus on RAG and AI application workloads. While its native Rust implementation delivers strong performance for combined graph-vector queries, teams may need alternatives that offer broader ecosystem support, different data models, or managed hosting options.
Top Alternatives Overview
Kubernetes is the industry-standard container orchestration platform with over 123,000 GitHub stars and backing from the CNCF. While not a database itself, Kubernetes is the infrastructure layer many teams use to deploy and scale databases like HelixDB, Neo4j, or Pinecone in production. It provides self-healing, horizontal scaling, and automated rollouts across any cloud provider. Choose this if you need a robust orchestration layer to run your graph-vector database at scale rather than a database replacement.
Docker is the containerization platform with over 71,000 GitHub stars that simplifies packaging and deploying applications, including databases. Docker Desktop starts free for individuals, with team plans from $9/month per seat. It provides consistent development environments, verified container images, and a catalog of over 14 million images on Docker Hub. Choose this if you need a reliable way to package and distribute your database workloads across development and production environments.
Memcached is a free, open-source distributed memory caching system licensed under BSD-3-Clause with over 14,000 GitHub stars. It serves as an in-memory key-value store for caching database call results, API responses, and rendered pages. Memcached is written in C and focuses purely on speed and simplicity for caching use cases. Choose this if you need a lightweight, high-throughput caching layer to reduce load on your primary database rather than a full graph-vector store.
Appsmith is an open-source low-code platform for building internal tools, with a free self-hosted option and paid plans starting at $15/month. It provides drag-and-drop UI components, database connectors, and JavaScript customization for building admin panels and dashboards. Choose this if you need to rapidly build internal tooling on top of your existing databases rather than replace your data layer.
Retool is a low-code platform used by over 27,000 organizations including Amazon and DoorDash for building internal tools. It connects to any database or API and offers drag-and-drop components for admin panels, dashboards, and CRUD applications. The free tier covers basic needs, with paid plans starting at $75/month. Choose this if you want a polished, enterprise-ready internal tool builder with broad database connectivity.
Streamlit is an open-source Python framework for building interactive data applications, ideal for data scientists and ML engineers. It requires no frontend experience and turns Python scripts into shareable web apps with just a few lines of code. The community edition is completely free and self-hosted. Choose this if you need to build data exploration interfaces or ML model demos that connect to your graph or vector database.
Architecture and Approach Comparison
HelixDB takes a unique architectural approach by combining graph and vector data types natively in a single Rust-based engine. Queries are compiled rather than interpreted, which reduces latency for combined graph traversal and vector similarity operations. The database runs as a single binary with SSD-backed storage, available in both a local Helix Lite edition and a cloud-hosted Helix Enterprise variant. Its query language supports both graph pattern matching and vector search within the same query context, which eliminates the need to maintain separate databases for relational and embedding-based lookups.
Kubernetes and Docker operate at an entirely different layer of the stack. Kubernetes manages container scheduling, service discovery, and horizontal scaling across clusters, while Docker handles container packaging and runtime isolation. Neither stores application data directly, but both are essential infrastructure for deploying databases like HelixDB in production. Teams running HelixDB at scale will likely use both Docker for containerization and Kubernetes for orchestration.
Memcached sits in front of databases as a caching tier rather than replacing them. It stores data purely in memory with no persistence guarantees, using a simple key-value model. Where HelixDB provides rich graph traversals and vector similarity queries, Memcached offers sub-millisecond reads for frequently accessed data. Many production architectures use Memcached alongside a primary database like HelixDB to reduce query load.
Appsmith, Retool, and Streamlit are application-layer tools that consume data from databases rather than storing it. Appsmith and Retool provide visual builders for internal tools with connectors to PostgreSQL, MySQL, MongoDB, and REST APIs. Streamlit uses pure Python to create data dashboards. These tools complement HelixDB rather than replace it, providing the UI layer for data stored in graph-vector databases.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Pricing Model | Starting Price | Notes |
|---|---|---|---|
| HelixDB | Open Source (AGPL-3.0) | Free | Self-hosted free, Helix Cloud available |
| Kubernetes | Open Source (Apache-2.0) | Free | Managed services (EKS, GKE) bill per cluster |
| Docker | Freemium | Free / $9/mo per seat | Personal free, Pro $9/mo, Team $15/mo, Business $24/mo |
| Memcached | Open Source (BSD-3-Clause) | Free | Fully free, managed options via AWS ElastiCache |
| Appsmith | Freemium | Free / $15/mo | Free self-hosted, Business at $15/user/month |
| Retool | Freemium | Free / $75/mo | Free tier available, Team starts at $75/month |
| Streamlit | Open Source | Free | Community edition fully free and self-hosted |
HelixDB and Memcached carry no licensing costs for self-hosted deployments. Docker's free tier covers individual developers, with per-seat pricing for teams. Retool has the highest entry point at $75/month for team functionality. For teams seeking a fully open-source stack, HelixDB combined with Kubernetes and Streamlit provides a zero-cost foundation.
When to Consider Switching
Consider moving away from HelixDB if your application has outgrown its current ecosystem maturity. With approximately 4,000 GitHub stars, HelixDB's community is focused compared to established tools like Kubernetes (121,000 stars) or Docker (71,000 stars), which means a limited number of community-contributed integrations, tutorials, and third-party tooling. If your team needs extensive connector libraries or a large pool of developers with prior experience, more established databases may reduce ramp-up time.
Teams that only need vector search without graph traversals may find purpose-built vector databases like Pinecone, Weaviate, or Qdrant to be more optimized for that specific workload. Similarly, if your use case is purely graph analytics without embedding-based queries, mature graph databases like Neo4j or Amazon Neptune offer richer ecosystems and managed hosting options.
If your team relies heavily on the AGPL-3.0 license terms being compatible with your deployment model, verify that HelixDB's copyleft requirements align with your distribution strategy. Some organizations require permissive licenses like Apache-2.0 or MIT for their infrastructure dependencies.
Migration Considerations
Migrating away from HelixDB requires planning around its dual graph-vector data model. Export your graph relationships and vector embeddings separately, as most target databases will not natively support both in a single system. For graph data, Neo4j accepts CSV imports and supports the Cypher query language, while vector embeddings can be loaded into Pinecone, Weaviate, or Qdrant via their Python SDKs.
If you are moving to a general-purpose database like PostgreSQL with the pgvector extension, you gain SQL compatibility and broad tooling support, but lose HelixDB's compiled query optimization for graph traversals. Plan for query rewrites, as HelixDB's custom query syntax does not map directly to SQL or Cypher.
Expect a migration timeline of 2 to 4 weeks for small datasets (under 1 million records) and 4 to 8 weeks for production workloads with complex graph relationships. Budget additional time for rewriting application code that depends on HelixDB's combined graph-vector query API. Test throughput carefully, as the performance characteristics of compiled graph-vector queries in Rust will differ substantially from interpreted queries in other systems.