Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Modal states |
|---|---|
Workloads | Inference through OpenAI-compatible endpoints, optimized models or custom stacks; single- and multi-node GPU training; Sandboxes for coding agents, RL rollouts and untrusted code; and Functions for parallel or asynchronous batch work. |
Developer interface | The Python SDK includes the Modal CLI. JavaScript/TypeScript and Go SDKs support Sandboxes, deployed Functions and some platform resources; the SDK repository is Apache-2.0 licensed. |
Capacity and operations | Modal states that its infrastructure spans 20+ clouds, provides GPU access without quota requests or reservations, and can burst to thousands of GPU and CPU resources before scaling back to zero. |
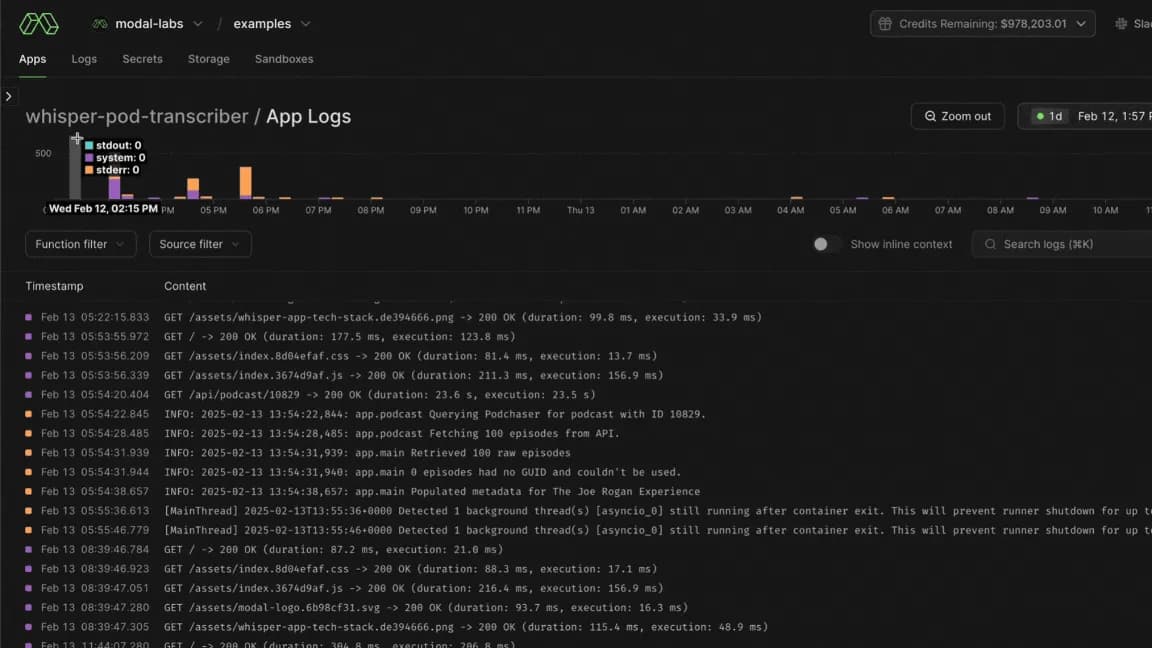
Security and observability | The site lists workload isolation and data-residency controls. The plan comparison lists SOC 2 compliance on Starter, Team and Enterprise; Modal also provides container-level logs and metrics and can export traces to OpenTelemetry providers. |
Our take
Choose Modal when a Python team needs GPU capacity or bursts of compute without operating clusters or reserving capacity, especially where demand is spiky or unpredictable. For steady, round-the-clock workloads, model the application-load time, the configurable idle timeout and requested-resource floor before committing; Modal says its per-hour prices can appear higher than traditional compute.
Evaluate Modal
Comparisons
Where it stands out
Sandboxes for agent workloads. Modal describes programmatically creating millions of concurrent sandboxes in under a minute, with custom images or dependencies and snapshot-and-restore support.
Model-loading infrastructure. A distributed filesystem loads container images, model weights and datasets at full bandwidth wherever Functions run; Modal also describes a custom container runtime and image system for large images and GPU scheduling.
Short-lived execution model. Modal says containers spin up and down in 1–2 seconds, have no minimum usage time per instance, and stop charging after the application scales down to zero containers.
Product screenshot

Trade-offs to weigh
Load and idle time are billable. Modal bills during application loading and input processing. Containers remain alive for 60 seconds after the last input by default, and that time is billed; the timeout is configurable. Charges use the greater of requested or used resources, with minimum requests of 128 MiB memory and 0.125 CPU cores per container.
Execution options affect the base rate. The plan comparison lists region selection at 1.15–1.75× base prices and non-preemptible execution at 3× base prices on all plans.
Shared Endpoints are outside included compute. They are billed per token from the first request. Modal says Starter's free Shared Endpoint usage ended September 1, 2026, so token charges can appear before the $30 compute allotment is exhausted.
Pricing and plan conditions
Starter and Team combine a monthly fee with pay-as-you-go compute and monthly included compute for Functions, Sandboxes and Notebooks. Workspace budgets can limit monthly spend. AWS, GCP and Azure credits cannot be applied to Modal usage; Enterprise has custom compute pricing.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | Included each month | Limits and features |
|---|---|---|---|
Starter | $0 + compute / month | $30 / month free compute; 1 TiB / month network egress | Up to 3 seats; 100 containers; 10 GPU concurrency; 200 deployed apps; 5 deployed crons; 1-day log retention; Community Slack access. |
Team | $250 + compute / month | $100 / month free compute; 10 TiB / month network egress | Unlimited seats; 5,000 containers; 50 GPU concurrency; 1,000 deployed apps; 30-day log retention; custom domains, static IP proxy, RBAC, three-version rollbacks and environment-level budgets. |
Enterprise | Custom compute | Custom included compute; 100 TiB / month network egress | Volume-based discounts; unlimited seats; custom GPU concurrency; HIPAA compatibility, SSO and audit logs; private Slack support, embedded ML engineering services and AWS/GCP marketplace committed spend. |
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Resource | Published rate |
|---|---|
GPU tasks | B300 $0.001972 / sec; B200 $0.001736 / sec; H200 SXM $0.001261 / sec; H100 SXM5 $0.001097 / sec; RTX PRO 6000 $0.000842 / sec; A100 80 GB $0.000694 / sec; A100 40 GB $0.000583 / sec; L40S $0.000542 / sec; A10 $0.000306 / sec; L4 $0.000222 / sec; T4 $0.000164 / sec. |
CPU and memory | Functions: CPU $0.0000131 / physical core / sec and memory $0.00000222 / GiB / sec. A physical core equals 2 vCPU. Sandboxes and Notebooks: CPU $0.00003942 / core / sec and memory $0.00000667 / GiB / sec. |
Volumes and egress | Volumes cost $0.09 / GiB / month and include 1 TiB / month free. Network egress costs $0.04 / GiB, with plan-dependent included usage. |
Modal offers free compute-credit programs for early-stage startups. Graduate students, labs and researchers can receive up to $10k in free compute credits.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
10.6M PyPI weekly downloadsNot available Google Trends search interest0 vulnerabilities across 1 package
See all signals from 5 sources
Three-month score against stable baseline terms—not search volume or adoption.
PyPI · modal@1.6.2
Alternatives to Modal
The reviewed substitutes for Modal among the model hosting platforms, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Replicate
- Modal is used rather than Replicate for programmable GPU jobs, custom model-serving code, and batch AI processing workloads. **Modal** is a serverless cloud platform for AI and ML workloads built around GPU containers, scheduled jobs, model serving, and batch processing.
- Anyscale
- Both run GPU AI workloads as managed infrastructure; Anyscale is Ray-based, Modal is serverless containers.Applies to: Running GPU training and inference jobs on managed infrastructure.
- Ollama
- Modal is chosen instead of Ollama for workloads where inference is one step in a Python pipeline that wants a single compute platform. Choose it when inference is one job among several in a Python pipeline and you want one platform for all of them, rather than a dedicated runtime.
- vLLM
- Modal is named among the 2026 hosted-inference leaders, and against vLLM it is the same build-or-buy decision: provision GPUs, install an engine, handle scaling and updates and troubleshoot OOM crashes, or call an API and let the vendor carry it. The trade is zero operations against less control, vendor-managed compliance against lock-in, and higher steady-state cost against no idle waste. Conditional rather than direct, because the crossover is measurable -- roughly 1-2 billion tokens a month on a single GPU -- and the answer flips either side of it.Applies to: Running inference for an open-weight model. Modal stands in for vLLM when the team will not own GPU operations and the volume is intermittent enough that idle capacity would be waste; vLLM stands in when the GPUs are already there, the volume is sustained, or sovereignty rules out a vendor.
- Amazon SageMaker
- Modal replaces the inference-endpoint and batch-job part of SageMaker with serverless GPU compute a Python developer configures in code, while SageMaker is the broader managed ML platform with the compliance surface an enterprise buys it for. Independent write-ups treat Modal as a SageMaker alternative for that workload rather than for the whole platform.Applies to: Running model inference and scheduled GPU jobs without provisioning endpoints.
- Baseten
- Both run model workloads on managed GPUs, but Modal is a general serverless compute platform where you write the serving code and Baseten optimises the runtime for you. They compete when the workload is plain model serving and diverge when it is not.Applies to: Managed GPU inference for a self-supplied model
- Snowflake Cortex
- Cortex's pitch is not model quality -- it hosts other vendors' models -- but the perimeter: unified governance, permissions, telemetry and spend controls, with the text you pass in never leaving the Snowflake account boundary. A hosting platform is the other answer: send the data out to a managed endpoint and get a wider model catalogue and independent scaling. For the enrichment and analytics workload that sits on warehouse data, a team picks one. Modal is the general-purpose serverless GPU answer: arbitrary code and models on demand, with none of the governance plumbing and none of the constraint. The substitution is real only for the workload Cortex is scoped to; past that, Cortex is not in the running.