Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Snowplow states |
|---|---|
Deployment | Fully managed (Snowplow Platform) or self-managed and self-hosted (Self-Hosted Pipeline). |
License | Since January 8, 2024, new versions of the core pipeline are released under the Snowplow Limited Use License Agreement (SLULA). Other components are licensed differently depending on their purpose. |
Where data lands | Your warehouse, lakehouse or stream, or SaaS destinations of your choice. |
Data collection | Snowplow Platform lists 35+ first-party trackers and webhooks and in-stream enrichments. |
Support and SLAs | Snowplow Platform lists 24/7 customer support, collector and latency SLAs, and patches to critical CVEs. |
Our take
Snowplow fits a team that wants to own its behavioral event data: define its own event schemas, validate events on the way in, and model them in its own data platform. If you want that pipeline without running infrastructure, evaluate Snowplow Platform. If you need to keep running the pipeline yourself, plan around the Self-Hosted Pipeline and its license terms. If you only want ready-made analytics reports, this is more pipeline than you need.
Evaluate Snowplow
Comparisons
Where it stands out
Schemas and validation. Teams define and track custom events with their own validated schemas, so the data that reaches the warehouse follows a design the team controls rather than a vendor schema.
Enrichment built in. Snowplow states it offers more than 15 enrichments for the events it collects.
Real-time context for AI agents. Snowplow streams behavioral attributes to AI agents, integrates with LangChain, Bedrock, Vertex AI and Vercel, and can tell AI agent traffic apart from human visitors. Signals adds a profiles store and interventions on Snowplow Platform.
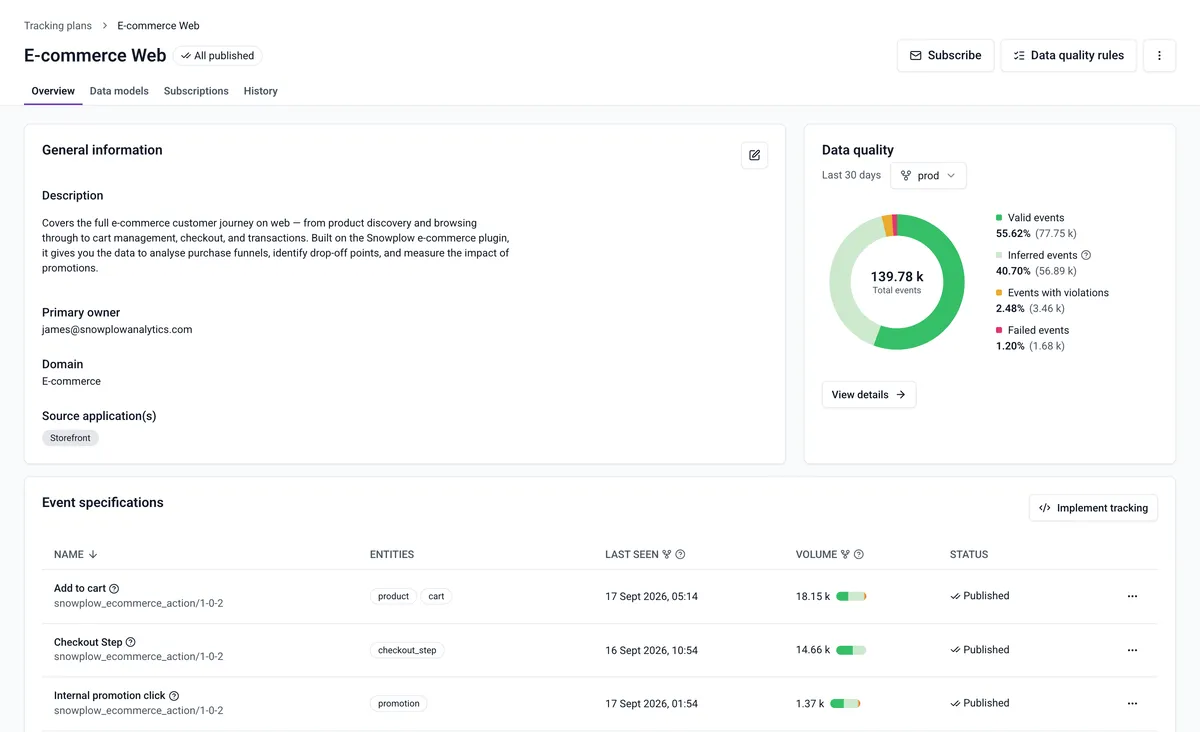
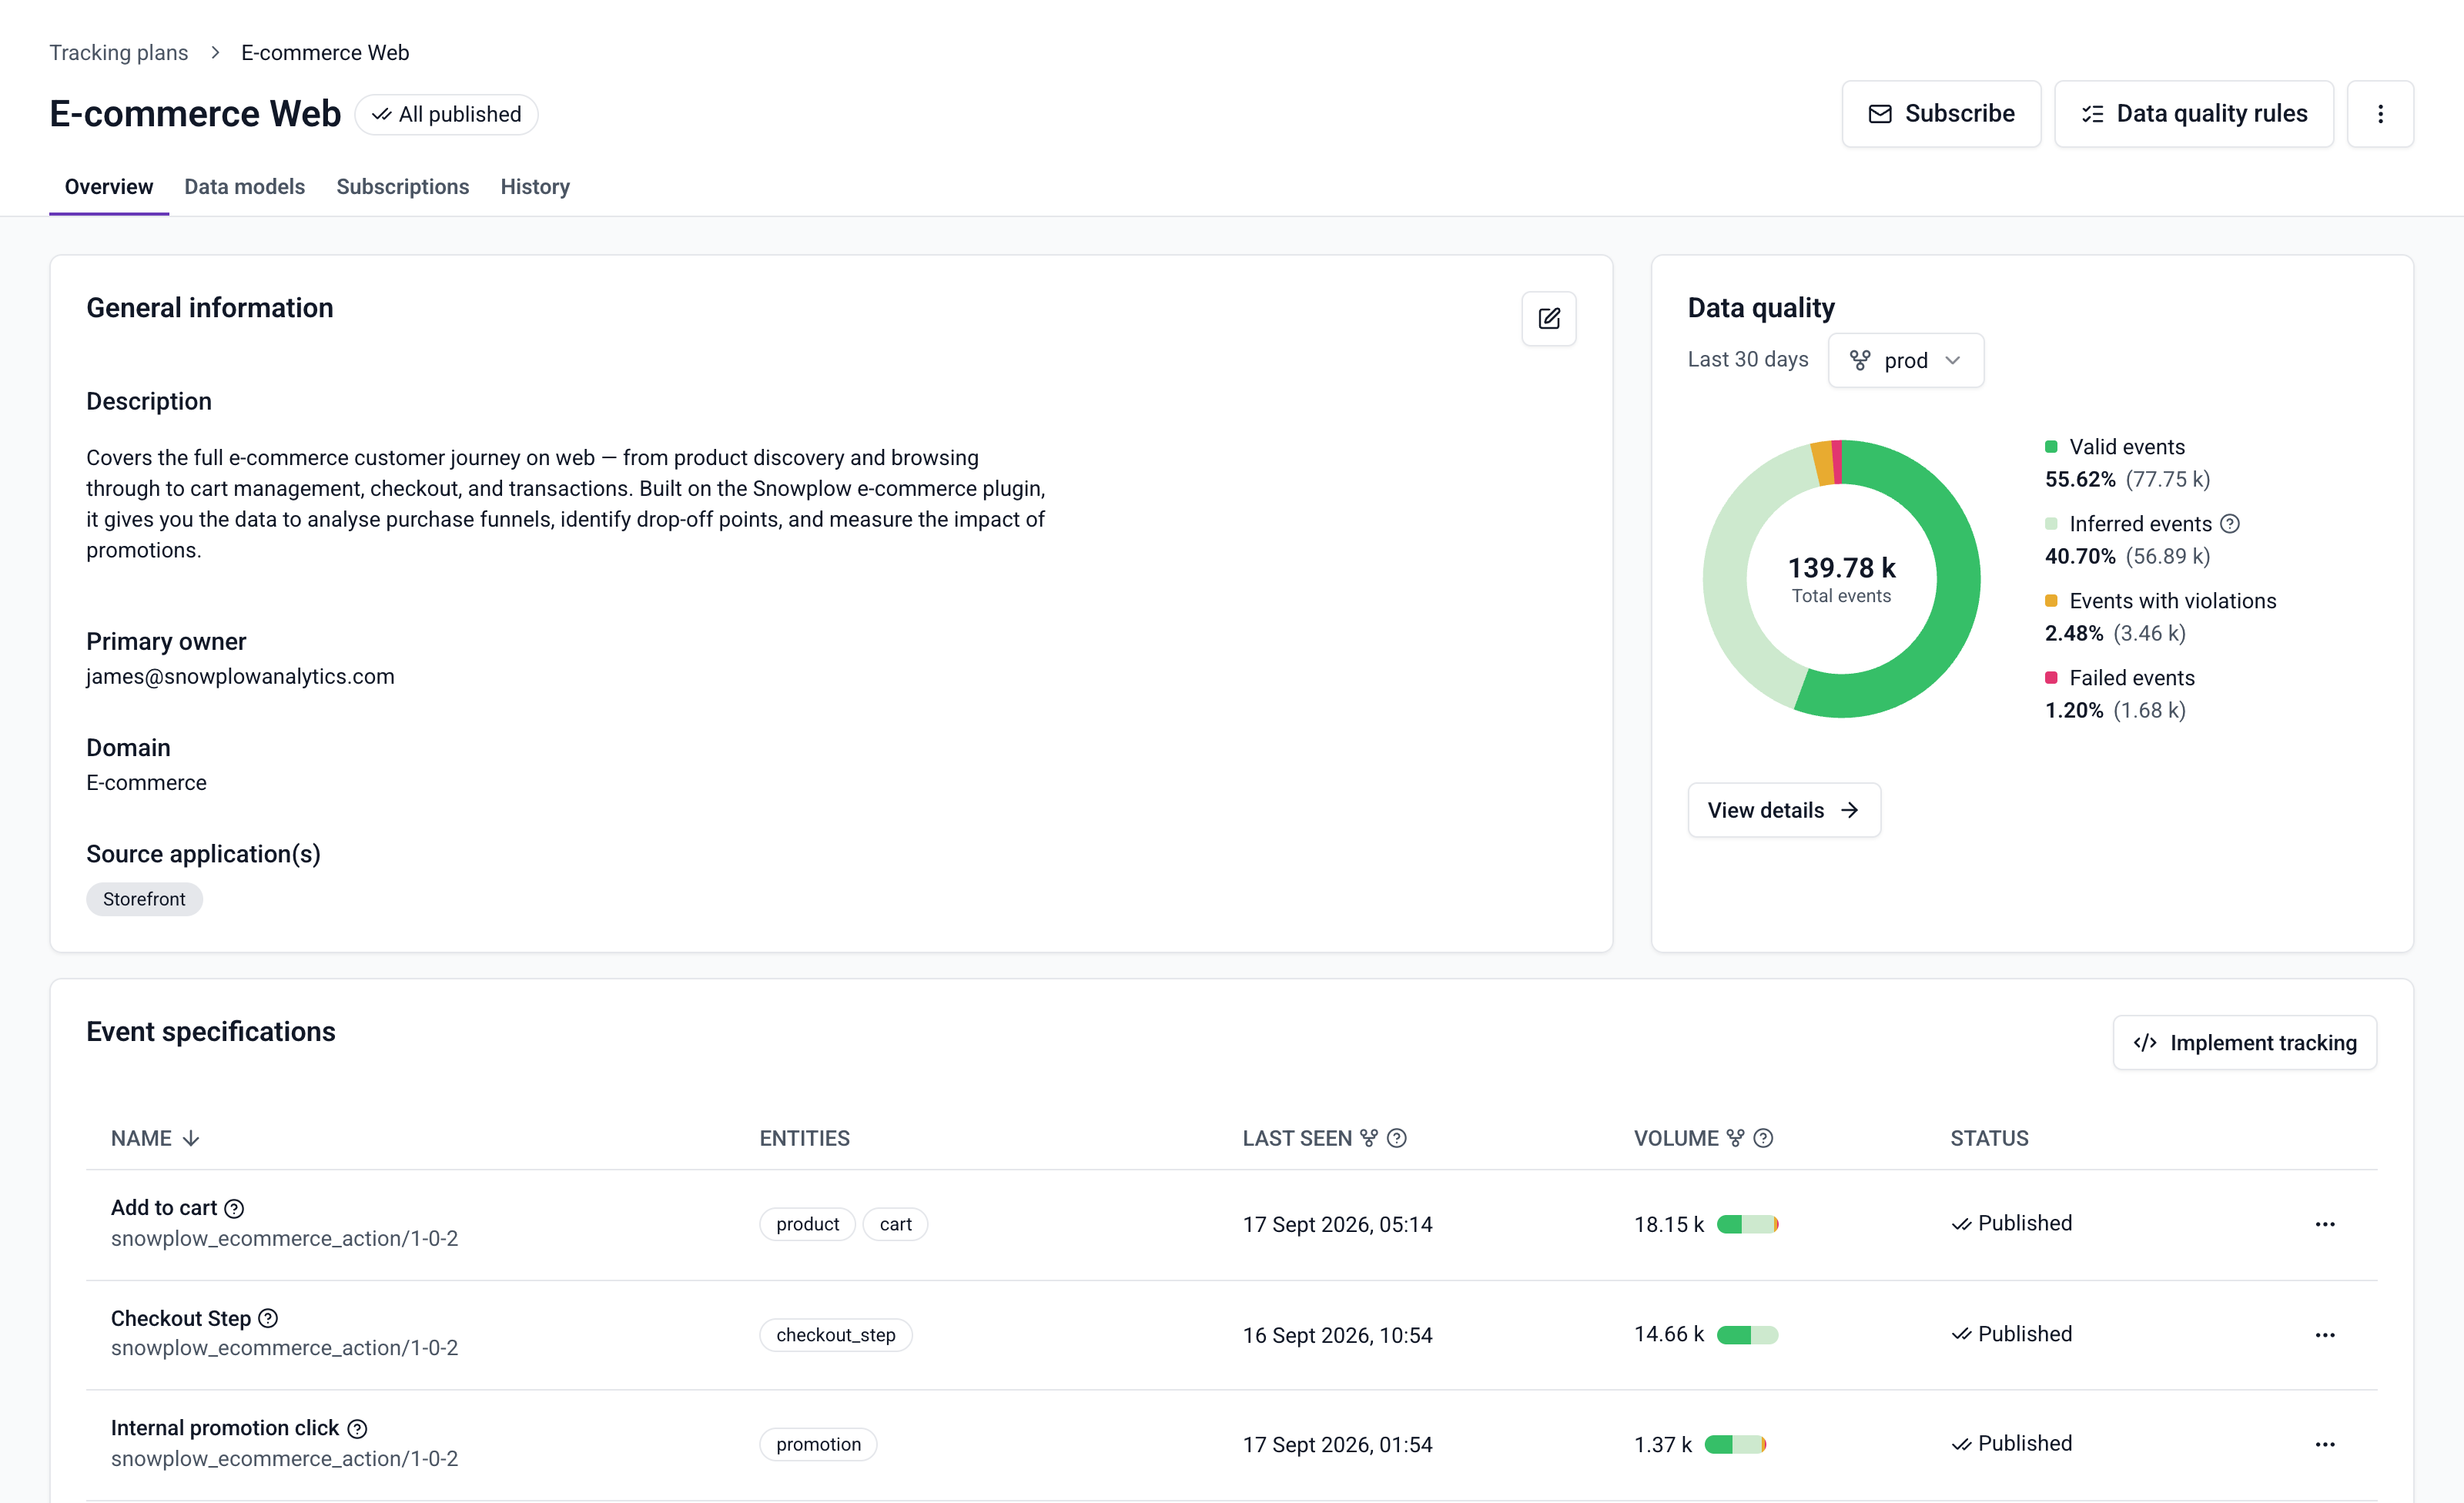
Tracking plans. Teams build and manage behavioral tracking plans in Event Studio.
Product screenshot
Trade-offs to weigh
Older open-source pipelines are frozen. Snowplow makes no security patches to versions that pre-date January 2024. If you run the pipeline in production, or in a way that competes with Snowplow, you need to contact Snowplow to use the current version.
Self-hosting means operating it yourself. The Self-Hosted Pipeline covers a single production pipeline that you manage and host, so your team carries the infrastructure work and cloud costs.
Schema ownership is ongoing work. Because events follow your own schemas, someone has to design, review and change those schemas as the product changes. The value of the data depends on that work.
No fixed price to plan against. A budget needs your expected monthly event volume, hosting choice and destinations before Snowplow can quote it. The free trial shows technical fit, such as whether events reach your warehouse, not the cost of a production workload.
Pricing and plan conditions
Snowplow says that, depending on what you choose, its rates are based on monthly event volume, hosting preferences, consumption or destinations, and that you only pay for what you use.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Cost basis | What it adds |
|---|---|---|
14-Day Free Trial | Free for 14 days; no credit card and no sales call to start | Full product and functionality: stand up a live pipeline, send events to your warehouse or AI agents, and work with it through the MCP server or Snowplow Assistant in the console. |
Self-Hosted Pipeline | Contact Snowplow | For previous open-source users: run a single Snowplow data pipeline in production, self-managed and self-hosted, without the non-commercial use restriction in SLULA 1.1. |
Snowplow Platform | Contact Snowplow | Fully managed for production workloads: real-time pipelines, UI console, managed auto-scaling, data quality monitoring, Data Product Studio, event forwarding, single sign-on and user permissions, surge and outage protection, and technical services access. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
1 GitHub commits 90d7.0k GitHub stars0 vulnerabilities across 2 packages
See all signals from 8 sources
npm · @snowplow/node-tracker@4.10.2 · PyPI · snowplow-tracker@1.1.0
Alternatives to Snowplow
The reviewed substitutes for Snowplow among the customer data platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- mParticle
- Choose mParticle when stitching identities across channels is the hard part of your problem and collection volume is not — and expect a sales cycle rather than a signup.Applies to: Choosing the platform that will collect customer events and send them to downstream tools.
- RudderStack
- Choose RudderStack when you want Snowplow's architecture and data ownership without an infrastructure team, and when you need to put a number in a budget before a sales call.Applies to: Choosing the platform that will collect customer events and send them to downstream tools.
- Segment
- Tracking what users do across apps and websites is the core job of Segment and Snowplow. Segment, owned by Twilio, emphasizes turning on many ready-made destinations for that data from one dashboard, while Snowplow emphasizes detailed, governed behavioral events built for analytics, personalization and AI agents.Applies to: Choosing the platform that will collect customer events and send them to downstream tools.
See detailed alternatives analysis
Snowplow alternatives come down to one question: do you want to own the event pipeline or rent it? Snowplow is a customer data platform built around behavioural event collection, with a core written in Scala that you can run yourself, alongside a fully managed platform. Every event is validated against a schema before it reaches your warehouse, lake or stream, which is why teams with strict data contracts pick it. A 14-day free trial covers full functionality, and both self-hosted and managed pipelines are priced on monthly event volume, hosting and destinations rather than from a public rate card. Teams look elsewhere when they want published prices, a lighter operational footprint, or activation rather than collection.
Top Alternatives Overview
RudderStack is the closest match in this list and the one with a published head-to-head against Snowplow. It takes the same warehouse-first position — your warehouse is the system of record, not the vendor's — while removing the Scala infrastructure Snowplow asks you to run yourself. Pricing is public, which is itself the difference for many buyers: Free is $0 per month for 250K events per month, Growth starts at $265 per month for 1 million events per month, and Enterprise is custom. Choose RudderStack when you want Snowplow's architecture and data ownership without an infrastructure team, and when you need to put a number in a budget before a sales call.
Segment is the managed incumbent and the other reviewed direct competitor with its own comparison page. The important difference is the billing basis: Segment charges by monthly tracked users, not events. Free is $0 for up to 1,000 MTUs. Team starts at $120 per month for 10,000 MTUs, then adds $12 per extra 1,000 MTUs from 10K to 25K, $11 from 25K to 100K and $10 above 100K, with a 14-day free trial and annual or monthly contracts saving up to 20% annually. Business is quoted by sales. Model this carefully: a product with few users generating many events each is far cheaper on Segment than on event-volume pricing, and a high-traffic, low-event product is the reverse.
mParticle, now part of Rokt, is the third reviewed direct competitor and the strongest of them on mobile and cross-device identity resolution. It targets multi-channel consumer brands that need one profile per person across apps, web and offline touchpoints. It publishes no rate card, so it sits in the same procurement bracket as Snowplow's managed platform rather than the self-serve tiers RudderStack and Segment offer. Choose mParticle when stitching identities across channels is the hard part of your problem and collection volume is not — and expect a sales cycle rather than a signup.
Census, now Fivetran Activations, solves the opposite half of the problem. It is reverse ETL: it reads modelled data out of the warehouse through an API and pushes it into the tools that act on it, instead of collecting events in the first place. A free tier is available and the list rate per model run is $0.00. Snowplow gets events in; Census gets attributes out. Many teams run both. Census only replaces Snowplow when the events you need already arrive by another route — a vendor SDK, a product analytics tool, or the application's own database.
Hightouch is the other large reverse-ETL platform, with personalisation and audience targeting layered on top. Basic Reverse ETL is free for up to 2 active syncs, and self-serve supports up to 10 active syncs per month; the Composable CDP and Agentic Marketing Platform plans use usage-based pricing and are quoted after a demo. It is strongest where marketing owns activation and wants to work directly from warehouse tables without commissioning a separate event pipeline. Like Census, it is a genuine Snowplow replacement only when collection is already handled somewhere else.
Polytomic is the smallest of the three activation tools here and the most explicit about its floor. It is a no-code sync layer between warehouses, databases, spreadsheets, apps and APIs. Pricing begins at $500 per month. The Standard tier adds syncing across multiple destinations with live chat support, and Enterprise adds on-prem deployment, SSO, a dedicated engineer and phone support; both are quote-only above that starting point. Choose Polytomic when a business team, not an engineering team, needs to move records between systems and a published starting price matters more than depth.
Architecture and Approach Comparison
These products split into two architectures that are often confused. Snowplow, RudderStack, Segment and mParticle are collection pipelines: an SDK or tracker in the client emits events, the pipeline validates and enriches them, and the output lands in a warehouse, lake or stream. Snowplow is the strictest of the four, validating each event against a JSON schema and failing bad data loudly rather than silently dropping fields; it is also the only one you can run end to end on your own infrastructure in Scala. RudderStack keeps the warehouse-first model with a managed control plane. Segment and mParticle hold more of the data themselves, which is what makes their identity and audience features work and what makes exit harder. Census, Hightouch and Polytomic invert the flow entirely: nothing is collected, and the warehouse is read through an API and synced outward. Choosing between the halves matters more than choosing a vendor within one.
Pricing Comparison
Published rates below; Segment's were verified against its own pricing page on 5 October 2026. Where a vendor publishes no currency rate, the table says so rather than estimating one.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Free Tier | Paid Plans | Focus Area |
|---|---|---|---|
| Snowplow | 14-day full-functionality trial | Usage-based on event volume, hosting and destinations | Schema-validated event collection you can self-host |
| RudderStack | $0 per month for 250K events per month | Growth from $265 per month for 1 million events per month; Enterprise custom | Warehouse-first collection with published prices |
| Segment | $0 for up to 1,000 MTUs | Team from $120 per month for 10,000 MTUs; Business quoted by sales | Managed CDP priced per tracked user |
| mParticle | Not publicly specified | Quoted per deal | Mobile and cross-device identity resolution |
| Census | Yes | List rate per model run $0.00 | Reverse ETL from the warehouse |
| Hightouch | Up to 2 active syncs | Usage-based, quoted after a demo | Reverse ETL with marketing activation |
| Polytomic | No | From $500 per month | No-code sync for business teams |
When to Consider Switching
Move to RudderStack when you want Snowplow's warehouse-first model but not its operational burden, and when a published price is a procurement requirement. Move to Segment when your user count is low relative to event volume, since MTU pricing then works in your favour, and when a large integration catalogue matters more than schema strictness. Move to mParticle when cross-channel identity is the real problem. Choose Census, Hightouch or Polytomic only when events already reach your warehouse by another route and what you actually need is activation. Stay with Snowplow when schema validation, data ownership and the option to self-host are non-negotiable.
Migration Considerations
Changing collection pipeline means changing the tracking code in every client, so plan for parallel collection rather than a cutover. Run both pipelines into the same warehouse for at least two to four weeks and reconcile event counts daily; a silent 2% gap is normal early and needs explaining before you switch off the old one. Snowplow's schemas do not export into another vendor's format, so budget time to rebuild the event contract by hand and keep a CSV of the current schema registry as the reference. Historical data stays where it is: none of these tools backfills another's events. Decide in advance which team owns the reconciliation and what gap is small enough to accept.