Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What mParticle states |
|---|---|
Built for | Multi-channel consumer brands |
Operating model | Real-time pipelines and warehouse-native activation run side by side; data in motion, data at rest, or both |
Integrations | Over 300 out-of-the-box integrations |
Web collection | Web SDK under the Apache License 2.0; load it with a script tag or bundle it from npm (@mparticle/web-sdk) |
Security and compliance | SSO, MFA, segregated identity spaces, TLS, data-at-rest encryption with 256-bit AES; GDPR, CCPA, LGPD, ISO 27001 and SOC II Type 2 |
Company | Headquartered in New York City; a mParticle press release announces that Rokt and mParticle merge |
Our take
Choose mParticle if you run a consumer brand across web, app and other channels and want one platform that serves both live event streams and warehouse data. If you only need to move tables into a warehouse, a full CDP is more platform than the job needs.
Evaluate mParticle
Comparisons
Where it stands out
Warehouse activation without new pipelines. Composable Audiences turn a cloud data warehouse or data lake into an activation source with zero-copy activation, so audiences stay in sync with data the team already manages.
Identity resolution you can inspect. IDSync resolves identities as each signal arrives, and the Identity Dashboard and Identity Logs show how each profile came together.
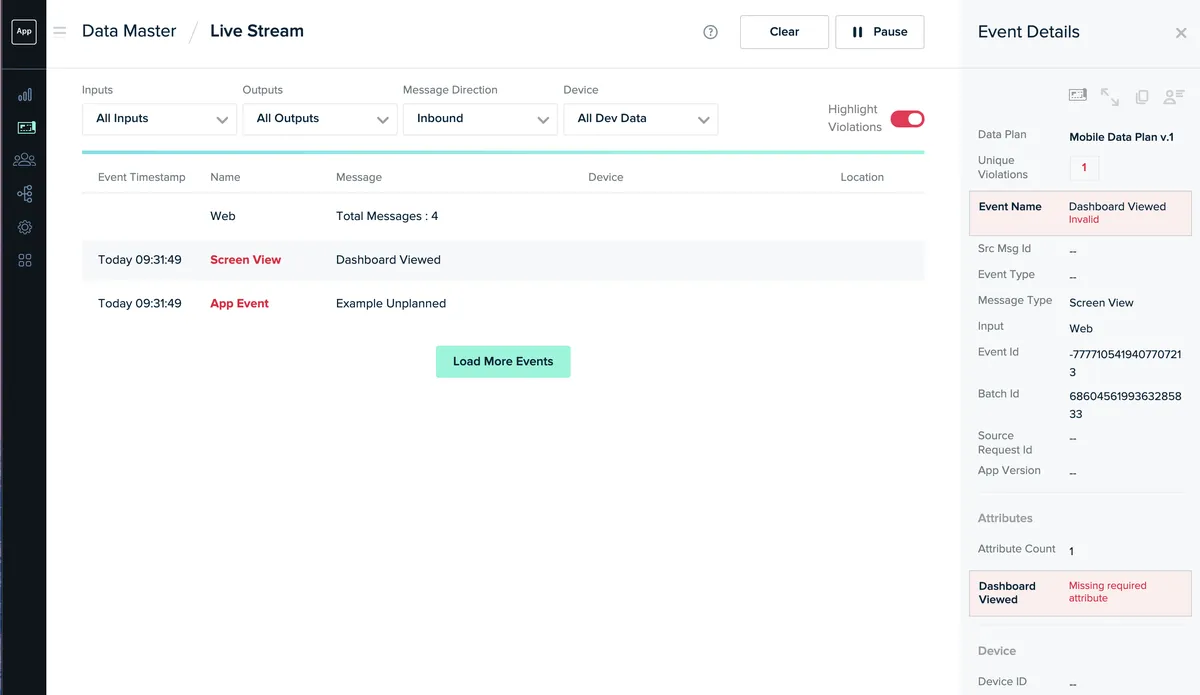
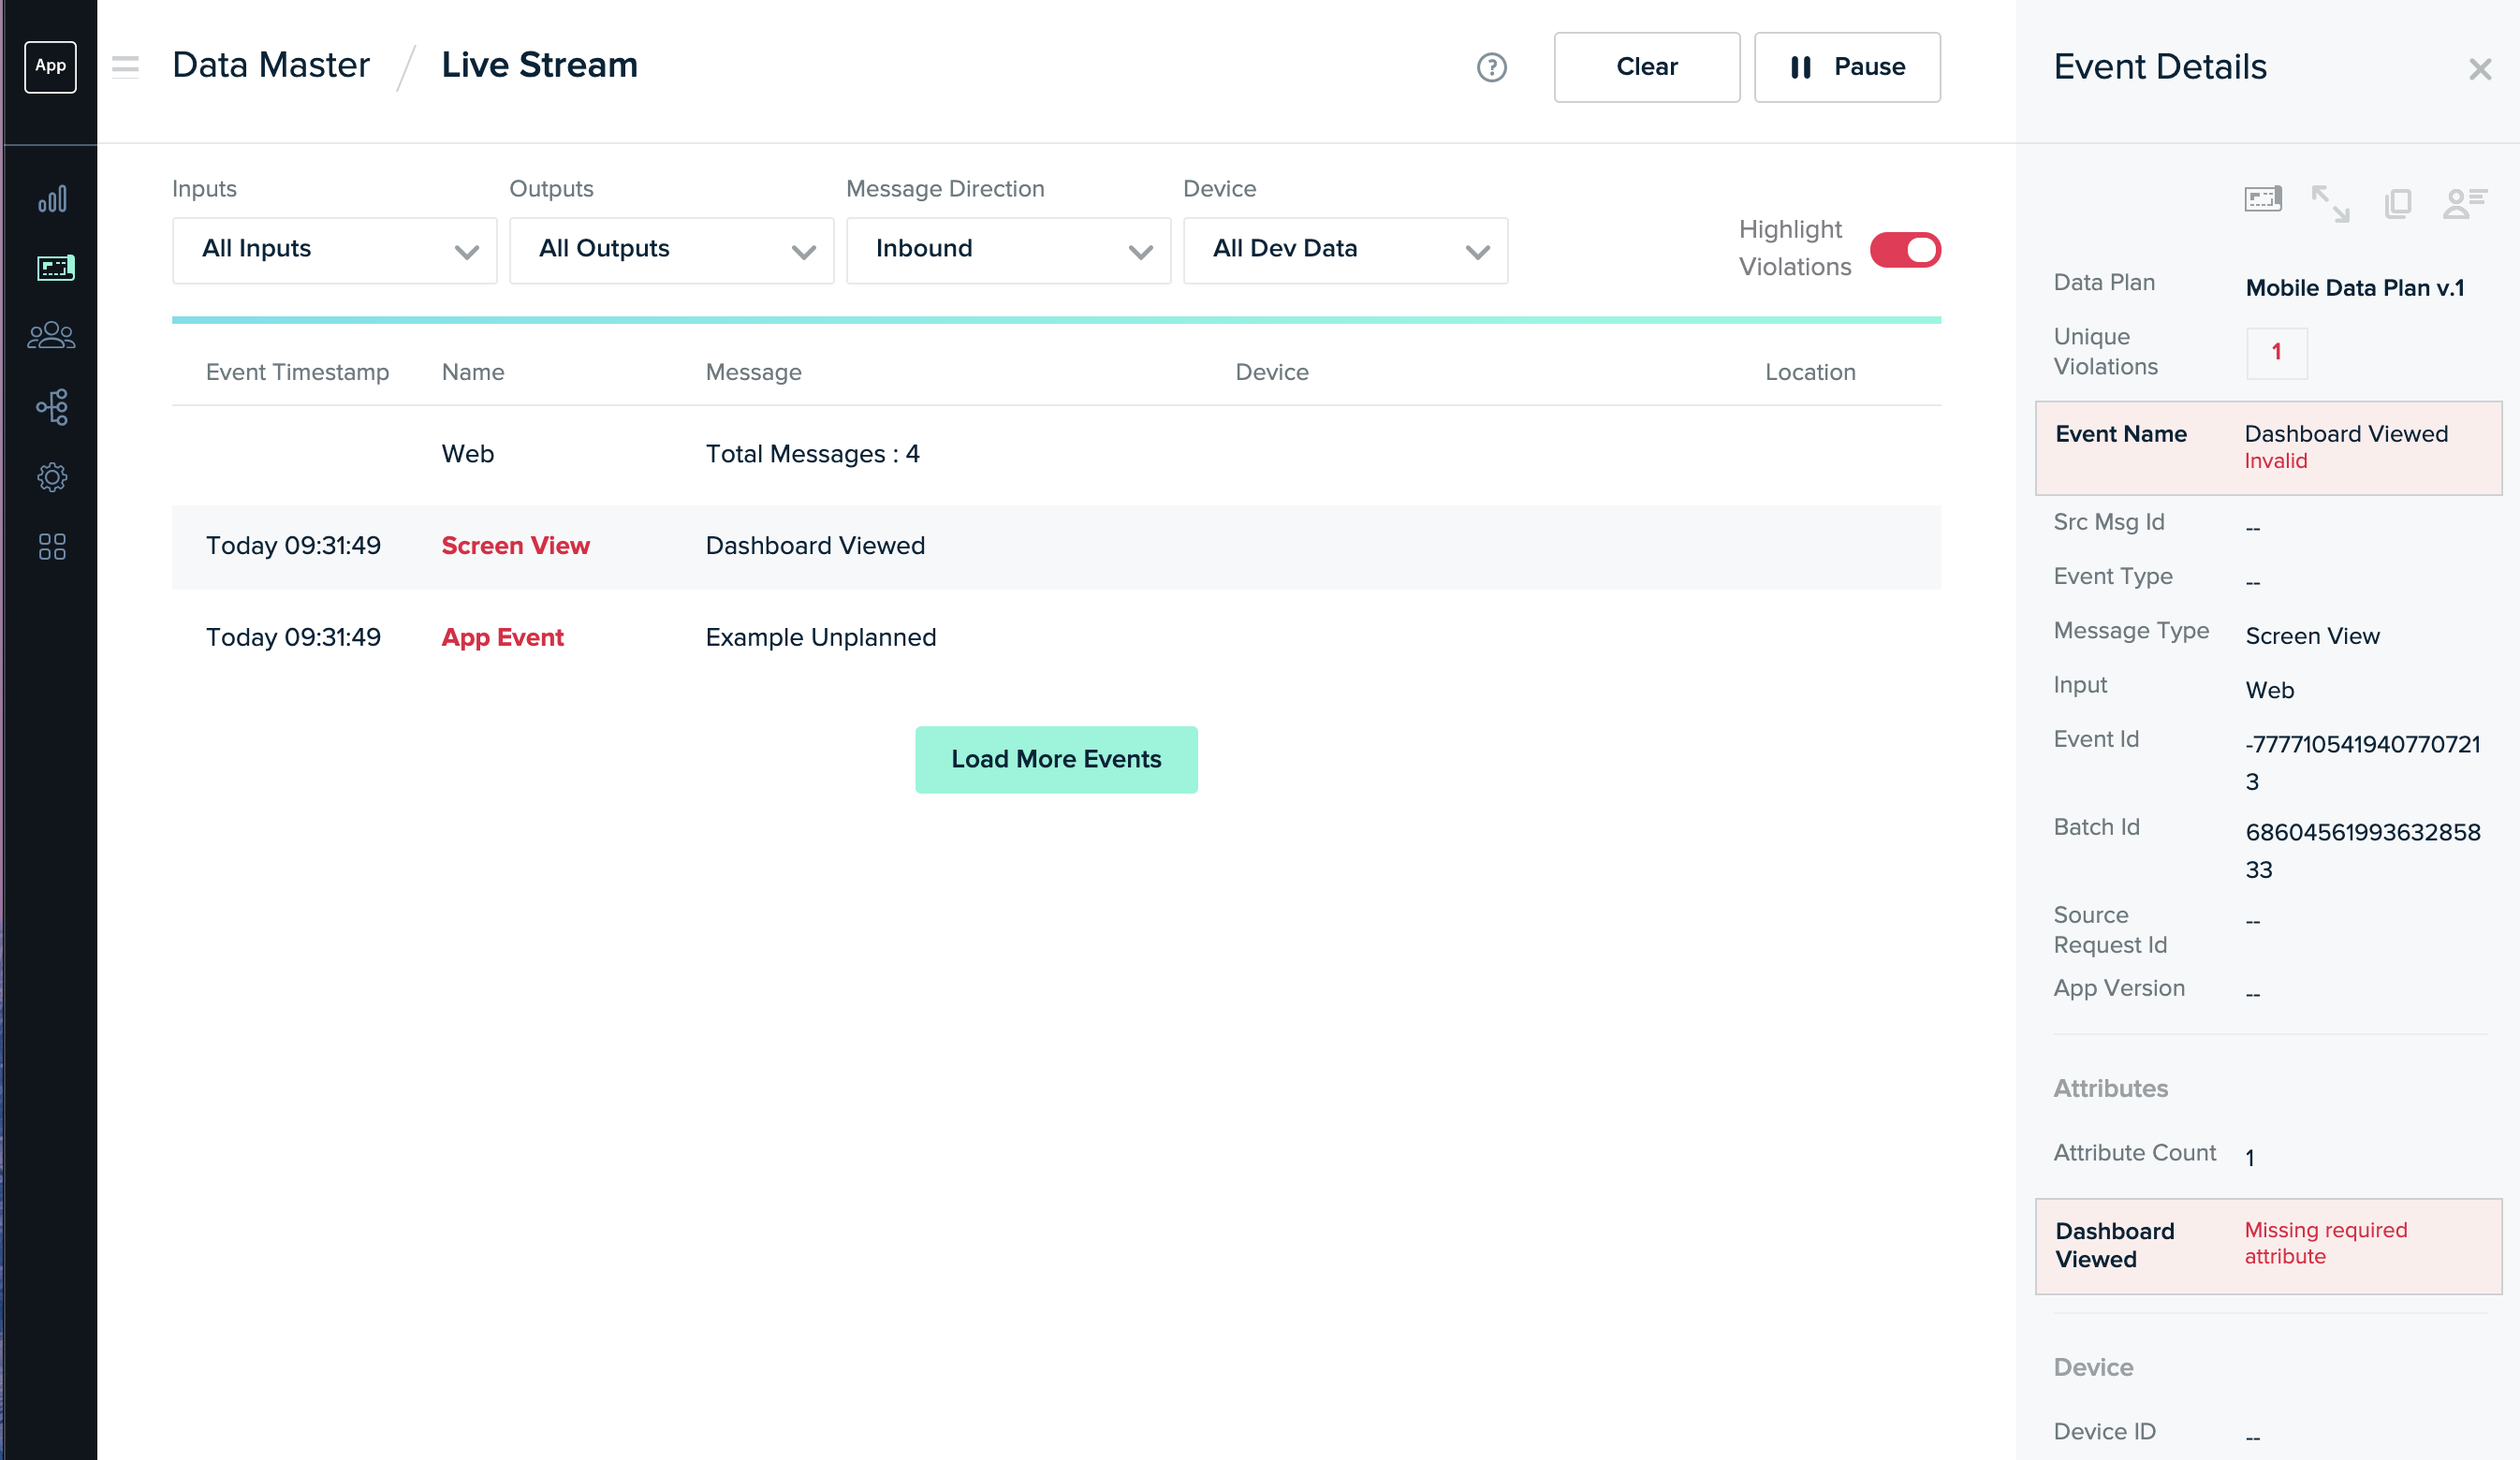
Data quality controls. Data Plans and the Data Catalog sit among mParticle's guardrails to enforce quality. Klarna's engineering manager says the data plan also shows them any unplanned data, which helps reduce unwanted data in the CDP.
Audience building from a goal. The Audience Agent turns a business goal into audience logic, shows its reasoning, and waits for approval before anything is saved. Predictive Audiences score likelihood to churn, convert or grow in value.
Product screenshot
Trade-offs to weigh
Governance work comes with the platform. Identity resolution, consent enforcement, role-based access and data plans are only as good as the rules your team defines and owns. Plan for that work before rollout.
The pitch is now marketing performance. mParticle presents itself as a "Performance Engine" for paid media and lifecycle programs, with features such as Match Boost and Household Reach. Data teams that want a neutral collection layer should check how much of the roadmap serves their needs.
Web SDK v3 is a migration. Version 3 of the Web SDK is generally available, with upgrade steps in MIGRATING.md. Its snippet also sets up Rokt methods such as selectPlacements, a sign of the Rokt merger reaching the SDK.
Pricing and plan conditions
mParticle sells through its sales team. Its pricing page asks buyers to "Talk with our team" and offers a demo. Get the scope of any quote in writing, including the data sources, destinations and warehouse connections you plan to use, before you compare offers.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
472 GitHub commits 90d24 GitHub stars0 vulnerabilities across 2 packages
See all signals from 7 sources
npm · @mparticle/web-sdk@2.81.0 · PyPI · mparticle@0.16.1
Alternatives to mParticle
The reviewed substitutes for mParticle among the customer data platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Segment
- **Segment** is the most direct competitor to mParticle as a customer data platform. Owned by Twilio, Segment provides event tracking, identity resolution, and data routing through a single API with 200+ integrations. Segment offers a freemium model and is widely adopted by both startups and enterprises.
- RudderStack
- RudderStack and mParticle are customer data platforms that collect customer events from apps and websites, clean them and send them to marketing and analytics tools. RudderStack is open source and warehouse-first, keeping profiles in the team's own warehouse, while mParticle, now part of Rokt, manages profiles, segments and enrichment inside its own platform.Applies to: Choosing between two products of the same kind for one job.
- Snowplow
- mParticle and Snowplow each collect behavioral events from websites and apps and turn them into usable customer data. mParticle is a commercial platform built for multi-channel consumer brands, with data cleansing, profiles and audience segments, while Snowplow focuses on detailed, governed behavioral data that lands in the team's own warehouse for analytics and AI.Applies to: Choosing the platform that will collect customer events and send them to downstream tools.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Apache Airflow
- A customer data or reverse-ETL tool moves records to and from operational systems; an orchestrator decides what runs and when. The two sit at different layers and are commonly deployed together, so the reader's question is whether both are needed.Applies to: Whether a customer data or reverse-ETL tool needs an orchestrator, or replaces one.
See detailed alternatives analysis
If you are evaluating mParticle alternatives, you are likely looking for a different approach to customer data collection, real-time activation, or data integration -- whether that means simpler pipelines, warehouse-native architecture, or more transparent pricing. mParticle is a hybrid customer data platform (CDP) built for multi-channel consumer brands, offering real-time data streaming, identity resolution, and AI-powered audience segmentation with 300+ integrations. However, its contact-sales pricing model and enterprise-oriented positioning can make it a challenging fit for mid-market teams or those seeking more predictable costs. We have reviewed the leading alternatives across the Data Pipeline & Orchestration category to help you find the right fit.
Top Alternatives Overview
Segment is the most direct competitor to mParticle as a customer data platform. Owned by Twilio, Segment provides event tracking, identity resolution, and data routing through a single API with 200+ integrations. Segment offers a freemium model and is widely adopted by both startups and enterprises. Where mParticle emphasizes real-time activation and warehouse-native composable architecture, Segment focuses on developer-friendly SDKs and a broad integration catalog. Segment is a strong choice for teams that want a CDP with a lower barrier to entry and well-documented developer tooling.
Hightouch takes a fundamentally different approach with its Composable CDP, and it also sells an Agentic Marketing Platform with Ad Studio and Lifecycle Studio. Rather than creating a separate data repository like a traditional CDP, Hightouch works directly with your existing data warehouse -- Snowflake, BigQuery, Redshift, or Databricks -- to sync audiences and attributes to 300+ destinations. This composable approach appeals to teams that already have a well-modeled warehouse and want to activate that data without duplicating it into another platform. Hightouch offers a free tier for basic Reverse ETL with up to 2 active syncs; the Composable CDP and the Agentic Marketing Platform have their own plans.
Fivetran is a managed ELT platform focused on automated data ingestion from 600+ sources into cloud warehouses and lakes. While mParticle concentrates on real-time event streaming and customer profiles, Fivetran handles the upstream challenge of consolidating data from SaaS applications, databases, and event streams. Fivetran manages schema evolution, incremental updates, and connector maintenance so data teams can focus on modeling and analytics rather than pipeline engineering. It offers a free plan for up to 500,000 monthly active rows, and its paid plans are priced on monthly active rows, with no per-plan price published.
Confluent is the data streaming platform built on Apache Kafka, founded by Kafka's original creators. Now part of IBM, Confluent provides fully managed Kafka (Confluent Cloud), an enterprise Kafka distribution, and 120+ pre-built connectors. Where mParticle focuses on marketing-oriented customer data use cases, Confluent targets broader real-time data infrastructure needs including event-driven architectures, microservices, and stream processing. Confluent Cloud offers usage-based pricing with tiers ranging from a free Basic cluster to Enterprise and Freight clusters designed for high-throughput workloads.
AWS Glue is a serverless data integration service for ETL workloads within the AWS ecosystem. It provides automated schema discovery, a centralized data catalog, and built-in generative AI capabilities for ETL authoring. AWS Glue is usage-based with pay-per-use pricing (DPU-hours), making it cost-effective for teams already on AWS who need batch and micro-batch data processing rather than real-time customer data activation.
Hevo Data is an ingestion option for a warehouse-centered stack. Free covers limited connectors and up to 1M events/month. Starter starts at $299/month billed monthly or $265/month billed annually for 5M events/month; On-Demand usage above quota costs extra. Events are destination inserts, updates and deletes. Evaluate event collection, identity resolution and activation separately rather than treating an ingestion plan as a complete CDP replacement.
Architecture and Approach Comparison
The alternatives to mParticle fall into three distinct architectural categories, each reflecting a different philosophy about where customer data should live and how it should be activated.
Traditional CDPs like Segment and mParticle maintain their own data store, collecting events via SDKs and APIs, resolving identities, building unified customer profiles, and routing data to downstream destinations. This approach provides real-time activation capabilities and a centralized customer view, but it also means your customer data lives in yet another platform. mParticle differentiates here with its hybrid CDP approach, allowing both in-platform real-time processing and warehouse-native activation via its composable architecture on Snowflake.
Composable and Reverse ETL platforms like Hightouch represent the warehouse-native movement. These tools treat your existing data warehouse as the single source of truth and focus on activating data that already lives there. Instead of duplicating data into a CDP, teams build audiences and segments directly in SQL or through visual interfaces, then sync results to marketing and operational tools. This approach eliminates data duplication and leverages existing warehouse investments, but requires a well-modeled warehouse as a prerequisite.
ELT and data integration platforms such as Hevo Data focus on ingestion into a warehouse. Combining ingestion with an activation tool adds separate subscriptions and operating responsibilities. Check collection, identity resolution, consent handling and destination requirements before calling the combination a CDP replacement; no measured workload here establishes lower total cost.
Data streaming and infrastructure platforms like Confluent and AWS Glue operate at a lower level of abstraction. Confluent provides real-time event streaming infrastructure suitable for engineering-driven use cases, while AWS Glue handles serverless ETL and data cataloging. These are not direct CDP replacements, but they serve teams whose needs extend beyond marketing activation into broader data engineering and real-time processing.
Legacy enterprise platforms like Informatica PowerCenter represent the prior generation of data integration technology. While PowerCenter was widely deployed for on-premises ETL, Informatica now focuses on cloud modernization paths to reduce cost and risk when migrating legacy workloads.
Pricing Comparison
mParticle uses a value-based, contact-sales pricing model with no publicly listed prices. The platform advertises access to all features, unlimited real-time products, no monthly event or user caps, and no overages or penalties -- but the actual cost requires speaking with their sales team.
Hevo publishes Starter from $299/month billed monthly or $265/month billed annually for 5M events/month, and Professional from $849/month billed monthly or $750/month billed annually for 20M events/month. Business Critical requires a custom quote. Free is limited to selected connectors and up to 1M events/month. Above-quota On-Demand usage is extra; the public page does not publish an overage unit rate. Obtain quotes for the complete collection-to-activation workload rather than comparing these ingestion rates directly with a CDP contract.
On the infrastructure side, Confluent Cloud uses consumption-based pricing with publicly listed cluster costs: Basic clusters at $0/mo, Standard at $385/mo, Enterprise at $895/mo, and Freight at $2,300/mo, plus usage-based rates for throughput, storage, and connectors. AWS Glue charges $0.44 per DPU-hour for ETL jobs, with a free tier for the Data Catalog. Y42 offers a free plan with Business plans at $500/mo.
A published entry rate helps identify a trial budget, but it does not make a multi-product stack's bill predictable. For Hevo, measure destination events and request the On-Demand rate; add activation, warehouse and operating costs separately. Compare that complete scope with the quoted CDP requirements.
When to Consider Switching
Switch to Segment if you want a CDP with similar capabilities to mParticle but need a lower entry point, stronger developer documentation, and a broader ecosystem of pre-built integrations. Segment is particularly well-suited for teams that prioritize developer experience and want to get started quickly without a lengthy enterprise sales cycle.
Switch to Hightouch if your team has already invested in building a well-modeled data warehouse and you want to activate that data directly without maintaining a separate CDP data store. The composable CDP approach eliminates data duplication and can significantly reduce total cost of ownership for teams with mature warehouse infrastructure.
Switch to Fivetran if your primary challenge is consolidating data from many SaaS sources into a warehouse for analytics and modeling, rather than real-time customer activation. Fivetran excels at automated, maintenance-free data ingestion with 600+ connectors and handles the complexity of schema evolution and incremental syncing.
Switch to Confluent if your use cases extend beyond marketing activation into real-time event streaming, event-driven architectures, or stream processing at scale. Confluent provides the underlying infrastructure for teams building real-time applications, not just marketing workflows.
Switch to AWS Glue if you are already invested in the AWS ecosystem and need serverless ETL capabilities for batch data processing, data cataloging, and warehouse loading. AWS Glue is cost-effective for teams whose workloads are primarily batch-oriented and do not require real-time customer data activation.
Evaluate Hevo Data when the requirement is managed warehouse ingestion. Confirm the connectors and sync behavior, then evaluate collection, identity resolution and activation separately. The published ingestion price does not establish savings against an enterprise CDP.
Migration Considerations
Migrating away from mParticle requires careful planning around three critical areas: event collection, identity resolution, and downstream integrations.
Event collection migration is typically the most straightforward step. If moving to Segment, you will need to replace mParticle SDKs with Segment SDKs across your web and mobile applications. Both platforms use similar event-based data models (track, identify, page/screen calls), so the conceptual mapping is direct even though the API implementations differ. For moves to ELT platforms like Fivetran or Hevo Data, you will shift from client-side SDK collection to server-side connector-based ingestion, which fundamentally changes how data enters your pipeline.
Identity resolution is often the hardest capability to replicate. mParticle's IDSync provides deterministic identity resolution with configurable strategies. Segment offers its own identity resolution, while Hightouch relies on identity graphs built within your warehouse. Teams moving to ELT-plus-Reverse-ETL stacks will need to build or adopt a separate identity resolution layer, often using dbt models or dedicated identity platforms.
Integration rewiring involves reconnecting all downstream destinations -- marketing automation, analytics, advertising platforms, and customer engagement tools. Start by auditing your active mParticle connections and mapping each to the equivalent integration in your target platform. Prioritize critical marketing workflows and run parallel pipelines during the transition period to validate data consistency before decommissioning mParticle connections.
For teams considering the composable CDP route (warehouse plus Hightouch), plan for an intermediate step of modeling your customer data in the warehouse using tools like dbt. This investment in data modeling becomes the foundation that replaces mParticle's built-in profile management and segmentation capabilities.