Decision comparison
Google BigQuery vs Yellowbrick Data
BigQuery and Yellowbrick are separated by where the data lives. BigQuery is serverless and Google-operated: no cluster exists, queries scale automatically, and you pay per terabyte scanned or buy committed slots. Yellowbrick runs as containers on Kubernetes inside your own cloud account or data centre, is PostgreSQL-compatible, and is available through vCPU subscriptions or on-demand vCPU-hour billing. If a data-residency or on-premise rule applies, that decides it.
Architecture choice. These take different approaches to the same problem. Read the table as a fit question rather than a feature race.
All 2 are cloud data warehouses.
Quick Comparison
| Decision factor | Google BigQuery | Yellowbrick Data |
|---|---|---|
| What it is | Google Cloud's serverless data warehouse, with no infrastructure to size or manage | A massively parallel data warehouse that runs as containers on Kubernetes, in your own cloud account or on your own hardware |
| Where it runs | Google Cloud only, operated by Google | Your own AWS, Azure or Google Cloud account, or your own data centre |
| Who holds the data | Data sits in Google-managed storage inside your project | Data stays inside your own account or building, under your own network controls |
| Pricing shape | BigQuery offers two compute pricing models. On-demand pricing charges for bytes processed by each query, billed per TiB, with the first 1 TiB of query data per month free. Capacity pricing charges for compute capacity per slot-hour instead. Storage is billed separately, and BigQuery also has a free usage tier and free operations. On-demand queries are $6.25 per TiB after the first 1 TiB free each month. BI Engine memory capacity is $0.0416 per GiB per hour in Iowa (us-central1). In the US multi-region, active logical storage is $0.02 per GiB per month and long-term logical storage $0.01 per GiB per month, with the first 10 GiB free. Streaming inserts through the Storage Write API (REST) cost $0.01 per 200 MiB, about $0.05 per GiB. Verified 2026-10-05 (streaming 2026-10-06) against https://cloud.google.com/bigquery/pricing. Capacity (editions) pay-as-you-go prices in the US are $0.04 per slot-hour for Standard, $0.06 for Enterprise and $0.10 for Enterprise Plus, billed per second with no commitment. Verified 2026-10-05 against https://cloud.google.com/bigquery/pricing. | Yellowbrick charges for its data warehouse software per vCPU: $613 per vCPU per year on a one-year subscription, $482 per vCPU per year on a three-year subscription, or $0.28 per vCPU per hour on demand, metered per second and billed monthly. You pay your own cloud or on-premises infrastructure costs on top, and 24x7 support is always included at no extra charge. Yellowbrick also sells on-premises infrastructure subscriptions through sales@yellowbrick.com. Verified 2026-10-26 against https://yellowbrick.com/pricing/. |
| Operating burden | None: no nodes, no patching, no sizing | You run it, though Kubernetes handles scaling and recovery |
| SQL dialect | Google's standard SQL, with BigQuery ML and geospatial extensions | PostgreSQL-compatible, so existing Postgres tooling and drivers work |
| Best fit | Teams on Google Cloud wanting zero infrastructure work | Teams needing the warehouse inside their own network or on their own hardware |
Google BigQuery
- What it is:
- Google Cloud's serverless data warehouse, with no infrastructure to size or manage
- Where it runs:
- Google Cloud only, operated by Google
- Who holds the data:
- Data sits in Google-managed storage inside your project
- Pricing shape:
- BigQuery offers two compute pricing models. On-demand pricing charges for bytes processed by each query, billed per TiB, with the first 1 TiB of query data per month free. Capacity pricing charges for compute capacity per slot-hour instead. Storage is billed separately, and BigQuery also has a free usage tier and free operations. On-demand queries are $6.25 per TiB after the first 1 TiB free each month. BI Engine memory capacity is $0.0416 per GiB per hour in Iowa (us-central1). In the US multi-region, active logical storage is $0.02 per GiB per month and long-term logical storage $0.01 per GiB per month, with the first 10 GiB free. Streaming inserts through the Storage Write API (REST) cost $0.01 per 200 MiB, about $0.05 per GiB. Verified 2026-10-05 (streaming 2026-10-06) against https://cloud.google.com/bigquery/pricing. Capacity (editions) pay-as-you-go prices in the US are $0.04 per slot-hour for Standard, $0.06 for Enterprise and $0.10 for Enterprise Plus, billed per second with no commitment. Verified 2026-10-05 against https://cloud.google.com/bigquery/pricing.
- Operating burden:
- None: no nodes, no patching, no sizing
- SQL dialect:
- Google's standard SQL, with BigQuery ML and geospatial extensions
- Best fit:
- Teams on Google Cloud wanting zero infrastructure work
Yellowbrick Data
- What it is:
- A massively parallel data warehouse that runs as containers on Kubernetes, in your own cloud account or on your own hardware
- Where it runs:
- Your own AWS, Azure or Google Cloud account, or your own data centre
- Who holds the data:
- Data stays inside your own account or building, under your own network controls
- Pricing shape:
- Yellowbrick charges for its data warehouse software per vCPU: $613 per vCPU per year on a one-year subscription, $482 per vCPU per year on a three-year subscription, or $0.28 per vCPU per hour on demand, metered per second and billed monthly. You pay your own cloud or on-premises infrastructure costs on top, and 24x7 support is always included at no extra charge. Yellowbrick also sells on-premises infrastructure subscriptions through sales@yellowbrick.com. Verified 2026-10-26 against https://yellowbrick.com/pricing/.
- Operating burden:
- You run it, though Kubernetes handles scaling and recovery
- SQL dialect:
- PostgreSQL-compatible, so existing Postgres tooling and drivers work
- Best fit:
- Teams needing the warehouse inside their own network or on their own hardware
Need the cost answer?
Compare BigQuery, Snowflake and Amazon Redshift Serverless using your workload.
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Google BigQuery | Yellowbrick Data |
|---|---|---|
| Search interest(Market interest) | 7 | Unavailable |
| Hacker News mentions, 90d(Community interest) | 9 | 0 |
| npm weekly downloads(Developer adoption) | 6.9M | Not available |
| PyPI weekly downloads(Developer adoption) | 38.6M | Not available |
| Stack Overflow questions(Community interest) | 26.1k | Not available |
| Docker Hub pulls(Product adoption) | Not available | 4.6k |
| GitHub commits, 90d(Developer adoption) | Not available | 0 |
| GitHub stars(Developer adoption) | Not available | 4 |
As of November 9, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Google BigQuery
November 9, 2026Package vulnerabilities
npm · @google-cloud/bigquery@9.5.0 · PyPI · google-cloud-bigquery@3.47.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Yellowbrick Data
Package vulnerabilities
Not available
Repository security score
Not available
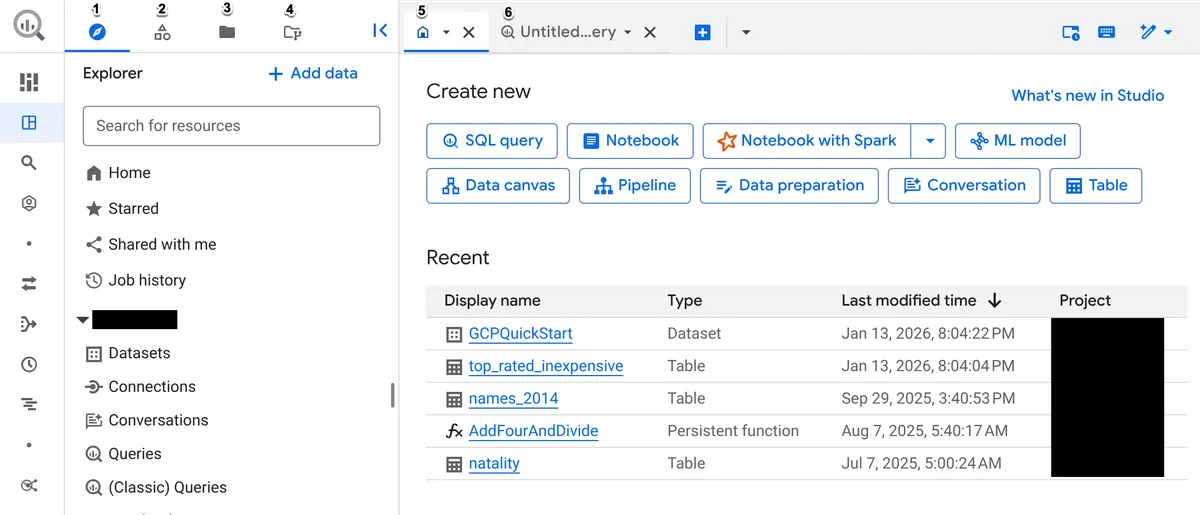
Interface Preview
Google BigQuery
Yellowbrick Data
Feature Comparison
| Feature | Google BigQuery | Yellowbrick Data |
|---|---|---|
| Query | ||
| Standard SQL analytics | Full support | Full support |
| PostgreSQL wire compatibility | Not verified | Full support |
| Materialised views | Full support | Full support |
| Query data in object storage | Full support | Partial support |
| Operations | ||
| No infrastructure to manage | Full support | Not verified |
| Automatic scaling per query | Full support | Partial support |
| Runs on Kubernetes | Not verified | Full support |
| Pause compute when idle | Full support | Full support |
| Deployment | ||
| Run on-premise | Not verified | Full support |
| Run in your own cloud account | Not verified | Full support |
| Available on AWS and Azure | Partial support | Full support |
| Fully managed by the vendor | Full support | Partial support |
| Platform | ||
| Machine learning in SQL | Full support | Not verified |
| Streaming ingestion | Full support | Partial support |
| Native BI integration | Full support | Full support |
| Fixed software fee at subscribed vCPU capacity | Partial support | Full support |
Query
Standard SQL analytics
PostgreSQL wire compatibility
Materialised views
Query data in object storage
Operations
No infrastructure to manage
Automatic scaling per query
Runs on Kubernetes
Pause compute when idle
Deployment
Run on-premise
Run in your own cloud account
Available on AWS and Azure
Fully managed by the vendor
Platform
Machine learning in SQL
Streaming ingestion
Native BI integration
Fixed software fee at subscribed vCPU capacity
Which approach fits
BigQuery and Yellowbrick are separated by where the data lives. BigQuery is serverless and Google-operated: no cluster exists, queries scale automatically, and you pay per terabyte scanned or buy committed slots. Yellowbrick runs as containers on Kubernetes inside your own cloud account or data centre, is PostgreSQL-compatible, and is available through vCPU subscriptions or on-demand vCPU-hour billing. If a data-residency or on-premise rule applies, that decides it.
When each approach fits
Choose Google BigQuery if:
Choose BigQuery when you are on Google Cloud and nobody should be managing warehouse infrastructure. There are no nodes to size, patch or pause; queries scale automatically onto managed capacity; idle periods cost only storage. BigQuery ML trains models in SQL and the Storage Write API handles streaming ingestion, so the warehouse covers modelling and freshness without separate services.
Choose Yellowbrick Data if:
Choose Yellowbrick when the warehouse has to sit inside your own network — on your own hardware, or in your own cloud account under your own controls. Running as containers on Kubernetes means the same deployment model works on-premise and on AWS, Azure or Google Cloud, PostgreSQL compatibility keeps existing drivers and tooling working, and a subscription fixes the software fee for selected vCPU capacity; infrastructure and on-demand bursts remain separate.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
When does the deployment difference actually decide this?
Whenever a rule rather than a preference is involved: regulated data that may not leave a jurisdiction or a private network, a sovereignty requirement, an existing data centre investment with years left on it, or a security policy that forbids third-party operated storage for certain classes of data. If none of those apply, the comparison is genuinely open and the operating-burden question takes over.
What does PostgreSQL compatibility buy?
Existing drivers, client libraries and many Postgres-aware tools connect without a new integration. Teams that already run Postgres keep their connection code, their ORMs and much of their SQL knowledge. BigQuery uses its own standard SQL and its own client libraries, which are well documented but are another thing to learn and another integration path to maintain.
How much operational work does Yellowbrick really need?
Less than a traditional appliance, more than none. Kubernetes handles scheduling, scaling and recovery, so day-to-day operations are largely cluster operations you may already do. But somebody owns upgrades, capacity and the Kubernetes platform itself. BigQuery's answer to all of that is that there is nothing to own, which is the single biggest practical difference between the two.
Which is cheaper?
Yellowbrick subscriptions fix the software fee for selected vCPU capacity, while infrastructure and on-demand bursts remain separate. Measure capacity, runtime, concurrency, storage and operating work for the same workload on both platforms. Compare full costs and service requirements; headcount, unit rates and utilisation alone do not establish which option is cheaper.
Can BigQuery reach data outside Google Cloud?
BigQuery Omni runs queries against data in AWS S3 and Azure Blob Storage, so the data does not have to move. The service itself remains Google-operated, and the control plane stays in Google Cloud. That covers multi-cloud analytics but does not satisfy a requirement that no third party operate the system, which is the case Yellowbrick is built for.
How hard is it to migrate between them?
Analytical SQL ports with modest editing, because both speak a standard dialect. The work is in everything around the tables: ingestion pipelines, orchestration schedules, the BI semantic layer, row-level security rules and the access model. Budget for those rather than for table definitions, and expect to run both in parallel for a period while you reconcile numbers against the old system.