Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What LiteLLM states |
|---|---|
License | Open-source gateway is MIT-licensed and free to self-host; Enterprise features build on the same core but fall under the LiteLLM Commercial License, which an Enterprise License covers |
Deployment | Self-hosted in your own cloud: official Helm chart, Terraform modules (AWS, GCP) or Docker images, including database-bundled and non-root variants; runs on your own Postgres and Redis |
SDK or gateway | Python SDK: library calls with a Router for retry and fallback. Proxy: central service with virtual keys, per-project cost tracking, auth and an admin dashboard |
Data handling | No telemetry sent to LiteLLM; prompts go only to the model providers you configure |
Model scope | 140+ providers and 1,892 models per the home page (the pricing page says 100+ providers), through one OpenAI-compatible API, plus agents and MCP servers through the same gateway |
Release track | Docker images with the -stable tag go through 12-hour load tests before publishing; GHCR images are signed with cosign |
Support | Open Source: community support. Enterprise: support with SLAs (up to 24/7) through a dedicated Slack or Teams channel with LiteLLM engineers |
Our take
If you run a platform team that hands model access to several teams across several providers, and you can operate a self-hosted service, LiteLLM is a strong default: the free self-hosted gateway already carries the spend controls. Plan on Enterprise when you need SSO, audit logs, SLAs or a multi-region control plane.
Evaluate LiteLLM
Comparisons
Where it stands out
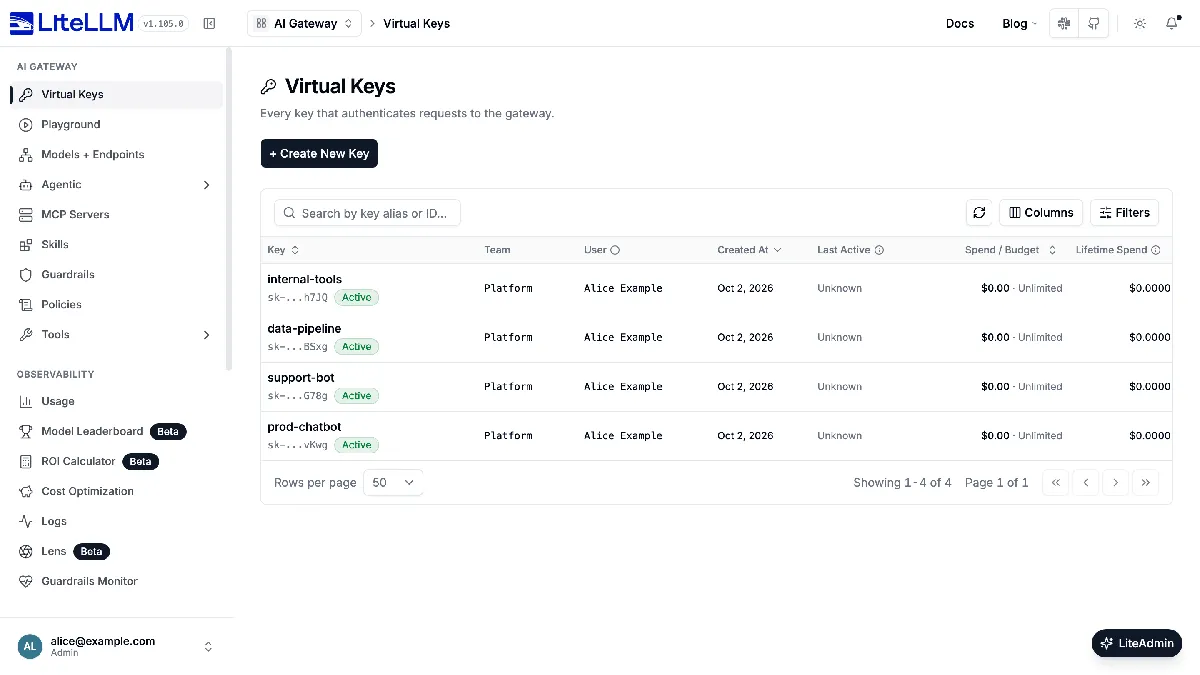
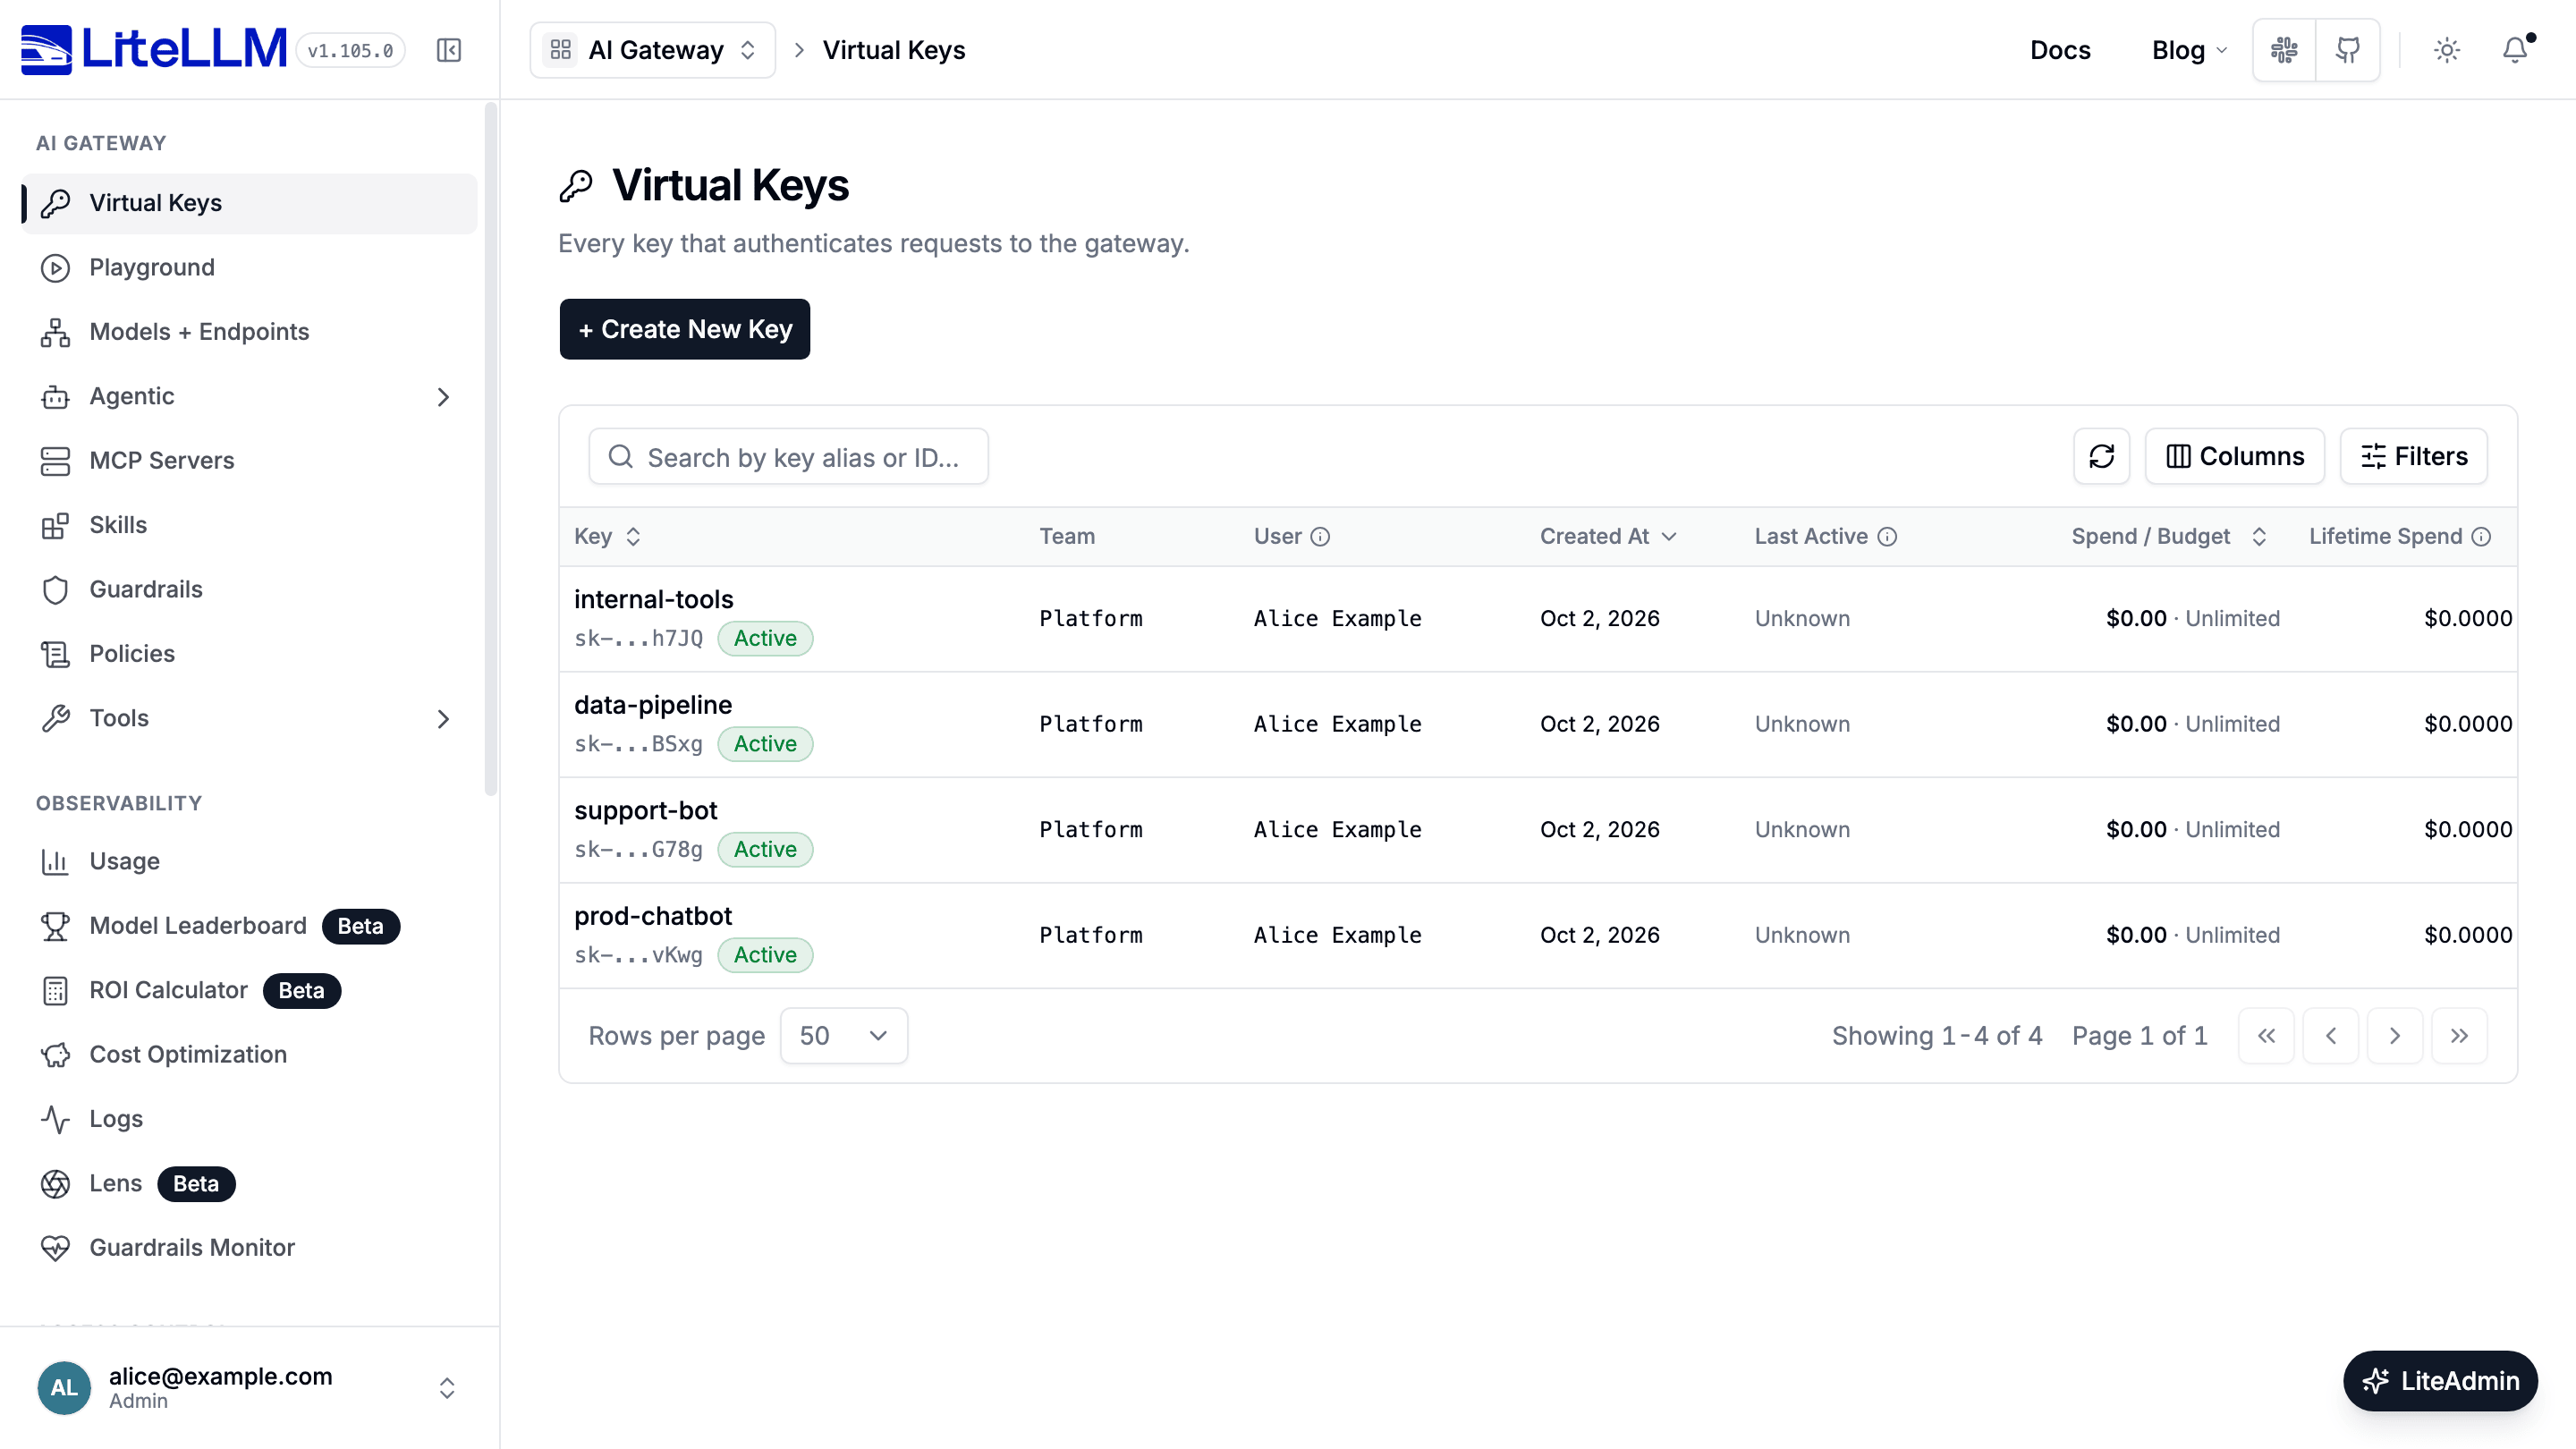
Spend controls in the free build. The $0 plan includes virtual keys, budgets and teams, load balancing with RPM/TPM limits, and LLM guardrails. LiteLLM says budgets are hard caps with daily and monthly resets, and at the cap requests stop, so a runaway job is stopped rather than reported later.
Routing that can cut the bill. LiteLLM lists load balancing across providers, regions and keys, lowest-cost routing to the cheapest deployment that can serve a request, Auto Routing of simple prompts to cheaper models, response and semantic caching (Redis, S3, GCS), and prompt compression.
Model changes become configuration. An Okta architect quoted on LiteLLM's site says switching the backend model is a configuration update in the gateway, with no code changes, procurement cycles or repeated security reviews.
Works with your existing monitoring. It logs to Langfuse, Arize Phoenix, LangSmith and OTEL, exposes Prometheus metrics, and exports spend to Prometheus, Datadog or CloudZero for chargeback.
Agents and tools on the same keys. MCP servers and A2A agents can be added to the gateway; A2A agents are called with the LiteLLM master key or a virtual key, so agent access follows the same key model as model access.
Product screenshot
Trade-offs to weigh
You run it, and it sits in the request path. The Terraform stacks bring managed Postgres (writer + reader), Redis, a versioned object store and a migration job that runs before the proxy starts. Every model call now depends on that service staying up.
Identity and audit need Enterprise. If your security review requires single sign-on, SCIM provisioning or audit logs, the free build does not cover them; they come with the Enterprise plan in the table below.
Check the air-gap terms. The pricing FAQ says air-gapped deployment is available on Enterprise Standard and SCALE, while the home page describes fully air-gapped self-hosting without naming a plan. Confirm which plan you need before you plan an isolated deployment.
Enterprise cost needs a quote. Enterprise is quote-based, so you cannot budget the step from free to Enterprise in advance. Ask for a quote early if SSO or SLAs are likely requirements.
Pricing and plan conditions
Neither plan is priced per token. The open-source gateway has no license fee, also for production use. Enterprise is an annual contract sized to your gateway request capacity, deployment architecture and support needs. You can get an instant 30-day Enterprise trial key, and buy direct, through AWS Marketplace or through authorized resellers.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Open Source | $0 (free forever, self-hosted) | 100+ providers through one OpenAI API; virtual keys, users and teams; spend tracking; budgets and rate limits; LLM fallbacks; request/response logging; Prometheus metrics |
Enterprise | Talk to sales (annual, sized to your usage) | Everything in Open Source, plus: SSO + SCIM; OIDC/JWT auth; audit logs; secret managers + key rotation; org and team admins; multi-region control plane; 24/7 support and SLAs; dedicated support and onboarding; annual request capacity with volume discounts; self-hosted, with air-gap available |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
13.1k GitHub commits 90d63.0k GitHub stars0 vulnerabilities across 1 package
See all signals from 4 sources
PyPI · litellm@1.108.3
Alternatives
The SDK alone. If one team calls models from Python and needs no shared keys or budgets, install the Python SDK (
uv add litellm) and skip running the proxy. A slimmer litellm-core distribution, with the sameimport litellmAPI but no optional extras, CLI entry points or bundled dashboard, must for now be built from a checkout of the repository with Git, uv and the Rust build toolchain while its release integration is pending.Portkey and Bifrost. LiteLLM's own benchmark (AI Gateway Bench, identical hardware, the same deterministic mock upstream, a single client) reports p99 added latency of 0.66 ms for LiteLLM's Rust gateway, 2.29 ms for Portkey and 4.54 ms for Bifrost. These are vendor-run numbers; rerun them on your own traffic if latency decides the choice.
Alternatives to LiteLLM
The reviewed substitutes for LiteLLM among the LLM gateways, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- OpenRouter
- Both are LLM gateways putting one API in front of many providers. LiteLLM is self-hosted and OpenRouter is a hosted service; a team routes through one of them.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Edgee
- Both sit in the request path to reduce LLM cost, but LiteLLM is a general gateway with governance and Edgee narrows to edge token compression. They compete only when cost reduction is the whole requirement.Applies to: Reducing LLM spend in the request path
- Helicone
- Helicone's proxy and LiteLLM's gateway both sit in front of model providers, but Helicone is bought for observability and LiteLLM for routing and governance. They compete only for a small team that wants one service instead of two.Applies to: A single proxy providing both routing and request visibility