Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What LlamaIndex states |
|---|---|
License | Framework: MIT license. LlamaParse: commercial platform, not open source. |
Installation | Python packages: the |
Integrations | Over 300 integration packages for LLM, embedding and vector store providers. |
LlamaParse deployment | SaaS on a secure cloud tenant, with data encrypted in transit and at rest. For enterprises, deployment in private VPCs across all cloud providers. Available on the AWS and Microsoft Azure marketplaces. |
LlamaParse cached data | SaaS cached data is kept for 48 hours, then permanently deleted. You can turn caching off. |
Compliance | LlamaParse is certified for SOC 2 Type II, GDPR and HIPAA. |
Our take
Pick the LlamaIndex framework if you want a free, self-run Python library to connect an LLM to your own documents and you will handle index storage yourself. Add LlamaParse only if parsing complex documents, such as tables, charts or handwriting, is what limits your answers, and test your own files first, because the credit cost per page depends on the parsing mode you choose.
Evaluate LlamaIndex
Comparisons
Where it stands out
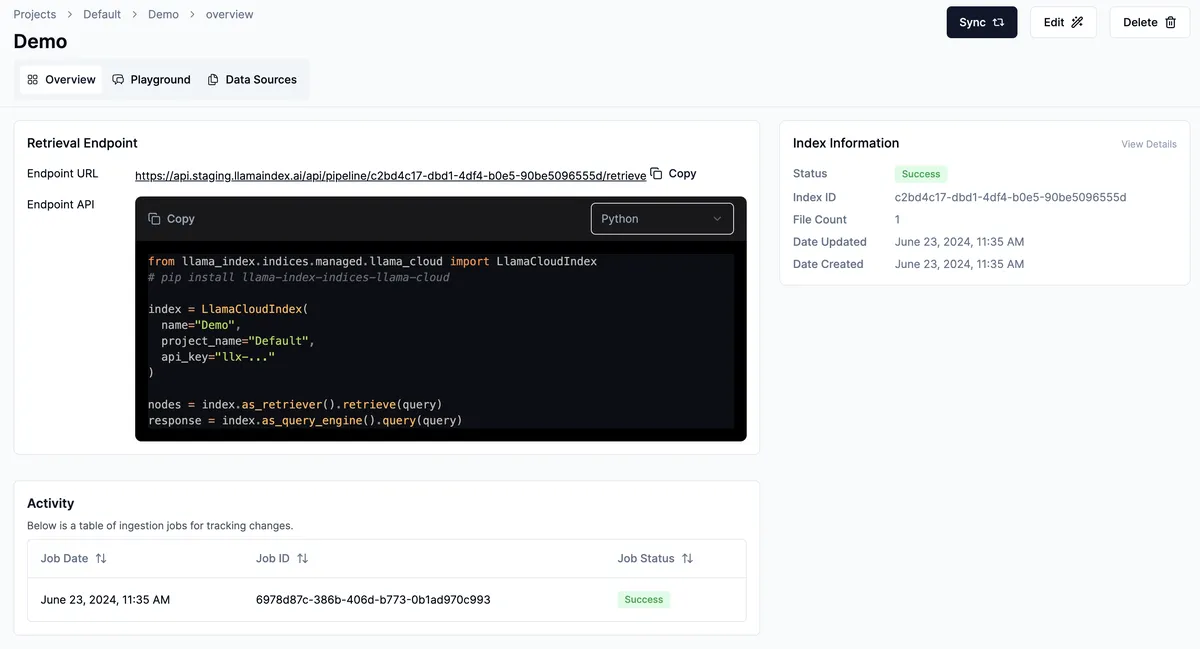
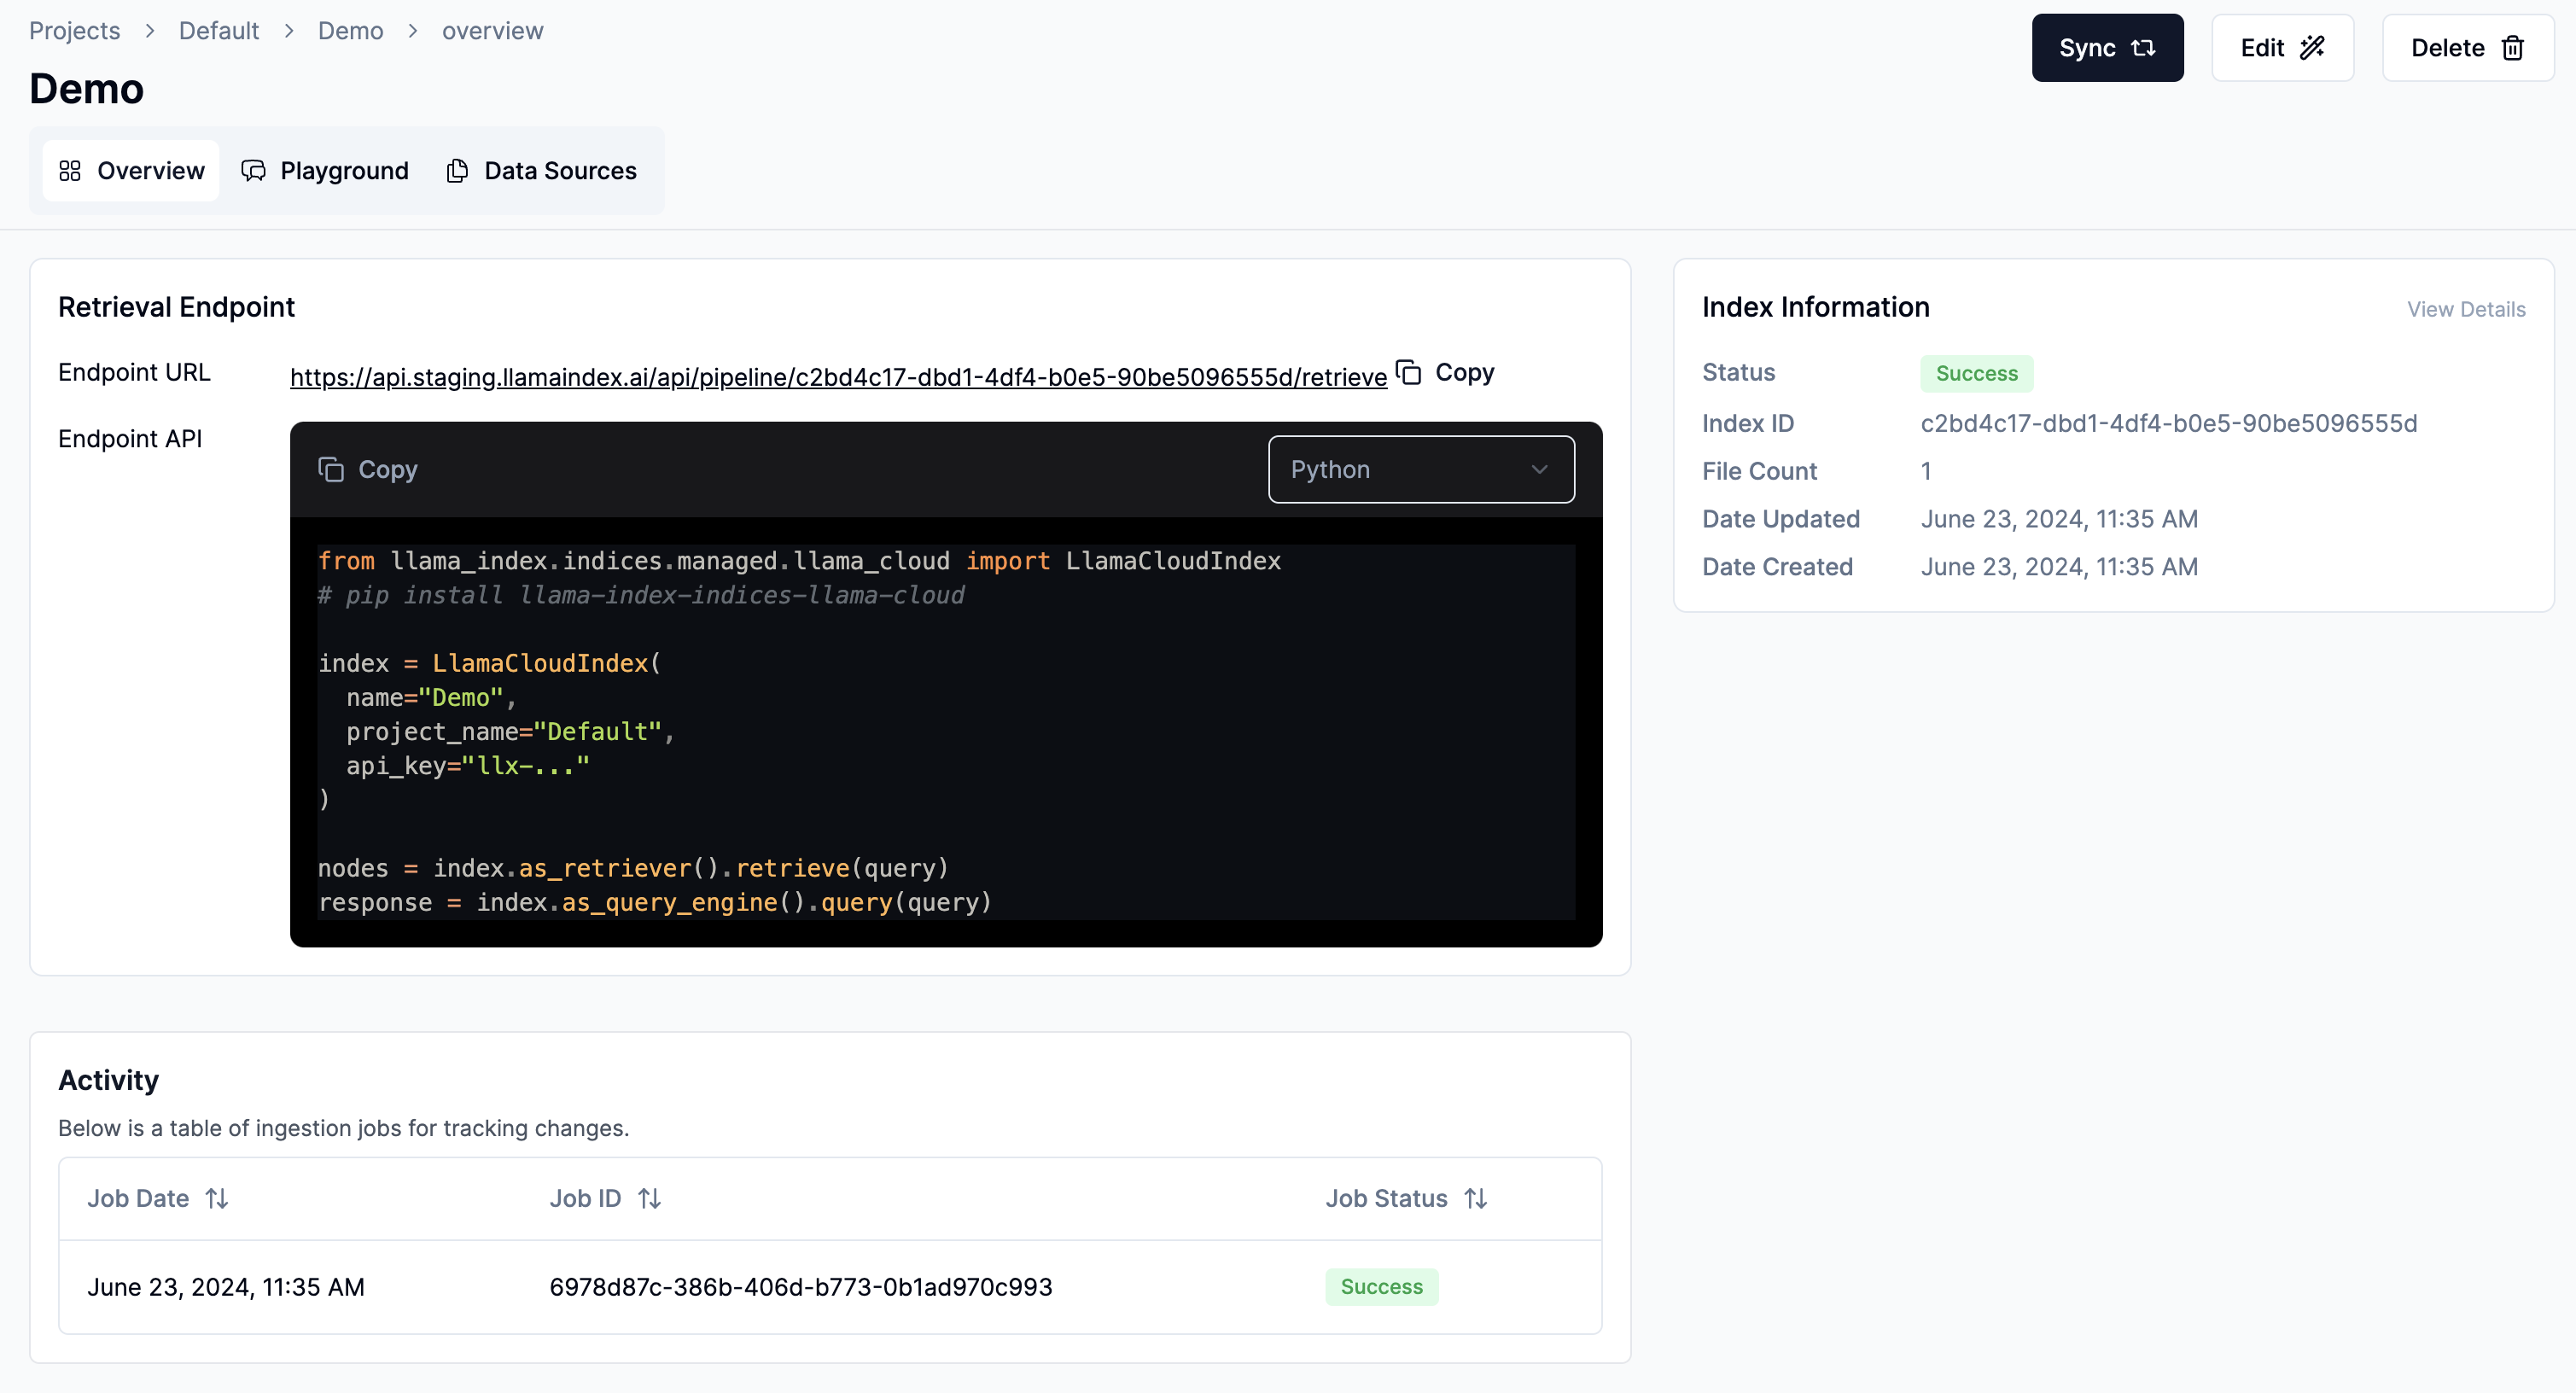
Quick start, deep control. The high-level API ingests and queries data in 5 lines of code. Lower-level APIs let you customise data connectors, indices, retrievers, query engines and reranking modules when answer quality needs work.
Not tied to one model vendor. The README walks through building an index with an LLM hosted through Ollama and a Hugging Face embedding model, not only with OpenAI.
Parsing for hard documents. LlamaParse handles 130+ file formats. Its plan comparison lists advanced table, chart and image extraction, layout detection with bounding boxes, structured JSON output and 80+ languages.
Ways to spend fewer credits. LlamaParse lists Auto Mode, which routes each page to a parse tier (the vendor says it saves up to 80%), and smart result caching, where a re-parse costs 0 credits.
A free local parser. LiteParse is the vendor's fully open-source parser for PDFs, Office documents and images. It runs locally with no cloud and no LLM tokens.
Product screenshot
Trade-offs to weigh
The framework is no longer the vendor's main product. The README says the company's primary focus has shifted to LlamaParse, LiteParse and benchmarking. The framework is still available as an open toolkit. If you build on it for years, weigh how much new work it will get.
Persistence is your job. By default the framework keeps index data in memory. You persist it to disk and reload it yourself, or connect a vector store through an integration.
LlamaParse plans cap scale, not only credits. The plan comparison sets per-plan limits on concurrent parse, extract and index jobs, on the number of indexes and on files per index, up to 2,000 files per index. On Free, external data sources are file upload only. Enterprise lists 5x higher rate limits. Check the limits for your plan before you size a pipeline.
Pricing and plan conditions
The framework has no license fee under MIT. The plans below are for LlamaParse. It bills in credits: each action, such as parsing, indexing or extracting, costs credits, and 1,000 credits = $1.25. The cost of a page depends on the mode. Basic parsing can cost as little as 1 credit, while layout-aware agentic parsing with LLMs or VLMs costs more credits. The vendor recommends testing new document types with different settings before you set up persistent pipelines. Startups can apply to a startup program for free credits.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Free | $0/month | 10K credits included (the homepage says 10,000 free credits per month, about 1,000 pages). No pay-as-you-go: upgrade to Starter for that. 100 users. The plan card says basic support; the plan comparison lists Community support for Free. |
Starter | $50/month | 40K credits included. Pay-as-you-go up to 400K credits (shown as up to $500/mo in the plan comparison). 100 users. Basic support (the plan comparison says Basic: email support). |
Pro | $500/month | 400K credits included. Pay-as-you-go up to $5,000/mo. 100 users, priority Slack support. Limited-time bonus: 800k credits ($1,000), one-time, for business email domains only; unused bonus credits expire immediately if you downgrade. |
Enterprise | Custom | Volume discount on credits, Enterprise SSO, SaaS or hybrid cloud deployment, dedicated account manager. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
92 GitHub commits 90d52.7k GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
PyPI · llama-index@0.14.25
Alternatives to LlamaIndex
The reviewed substitutes for LlamaIndex among the agent frameworks, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Haystack
- Haystack and LlamaIndex are both open-source frameworks for building production retrieval over your own documents, and a team standardises on one pipeline abstraction. LlamaIndex gives the shortest path from a document corpus to a queryable index with the widest connector set, while Haystack makes every pipeline step serializable, testable and validated at build time.Applies to: Building and operating a retrieval pipeline over a private corpus in open source. Haystack stands in for LlamaIndex when the team wants strict component contracts and testable pipelines; LlamaIndex stands in when indexing and retrieval quality over a large corpus is the job and connector breadth matters most.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Dify
- Cross-class on purpose: Dify is a low-code agent builder and LlamaIndex a code-first framework, so they are not the same product, and the substitution is real anyway for one workload. Dify ships RAG -- knowledge base, configurable chunking, hybrid search -- behind a visual canvas, which removes the reason to write ingestion and index code at all when engineering time rather than retrieval depth is the constraint. Conditional and one-directional in emphasis: LlamaIndex's indexing strategies and connector ecosystem have no Dify equivalent, and Dify's non-engineer authoring has no LlamaIndex equivalent.Applies to: Standing up a RAG chatbot over company documents. Dify stands in for LlamaIndex when the team wants it built and maintained without framework code; LlamaIndex stands in when the corpus or the retrieval strategy is the hard part.
- CrewAI
- CrewAI and LlamaIndex are both frameworks for building LLM applications with agents. CrewAI organises the work as a crew of agents with roles that collaborate on a task; LlamaIndex centres on ingesting, indexing and querying a private document corpus, with a simpler agent loop on top, and CrewAI has no indexing layer of its own.Applies to: Building an LLM application where the work divides into roles. CrewAI stands in for LlamaIndex when the job is role-based multi-agent collaboration a product team can read; LlamaIndex stands in when the job is indexing and querying a private corpus and the agent loop is simple.
- OpenAI Agents SDK
- OpenAI's File Search tool is described as RAG functionality with less work: it parses and chunks documents, creates and stores embeddings, and runs vector plus keyword search with query optimisation and reranking built in, billed at $2.50 per thousand queries and $0.10 per GB per day. Paired with the Agents SDK that covers the agent loop, handoffs and tracing, it removes the reason an OpenAI-committed team would build an ingestion and index layer at all. Conditional: it is a single hosted store with no connector ecosystem, and the substitution ends the moment a second model provider or a self-hosted index is required.
- PydanticAI
- The buyer guides put these two on the same side of the fork and then choose between them: 'you want a simple agent + tools + run loop: LlamaIndex or PydanticAI'. PydanticAI is picked when type safety and validated structured output are non-negotiable and the team wants idiomatic Python rather than a new paradigm. Conditional because PydanticAI ships no retrieval or indexing layer: it substitutes on the agent loop, not on the corpus.Applies to: A straightforward agent-plus-tools loop in Python. PydanticAI stands in for LlamaIndex when validated structured output is the requirement; LlamaIndex stands in when the same loop has to retrieve from a document corpus it also ingests and indexes.
- Semantic Kernel
- Semantic Kernel and LlamaIndex both orchestrate an LLM over enterprise data with memory, connectors and planning. Semantic Kernel is Microsoft's SDK for C#, Python and Java and suits a .NET or Azure-aligned shop, while LlamaIndex is Python-first and adds an ingestion and indexing layer that Semantic Kernel has no equivalent for.Applies to: Building LLM applications over internal data inside a Microsoft stack. Semantic Kernel stands in for LlamaIndex when the codebase is .NET and the deployment is Azure; LlamaIndex stands in when the work is Python-first and the hard part is ingesting and indexing a document corpus.
- Google Agent Development Kit
- Google's open agent framework — hierarchical multi-agent composition, graph workflows that mix deterministic code with model reasoning, a local dev UI and evaluation harness, and a deployment path onto Vertex AI Agent Engine. Python, TypeScript, Go, Java and Kotlin.
- Agno
- Agno ships the knowledge layer rather than expecting you to assemble one: built-in memory and knowledge stores, 25+ vector databases and 29 embedder options, with agent instructions, tools, memory and knowledge declared together. Reviewers describe it as the simpler development experience for common RAG use cases. That is LlamaIndex's job done with a smaller surface, so a team building an ordinary knowledge agent chooses one. Conditional: LlamaIndex keeps the deeper indexing strategies and connector ecosystem for a large or awkward corpus.Applies to: An agent that answers from a knowledge base with ordinary documents. Agno stands in for LlamaIndex when the retrieval need is standard and speed of assembly matters; LlamaIndex stands in when ingestion, chunking and index strategy are themselves the problem.
- LangChain
- LangChain and LlamaIndex are both frameworks a team builds an LLM application on. LlamaIndex is strongest at ingestion, indexing and retrieval over private data, while LangChain, with LangGraph, is strongest at chains, tools and stateful multi-step agents, so the centre of the application decides.Applies to: Building an LLM application, and whether the centre of it is retrieval or orchestration.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- LangGraph
- Not a substitute, and the extractor proposed it as one. The 2026 buyer guidance is explicit that this pair is used together rather than chosen between: LlamaIndex for ingestion and retrieval, LangGraph for orchestration and agent control flow, which multiple enterprise sources describe as the pattern production teams already follow. LangGraph brings no ingestion or indexing layer, so it cannot stand in for the half of LlamaIndex a reader comes for. Recorded as complementary so it stays off the alternatives grid instead of telling a reader to pick one.Applies to: Retrieval and stateful agent orchestration in one application: LlamaIndex indexes and retrieves, LangGraph runs the multi-step agent over it.