Decision comparison
BentoML vs Weights & Biases
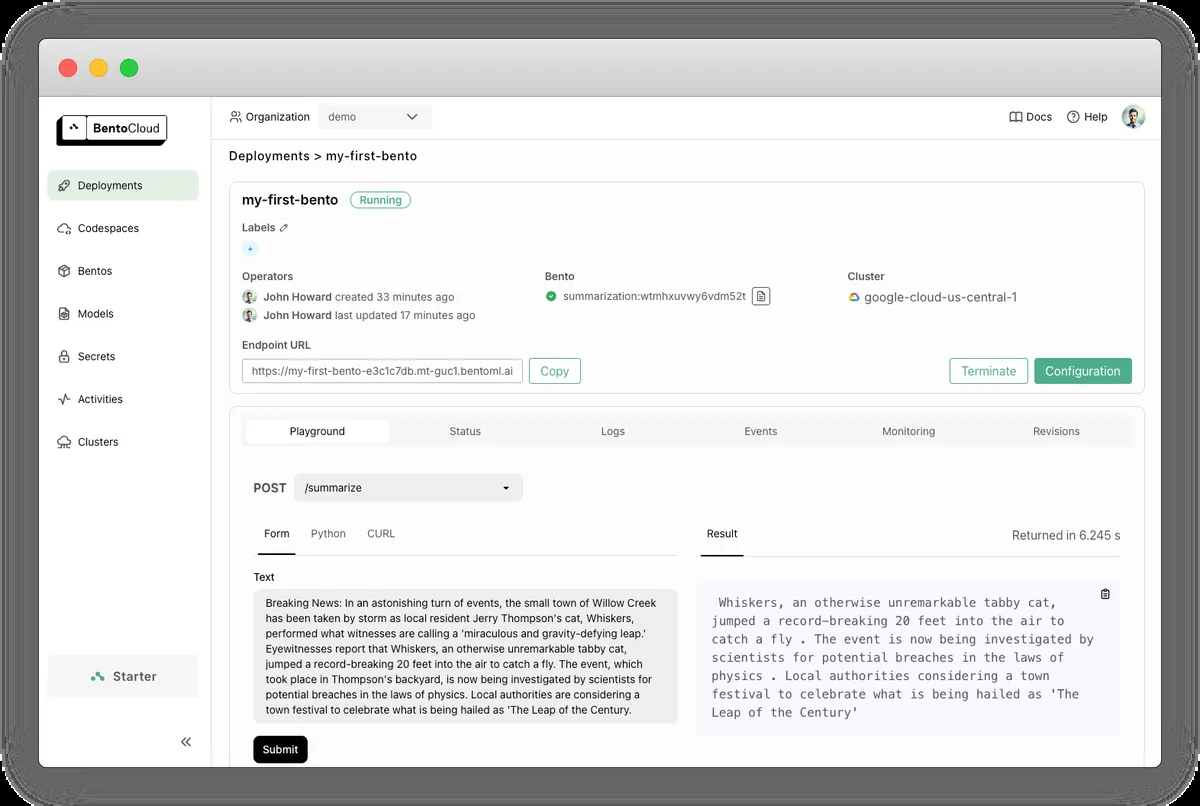
BentoML and Weights & Biases serve different stages of the ML lifecycle and are best understood as complementary tools rather than direct alternatives. BentoML excels at the production deployment side: packaging models into portable Bento archives, optimizing inference for latency, throughput, and cost, and managing production infrastructure with intelligent auto-scaling and multi-cloud orchestration. Weights & Biases excels at the development side: tracking experiments with full reproducibility, comparing model performance through rich visualizations, running hyperparameter sweeps, and managing model artifacts across teams. Many production ML teams use both tools together, with W&B guiding model development and BentoML handling deployment. Organizations that need to choose one should base their decision on where their bottleneck sits today.
Used together. These are normally used together rather than chosen between. The comparison explains what each one does in the stack.
These are different kinds of product — Model Serving and Experiment Tracking.
Quick Comparison
| Decision factor | BentoML | Weights & Biases |
|---|---|---|
| Primary Focus | Model serving, inference optimization, and production deployment of AI models | Experiment tracking, model visualization, hyperparameter optimization, and ML collaboration |
| Core Workflow | Package models into Bentos, optimize inference, deploy and scale across any infrastructure | Log experiments, compare runs, sweep hyperparameters, register models, evaluate AI applications |
| Deployment Model | Self-hosted open source, BYOC, on-prem Kubernetes, or fully managed BentoCloud | Cloud-hosted SaaS, self-hosted server via Docker, or dedicated cloud with Enterprise tier |
| Pricing Model | Free and open source | Weights & Biases is now part of CoreWeave Forge, whose pricing page lists the plans. Free: $0 per month, up to 5 model seats, 5 GB of storage and 1 GB of Weave data ingestion a month. Pro: starts at $60 per month, billed monthly, for early-stage teams with fewer than 50 employees; up to 10 model seats, 100 GB of storage and 1.5 GB of Weave data ingestion a month; additional storage $0.03 per GB and additional Weave data ingestion $0.10 per MB. Enterprise: custom plans with customizable seats, storage and ingestion; additional Weave data ingestion $0.20 per MB. Academic: free, with unlimited projects and teams and 200 GB of cloud storage. Verified 2026-10-09 against https://coreweave.com/forge-pricing. |
| Open Source | Fully open source under Apache 2.0 with 8,500+ GitHub stars | Open-source Python client under MIT license with 11,000+ GitHub stars |
| Best For | AI teams deploying models to production who need inference optimization and infrastructure control | ML teams focused on experiment tracking, model comparison, and collaborative model development |
BentoML
- Primary Focus:
- Model serving, inference optimization, and production deployment of AI models
- Core Workflow:
- Package models into Bentos, optimize inference, deploy and scale across any infrastructure
- Deployment Model:
- Self-hosted open source, BYOC, on-prem Kubernetes, or fully managed BentoCloud
- Pricing Model:
- Free and open source
- Open Source:
- Fully open source under Apache 2.0 with 8,500+ GitHub stars
- Best For:
- AI teams deploying models to production who need inference optimization and infrastructure control
Weights & Biases
- Primary Focus:
- Experiment tracking, model visualization, hyperparameter optimization, and ML collaboration
- Core Workflow:
- Log experiments, compare runs, sweep hyperparameters, register models, evaluate AI applications
- Deployment Model:
- Cloud-hosted SaaS, self-hosted server via Docker, or dedicated cloud with Enterprise tier
- Pricing Model:
- Weights & Biases is now part of CoreWeave Forge, whose pricing page lists the plans. Free: $0 per month, up to 5 model seats, 5 GB of storage and 1 GB of Weave data ingestion a month. Pro: starts at $60 per month, billed monthly, for early-stage teams with fewer than 50 employees; up to 10 model seats, 100 GB of storage and 1.5 GB of Weave data ingestion a month; additional storage $0.03 per GB and additional Weave data ingestion $0.10 per MB. Enterprise: custom plans with customizable seats, storage and ingestion; additional Weave data ingestion $0.20 per MB. Academic: free, with unlimited projects and teams and 200 GB of cloud storage. Verified 2026-10-09 against https://coreweave.com/forge-pricing.
- Open Source:
- Open-source Python client under MIT license with 11,000+ GitHub stars
- Best For:
- ML teams focused on experiment tracking, model comparison, and collaborative model development
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | BentoML | Weights & Biases |
|---|---|---|
| GitHub commits, 90d(Product adoption) | 13 | 514 |
| GitHub stars(Product adoption) | 8,500+ | 11,000+ |
| Search interest(Market interest) | Unavailable | 0 |
| PyPI weekly downloads(Product adoption) | 43.4k | 4.6M |
| Stack Overflow questions(Community interest) | 8 | 139 |
| Docker Hub pulls(Product adoption) | Not available | 4.1M |
| Hacker News mentions, 90d(Community interest) | Not available | 0 |
| Hugging Face downloads(Product adoption) | Not available | 3.3k |
| Hugging Face likes(Product adoption) | Not available | 33 |
| npm weekly downloads(Developer adoption) | Not available | 3.8k |
| Product Hunt comments(Community interest) | Not available | 8 |
| Product Hunt rating(Community interest) | Not available | 5.0/5 |
| Product Hunt reviews(Community interest) | Not available | 3 |
| Product Hunt votes(Community interest) | Not available | 110 |
As of November 9, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
BentoML
November 9, 2026Package vulnerabilities
PyPI · bentoml@1.4.40
0 vulnerabilities
across 1 package
Repository security score
Not available
Weights & Biases
November 9, 2026Package vulnerabilities
npm · @wandb/sdk@0.5.1 · PyPI · wandb@0.31.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Interface Preview
BentoML
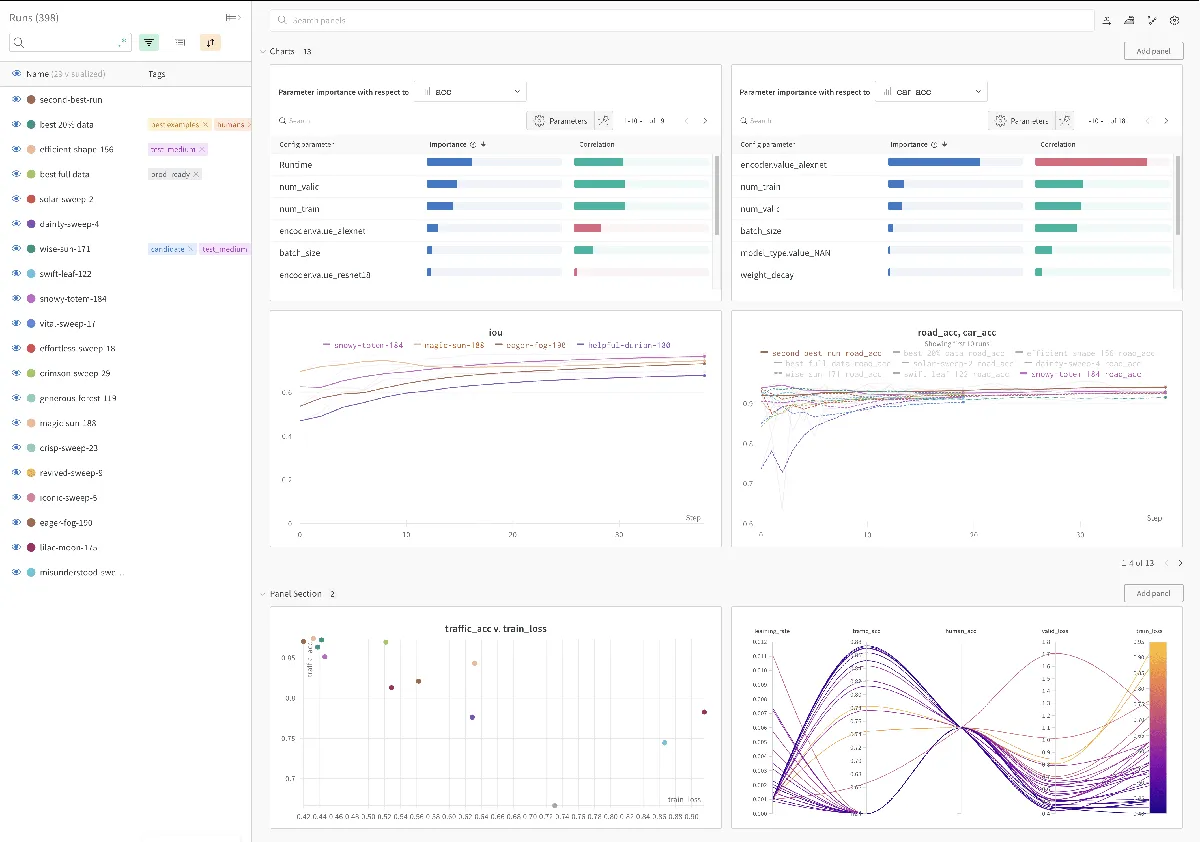
Weights & Biases
Feature Comparison
| Feature | BentoML | Weights & Biases |
|---|---|---|
| Model Serving & Deployment | ||
| Model Serving Framework | Unified framework for packaging and serving models of any architecture, framework, or modality | Not a model serving platform; focused on tracking and managing models before deployment |
| Inference Optimization | Tailored optimization with automatic configuration tuning for latency, throughput, and cost goals | Not applicable; W&B operates in the experiment and training phase, not the inference phase |
| Auto-Scaling | Intelligent auto-scaling with cold-start acceleration, scaling-to-zero, and inference-specific metrics | Not applicable; W&B does not manage production inference infrastructure |
| Experiment Tracking & Visualization | ||
| Experiment Logging | Not a core capability; BentoML focuses on serving rather than experiment tracking | Comprehensive logging of metrics, hyperparameters, git commits, model weights, GPU usage, and datasets |
| Run Comparison & Visualization | Not offered; teams typically use external tools for experiment comparison | Rich interactive dashboards for comparing runs, visualizing metrics, and analyzing training dynamics |
| Hyperparameter Sweeps | Not offered; hyperparameter tuning is outside BentoML's scope | Built-in sweep agents supporting grid, random, and Bayesian optimization strategies |
| Model Management | ||
| Model Registry | Local Model Store for saving, loading, and managing models with versioning via Bento archives | Centralized model registry with lineage tracking, artifact versioning, and lifecycle management |
| Model Packaging | Bento archives bundle source code, models, data, and configurations into deployable units | Artifact logging and versioning for models; does not produce deployment-ready packages |
| CI/CD Integration | Deployment automation with version control, canary releases, shadow deployments, and A/B testing | CI/CD automations with webhook triggers, Slack alerts, and email notifications for model events |
| Infrastructure & Operations | ||
| GPU Management | Access to Nvidia B200, H100, H200 and AMD MI300X GPUs; multi-GPU distributed inference support | GPU usage tracking and monitoring during training; does not provision or manage GPU infrastructure |
| Observability | Full observability with compute tracking, LLM-specific metrics, performance monitoring, and system health | AI application tracing and evaluation scorers for monitoring production AI application behavior |
| Multi-Cloud Support | Cross-region scaling with BYOC, on-prem Kubernetes, and Bento Cloud across multiple providers | Cloud-hosted SaaS with single-tenant Enterprise option and choice of region; self-hosted server available |
| Collaboration & Security | ||
| Team Collaboration | Fine-grained access control and resource quota tracking; Enterprise tier adds SSO and audit logs | Unlimited teams, team-based access controls, and service accounts on Pro; custom roles on Enterprise |
| Compliance & Security | SOC 2 Type II, data sovereignty controls, and enterprise-grade security with on-prem deployment | HIPAA compliant option, customer-managed encryption keys, SSO, SCIM provisioning, and audit logs |
| Support Tiers | Community Slack on Starter; dedicated Slack channel on Scale; dedicated support engineering on Enterprise | Community support on Free; priority email and chat on Pro; enterprise support package on Enterprise |
Model Serving & Deployment
Model Serving Framework
Inference Optimization
Auto-Scaling
Experiment Tracking & Visualization
Experiment Logging
Run Comparison & Visualization
Hyperparameter Sweeps
Model Management
Model Registry
Model Packaging
CI/CD Integration
Infrastructure & Operations
GPU Management
Observability
Multi-Cloud Support
Collaboration & Security
Team Collaboration
Compliance & Security
Support Tiers
How they fit together
BentoML and Weights & Biases serve different stages of the ML lifecycle and are best understood as complementary tools rather than direct alternatives. BentoML excels at the production deployment side: packaging models into portable Bento archives, optimizing inference for latency, throughput, and cost, and managing production infrastructure with intelligent auto-scaling and multi-cloud orchestration. Weights & Biases excels at the development side: tracking experiments with full reproducibility, comparing model performance through rich visualizations, running hyperparameter sweeps, and managing model artifacts across teams. Many production ML teams use both tools together, with W&B guiding model development and BentoML handling deployment. Organizations that need to choose one should base their decision on where their bottleneck sits today.
What each one handles
Use BentoML for:
Choose BentoML if your primary challenge is getting models into production and keeping them running reliably at scale. BentoML provides a complete inference platform that handles model packaging, inference optimization, auto-scaling, and multi-cloud deployment. Its open-source core under Apache 2.0 gives you full control over your infrastructure without licensing constraints, and BentoCloud adds managed GPU access and enterprise features when you need them. AI teams deploying LLMs, computer vision models, or multi-model pipelines will find BentoML's unified serving framework and advanced deployment patterns like canary releases and distributed inference especially valuable.
Use Weights & Biases for:
Choose Weights & Biases if your primary challenge is experiment management, model comparison, and team collaboration during the training and development phase. W&B provides the most comprehensive experiment tracking available, with automatic logging of metrics, hyperparameters, git state, model weights, and datasets that makes every run fully reproducible. The platform's visualization dashboards and hyperparameter sweep capabilities accelerate the model selection process. Its free tier supports up to 5 model seats, and the Pro tier starts at $60/month, billed monthly, while unlocking unlimited teams and priority support. ML teams that need to standardize how they track, compare, and hand off models will get the most value from W&B.
These roles reflect the available product evidence. Most teams run both; which one owns a given job depends on your stack and team.
Frequently Asked Questions
What is the main difference between BentoML and Weights & Biases?
BentoML and Weights & Biases address different stages of the ML lifecycle. BentoML is an inference platform focused on model serving, deployment, and production scaling. It packages trained models into deployable units called Bentos, optimizes inference performance, and manages production infrastructure. Weights & Biases is an experiment tracking and model management platform focused on the training and development phase. It logs experiments, visualizes metrics, runs hyperparameter sweeps, and manages model artifacts. The two tools are complementary rather than competing.
Can BentoML and Weights & Biases be used together?
Yes, and this is a common pattern in production ML workflows. Teams use Weights & Biases during the training and experimentation phase to track runs, compare model performance, and select the best model. They then use BentoML to package that model into a Bento archive, optimize its inference performance, and deploy it to production infrastructure. W&B handles everything before deployment; BentoML handles everything after. Both tools integrate with popular ML frameworks like PyTorch, TensorFlow, and JAX.
Which tool is better for deploying models to production?
BentoML is purpose-built for production deployment. It provides a unified framework for packaging models of any architecture into deployable units, optimizing inference with automatic configuration tuning, and scaling across multiple clouds or on-prem infrastructure. BentoML supports advanced deployment patterns like canary releases, shadow deployments, and A/B testing. Weights & Biases does not serve or deploy models to production; it tracks and manages models during the development phase and hands off to deployment tools like BentoML.
How do pricing models compare between BentoML and Weights & Biases?
BentoML's open-source core is completely free under the Apache 2.0 license. BentoCloud, the managed platform, offers a Starter tier with pay-as-you-go compute pricing, a Scale tier for teams needing priority GPU access and dedicated compute pools, and an Enterprise tier for full VPC or on-prem control. Weights & Biases offers a free tier with up to 5 model seats and 5 GB storage, a Pro tier that starts at $60/month, billed monthly, with 10 model seats and 100 GB storage, and a custom-priced Enterprise tier. W&B also provides a 30-day free trial on Pro.
Which tool has better open-source community support?
Both tools have strong open-source communities. BentoML has over 8,500 GitHub stars and is fully open source under Apache 2.0, with its entire inference framework available for self-hosting. Weights & Biases has over 11,000+ GitHub stars for its Python client library, which is open source under MIT. However, the W&B server platform itself is proprietary. BentoML offers more flexibility for teams that want to run everything on their own infrastructure without licensing constraints, while W&B provides a more polished managed experience for experiment tracking.