Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What BentoML states |
|---|---|
License | Apache License 2.0 for the open-source framework |
Installation |
|
Packaging |
|
Where it runs | Bring Your Own Cloud, on-prem or Kubernetes; or Bento Cloud with Nvidia and AMD GPUs, including B200, H100 and MI300X |
Framework APIs | Diffusers, ONNX, Scikit-Learn, Transformers, Flax, TensorFlow, TorchScript, XGBoost, Picklable Model, PyTorch, LightGBM, MLflow, CatBoost, fast.ai, EasyOCR, Keras, Ray, Detectron |
Enterprise support | Performance SLAs, 24/7 monitoring, uptime guarantee, automatic failover and Forward Deployed Engineering (dedicated technical experts), listed under Built For Enterprise |
Our take
Choose BentoML if your team writes Python and wants one way to package models as inference APIs, while keeping the option to self-host the Apache-2.0 framework or move to BentoCloud or your own cloud later. If you want an endpoint that scales well without load testing and configuration work, budget for that work first or look at a more hands-off service.
Evaluate BentoML
Comparisons
Where it stands out
Python code becomes an API. BentoML turns an inference script into a REST API server with a few lines of code and standard Python type hints, and
bentoml serveruns it locally athttp://localhost:3000by default. Data scientists can test the same service they ship.Serving optimizations are built in. BentoML lists dynamic batching, model parallelism, multi-stage pipelines and multi-model inference graphs, and says it supports any ML framework, modality and inference runtime.
Ready for open LLMs. The platform's Open Model Catalog covers Llama 4, DeepSeek, Ling/Ring, Flux, Qwen and GPT-OSS. Custom serving works with vLLM, TRT-LLM, JAX, SGLang, PyTorch and Transformers, and distributed LLM inference runs large models across multiple GPUs.
Scaling follows requests, not only CPU. BentoCloud scales replicas on concurrent requests per replica, within your minimum and maximum. In BentoML's own example, with concurrency 32 and 2 replicas it does not scale up until it handles over 64 simultaneous requests, and at 100 concurrent requests it scales to 4 replicas. Setting minimum replicas to 0 turns on scale-to-zero.
Tuning and monitoring aimed at inference. The platform lists automatic search for the best configuration against your latency, throughput or cost requirements, scaling on inference-specific metrics for auto-regressive models, and cold-start acceleration. Its Full Observability tracks compute and performance, LLM-specific metrics and system health.
One platform for several workload shapes. BentoML lists interactive applications with sub-second latency, async long-running tasks, large-scale batch inference and multi-model chains for RAG and compound AI systems.
Release and iteration tooling. The platform lists version control with rollbacks, canary, shadow and A/B testing, a Dev Codespace for cloud GPU runs, and an LLM Gateway with one API across LLM providers. On BentoML's site, Neurolabs CTO Patric Fulop says scale-to-zero and BYOC have saved them a considerable amount of money.
Product screenshot
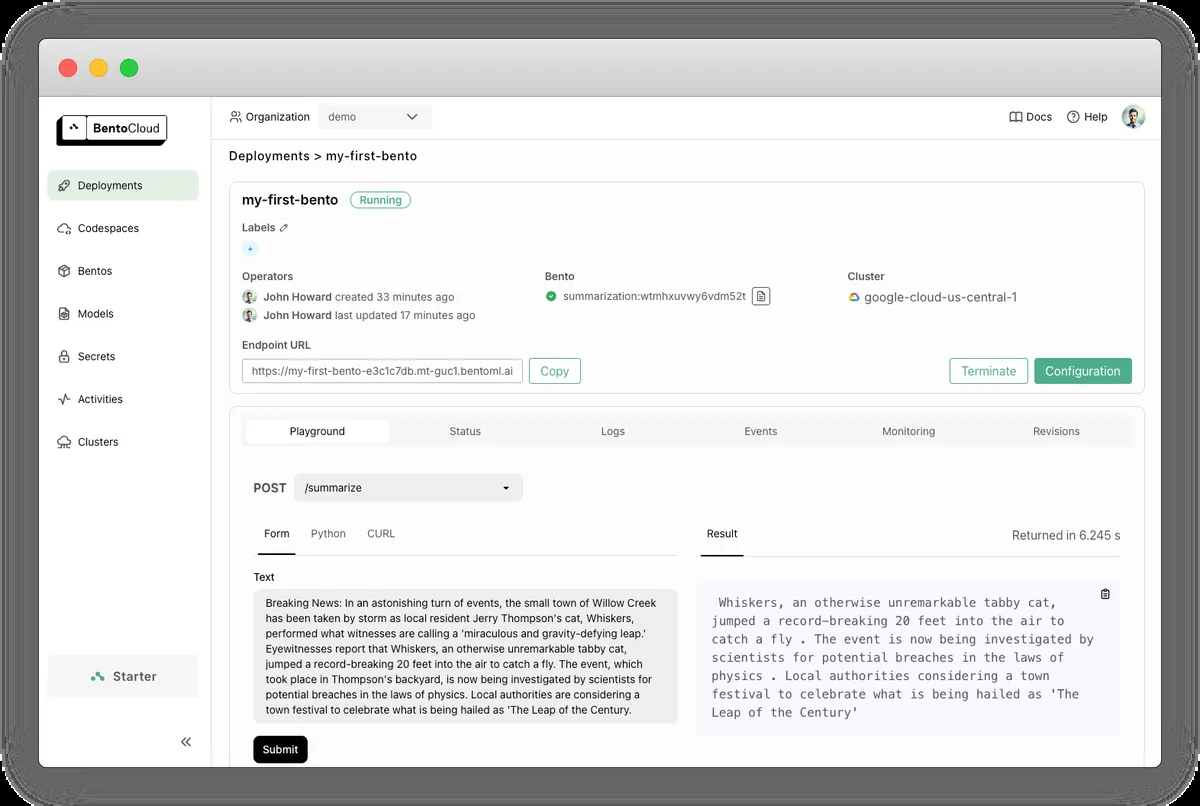

Trade-offs to weigh
You must tune concurrency yourself. BentoML sets no concurrency limit by default. If you leave it unset, the Service autoscales only on CPU utilization, which BentoML says may not be optimal. BentoML recommends a stress test with a tool such as Locust to find the right value.
The external queue protects replicas but adds latency. The
external_queuesetting is a BentoCloud-only field that holds excess requests until the Service has capacity. BentoML notes it increases the latency of the Service.Scale-to-zero means the first request waits. When a Deployment at zero replicas receives a request, the request is queued until the Service scales up; the timeout timer starts only after that. You can trigger the scale-up early with a GET request to
/readyz.The scaling controls are documented for BentoCloud. The concurrency and autoscaling guide describes how BentoCloud autoscales Deployments, with a stabilization window from 0 to 3600 seconds set in a YAML or JSON file passed to
bentoml deploy. If you self-host the Docker image on Kubernetes, check how you will get the same behaviour.Usage tracking is on unless you turn it off. The framework sends anonymous usage data about BentoML's internal API calls, excluding user code, model data, model names and stack traces. Opt out with
--do-not-trackorBENTOML_DO_NOT_TRACK=True.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
13 GitHub commits 90d8.9k GitHub stars0 vulnerabilities across 1 package
See all signals from 5 sources
Three-month score against stable baseline terms—not search volume or adoption.
PyPI · bentoml@1.4.40
Alternatives to BentoML
The reviewed substitutes for BentoML among the model serving, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Seldon
- BentoML and Seldon both put trained models into production as scalable inference services. BentoML is an open-source framework for packaging models into AI applications that can be deployed anywhere, with BentoCloud as a managed option, while Seldon centers on Kubernetes-native serving with traffic routing, A/B tests, drift detection and explainability.Applies to: Choosing between two products of the same kind for one job.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- MLflow
- A tracker records runs and model versions; a serving framework packages a model and exposes it behind an endpoint. The usual pipeline registers in one and deploys with the other, so they are deployed together.Applies to: Whether an experiment tracker can deploy models, or a serving framework is needed.
- Weights & Biases
- A tracker records runs and model versions; a serving framework packages a model and exposes it behind an endpoint. The usual pipeline registers in one and deploys with the other, so they are deployed together.Applies to: Whether an experiment tracker can deploy models, or a serving framework is needed.
See detailed alternatives analysis
If you are evaluating BentoML alternatives, you are likely looking for an inference serving platform, an MLOps framework, or a broader AI infrastructure tool that better fits your team's workflow, deployment environment, or scaling requirements. BentoML occupies a focused niche as an open-source inference platform built for packaging and deploying ML models, but the MLOps landscape offers several strong options depending on whether you need full lifecycle management, distributed computing, or experiment tracking alongside serving.
Top Alternatives Overview
We have identified ten noteworthy alternatives to BentoML, spanning model serving platforms, ML lifecycle tools, and distributed computing frameworks. Here is a summary of what each brings to the table.
MLflow is the most widely adopted open-source AI engineering platform, backed by the Linux Foundation. It covers the full ML lifecycle including experiment tracking, model registry, evaluation, prompt management, and an agent server for production deployment. MLflow integrates with over 100 AI frameworks and is written in Python under the Apache 2.0 license.
Ray is an open-source distributed computing framework developed by Anyscale. It orchestrates infrastructure for any distributed workload across any accelerator, making it especially strong for teams that need to scale training and inference across multiple GPUs or nodes. Ray Serve, its model serving component, handles online inference with features like dynamic batching and model composition.
Kubeflow is a Kubernetes-native platform for deploying, monitoring, and managing ML workflows at scale. It provides pipeline orchestration, model training operators, and a serving component (KServe) that handles inference on Kubernetes clusters. Kubeflow is ideal for teams already invested in the Kubernetes ecosystem.
TensorFlow and PyTorch are the two dominant deep learning frameworks, and both include production serving capabilities. TensorFlow Serving and TorchServe provide dedicated inference endpoints, though they are tightly coupled to their respective framework ecosystems.
Weights & Biases focuses on experiment tracking, model evaluation, and collaboration. It complements serving platforms rather than replacing them directly, and offers a free tier alongside paid plans for teams.
Metaflow, originally developed at Netflix, is a human-centric framework for building and managing real-life data science projects. It handles workflow orchestration and deployment under the Apache 2.0 license.
DVC (Data Version Control) brings Git-like version control to datasets, models, and experiments. It works with any storage backend and integrates into CI/CD pipelines, focusing on reproducibility rather than model serving.
Kedro, developed by McKinsey's QuantumBlack and now part of the Linux Foundation, is a Python framework for building reproducible, maintainable data and ML pipelines with a standardized project structure.
ClearML is an open-source MLOps platform that bundles experiment tracking, pipeline orchestration, dataset versioning, model deployment, and compute orchestration in a single tool, with both self-hosted and managed cloud options.
Architecture and Approach Comparison
BentoML follows a "Bento" packaging model where your model, source code, dependencies, and configuration are bundled into a self-contained archive. You define service APIs using Python decorators, and the framework handles serialization, batching, and containerization. BentoCloud extends this with a managed platform for deployment and scaling, featuring inference-specific autoscaling that differs from standard microservice scaling patterns.
MLflow takes a broader lifecycle approach. While it includes model serving via the MLflow Agent Server, its primary strength lies in observability, evaluation, and prompt management built on OpenTelemetry. Teams often use MLflow for tracking and evaluation alongside a dedicated serving solution.
Ray approaches the problem from a distributed computing angle. Ray Serve integrates with the extensive Ray ecosystem for distributed training, data processing, and hyperparameter tuning. This makes it particularly powerful when your inference workloads need to scale dynamically alongside training jobs or when you need multi-model composition.
Kubeflow is deeply tied to Kubernetes primitives. Its serving component, KServe, provides serverless inference with autoscaling, canary rollouts, and multi-framework support. If your infrastructure team already manages Kubernetes clusters, Kubeflow fits naturally into that operational model.
TensorFlow Serving and TorchServe are framework-specific. They offer tight optimization for their respective model formats but lack the framework-agnostic flexibility that BentoML provides. If your models are exclusively TensorFlow or PyTorch, the native serving solutions can be simpler to operate.
ClearML and Weights & Biases both focus on the experiment-to-deployment lifecycle but from different angles. ClearML includes its own serving infrastructure, while Weights & Biases concentrates on tracking and evaluation, leaving serving to other tools.
Metaflow and Kedro are workflow orchestration frameworks. They help structure how you build and deploy ML pipelines but do not provide inference serving directly. DVC similarly focuses on versioning and reproducibility rather than runtime model serving.
Pricing Comparison
BentoML's core framework is free and open source under the Apache 2.0 license. BentoCloud, the managed inference platform, offers cloud-hosted deployment with managed scaling and operations; contact BentoML for current pricing details.
MLflow is entirely open source under Apache 2.0 with no paid tiers. Databricks, the company behind MLflow, offers managed MLflow as part of the Databricks platform.
Ray is open source. Anyscale, the company behind Ray, provides a managed platform. Contact Anyscale for enterprise pricing.
Kubeflow, Metaflow, DVC, and Kedro are all free and open source. DataChain Studio (formerly DVC Studio) is a managed web UI for experiment tracking and collaboration. Kedro is maintained under the Linux Foundation.
Weights & Biases operates on a freemium model with a free tier and paid plans for teams and enterprises. Contact their sales team for Enterprise pricing details.
ClearML is open source with a free self-hosted option. Their managed cloud offering includes paid tiers. Contact ClearML for current pricing.
TensorFlow is free and open source. PyTorch is free and open source, maintained by the PyTorch Foundation under the Linux Foundation.
For teams seeking a fully open-source stack, BentoML combined with tools like MLflow, DVC, and Kedro can cover the full lifecycle at no licensing cost. The main expense shifts to infrastructure and operational overhead.
When to Consider Switching
We recommend evaluating alternatives to BentoML when your requirements have outgrown its core serving focus or when your team's workflow demands a different architectural pattern.
If you need a complete ML lifecycle platform rather than a focused serving tool, MLflow or ClearML may serve you better. They provide experiment tracking, model registry, and evaluation alongside deployment capabilities, reducing the number of tools your team needs to maintain.
If your workloads require distributed computing across multiple GPUs or nodes, Ray offers a more comprehensive solution. Ray Serve handles inference, but the extensive Ray ecosystem also supports distributed training, data processing, and reinforcement learning, all managed through a unified API.
If your organization runs on Kubernetes and you need inference serving that integrates with your existing cluster management, Kubeflow and KServe provide a Kubernetes-native alternative. This is especially relevant for teams with established Kubernetes operations and tooling.
If you are exclusively using TensorFlow or PyTorch models and want serving infrastructure optimized for those specific frameworks, TensorFlow Serving or TorchServe can offer simpler setup and tighter integration with their respective ecosystems.
If your primary pain point is experiment tracking and model comparison rather than serving, Weights & Biases or MLflow might address your needs more directly while you keep BentoML for inference.
Migration Considerations
Migrating from BentoML means rethinking how you package and deploy your models. BentoML's Bento archive format and service decorator pattern are unique to the framework, so model code will need to be adapted to the target platform's conventions.
For a move to Ray Serve, you would replace BentoML service definitions with Ray Serve deployments. Ray uses a similar Python-native approach, so the conceptual translation is relatively straightforward. Your model loading and preprocessing logic can often be reused with minimal changes.
Migrating to Kubeflow's KServe involves creating InferenceService manifests and potentially packaging models in container images rather than Bento archives. Teams familiar with Kubernetes will find this natural, but those new to Kubernetes face a steeper learning curve.
If moving to TensorFlow Serving or TorchServe, you need to export models in the expected format (SavedModel for TensorFlow, TorchScript or eager mode for PyTorch). Custom preprocessing logic that lived in your BentoML service may need to be moved into a separate preprocessing service or embedded in the model graph.
For MLflow, the migration path is well-documented since MLflow supports logging and serving models from many frameworks. You can log your existing models to the MLflow model registry and serve them using the MLflow Agent Server or export them to other serving platforms.
We suggest running the new serving infrastructure in parallel with your existing BentoML deployment during migration. Gradually shift traffic using canary deployments or feature flags to validate performance and correctness before fully cutting over. Ensure that your inference latency and throughput benchmarks are met on the new platform before decommissioning BentoML services.