Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What DVC states |
|---|---|
License | Free and open source, under the Apache license version 2.0 |
Installation | Install with pip, conda, brew, choco or snap, in VS Code, or with self-contained packages for Linux, Windows and Mac (deb and rpm repos included) |
Operating model | Runs on your machine; experiments are tracked in your local Git repo with no servers needed, and teams share work through existing Git hosting such as GitHub or GitLab |
Data storage | Data and model files sit in a cache outside Git; remotes can be any cloud (S3, Azure, Google Cloud and others) or on-premise network storage, for example via SSH |
Intended scale | Presented on dvc.org as a Git extension for small data science projects and individual data scientists |
Our take
If your team already works in Git and needs to know which data, code and parameters produced each model, DVC is a sound free choice. If you need versioning across a large shared data lake rather than per project, look at lakeFS first, which the same site offers for enterprise teams.
Evaluate DVC
Comparisons
Where it stands out
Data versions live next to code. Git stores DVC meta-files as placeholders for the data, so a commit records which data and model versions go with which code.
Pipelines skip unchanged work. DVC pipelines list the code, data and commands for each step; when you change something, only the steps affected by that change run again.
Experiments without a tracking server.
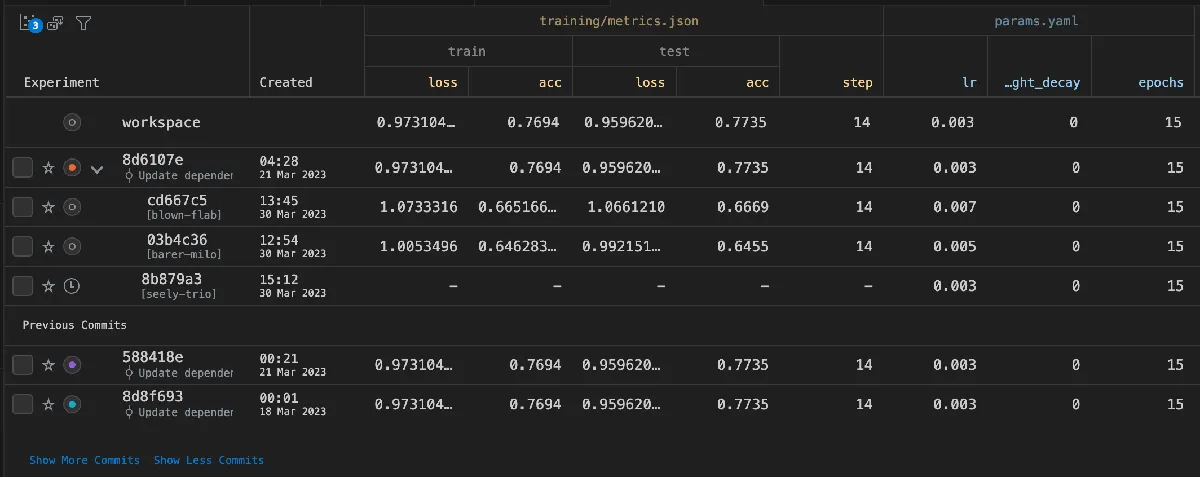
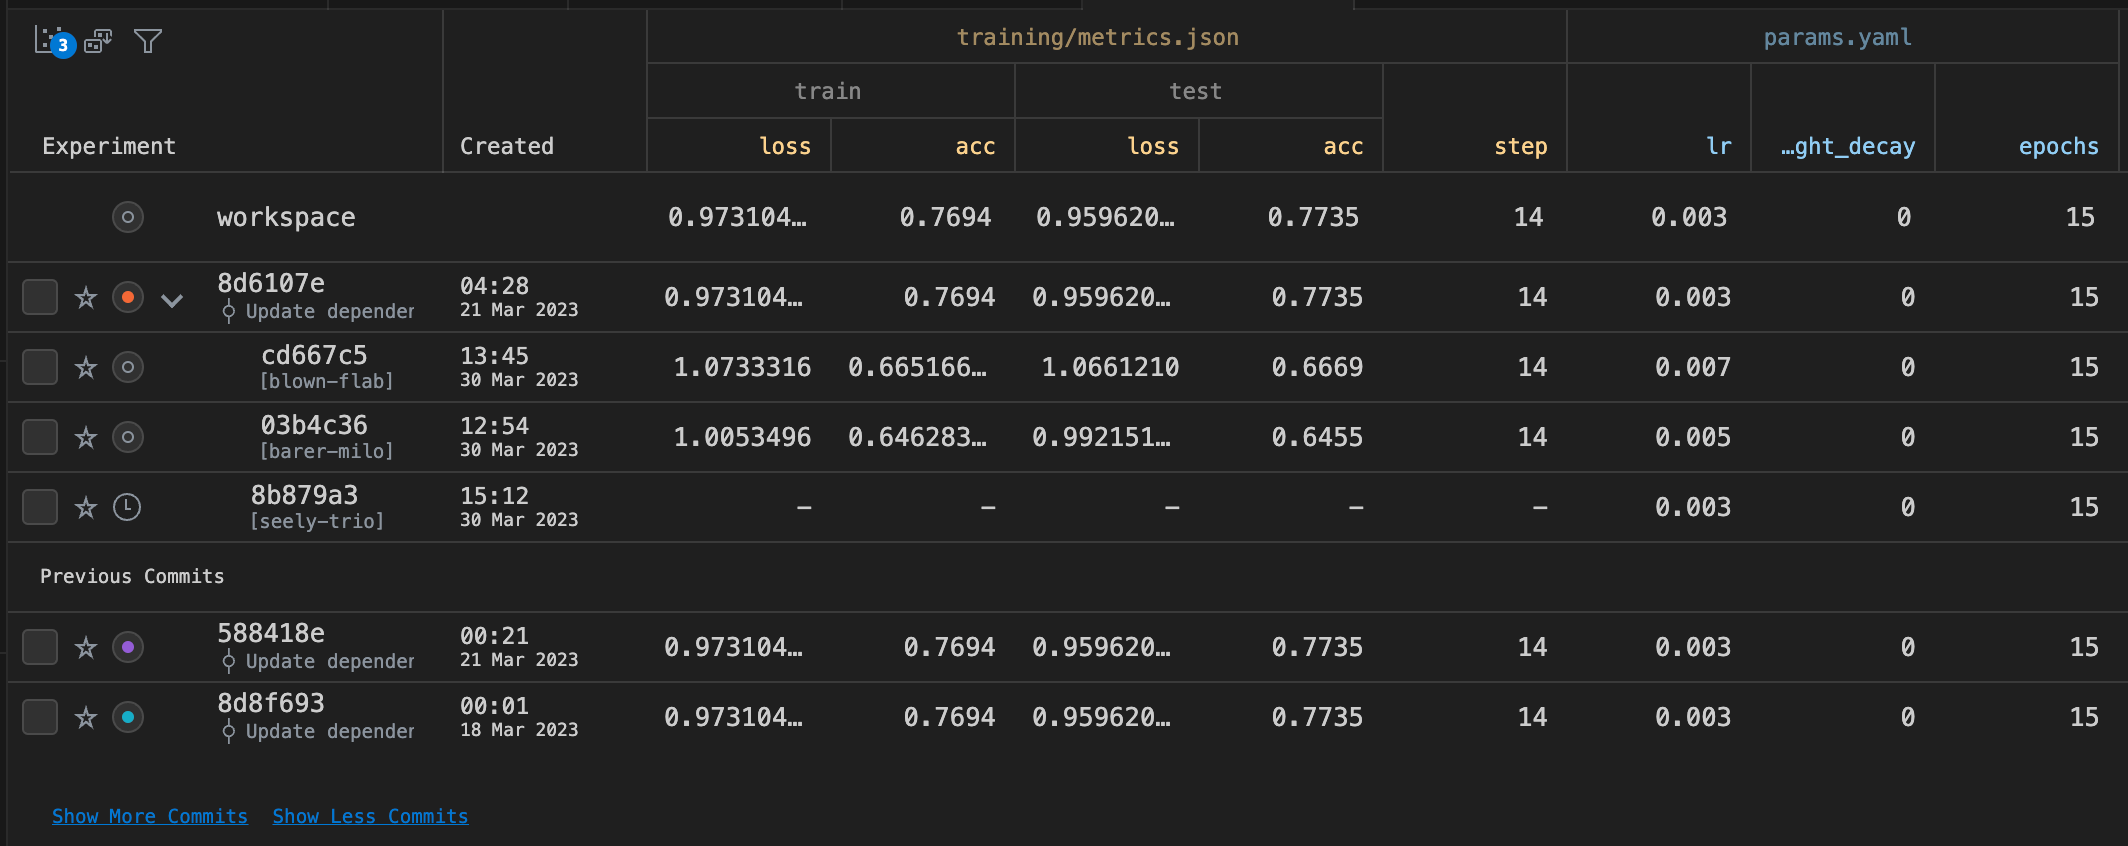
dvc exp runanddvc exp showlet you run, filter and compare many experiments by hyperparameters and metrics, and anyone can reproduce a shared experiment.You keep the storage choice. Because data goes to a remote you add yourself, such as an S3 bucket with
dvc remote add, you are not tied to a vendor-hosted store.
Product screenshot
Trade-offs to weigh
Two tools in every workflow. The usual flow mixes
git add,git commitandgit pushwithdvc add,dvc stage addanddvc push, so people new to Git face a learning curve.The GUI is partial. The VS Code extension currently covers experiment tracking and data management, with data pipeline support described as coming soon, and core DVC still has to be installed separately.
Remote storage needs extras. Depending on your storage type you may need optional packages such as
dvc[s3],dvc-azureordvc-ssh, which is one more thing to pin in team setups.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
8 GitHub commits 90d16.0k GitHub stars0 vulnerabilities across 1 package
See all signals from 4 sources
PyPI · dvc@3.67.1
Alternatives
lakeFS. Offered on dvc.org as lakeFS Team and lakeFS Enterprise for enterprise AI and data engineering teams. The site describes it as highly scalable data version control infrastructure for petabyte-scale multimodal object stores and data lakes.
Git LFS. The DVC README describes DVC as Git for data: it stores and shares data artifacts and models like Git-LFS but without a server.
MLflow. A September 22, 2026 post on dvc.org shows AWS solutions architects using DVC for data versioning together with SageMaker AI MLflow Apps for experiment tracking and lineage.
Alternatives to DVC
The reviewed substitutes for DVC among the experiment tracking, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- MLflow
- Choose it when experiment tracking and model lifecycle operations are more important than DVC's Git-oriented approach to versioning datasets, models, and pipelines.Applies to: Tracking experiments and reproducing a model training run.
- Kedro
- Choose Kedro if your primary challenge is structuring messy data science code into reproducible, maintainable pipelines rather than just tracking experiments.Applies to: where the problem is structuring pipeline code rather than versioning data and tracking experiments.
- Weights & Biases
- Choose Weights & Biases if your team prioritizes rich visualization, collaborative experiment analysis, and you prefer a managed SaaS over self-hosted tooling.Applies to: Recording metrics and artifacts across training runs.
- Comet ML
- Choose Comet ML if you need a lightweight, low-friction experiment tracker with strong production monitoring capabilities and prefer a SaaS-first approach at a lower price point than Weights & Biases.Applies to: Tracing a model version back to the data and code that produced it.