Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Seldon states |
|---|---|
Deployment | Runs in Kubernetes, on-premise, hybrid or multi-cloud. Seldon says it is tested on AWS EKS, Azure AKS, Google GKE, Alicloud, Digital Ocean and OpenShift. |
License | Core 2 is distributed under the Business Source License, and contributions are licensed under it too. For commercial use, the repository asks you to contact Seldon through its website. |
Inference interfaces | REST and gRPC for every model type; MLServer is compatible with the Open Inference Protocol. |
How you deploy | One Kubernetes manifest; models and pipelines are declared as Model and Pipeline resources. Seldon says inference server selection, scaling, monitoring and audit logging are built in. |
Community help | A Slack community for updates and answers to questions. |
Our take
Seldon Core 2 fits platform teams that already run Kubernetes and need to serve many models, or chain them into streaming pipelines, on infrastructure they control. If you want a model endpoint without operating a cluster, or you need a permissive open-source license, confirm both points before you commit.
Evaluate Seldon
Comparisons
Where it stands out
Many models on less hardware. Multi-model serving puts several models on shared inference servers, and overcommit lets you deploy more models than available memory allows. Seldon says LRU memory swapping makes this work, which matters when many models get little traffic.
Composable pipelines. You can connect models, processing steps, custom logic and monitoring components into real-time pipelines that use Kafka to stream data between components.
Experiments in production. Core 2 routes data between candidate models or pipelines for A/B tests and shadow deployments; Seldon's site also lists canary deployments and multi-armed bandits.
Scaling down to zero. Autoscaling works on native or custom logic. Seldon says on-demand workloads can scale to zero while keeping deployment state for reactivation.
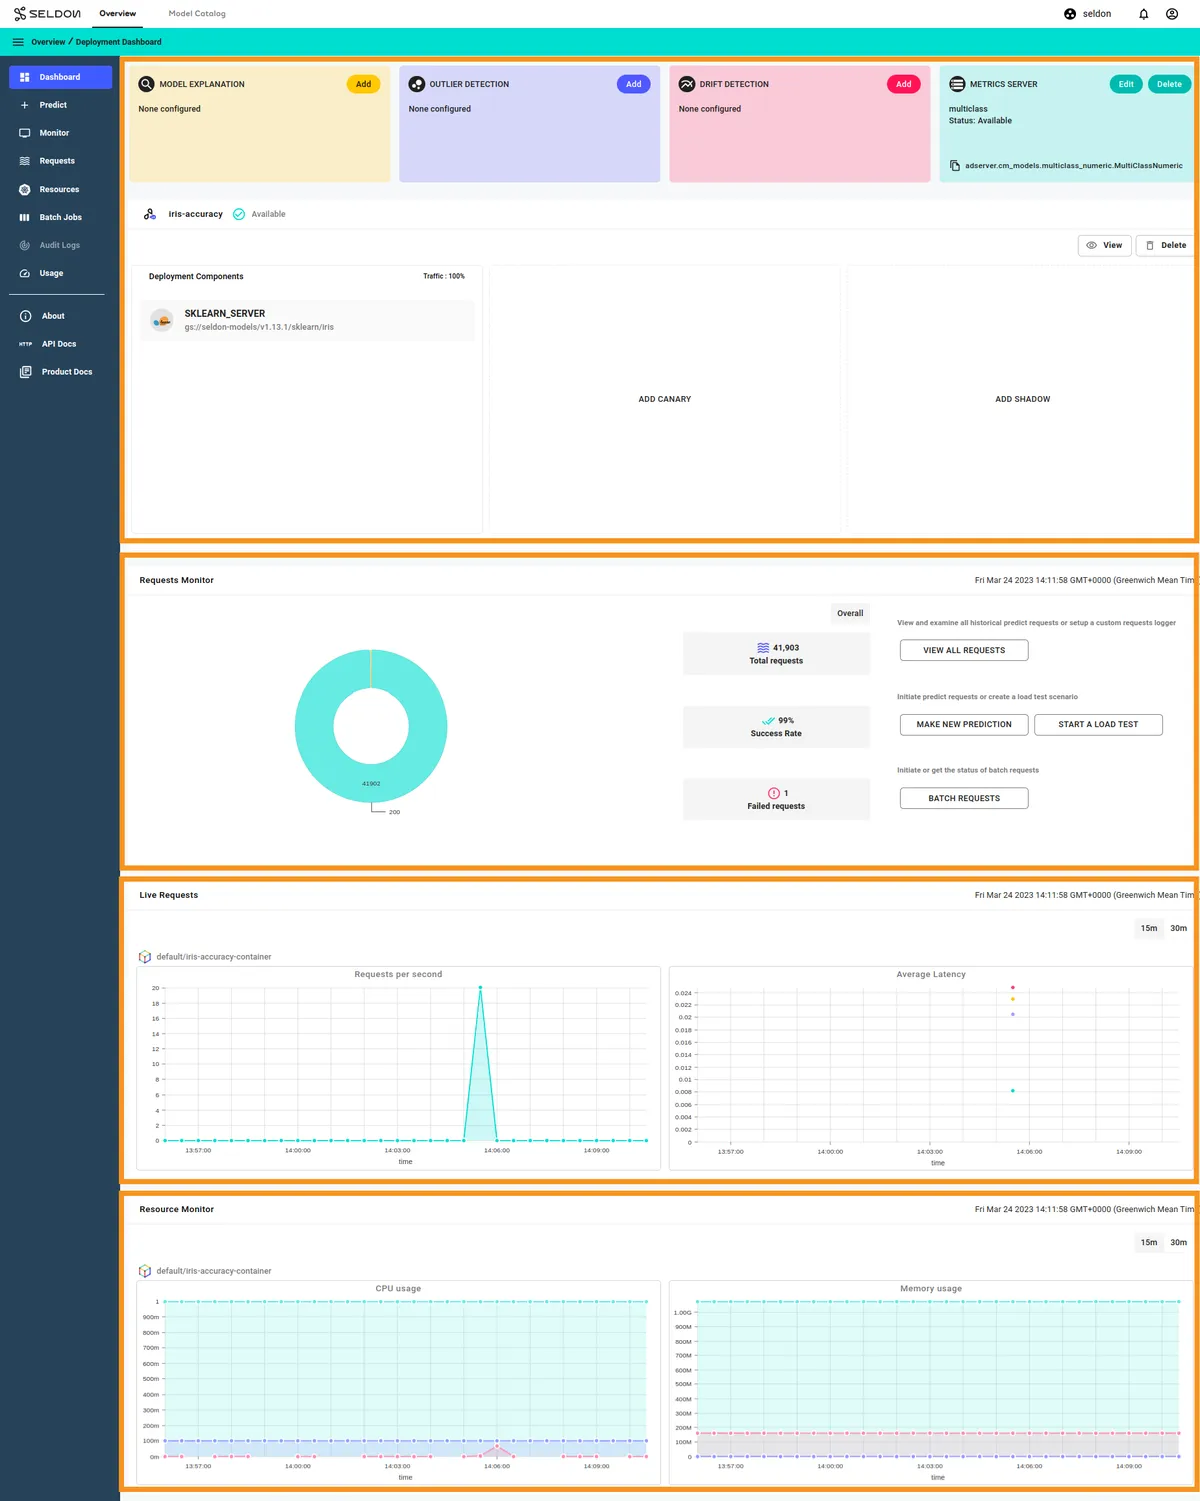
Monitoring and explanation in one ecosystem. Seldon says every prediction is logged and auditable, with monitoring through Prometheus, Grafana and custom dashboards. Alibi adds drift and outlier detection and explanation methods for teams with compliance needs.
Fits an existing stack. Listed integrations include Kafka, Jaeger, Elasticsearch, Triton Inference, MLflow, Weights & Biases, Istio, Envoy, ArgoCD, Flux, Hugging Face, LangSmith and Databricks.
Product screenshot

Trade-offs to weigh
You operate the platform. Models and pipelines are Kubernetes resources, so your team needs a cluster and the skills to run Seldon's components on it.
"Open source" needs a license check. Seldon's website labels Core 2 open source, but the repository distributes it under the Business Source License. Have legal read the LICENSE file before production use.
Ownership and roadmap are changing. Seldon's site points existing enterprise customers to a combined TrueFoundry + Seldon roadmap. Ask how that affects the modules you plan to buy.
Core 1 users face a migration. Seldon labels the original Seldon Core (Core 1) as legacy, so teams still on it should plan a move to Core 2.
Pricing and plan conditions
Seldon describes its pricing as modular, "from open-source to enterprise", so you pay only for the modules you need; its Core 2 docs promise "predictable, fixed pricing".
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Product | How Seldon labels it | What it adds |
|---|---|---|
Seldon Core 2 | Open Source (Business Source License) | The Kubernetes-native MLOps and LLMOps framework: the core deployment engine |
MLServer | Open Source | Multi-framework inference server with REST/gRPC and the Open Inference Protocol |
Alibi Detect and Alibi Explain | Open Source | Outlier, adversarial and drift detection; local, global, black-box and white-box explanation methods |
LLM Module | Module | GenAI deployment with prompt orchestration, observability and guardrails |
MPM Module | Module | Model performance metrics for classification and regression models in production |
Enterprise Platform | Enterprise | Oversight, governance, enhanced authentication and audit for ML and LLM at scale |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
0 GitHub commits 90d4.8k GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
Three-month score against stable baseline terms—not search volume or adoption.
PyPI · seldon-core@1.19.0
Alternatives to Seldon
The reviewed substitutes for Seldon among the model serving, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- BentoML
- BentoML and Seldon both put trained models into production as scalable inference services. BentoML is an open-source framework for packaging models into AI applications that can be deployed anywhere, with BentoCloud as a managed option, while Seldon centers on Kubernetes-native serving with traffic routing, A/B tests, drift detection and explainability.Applies to: Choosing between two products of the same kind for one job.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Kubeflow
- The two sit at different layers of one system and the documented deployments run them together, so the reader's question is which job each one does rather than which to buy.Applies to: Whether these two do the same job, or different jobs in one pipeline.