Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What LanceDB states |
|---|---|
License | Apache-2.0 for the lancedb/lancedb repository. |
Search types | Vector similarity search, full-text search and SQL. The website also describes hybrid search combined with SQL filters against one table. |
Data you can store | Vectors, metadata and multimodal data (text, images, videos, point clouds, and more), which you can store, query and filter. |
APIs and SDKs | Python, Typescript and Rust SDKs, plus a REST API. |
Integrations | LangChain, LlamaIndex, Apache-Arrow, Pandas, Polars and DuckDB, with more on the way. |
Catalogs | Lance Namespace with the latest Lance Spark connector manages Lance tables in Hive, Glue, Unity Catalog, or any catalog service. |
Our take
If you want search inside your own application, with versioned multimodal tables and an Apache-2.0 license, LanceDB is a strong default to try first. If you would rather run a separate search service, or you are buying for the large-scale features, confirm the edition with LanceDB and test it against an alternative before you commit.
Evaluate LanceDB
Comparisons
Where it stands out
Runs inside your application. LanceDB is an embedded library, so there is no separate search server to run for local work. LanceDB says agents such as OpenClaw need a local-first memory layer and that it fits that role with filesystem-native storage, and Continue uses the embedded TypeScript library for semantic code search that works offline.
Versioning without extra tools. LanceDB offers zero-copy, automatic versioning, so you can manage versions of your data without extra infrastructure. That helps when you need to reproduce an experiment or undo a bad load.
Add data without rewriting it. Runway's Head of Engineering, quoted by LanceDB, says Lance let them append columns without rewriting entire datasets, together with fast random access and multimodal support. This matters when you keep adding embeddings or features to a large table.
GPU index building. LanceDB supports GPUs for building vector indexes, and its blog shows index training with CUDA or Apple Silicon (MPS).
Product screenshot

Trade-offs to weigh
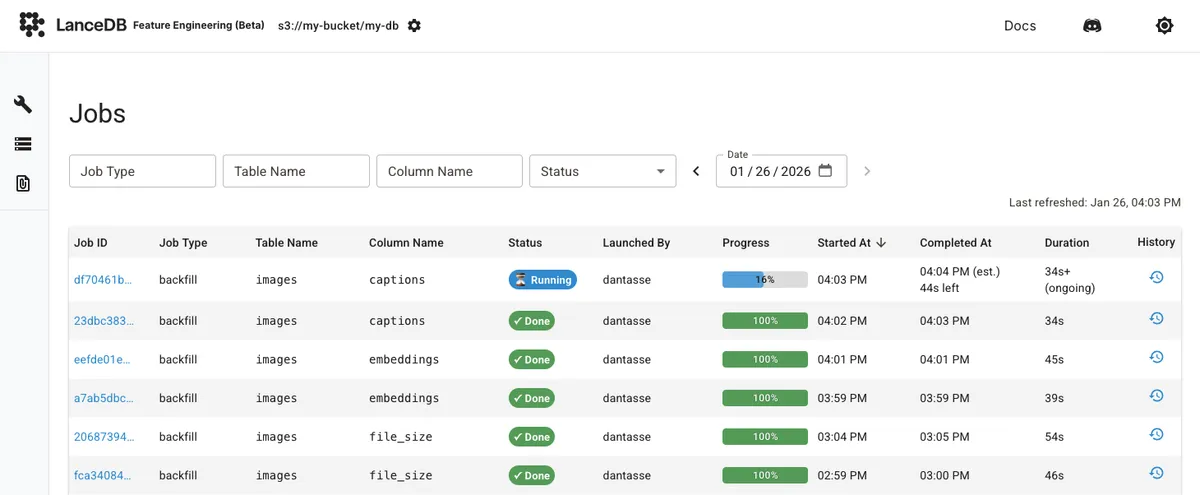
Some features belong to Enterprise. LanceDB calls its feature engineering platform an Enterprise feature. Its blog also describes distributed indexing and query execution that scale search to 10B vectors and beyond; ask which edition includes this before you plan around it.
Headline figures are the vendor's. LanceDB claims up to 70% Model FLOPS Utilization, 100K+ queries per second and 100B+ rows in a single table. Treat these as vendor claims and test with your own data.
Pricing and plan conditions
The billing line falls between the two offerings below. The library is Apache-2.0 licensed, so it has no license fee and your cost is the compute and storage you provide. For Cloud and Enterprise, ask LanceDB for its terms.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Offering | What LanceDB states |
|---|---|
Open Source & Local | 100% open source; runs locally or in your cloud, with no vendor lock-in. |
Cloud and Enterprise | Production-scale vector search with no servers to manage; complete data sovereignty and security. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
707 GitHub commits 90d11.9k GitHub stars0 vulnerabilities across 2 packages
See all signals from 7 sources
npm · @lancedb/lancedb@0.41.0 · PyPI · lancedb@0.41.0
Alternatives
OpenSearch. LanceDB frames this choice as a full search service versus an in-process library. Its own benchmark compares the two on COCO 2017 images embedded with SigLIP, covering ingestion throughput, query cost, storage layout and infra cost. Because the vendor ran it, repeat the test on your workload.
Apache Iceberg and Delta Lake. LanceDB benchmarked Lance against both on S3 metadata performance. Its article on Iceberg and Lance places them in the same lakehouse stack, with designs that bridge analytics and AI/ML workloads on one data foundation, so you may use both rather than pick one.
Alternatives to LanceDB
The reviewed substitutes for LanceDB among the vector databases, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Milvus
- Milvus and LanceDB are open-source vector databases for search over embeddings in AI applications. Milvus is a distributed, cloud-native database with stateless components that scales storage and compute separately, while LanceDB keeps multimodal data with native versioning in the Lance columnar format on disk or object storage.Applies to: Choosing a vector store for embedding search in a retrieval or agent application.
- pgvector
- pgvector and LanceDB are open-source ways to store embeddings and run vector similarity search for RAG and AI search. pgvector is a PostgreSQL extension, so vectors are queried with SQL next to existing tables, while LanceDB is a multimodal vector database that keeps versioned data in its own columnar format on disk or object storage.Applies to: Choosing between these two for the vector databases decision.
- Pinecone
- Pinecone and LanceDB store embeddings and run fast similarity search for RAG, agents and search engines. Pinecone is a closed-source managed service delivered as an API call, while LanceDB is an open-source multimodal database with native versioning that keeps data on local disk or cloud object storage.Applies to: Choosing between two products of the same kind for one job.
- Weaviate
- Weaviate and LanceDB are open-source databases for storing and searching embeddings in AI applications. Weaviate runs as a server or managed cloud with hybrid keyword and vector search, while LanceDB stores multimodal data with versioning in the Lance format on disk or object storage.Applies to: Choosing between these two for the vector databases decision.
- Qdrant
- Qdrant and LanceDB are open-source vector databases for RAG, agents and semantic search. Qdrant runs as a Rust search service with detailed payload filtering and a managed cloud, while LanceDB keeps multimodal data in a versioned columnar format on disk or object storage.Applies to: Choosing between these two for the vector databases decision.
Head to head
See detailed alternatives analysis
If you are evaluating LanceDB alternatives, you have landed in the right place. LanceDB is an open-source multimodal vector database designed for AI workloads at scale, combining persistent storage with native versioning and S3-compatible object storage. It serves as both a vector database and an AI data lakehouse, supporting everything from embedding search to model training pipelines. However, depending on your team's infrastructure requirements, operational preferences, or specific use cases, a different vector database may be the better fit.
We have researched and compared the leading alternatives to help you make an informed decision based on architecture, pricing, and real-world suitability.
Top Alternatives Overview
The vector database landscape offers several strong alternatives to LanceDB, each with distinct strengths:
Pinecone is a fully managed, purpose-built vector database focused on delivering high-performance similarity search at production scale. It abstracts away all infrastructure management, making it ideal for teams that want to ship fast without worrying about cluster operations. Pinecone supports metadata filtering and namespaces for organizing large-scale datasets.
Milvus is an open-source, cloud-native vector database built for GenAI applications. Its architecture separates storage and computation, providing strong horizontal scalability. Milvus supports multiple deployment modes from a lightweight pip-installable version to a fully distributed enterprise setup. Zilliz Cloud offers a managed Milvus service for teams preferring a hosted solution.
Qdrant is an open-source vector search engine written in Rust, emphasizing performance and reliability. It provides a convenient API for vector similarity search with advanced filtering capabilities. Qdrant offers both self-hosted and cloud deployment options, including a hybrid cloud model for enterprises with strict data residency requirements.
pgvector is an open-source PostgreSQL extension that brings vector similarity search directly into your existing Postgres infrastructure. It supports HNSW and IVFFlat indexing, multiple distance metrics, and integrates seamlessly with standard SQL workflows. For teams already running PostgreSQL, pgvector eliminates the need for a separate vector database entirely.
Weaviate is an open-source vector database with built-in vectorization modules, hybrid search combining keyword and vector approaches, and a GraphQL API. It positions itself as an AI-native database with a focus on reducing hallucinations and vendor lock-in in AI applications.
Vespa is an open-source AI search platform designed for large-scale RAG, personalization, and recommendation workloads. It provides native tensor support for complex ranking and real-time inference, making it well-suited for applications requiring sophisticated ML-driven decisioning beyond simple similarity search.
Architecture and Approach Comparison
LanceDB distinguishes itself through its lakehouse architecture built on the Lance columnar format. This enables zero-copy data versioning at petabyte scale, fast random access for both vectors and large blobs like images and video, and integrated feature engineering pipelines with native LLM-as-UDF support. LanceDB runs in-process, meaning it can be embedded directly into your application without a separate server process.
Pinecone takes the opposite approach as a fully managed cloud service. You interact exclusively through APIs, with no infrastructure to provision or manage. This makes it the simplest option operationally but offers less flexibility for custom deployments or offline use cases.
Milvus and its managed counterpart Zilliz Cloud use a disaggregated architecture where all components are stateless, enabling elastic scaling. This makes Milvus particularly strong for workloads with unpredictable query volumes that need to scale horizontally across tens of billions of vectors.
pgvector leverages the proven PostgreSQL ecosystem, giving you ACID compliance, point-in-time recovery, JOINs, and the full SQL feature set alongside vector search. The trade-off is that pgvector performs best for datasets up to roughly 50 million vectors; beyond that, purpose-built vector databases typically offer better performance.
Qdrant's Rust-based implementation prioritizes raw search performance and memory efficiency. Its payload filtering system allows complex queries that combine vector similarity with structured data conditions, useful for recommendation and e-commerce applications.
Weaviate provides built-in vectorization, meaning you can send raw text or images and have the database generate embeddings automatically. This reduces pipeline complexity but introduces tighter coupling between your database and specific ML models.
Vespa stands apart by combining vector search with advanced ML ranking and real-time inference in a single platform, making it the strongest choice for teams building complex retrieval-and-ranking pipelines rather than simple nearest-neighbor search.
Pricing Comparison
LanceDB is open-source and free for self-hosted deployments. For managed cloud services, LanceDB provides pricing on request through their sales team.
pgvector is entirely free as a PostgreSQL extension. Your costs are limited to whatever you spend on PostgreSQL hosting, whether that is self-managed servers or a managed Postgres provider.
Milvus is open-source for self-hosted use. Zilliz Cloud, the managed Milvus service, offers a free tier along with paid plans; the Enterprise tier starts at $197/mo on Dedicated clusters.
Pinecone offers a free tier for getting started. Paid plans are usage-based, with pricing starting at $0.15 per hour for dedicated compute resources.
Weaviate Cloud has a free plan at $0/month. The Flex plan starts at $45/mo, with Premium from $400/mo. Self-hosted open-source deployment is available at no cost. Flex usage rates start from $0.00465 per 1M vector dimensions.
Qdrant offers a free tier on their cloud platform. Self-hosted deployment is free and open-source.
Turbopuffer uses a serverless model built on object storage. Their Launch plan starts at $16/month and the Scale plan at $256/month, with enterprise pricing available on request.
Typesense is open-source for self-hosting. Typesense Cloud's smallest managed cluster costs $0.03 per hour, about $21.60 per month, and the first 720 hours are free.
Vespa's Community Edition is free for self-hosted use, with cloud pricing available through their cloud platform.
Marqo offers enterprise-level pricing through their sales team. Contact Marqo directly for current rates.
When to Consider Switching
We recommend evaluating alternatives to LanceDB in the following scenarios:
You need a fully managed service with zero operational burden. LanceDB's core strength is its open-source, embeddable architecture. If your team lacks the capacity to manage infrastructure and you want a turnkey solution, Pinecone or Zilliz Cloud may be a better fit.
Your workload is pure vector search on structured data. If you do not need LanceDB's multimodal lakehouse features like training pipeline integration, feature engineering, or large blob storage, a lighter-weight solution like Qdrant or pgvector could simplify your stack.
You are already invested in PostgreSQL. If your team runs PostgreSQL and your vector dataset stays within tens of millions of rows, pgvector keeps everything in one database, reducing operational complexity and eliminating data synchronization challenges.
You need built-in vectorization. If generating and managing embeddings outside your database adds unwanted complexity, Weaviate's built-in vectorization modules can streamline your pipeline.
You require advanced ML ranking beyond similarity search. For applications needing real-time learned ranking, personalization, and complex tensor operations, Vespa offers a more comprehensive ML serving platform.
Migration Considerations
Migrating from LanceDB requires planning around several dimensions. First, consider your data format: LanceDB uses the Lance columnar format, which is optimized for multimodal data. Moving to another database means converting your data, and any Lance-specific features like zero-copy versioning will not carry over directly.
For teams using LanceDB's in-process mode, switching to a client-server architecture like Pinecone, Milvus, or Qdrant introduces network latency and requires changes to your application code. Plan for API refactoring and performance testing.
If you rely on LanceDB's integrated feature engineering or training pipeline features, you will need to replace those workflows with external tools or custom pipelines. Most other vector databases focus on search and retrieval rather than end-to-end data processing.
Embedding compatibility is generally straightforward since vector databases are largely format-agnostic for standard float vectors. However, verify that your target database supports your specific vector dimensions and distance metrics.
We suggest running a parallel evaluation period where you test your actual query patterns and data volumes against the target database before committing to a full migration. This helps uncover performance differences that benchmarks alone may not reveal.