Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Chroma states |
|---|---|
License | Apache 2.0. |
Ways to run it | Single node with pip, npm or Docker, in memory or with persistent storage; client-server mode with chroma run; Chroma Cloud, fully managed and serverless; or managed single-tenant clusters for Enterprise. Chroma states in an October 2026 update that it no longer offers BYOC deployments. |
Clients and releases | Python and JavaScript/TypeScript clients (JavaScript client v3 is a rewrite with a smaller bundle) and a CLI. New pypi and npm versions ship on Mondays; hotfixes at any time. |
Security | Chroma's site states SOC 2 Type II, and the pricing page lists SOC II under Team. Updates add AWS PrivateLink and customer-managed encryption keys; confirm which plans include them. |
Self-hosted help | Community help on Discord and open-source deployment guides for your own infrastructure. Cloud support levels are listed under Pricing. |
Our take
Choose ChromaDB when you want to build retrieval on a laptop and keep the same Apache 2.0 engine as the app moves to Chroma Cloud. Self-host if you would rather run the servers yourself; choose Chroma Cloud if you would rather pay for usage than operate the database.
Evaluate ChromaDB
Popular comparisons
Where it stands out
Same engine from prototype to production. The README starts with an in-memory client and adds persistence when you need it. Chroma handles tokenization, embedding and indexing as you add documents, or takes your own embeddings. One codebase powers both open source and Chroma Cloud; Chroma says this means no vendor lock-in and easy data export.
Several search methods in one query. Dense vectors, sparse vectors (BM25, SPLADE), full-text (trigram and regex) and metadata filters with facets share one query interface for hybrid search. GroupBy aggregates results by metadata key, and metadata can hold arrays.
Built on object storage. All vectors, metadata and indexes live in S3 or GCS, with memory and SSD caches for hot and warm data and automatic query-aware tiering. Chroma's argument is that vectors are large, with 1GB of text becoming 15GB of vectors, and that memory is expensive while object storage is not.
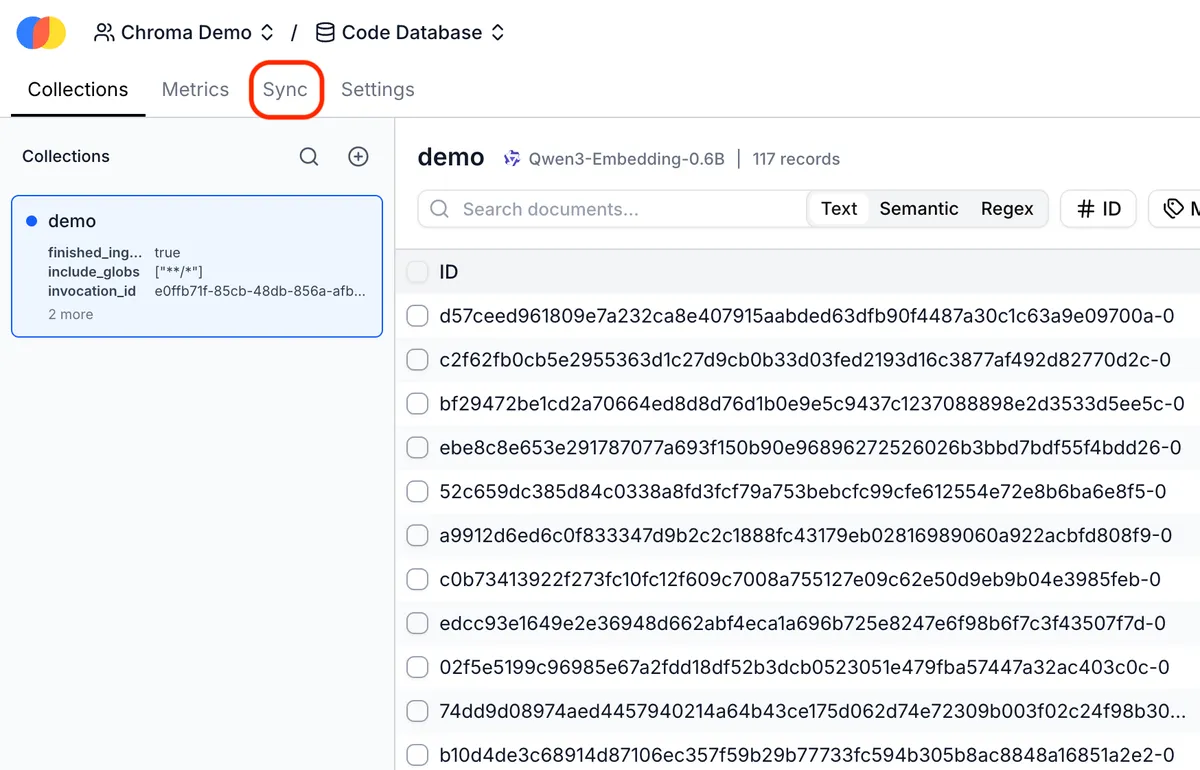
Tools for iterating on retrieval. Collection forking makes copy-on-write copies for dataset versioning, A/B tests and roll-outs. Chroma Sync indexes GitHub repositories, Web Sync crawls and embeds web pages, and Chroma Cloud Sync adds serverless ingestion for Chroma Cloud. Indexing status shows progress, and read level chooses index-only or full reads.
Product screenshot
Trade-offs to weigh
Cold queries can take more than a second. Chroma's figures at 384 dimensions and 100k vectors show p50 latency of 20ms warm and 650ms cold, and p99 of 57ms warm and 1.5s cold. Test latency-sensitive features with realistic access patterns; Chroma offers a proof of concept for specific workloads.
Per-collection ceilings. The technical specs list 90-100% recall, but also 5M records, 10 concurrent reads (200+ QPS) and 30 MB/s of writes (2000+ QPS) per collection, and 1M collections per database. Bigger datasets need a plan to split data across collections, or a talk about dedicated clusters, which Chroma says scale to your requirements.
Usage limits pause Chroma Cloud. When a limit you set, or one Chroma sets, is reached, Chroma pauses the service until the limit is changed. Leave headroom for traffic peaks.
Pricing and plan conditions
The plans below cover Chroma Cloud; the open-source database runs on your own infrastructure. Starter and Team add usage charges to their monthly price for data written, data stored per month, data queried and data returned over the network, after their credits are used; Enterprise pricing is custom. Credits usually do not expire, but Team's $100 of included usage does not roll over. Starter and Team are paid by credit card, Enterprise has configurable billing, and plan changes are pro-rated to the calendar month.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What the plan lists |
|---|---|---|
Starter | $0 / month + usage; $5 in free credits | 10 databases; 10 team members; Community Slack |
Team | $250 / month + usage; $100 credits | 100 databases; 30 team members; Slack support; SOC II; volume-based discounts |
Enterprise | Custom pricing | Unlimited databases and team members; dedicated support; single-tenant clusters; SLAs, which Chroma's site describes as customized for 24/7 assistance |
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Usage meter | Published rate (shown with Starter) |
|---|---|
Write | $2.50 per GiB written |
Storage | $0.33 per GiB per month |
Query | $0.0075 per TiB queried |
Network | $0.09 per GiB returned |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
85 GitHub commits 90d29.7k GitHub stars8 vulnerabilities across 2 packages
See all signals from 9 sources
npm · chromadb@3.5.0 · PyPI · chromadb@1.5.9
Alternatives to ChromaDB
The reviewed substitutes for ChromaDB among the vector databases, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Pinecone
- Choose this if you want zero-ops production vector search and your budget supports a managed service starting at $50/month.Applies to: Choosing a vector store for embedding search in a retrieval or agent application.
- Weaviate
- Choose this if you need hybrid search combining semantic and keyword retrieval with enterprise-grade deployment options.Applies to: Choosing a vector store for embedding search in a retrieval or agent application.
- Milvus
- Choose this if you need to search across billions of vectors with distributed infrastructure and are comfortable with Kubernetes operations.Applies to: Choosing a vector store for embedding search in a retrieval or agent application.
- pgvector
- Choose this if you already run PostgreSQL and want to add vector search without introducing a new database into your stack.Applies to: Choosing between these two for the vector databases decision.
- LanceDB
- Choose this if you need an embedded, serverless vector database for multimodal AI workloads or want built-in dataset versioning.Applies to: Choosing between these two for the vector databases decision.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Marqo
- Marqo optimises search conversion using click-stream, purchase and event data, creating a personalised experience that knows what your customers are looking for - better than they do.Applies to: For teams that build their own product search on a vector store rather than buying a hosted ecommerce search platform.
- Aerospike
- Multi-model database with vector search capabilities — real-time key-value, document, and vector operations at massive scale with predictable low latency.Applies to: LLM and RAG prototyping workloads centered on embeddings
See detailed alternatives analysis
ChromaDB has earned its reputation as the go-to embedding database for developers prototyping RAG applications with LangChain and LlamaIndex. With over 5 million monthly downloads and 24,000+ GitHub stars, it is the most accessible entry point into vector search. But as teams move from prototype to production, they often discover that ChromaDB alternatives offer capabilities better suited to their scale, infrastructure requirements, or budget. We evaluated the leading vector databases to help you find the right fit.
Top Alternatives Overview
Pinecone is the fully managed vector database built for production scale. It delivers p50 query latency of 16ms on dense indexes with 10 million records and supports up to 600 QPS across 135 million vectors on Dedicated Read Nodes. Pinecone handles infrastructure, scaling, and indexing automatically, which eliminates operational overhead entirely. The tradeoff is vendor lock-in: there is no open-source version and no self-hosting option. Choose this if you want zero-ops production vector search and your budget supports a managed service starting at $50/month.
Weaviate is an open-source vector database that combines vector, keyword (BM25), and hybrid search in a single platform. Its built-in vectorizer modules connect directly to 20+ ML models, so you can generate embeddings without an external pipeline. Weaviate scales to billions of objects with native multi-tenancy, RBAC, and vector index compression for memory efficiency. The managed cloud starts at $45/month on the Flex plan with a 99.5% uptime SLA. Choose this if you need hybrid search combining semantic and keyword retrieval with enterprise-grade deployment options.
Milvus is the open-source vector database engineered for billion-scale workloads. Its fully distributed architecture separates storage and computation, allowing independent scaling of query nodes and data nodes. Milvus supports multiple index types including IVF, HNSW, and DiskANN for optimizing the speed-accuracy tradeoff at different scales. The managed cloud option (Zilliz Cloud) handles operations, while self-hosted Milvus runs on Kubernetes. Choose this if you need to search across billions of vectors with distributed infrastructure and are comfortable with Kubernetes operations.
pgvector is a PostgreSQL extension that adds vector similarity search directly to your existing Postgres database. It supports both exact and approximate nearest neighbor search using IVFFlat and HNSW indexes, and it works with standard SQL queries and existing PostgreSQL tooling. There is no additional service to manage, no new API to learn, and no separate infrastructure to maintain. The latest release (0.8.2, February 2026) continues to improve performance and index support. Choose this if you already run PostgreSQL and want to add vector search without introducing a new database into your stack.
Qdrant is a vector search engine written in Rust that emphasizes performance and advanced filtering. It supports payload-based filtering alongside vector search, enabling complex queries that combine semantic similarity with structured metadata constraints. Qdrant offers a free tier on its managed cloud, self-hosted deployment, and hybrid cloud options. The Rust implementation delivers strong memory efficiency and query throughput. Choose this if you need advanced filtering capabilities combined with vector search and value a Rust-based performance profile.
LanceDB is a multimodal vector database built on the Lance columnar format with native versioning and S3-compatible object storage. It operates as an embedded database (similar to SQLite), meaning it runs in-process without a separate server. This serverless architecture makes it exceptionally lightweight for development and edge deployments. LanceDB supports multimodal data including text, images, and video embeddings natively. Choose this if you need an embedded, serverless vector database for multimodal AI workloads or want built-in dataset versioning.
Architecture and Approach Comparison
ChromaDB runs as a lightweight, single-node database with in-memory or persistent storage. Its architecture uses HNSW indexing and stores data locally, making it fast for development but limited for large-scale production. ChromaDB Cloud adds a serverless layer built on object storage with automatic data tiering (memory cache, SSD cache, S3/GCS cold storage), delivering p50 latency of 20ms at 100k vectors with 384 dimensions.
Pinecone takes a fundamentally different approach with a fully proprietary, serverless architecture backed by distributed object storage. Vectors are cached across tiered storage for optimal speed and cost. Its dense indexes achieve p50 of 16ms and p99 of 33ms at 10 million records. Pinecone also offers sparse indexes for BM25-style keyword search at p50 of 8ms.
Weaviate uses a modular architecture with pluggable vectorizer modules and a custom HNSW implementation. It supports rotational quantization (RQ-8) for 4x memory reduction while maintaining search accuracy. Weaviate's hybrid search fuses BM25 rankings with vector similarity scores using a configurable alpha parameter, giving fine-grained control over the keyword-to-semantic balance.
Milvus separates storage and computation with a cloud-native, microservices-based architecture. Query nodes, data nodes, and index nodes scale independently. This makes Milvus the strongest choice for billion-scale deployments where you need elastic scaling across multiple index types.
pgvector takes the most conservative approach: it extends PostgreSQL with vector data types and operators. Vectors live alongside your relational data in the same database, accessed through standard SQL. This eliminates the need for a separate vector database but means performance is bounded by PostgreSQL's single-node architecture.
LanceDB uses the Lance columnar format optimized for ML workloads. Running in-process (embedded mode) eliminates network overhead for queries. Its copy-on-write versioning enables dataset branching and time travel, which is valuable for ML experiment tracking.
Pricing Comparison
The vector database market spans from completely free open-source options to managed services costing hundreds per month. Here is how the main options compare.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Pricing Model | Free Tier | Starting Price | Self-Hosted Option |
|---|---|---|---|---|
| ChromaDB | Usage-based | Yes (free credits) | $0/mo (cloud free tier) | Yes (Apache 2.0) |
| Pinecone | Usage-based | 2 GB storage | $50/mo (Standard) | No |
| Weaviate | Usage-based | 14-day sandbox | $45/mo (Flex) | Yes (open source) |
| Milvus | Enterprise | Community edition | Contact sales (Zilliz Cloud) | Yes (open source) |
| pgvector | Open Source | Unlimited | $0 (extension) | Yes (PostgreSQL extension) |
| Qdrant | Freemium | Free tier available | Free cloud tier | Yes (open source) |
| LanceDB | Open Source | Unlimited | $0 (embedded) | Yes (open source) |
| FAISS | Open Source | Unlimited | $0 (library) | Yes (MIT license) |
Pinecone's Standard plan starts at $50/month with a 3-week trial including $300 in credits, while its Enterprise plan requires a $500/month minimum with a 99.95% uptime SLA. Weaviate's Flex plan starts at $45/month with pay-as-you-go billing on top of the minimum, and the Premium plan jumps to $400/month for dedicated infrastructure. ChromaDB Cloud offers free credits to start with usage-based pricing scaling from there. For teams with PostgreSQL already in their stack, pgvector adds vector search at zero incremental licensing cost.
When to Consider Switching
We recommend evaluating ChromaDB alternatives in these scenarios. First, if your dataset has grown beyond 5 million records per collection (ChromaDB Cloud's documented limit) or you need sub-10ms latency at scale, Pinecone or Milvus will serve you better. Second, if you need hybrid search combining keyword and semantic retrieval, Weaviate's built-in BM25 + vector fusion or ChromaDB's newer sparse vector support (added October 2025) should be compared head-to-head for your use case.
Third, if you already operate PostgreSQL in production and want to avoid managing a separate database, pgvector eliminates an entire service from your infrastructure. Fourth, if your workload requires billion-scale search with distributed computation, Milvus provides the most mature distributed architecture. Fifth, if you need an embedded database for edge or mobile deployments, LanceDB runs in-process without a server.
Finally, if your primary concern is raw similarity search performance on a single machine and you do not need persistence or a database API, FAISS (Meta's similarity search library) provides the fastest CPU and GPU implementations available, though it is a library rather than a database.
Migration Considerations
Migrating from ChromaDB involves exporting your embeddings, metadata, and document references, then re-ingesting them into your target system. Since ChromaDB stores vectors as arrays and metadata as JSON, the data format is portable to any vector database.
To Pinecone: The API patterns are similar (upsert vectors with IDs and metadata, query by vector). The main change is moving from ChromaDB's collection model to Pinecone's index + namespace model. Pinecone requires pre-computed embeddings, so if you relied on ChromaDB's built-in embedding generation, you will need to add an embedding step. Plan 1-2 weeks for a small application.
To Weaviate: Weaviate uses a schema-based approach where you define classes with properties, unlike ChromaDB's schemaless collections. You will need to define your data schema before importing. Weaviate's vectorizer modules can replace ChromaDB's built-in embedding, so the migration may simplify your pipeline. Plan 2-3 weeks, accounting for schema design and hybrid search tuning.
To pgvector: This is the most architecturally different migration. You will create PostgreSQL tables with vector columns, insert your embeddings as row data, and build HNSW or IVFFlat indexes. Queries become SQL statements with vector operators. If your team knows SQL, the learning curve is minimal. Plan 1-2 weeks for small datasets, longer for schema design on complex applications.
To Milvus: Milvus supports batch insertion via its Python SDK with a similar collection-based model. You will need to choose an appropriate index type (HNSW for low-latency, IVF_FLAT for balanced, DiskANN for large on-disk datasets). Plan 2-4 weeks, including index tuning and Kubernetes setup for self-hosted deployments.
To LanceDB: LanceDB uses a table-based model with the Lance format. Migration involves writing your vectors and metadata into Lance tables, which can be done with the Python SDK in a few lines. The embedded architecture means no server setup. Plan under 1 week for straightforward migrations.