Decision comparison
Databricks vs Trino
Databricks delivers a complete lakehouse platform with integrated ML, governance, and collaborative notebooks, while Trino provides a fast, open-source SQL federation engine that queries 50+ data sources without moving data. Choose Databricks for end-to-end data engineering and AI; choose Trino for cross-source SQL analytics when deployment control justifies owning infrastructure and operations.
Architecture choice. These take different approaches to the same problem. Read the table as a fit question rather than a feature race.
These are different kinds of product — Lakehouse Platform and Query Engine.
Quick Comparison
| Decision factor | Databricks | Trino |
|---|---|---|
| Query Engine | Built on managed Apache Spark with Photon engine optimizations for SQL, Python, Scala, and R workloads | Purpose-built distributed SQL engine using coordinator-worker architecture with parallel query execution |
| Data Source Access | Primarily queries Delta Lake tables in cloud object storage (S3, ADLS, GCS) with Spark connectors | Federated queries across 50+ connectors including S3, MySQL, PostgreSQL, MongoDB, Kafka in one query |
| Pricing Model | Databricks is pay as you go with no up-front costs: you pay only for the products you use, at per-second granularity, and committed use contracts give discounts and other benefits for larger usage commitments. Rates start at $0.15 per DBU for Data Engineering, $0.22 per DBU for Data Warehousing, $0.40 per DBU for interactive workloads, $0.07 per DBU for Artificial Intelligence and for Genie beyond free usage, and $0.069 per CU for the Operational Database (managed Postgres). Prices vary by region and cloud provider, and storage, networking and related costs depend on the services you choose and your cloud provider. Azure Databricks is priced and billed by Microsoft. Free Edition is a no-cost offering meant for non-commercial use; a free trial gives access to the full platform, and some trials include credits. Verified 2026-11-02 against https://www.databricks.com/product/pricing and https://docs.databricks.com/aws/en/getting-started/free-edition-limitations. | Trino is free open source software licensed under the Apache License 2.0. The project site lists no paid plans or prices. Verified 2026-10-05 against https://trino.io. |
| ML and AI Capabilities | Integrated MLflow, managed model serving, Mosaic AI services, and collaborative notebooks for data science | No built-in ML tooling; focused exclusively on SQL query execution across distributed data sources |
| Deployment Model | Fully managed SaaS on AWS, Azure, and GCP with serverless options and automatic cluster management | Self-hosted open-source on any infrastructure including on-premise, AWS, Azure, and Google Cloud |
| Governance and Security | Unity Catalog provides unified governance with RBAC, audit logging, data lineage on Premium tier | SQL-standard authentication and authorization; governance depends on underlying data source controls |
Databricks
- Query Engine:
- Built on managed Apache Spark with Photon engine optimizations for SQL, Python, Scala, and R workloads
- Data Source Access:
- Primarily queries Delta Lake tables in cloud object storage (S3, ADLS, GCS) with Spark connectors
- Pricing Model:
- Databricks is pay as you go with no up-front costs: you pay only for the products you use, at per-second granularity, and committed use contracts give discounts and other benefits for larger usage commitments. Rates start at $0.15 per DBU for Data Engineering, $0.22 per DBU for Data Warehousing, $0.40 per DBU for interactive workloads, $0.07 per DBU for Artificial Intelligence and for Genie beyond free usage, and $0.069 per CU for the Operational Database (managed Postgres). Prices vary by region and cloud provider, and storage, networking and related costs depend on the services you choose and your cloud provider. Azure Databricks is priced and billed by Microsoft. Free Edition is a no-cost offering meant for non-commercial use; a free trial gives access to the full platform, and some trials include credits. Verified 2026-11-02 against https://www.databricks.com/product/pricing and https://docs.databricks.com/aws/en/getting-started/free-edition-limitations.
- ML and AI Capabilities:
- Integrated MLflow, managed model serving, Mosaic AI services, and collaborative notebooks for data science
- Deployment Model:
- Fully managed SaaS on AWS, Azure, and GCP with serverless options and automatic cluster management
- Governance and Security:
- Unity Catalog provides unified governance with RBAC, audit logging, data lineage on Premium tier
Trino
- Query Engine:
- Purpose-built distributed SQL engine using coordinator-worker architecture with parallel query execution
- Data Source Access:
- Federated queries across 50+ connectors including S3, MySQL, PostgreSQL, MongoDB, Kafka in one query
- Pricing Model:
- Trino is free open source software licensed under the Apache License 2.0. The project site lists no paid plans or prices. Verified 2026-10-05 against https://trino.io.
- ML and AI Capabilities:
- No built-in ML tooling; focused exclusively on SQL query execution across distributed data sources
- Deployment Model:
- Self-hosted open-source on any infrastructure including on-premise, AWS, Azure, and Google Cloud
- Governance and Security:
- SQL-standard authentication and authorization; governance depends on underlying data source controls
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Databricks | Trino |
|---|---|---|
| GitHub commits, 90d(Ecosystem adoption) | 1.4k | Not available |
| GitHub stars(Ecosystem adoption) | 44,000+ | Not available |
| Search interest(Market interest) | 38 | Unavailable |
| Hacker News mentions, 90d(Community interest) | 54 | 0 |
| npm weekly downloads(Developer adoption) | 738.8k | 157.5k |
| Product Hunt comments(Community interest) | 5 | Not available |
| Product Hunt rating(Community interest) | 5.0/5 | Not available |
| Product Hunt reviews(Community interest) | 6 | Not available |
| Product Hunt votes(Community interest) | 86 | Not available |
| PyPI weekly downloads(Developer adoption) | 20.4M | 3.9M |
| Stack Overflow questions(Community interest) | 8.4k | 893 |
| Docker Hub pulls(Product adoption) | Not available | 29.6M |
| GitHub commits, 90d(Product adoption) | Not available | 1.4k |
| GitHub stars(Product adoption) | Not available | 13,000+ |
As of November 9, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Databricks
November 9, 2026Package vulnerabilities
npm · @databricks/sql@3.0.0 · PyPI · databricks-sdk@0.163.0
0 vulnerabilities
across 2 packages
Repository security score
github.com/apache/spark
5.6/10
Trino
November 9, 2026Package vulnerabilities
PyPI · trino@0.340.0 · npm · trino-client@0.2.9
0 vulnerabilities
across 2 packages
Repository security score
github.com/trinodb/trino
5.6/10
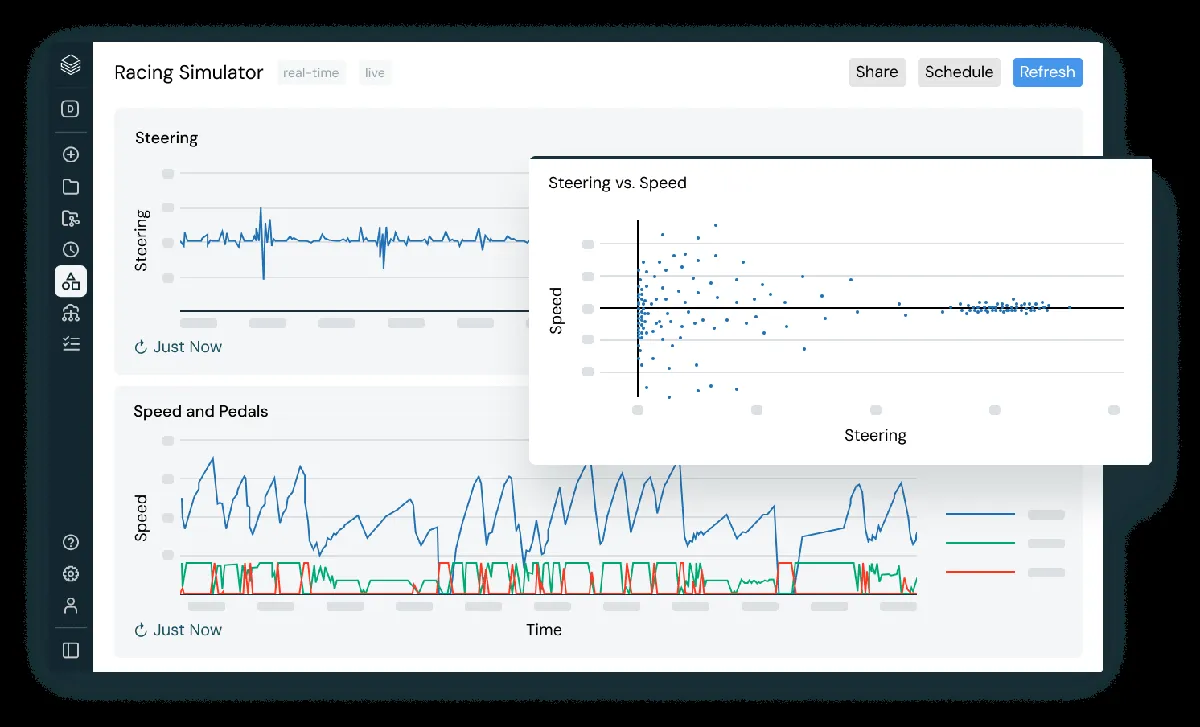
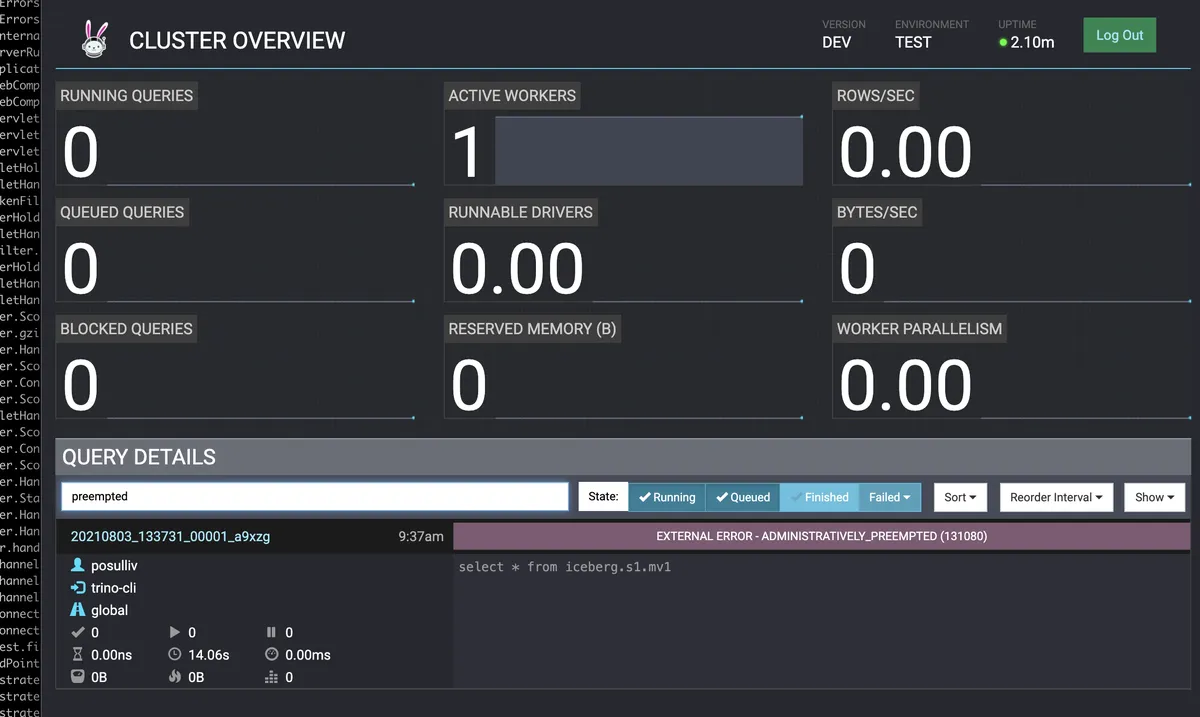
Interface Preview
Databricks
Trino
Feature Comparison
| Feature | Databricks | Trino |
|---|---|---|
| Query Processing | ||
| SQL Execution Engine | Spark SQL with Photon vectorized execution for accelerated query performance | Custom distributed SQL engine with pipelined execution, dynamic scheduling, and in-memory processing |
| Query Federation | Queries primarily target Delta Lake tables; limited cross-source federation through Spark connectors | Native federation across 50+ data sources in a single SQL query joining S3, MySQL, Kafka, and more |
| ANSI SQL Compliance | Supports Spark SQL dialect with ANSI SQL mode available; some syntax differences from standard SQL | Fully ANSI SQL compliant query engine that works natively with Tableau, Power BI, and Superset |
| Data Management | ||
| Storage Format | Delta Lake with ACID transactions, schema evolution, and time travel on Parquet files in cloud storage | Queries data in-place across any format; supports Parquet, ORC, Avro, Iceberg, Delta Lake, and Hive |
| ETL Pipeline Support | Lakeflow pipelines for declarative ETL pipelines with automatic data quality monitoring | Batch ETL processing across disparate systems using standard SQL; speeds up extract-transform-load jobs |
| Data Sharing | Delta Sharing protocol enables open, cross-platform data sharing without proprietary formats or replication | Provides centralized query access to distributed data sources; no built-in data sharing protocol |
| Scalability and Performance | ||
| Scaling Architecture | Managed clusters with autoscaling on cloud VMs; serverless SQL warehouses handle capacity automatically | Horizontal scaling by adding worker nodes; coordinator distributes tasks across all available workers |
| Concurrency Handling | SQL Warehouses support concurrent BI queries with automatic queuing and workload-specific autoscaling | Distributed parallel processing handles concurrent queries; optimized for interactive exabyte-scale analytics |
| Processing Scale | Handles petabyte-scale data engineering, ML training, and SQL analytics across unified lakehouse storage | Processes exabyte-scale data lakes and massive data warehouses; used by Facebook and Amazon at scale |
| Development and Collaboration | ||
| Language Support | Multi-language notebooks and jobs in SQL, Python, Scala, and R with integrated Spark execution | SQL-only query interface; connects to BI tools and applications through JDBC/ODBC drivers |
| Notebook Environment | Collaborative workspace with shared notebooks, Git repos integration, dashboards, and RBAC | No built-in notebook environment; users connect through SQL clients, BI tools, or custom applications |
| Machine Learning | Managed MLflow, experiment tracking, feature store, model serving, and Mosaic AI for generative AI | No native ML capabilities; teams use Trino for data access and pair with separate ML platforms |
| Operations and Deployment | ||
| Deployment Options | Fully managed SaaS on AWS, Azure, and GCP; serverless SQL warehouses eliminate cluster management | Self-hosted open-source on any infrastructure; managed cloud from Starburst and other providers |
| Open Source Status | Proprietary platform built on open-source foundations (Apache Spark, Delta Lake, MLflow) | Fully open-source under Apache-2.0 license with 13,000+ GitHub stars; Trino Software Foundation |
| Connector Ecosystem | Connectors for cloud storage (S3, ADLS, GCS), Delta Lake, and select external databases via Spark | 50+ built-in connectors for S3, Cassandra, MySQL, Hive, PostgreSQL, MongoDB, Kafka, Elasticsearch |
Query Processing
SQL Execution Engine
Query Federation
ANSI SQL Compliance
Data Management
Storage Format
ETL Pipeline Support
Data Sharing
Scalability and Performance
Scaling Architecture
Concurrency Handling
Processing Scale
Development and Collaboration
Language Support
Notebook Environment
Machine Learning
Operations and Deployment
Deployment Options
Open Source Status
Connector Ecosystem
Which approach fits
Databricks delivers a complete lakehouse platform with integrated ML, governance, and collaborative notebooks, while Trino provides a fast, open-source SQL federation engine that queries 50+ data sources without moving data. Choose Databricks for end-to-end data engineering and AI; choose Trino for cross-source SQL analytics when deployment control justifies owning infrastructure and operations.
When each approach fits
Choose Databricks if:
Choose Databricks when your organization needs a unified platform for data engineering, SQL analytics, and machine learning. Databricks excels for teams building end-to-end data pipelines with Lakeflow pipelines, training ML models with managed MLflow and Mosaic AI, and running governed analytics through Unity Catalog. It is the stronger choice for teams that need collaborative notebooks in Python, Scala, and R alongside SQL, and for enterprises requiring built-in RBAC, audit logging, and data lineage. The managed SaaS model eliminates infrastructure management, making it ideal for organizations willing to invest in a premium platform that handles everything from ETL to model serving.
Choose Trino if:
Choose Trino when your primary need is fast, federated SQL queries across multiple data sources without moving or copying data. Trino is the clear winner for teams that want to query S3, MySQL, PostgreSQL, Kafka, Elasticsearch, and dozens of other systems from a single SQL interface. Its open-source Apache-2.0 license and 12,738 GitHub stars make it ideal for organizations that want zero licensing costs and full control over deployment. Trino fits best for data analysts running interactive queries, teams performing cross-source analytics, and organizations with existing infrastructure that need a lightweight, high-performance query layer rather than a full managed platform.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Can Databricks and Trino be used together in the same data stack?
Databricks and Trino serve complementary roles in many data architectures. Organizations use Databricks for data engineering pipelines, Delta Lake storage, and ML model training, while deploying Trino as a federated query layer that provides SQL access across Databricks tables and other data sources simultaneously. Trino can query Delta Lake tables stored in cloud object storage, giving analysts a single SQL interface to access both Databricks-managed data and other databases like MySQL or PostgreSQL. This combination works well when teams need Databricks for heavy processing and governance but want Trino for lightweight, cross-source ad-hoc analytics.
How do the total costs compare between Databricks and Trino for a mid-size team?
Compare the actual workload and deployment model. Databricks uses DBU-based service pricing, with infrastructure treatment depending on the product and deployment. Trino has no engine license fee, but infrastructure, source systems and operating work remain your responsibility. A free engine does not establish savings over Databricks without equivalent workload and service requirements.
Which tool provides better support for real-time and streaming data?
Databricks provides stronger streaming capabilities through its integration with Apache Spark Structured Streaming and Lakeflow pipelines. Teams can build real-time ETL pipelines that process streaming data and write to Delta Lake tables with ACID guarantees. Databricks handles both batch and streaming in a unified environment. Trino focuses on interactive analytics and does not process streaming data natively, though it can query streaming systems like Kafka through its connector ecosystem. For organizations that need to ingest, transform, and analyze streaming data in real time, Databricks is the clear choice. Trino works best for querying data after it has landed in storage.
What are the key differences in governance and security between Databricks and Trino?
Databricks offers enterprise-grade governance through Unity Catalog on the Premium tier, providing unified data lineage, role-based access control, audit logging, table access controls, and compliance features. This makes Databricks suitable for regulated industries with strict data governance requirements. Trino relies on SQL-standard authentication and authorization, with governance depending largely on the underlying data sources it connects to. Trino supports LDAP authentication, Kerberos, and TLS encryption, but does not provide built-in data lineage, centralized catalog governance, or audit logging at the platform level. Teams needing comprehensive governance as a built-in capability should lean toward Databricks.