Decision comparison
Groq vs Together AI
Groq wins on speed and per-token cost with its custom LPU hardware, making it ideal for latency-critical inference workloads. Its sub-100ms time-to-first-token claims and 500+ tokens/sec on 70B models suit real-time conversational AI, voice systems, coding assistants, and high-volume serving. Together AI wins on platform completeness with fine-tuning, dedicated endpoints, and the broadest model catalog, making it the better choice for teams needing a full AI development lifecycle. Its LoRA or full fine-tuning, managed H100 and B200 capacity, and serverless deployment cover experimentation through production.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
All 2 are model hosting platforms.
Quick Comparison
| Decision factor | Groq | Together AI |
|---|---|---|
| Best For | Ultra-low latency inference on popular open-source models at competitive prices, including real-time voice, agentic applications, structured JSON outputs, and tool use. | Full-lifecycle AI platform with inference, fine-tuning, and dedicated GPU endpoints, spanning experimentation, model shaping, pre-training, serverless deployment, and production scale. |
| Hardware | Custom LPU (Language Processing Unit) chips purpose-built for sequential token generation, deployed globally for localized low-latency inference; GroqMetal offers dedicated bare-metal infrastructure. | NVIDIA HGX H100, H200, B200 and B300 GPUs with optimized inference serving; dedicated endpoints cost $5.49/GPU/hour on demand for H100 capacity and provide managed infrastructure. |
| Pricing Model | GroqCloud bills per 1M tokens, with separate input and output rates. Production models: GPT OSS 120B is $0.15 input and $0.60 output; GPT OSS 20B is $0.075 input and $0.30 output. Speech to text is billed per hour: Whisper Large V3 $0.111 and Whisper Large V3 Turbo $0.04. Preview models include Qwen3.8 27B at $0.80 input and $4.00 output, and Orpheus text to speech at $22.00 (English) or $40.00 (Arabic Saudi) per 1M characters. Llama 3.1 8B, Llama 3.3 70B and MiniMax M2.7 are Enterprise models priced through sales. Verified 2026-10-05 against https://console.groq.com/docs/models. | Pay as you go. Serverless inference is priced per 1M tokens by model, with separate input and output rates; paid chat models range from $0.04 input (Tev1 4B Experimental) to $3.00 input and $15.00 output (Kimi K3). Dedicated inference on demand: $5.49 per GPU per hour for NVIDIA HGX H100 and $8.99 for HGX B200; other GPUs and reserved capacity are quoted by sales. GPU clusters on demand from $3.99 per GPU per hour (H100). LoRA fine-tuning from $0.34 per 1M tokens (SFT), with a minimum charge per job from $4.00. Verified 2026-10-05 against https://www.together.ai/pricing. Together AI GPU Clusters on demand cost $3.99 per GPU-hour for NVIDIA HGX H100, $5.99 for HGX H200 and $8.19 for HGX B200. Code Sandbox is $0.0446 per vCPU-hour and $0.0149 per GiB RAM-hour, Code Interpreter is $0.03 per 60-minute session, and Shared Filesystem storage is $0.16 per GiB per month. Verified 2026-10-05 against https://www.together.ai/pricing. On Together AI serverless inference, Qwen3.7-Max costs $1.50 per 1M input tokens and $4.50 per 1M output tokens; gpt-oss-120B costs $0.15 input and $0.60 output. Verified 2026-10-05 against https://www.together.ai/pricing. |
| Model Catalog | Focused selection: Llama, Mixtral, Qwen, Gemma, Whisper, plus Orpheus text-to-speech; supports vision inputs, function calling, and OpenAI-compatible API endpoints. | 100+ open-source models across multiple architectures; broadest selection, including published pricing entries for GLM-5.1, MiniMax M2.7, Kimi K2.6, DeepSeek V4 Pro, and Qwen3.6-Plus. |
| Fine-Tuning | Not available; inference-only platform. GroqCore provides a production inference stack, while GroqAssured adds enterprise governance, auditability, and operational control. | LoRA and full fine-tuning on supported architectures, with LoRA SFT from $0.34 per 1M tokens, alongside model shaping and pre-training capabilities on a research-optimized full-stack platform. |
| Latency | Industry-leading; time-to-first-token often under 100ms, 500+ tokens/sec on 70B models, enabled by custom inference-purpose LPU silicon and worldwide data-center deployment. | Competitive with GPU providers; typically 200-500ms TTFT, with serverless inference designed for on-demand open-source models and no infrastructure management or long-term commitments. |
Groq
- Best For:
- Ultra-low latency inference on popular open-source models at competitive prices, including real-time voice, agentic applications, structured JSON outputs, and tool use.
- Hardware:
- Custom LPU (Language Processing Unit) chips purpose-built for sequential token generation, deployed globally for localized low-latency inference; GroqMetal offers dedicated bare-metal infrastructure.
- Pricing Model:
- GroqCloud bills per 1M tokens, with separate input and output rates. Production models: GPT OSS 120B is $0.15 input and $0.60 output; GPT OSS 20B is $0.075 input and $0.30 output. Speech to text is billed per hour: Whisper Large V3 $0.111 and Whisper Large V3 Turbo $0.04. Preview models include Qwen3.8 27B at $0.80 input and $4.00 output, and Orpheus text to speech at $22.00 (English) or $40.00 (Arabic Saudi) per 1M characters. Llama 3.1 8B, Llama 3.3 70B and MiniMax M2.7 are Enterprise models priced through sales. Verified 2026-10-05 against https://console.groq.com/docs/models.
- Model Catalog:
- Focused selection: Llama, Mixtral, Qwen, Gemma, Whisper, plus Orpheus text-to-speech; supports vision inputs, function calling, and OpenAI-compatible API endpoints.
- Fine-Tuning:
- Not available; inference-only platform. GroqCore provides a production inference stack, while GroqAssured adds enterprise governance, auditability, and operational control.
- Latency:
- Industry-leading; time-to-first-token often under 100ms, 500+ tokens/sec on 70B models, enabled by custom inference-purpose LPU silicon and worldwide data-center deployment.
Together AI
- Best For:
- Full-lifecycle AI platform with inference, fine-tuning, and dedicated GPU endpoints, spanning experimentation, model shaping, pre-training, serverless deployment, and production scale.
- Hardware:
- NVIDIA HGX H100, H200, B200 and B300 GPUs with optimized inference serving; dedicated endpoints cost $5.49/GPU/hour on demand for H100 capacity and provide managed infrastructure.
- Pricing Model:
- Pay as you go. Serverless inference is priced per 1M tokens by model, with separate input and output rates; paid chat models range from $0.04 input (Tev1 4B Experimental) to $3.00 input and $15.00 output (Kimi K3). Dedicated inference on demand: $5.49 per GPU per hour for NVIDIA HGX H100 and $8.99 for HGX B200; other GPUs and reserved capacity are quoted by sales. GPU clusters on demand from $3.99 per GPU per hour (H100). LoRA fine-tuning from $0.34 per 1M tokens (SFT), with a minimum charge per job from $4.00. Verified 2026-10-05 against https://www.together.ai/pricing. Together AI GPU Clusters on demand cost $3.99 per GPU-hour for NVIDIA HGX H100, $5.99 for HGX H200 and $8.19 for HGX B200. Code Sandbox is $0.0446 per vCPU-hour and $0.0149 per GiB RAM-hour, Code Interpreter is $0.03 per 60-minute session, and Shared Filesystem storage is $0.16 per GiB per month. Verified 2026-10-05 against https://www.together.ai/pricing. On Together AI serverless inference, Qwen3.7-Max costs $1.50 per 1M input tokens and $4.50 per 1M output tokens; gpt-oss-120B costs $0.15 input and $0.60 output. Verified 2026-10-05 against https://www.together.ai/pricing.
- Model Catalog:
- 100+ open-source models across multiple architectures; broadest selection, including published pricing entries for GLM-5.1, MiniMax M2.7, Kimi K2.6, DeepSeek V4 Pro, and Qwen3.6-Plus.
- Fine-Tuning:
- LoRA and full fine-tuning on supported architectures, with LoRA SFT from $0.34 per 1M tokens, alongside model shaping and pre-training capabilities on a research-optimized full-stack platform.
- Latency:
- Competitive with GPU providers; typically 200-500ms TTFT, with serverless inference designed for on-demand open-source models and no infrastructure management or long-term commitments.
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Groq | Together AI |
|---|---|---|
| GitHub commits, 90d(Developer adoption) | 20 | 337 |
| GitHub stars(Developer adoption) | 623 | 13 |
| Search interest(Market interest) | 2 | 11 |
| Hacker News mentions, 90d(Community interest) | 19 | 3 |
| Hugging Face downloads(Product adoption) | 1.6k | 24.0k |
| Hugging Face likes(Product adoption) | 511 | 2.4k |
| npm weekly downloads(Developer adoption) | 1.2M | 90.7k |
| PyPI weekly downloads(Developer adoption) | 3.7M | 387.6k |
As of November 16, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Groq
November 16, 2026Package vulnerabilities
PyPI · groq@1.7.0 · npm · groq-sdk@1.6.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Together AI
November 16, 2026Package vulnerabilities
PyPI · together@3.1.1 · npm · together-ai@1.1.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Interface Preview
Groq
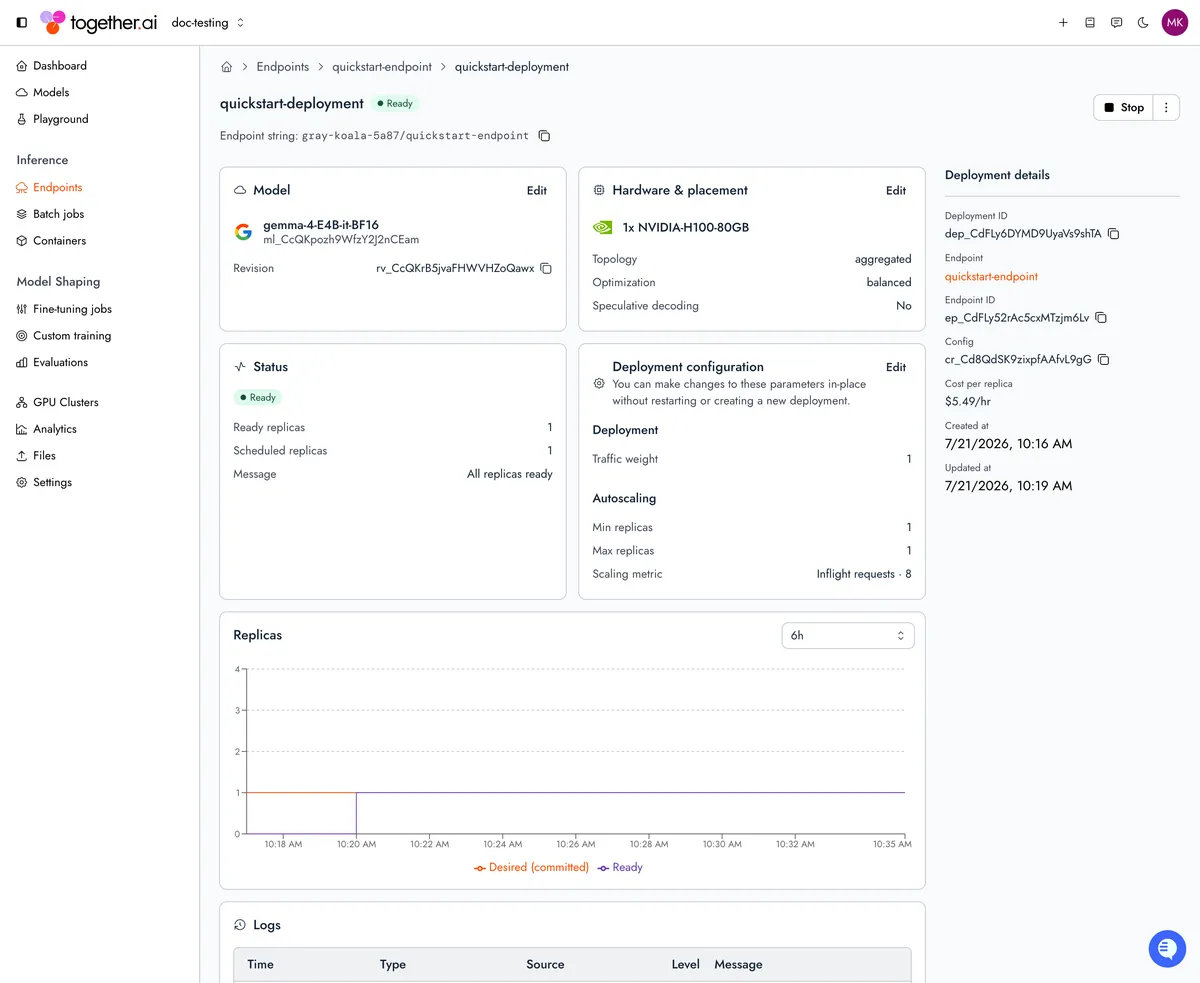
Together AI
Feature Comparison
| Feature | Groq | Together AI |
|---|---|---|
| Inference Capabilities | ||
| Hardware Architecture | Custom LPU chips designed for sequential token generation | NVIDIA HGX H100, H200, B200 and B300 GPUs with standard inference optimization |
| Inference Latency | Industry-leading; TTFT often under 100ms | Competitive with GPU providers; typically 200-500ms TTFT |
| Model Catalog Breadth | Focused: Llama, Mixtral, Qwen, Gemma, Whisper | Broad: 100+ open-source models across multiple architectures |
| Batch Processing | Batch API with 50% discount on standard pricing | Batch endpoints available for high-throughput workloads |
| Prompt Caching | 50% savings on cached input tokens | Context caching available for repeated prompts |
| Training & Customization | ||
| Fine-Tuning | Not verified | LoRA and full fine-tuning; LoRA SFT from $0.34 per 1M tokens |
| Dedicated Endpoints | Not available; shared LPU infrastructure only | $5.49/GPU/hour on demand for H100; reserved capacity quoted by sales |
| Custom Model Deployment | Limited to models supported on LPU hardware | Deploy custom fine-tuned models on dedicated endpoints |
| API & Integration | ||
| API Compatibility | OpenAI-compatible REST API | OpenAI-compatible API with additional fine-tuning endpoints |
| Built-in Tools | Search tools available | Function calling support on compatible models |
| Audio/Speech Support | Whisper v3 at $0.04-$0.111/hour | Speech models available through model catalog |
| Pricing & Access | ||
| Free Tier | No free tier; pay-as-you-go from first token | Pay as you go |
| Minimum Commitment | None; pure pay-as-you-go pricing | None; pay-as-you-go with no minimum |
Inference Capabilities
Hardware Architecture
Inference Latency
Model Catalog Breadth
Batch Processing
Prompt Caching
Training & Customization
Fine-Tuning
Dedicated Endpoints
Custom Model Deployment
API & Integration
API Compatibility
Built-in Tools
Audio/Speech Support
Pricing & Access
Free Tier
Minimum Commitment
Which to choose
Groq wins on speed and per-token cost with its custom LPU hardware, making it ideal for latency-critical inference workloads. Its sub-100ms time-to-first-token claims and 500+ tokens/sec on 70B models suit real-time conversational AI, voice systems, coding assistants, and high-volume serving. Together AI wins on platform completeness with fine-tuning, dedicated endpoints, and the broadest model catalog, making it the better choice for teams needing a full AI development lifecycle. Its LoRA or full fine-tuning, managed H100 and B200 capacity, and serverless deployment cover experimentation through production.
Best-fit scenarios
Choose Groq if:
Choose Groq for latency-critical applications, real-time conversational AI, coding assistants, and high-volume inference where speed and per-token cost are the primary decision factors. Use its OpenAI-compatible endpoints, JSON mode, function calling, and compound tools when building responsive agents without managing infrastructure.
Choose Together AI if:
Choose Together AI when you need fine-tuning on proprietary data, dedicated GPU endpoints with guaranteed capacity, or access to the broadest catalog of open-source models for experimentation and production. Its serverless pricing from $0.04/M input tokens and dedicated H100 endpoints at $5.49/GPU/hour support a staged rollout.
Choose Groq if:
Choose Groq for batch processing workloads where the 50% Batch API discount makes it significantly cheaper than alternatives for offline token processing at scale. Prompt caching also provides 50% savings on cached input tokens, helping recurring-context workloads reduce inference spend.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Is Groq faster than Together AI for inference?
Yes, significantly. Groq's custom LPU hardware is purpose-built for sequential token generation and consistently delivers inference speeds of 3-10x compared to GPU-based providers including Together AI. Time-to-first-token on Groq is often under 100 milliseconds, while GPU-based services typically range from 200-500 milliseconds.
Can I fine-tune models on Groq?
No. Groq is an inference-only platform and does not offer fine-tuning capabilities. If you need to customize model weights, Together AI (LoRA fine-tuning from $0.34 per 1M tokens) or other training platforms are your options. You can fine-tune a model elsewhere and run inference on Groq if the model is among supported architectures.
Which platform is cheaper for high-volume inference?
For pure inference without fine-tuning, Groq is generally 30-50% cheaper per token than Together AI on comparable models. The Batch API discount of 50% makes Groq even more cost-effective for offline workloads.
Does Together AI offer dedicated GPU capacity?
Yes. Together AI offers dedicated endpoints, providing reserved compute capacity with consistent latency for production applications with strict SLA requirements. Groq does not offer dedicated capacity.