Decision comparison
Fireworks AI vs Together AI
Fireworks AI wins on inference speed and per-token cost efficiency for small-to-mid-size models with batch discounts and hardware-level latency optimizations. Together AI wins on platform breadth and dedicated GPU economics, with H100s at $5.49/GPU/hour, for sustained workloads.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
All 2 are model hosting platforms.
Quick Comparison
| Decision factor | Fireworks AI | Together AI |
|---|---|---|
| Best For | Latency-sensitive production inference with aggressive per-token pricing on small-to-mid models | Unified platform for training, fine-tuning, and serving with broader model catalog |
| Pricing Model | Serverless inference is billed per token (input, output and cached) from pre-paid credits; per-model rates are in the pricing docs. Embeddings per 1M input tokens: $0.008 up to 150M parameters, $0.016 for 150M-350M, $0.1 for Qwen3 8B. Managed training per 1M training tokens, LoRA SFT: $0.50 up to 16B, $3.00 for 16.1B-80B, $6.00 for 80B-300B, $10.00 above 300B; DPO and full-parameter cost more. On-demand GPUs per hour: H100 and H200 $8.00, B200 $13.00, B300 $15.00, GB300 $20.00; region-restricted 1.5x. Verified 2026-10-05 against https://fireworks.ai/pricing. Serverless models without a per-model rate are priced by size: $0.10 per 1M tokens for models under 4B parameters and $0.90 per 1M tokens for models over 16B parameters. Per-model rates are listed in the serverless pricing docs. Verified 2026-10-05 against https://docs.fireworks.ai/serverless/pricing. | Pay as you go. Serverless inference is priced per 1M tokens by model, with separate input and output rates; paid chat models range from $0.04 input (Tev1 4B Experimental) to $3.00 input and $15.00 output (Kimi K3). Dedicated inference on demand: $5.49 per GPU per hour for NVIDIA HGX H100 and $8.99 for HGX B200; other GPUs and reserved capacity are quoted by sales. GPU clusters on demand from $3.99 per GPU per hour (H100). LoRA fine-tuning from $0.34 per 1M tokens (SFT), with a minimum charge per job from $4.00. Verified 2026-10-05 against https://www.together.ai/pricing. Together AI GPU Clusters on demand cost $3.99 per GPU-hour for NVIDIA HGX H100, $5.99 for HGX H200 and $8.19 for HGX B200. Code Sandbox is $0.0446 per vCPU-hour and $0.0149 per GiB RAM-hour, Code Interpreter is $0.03 per 60-minute session, and Shared Filesystem storage is $0.16 per GiB per month. Verified 2026-10-05 against https://www.together.ai/pricing. On Together AI serverless inference, Qwen3.7-Max costs $1.50 per 1M input tokens and $4.50 per 1M output tokens; gpt-oss-120B costs $0.15 input and $0.60 output. Verified 2026-10-05 against https://www.together.ai/pricing. |
| Free Credits | $1 for new accounts | None published; some serverless models are free, such as Ternary Bonsai 27B |
| Fine-Tuning | LoRA SFT from $0.50-$10.00/1M training tokens depending on model size | LoRA supervised fine-tuning from $0.34 per 1M tokens, minimum charge per job from $4.00 |
| Dedicated GPU | H100 at $8.00/hr, B200 at $13.00/hr on-demand | H100 at $5.49 and B200 at $8.99 per GPU-hour on demand for dedicated endpoints; other GPUs quoted |
| Model Catalog | Curated set of optimized models including Llama, Mixtral, DeepSeek V3, Qwen | Broad catalog spanning Llama, Mistral, DBRX, Stable Diffusion and more |
Fireworks AI
- Best For:
- Latency-sensitive production inference with aggressive per-token pricing on small-to-mid models
- Pricing Model:
- Serverless inference is billed per token (input, output and cached) from pre-paid credits; per-model rates are in the pricing docs. Embeddings per 1M input tokens: $0.008 up to 150M parameters, $0.016 for 150M-350M, $0.1 for Qwen3 8B. Managed training per 1M training tokens, LoRA SFT: $0.50 up to 16B, $3.00 for 16.1B-80B, $6.00 for 80B-300B, $10.00 above 300B; DPO and full-parameter cost more. On-demand GPUs per hour: H100 and H200 $8.00, B200 $13.00, B300 $15.00, GB300 $20.00; region-restricted 1.5x. Verified 2026-10-05 against https://fireworks.ai/pricing. Serverless models without a per-model rate are priced by size: $0.10 per 1M tokens for models under 4B parameters and $0.90 per 1M tokens for models over 16B parameters. Per-model rates are listed in the serverless pricing docs. Verified 2026-10-05 against https://docs.fireworks.ai/serverless/pricing.
- Free Credits:
- $1 for new accounts
- Fine-Tuning:
- LoRA SFT from $0.50-$10.00/1M training tokens depending on model size
- Dedicated GPU:
- H100 at $8.00/hr, B200 at $13.00/hr on-demand
- Model Catalog:
- Curated set of optimized models including Llama, Mixtral, DeepSeek V3, Qwen
Together AI
- Best For:
- Unified platform for training, fine-tuning, and serving with broader model catalog
- Pricing Model:
- Pay as you go. Serverless inference is priced per 1M tokens by model, with separate input and output rates; paid chat models range from $0.04 input (Tev1 4B Experimental) to $3.00 input and $15.00 output (Kimi K3). Dedicated inference on demand: $5.49 per GPU per hour for NVIDIA HGX H100 and $8.99 for HGX B200; other GPUs and reserved capacity are quoted by sales. GPU clusters on demand from $3.99 per GPU per hour (H100). LoRA fine-tuning from $0.34 per 1M tokens (SFT), with a minimum charge per job from $4.00. Verified 2026-10-05 against https://www.together.ai/pricing. Together AI GPU Clusters on demand cost $3.99 per GPU-hour for NVIDIA HGX H100, $5.99 for HGX H200 and $8.19 for HGX B200. Code Sandbox is $0.0446 per vCPU-hour and $0.0149 per GiB RAM-hour, Code Interpreter is $0.03 per 60-minute session, and Shared Filesystem storage is $0.16 per GiB per month. Verified 2026-10-05 against https://www.together.ai/pricing. On Together AI serverless inference, Qwen3.7-Max costs $1.50 per 1M input tokens and $4.50 per 1M output tokens; gpt-oss-120B costs $0.15 input and $0.60 output. Verified 2026-10-05 against https://www.together.ai/pricing.
- Free Credits:
- None published; some serverless models are free, such as Ternary Bonsai 27B
- Fine-Tuning:
- LoRA supervised fine-tuning from $0.34 per 1M tokens, minimum charge per job from $4.00
- Dedicated GPU:
- H100 at $5.49 and B200 at $8.99 per GPU-hour on demand for dedicated endpoints; other GPUs quoted
- Model Catalog:
- Broad catalog spanning Llama, Mistral, DBRX, Stable Diffusion and more
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Fireworks AI | Together AI |
|---|---|---|
| GitHub commits, 90d(Developer adoption) | 56 | 337 |
| GitHub stars(Developer adoption) | 12 | 13 |
| Search interest(Market interest) | 1 | 11 |
| Hacker News mentions, 90d(Community interest) | 0 | 3 |
| Hugging Face downloads(Product adoption) | 441 | 24.0k |
| Hugging Face likes(Product adoption) | 341 | 2.4k |
| PyPI weekly downloads(Developer adoption) | 330.9k | 387.6k |
| npm weekly downloads(Developer adoption) | Not available | 90.7k |
As of November 16, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Fireworks AI
November 16, 2026Package vulnerabilities
PyPI · fireworks-ai@1.2.33
0 vulnerabilities
across 1 package
Repository security score
Not available
Together AI
November 16, 2026Package vulnerabilities
PyPI · together@3.1.1 · npm · together-ai@1.1.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Interface Preview
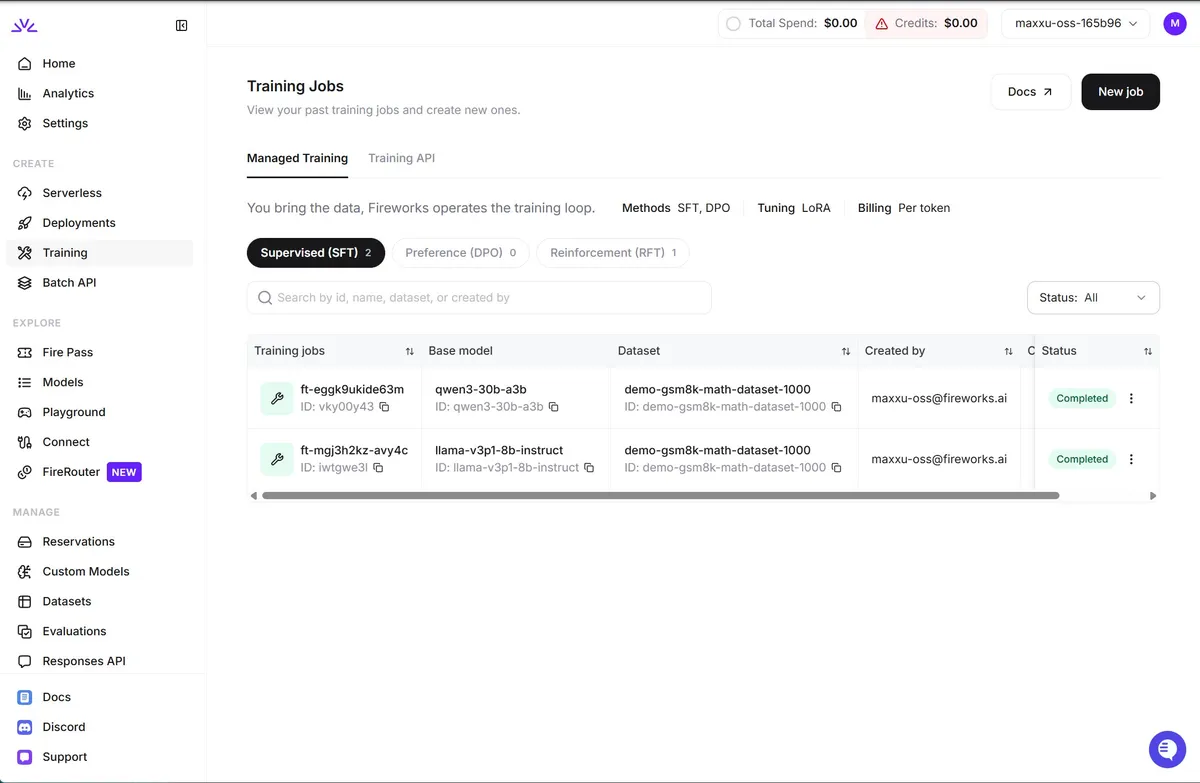
Fireworks AI
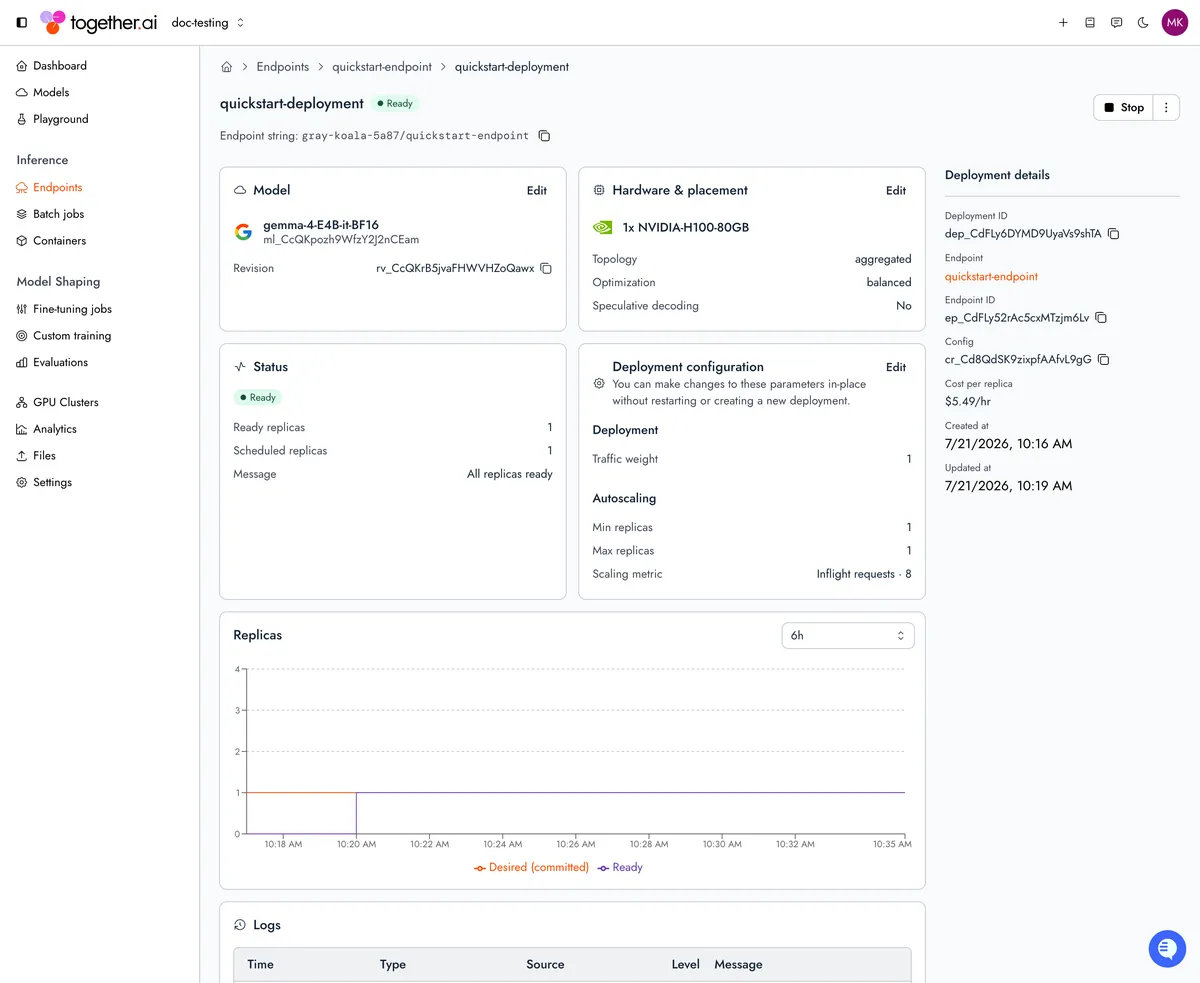
Together AI
Feature Comparison
| Feature | Fireworks AI | Together AI |
|---|---|---|
| Inference Capabilities | ||
| Serverless Inference | Pay-per-token with three model-size tiers; per-model rates are published in the documentation | Pay-per-token, with rates set per model |
| Batch Inference | 50% discount on batch processing jobs | Available through dedicated endpoint allocation |
| Cached Input | 50% discount on cached prompt tokens | No separately listed cached input discount |
| Function Calling | Native function calling support in serverless endpoints | Supported on compatible model architectures |
| Image Generation | FLUX.1 Kontext Pro | Stable Diffusion family models available |
| GPU and Compute | ||
| Dedicated GPU Hardware | H100 at $8.00/hr and B200 at $13.00/hr on-demand | H100 at $5.49 and B200 at $8.99 per GPU-hour on demand for dedicated endpoints; other GPUs quoted |
| GPU Pricing Model | On-demand hourly billing for reserved compute | Dedicated endpoint hourly billing with reserved capacity |
| Embeddings | From $0.008/1M tokens for embedding models | Available through serverless API at model-specific rates |
| Fine-Tuning and Training | ||
| Fine-Tuning Method | LoRA SFT with pricing from $0.50-$10.00/1M training tokens | LoRA supervised fine-tuning from $0.34 per 1M tokens |
| Model Size Impact on Cost | Training cost scales with base model size across tiers | Flat per-token rate regardless of model size |
| Pricing and Onboarding | ||
| Free Tier | $1 in free credits for new accounts | No free credits published; some serverless models are free, such as Ternary Bonsai 27B |
| Minimum Commitment | No minimum; pay-as-you-go serverless billing | No minimum; pay-as-you-go with no commitment required |
| MoE Model Pricing | MoE models in the 0-56B range | Per-model pricing for MoE architectures |
| DeepSeek V3 | Billed per 1M input and output tokens at the model's published rate | Available at model-specific serverless rate |
Inference Capabilities
Serverless Inference
Batch Inference
Cached Input
Function Calling
Image Generation
GPU and Compute
Dedicated GPU Hardware
GPU Pricing Model
Embeddings
Fine-Tuning and Training
Fine-Tuning Method
Model Size Impact on Cost
Pricing and Onboarding
Free Tier
Minimum Commitment
MoE Model Pricing
DeepSeek V3
Which to choose
Fireworks AI wins on inference speed and per-token cost efficiency for small-to-mid-size models with batch discounts and hardware-level latency optimizations. Together AI wins on platform breadth and dedicated GPU economics, with H100s at $5.49/GPU/hour, for sustained workloads.
Best-fit scenarios
Choose Fireworks AI if:
Choose Fireworks AI for latency-sensitive production inference on sub-16B models where batch discounts (50% off) and hardware-optimized speed are top priorities.
Choose Together AI if:
Choose Together AI for a unified training-to-serving platform, dedicated H100 GPUs at $5.49/hr, and a broader model catalog for experimentation and fine-tuning.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Can I use both Fireworks AI and Together AI simultaneously?
Yes, many teams use a multi-provider strategy where they route different model sizes or workload types to the most cost-effective platform. Both expose OpenAI-compatible API endpoints, making switching straightforward.
Which platform supports more open-source models?
Together AI generally offers a broader model catalog spanning language, image, and embedding models. Fireworks AI focuses on a curated set optimized for its inference engine including Llama, Mixtral, DeepSeek V3, and Qwen families.
How do fine-tuning costs compare between the two platforms?
Fireworks AI charges $0.50-$10.00/1M training tokens for LoRA SFT depending on model size. Together AI's LoRA supervised fine-tuning starts at $0.34 per 1M tokens, with a minimum charge per job from $4.00. Fireworks publishes its per-model serverless rates in its documentation.
What happens when I exhaust the free credits?
On Fireworks AI, after the $1 credit is consumed, usage bills at standard rates. On Together AI, billing is pay-as-you-go. Neither cuts off access; both transition to paid billing automatically.