Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Together AI states |
|---|---|
Operating model | Serverless Inference runs open-source models on demand with no infrastructure to manage and no long-term commitments. |
Inference options | Serverless, Batch, Provisioned Throughput, Dedicated Model Inference and Dedicated Container Inference (for video, audio and image models). |
Uptime SLA | 99% uptime SLA on Provisioned Throughput, which reserves committed inference capacity with token-based pricing. |
Batch scale | Asynchronous batch jobs scale to 30 billion tokens per model, with any serverless model or private deployment. |
Storage egress | Managed Storage (object storage and parallel filesystems) has zero egress fees. |
Python SDK | Official client under the Apache-2.0 license; |
Our take
Together AI is a good fit if you want to start with pay-per-use model calls and later move the same workload to reserved capacity, dedicated GPUs or a fine-tuned model without changing vendors. Together AI says on its pricing page that most teams start with serverless inference and move to dedicated endpoints at scale. If you need one fixed monthly figure before you start, expect to model usage per model and per service first.
Evaluate Together AI
Popular comparisons
See all 5 Together AI comparisons
Where it stands out
Model weights can move in and out. The CLI can download fine-tuned model weights and upload a model from S3 or Hugging Face, so a tuned model is not tied to Together's endpoints.
One account for many model types. The pricing page covers chat, vision, image, audio, video, transcription, embeddings, rerank and moderation. Listed models include GPT Image 2 and ByteDance Seedance 2.5.
Production defaults in the SDK. The Python client retries connection errors, 408, 409, 429 and 5xx responses 2 times by default, times out after 1 minute, and streams responses over Server Side Events. Less retry code to write yourself.
Live transcription that survives drops. The beta realtime transcription session streams PCM audio over a WebSocket and reconnects automatically, keeping speech that was not yet transcribed.
Product screenshot
Trade-offs to weigh
Each service bills in its own unit. Tokens, megapixels or images, characters, videos, audio minutes, GPU-hours and vCPU-hours all apply. Shown image and video prices refer to the lowest resolution or duration settings, and the vendor says actual prices might vary.
Reserved throughput needs sizing. Provisioned Throughput is bought in throughput units (PTUs); the tokens per minute one PTU delivers depends on the model and the token type, so you must size it per model.
Some tools are still beta. Realtime transcription sits under
client.beta, and Jig container deployments run undertg beta jig. Plan for interface changes if you build on them.
Pricing and plan conditions
Billing is usage-based and set per service. Serverless calls bill per model and per unit, while dedicated inference and GPU clusters bill per GPU per hour. Moving from serverless to dedicated changes what drives the bill from usage volume to hours of dedicated GPU time. The table shows sample rates; each service lists many more models and hardware types.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Service | Published price | Billing conditions |
|---|---|---|
Serverless chat: MiniMax M3 | $0.30 input, $0.06 cached input, $1.20 output per 1M tokens | Separate input and output rates; cached-input rates are shown for some models. |
Serverless chat: Kimi K3 | $3.00 input, $15.00 output per 1M tokens | Rates vary by model. |
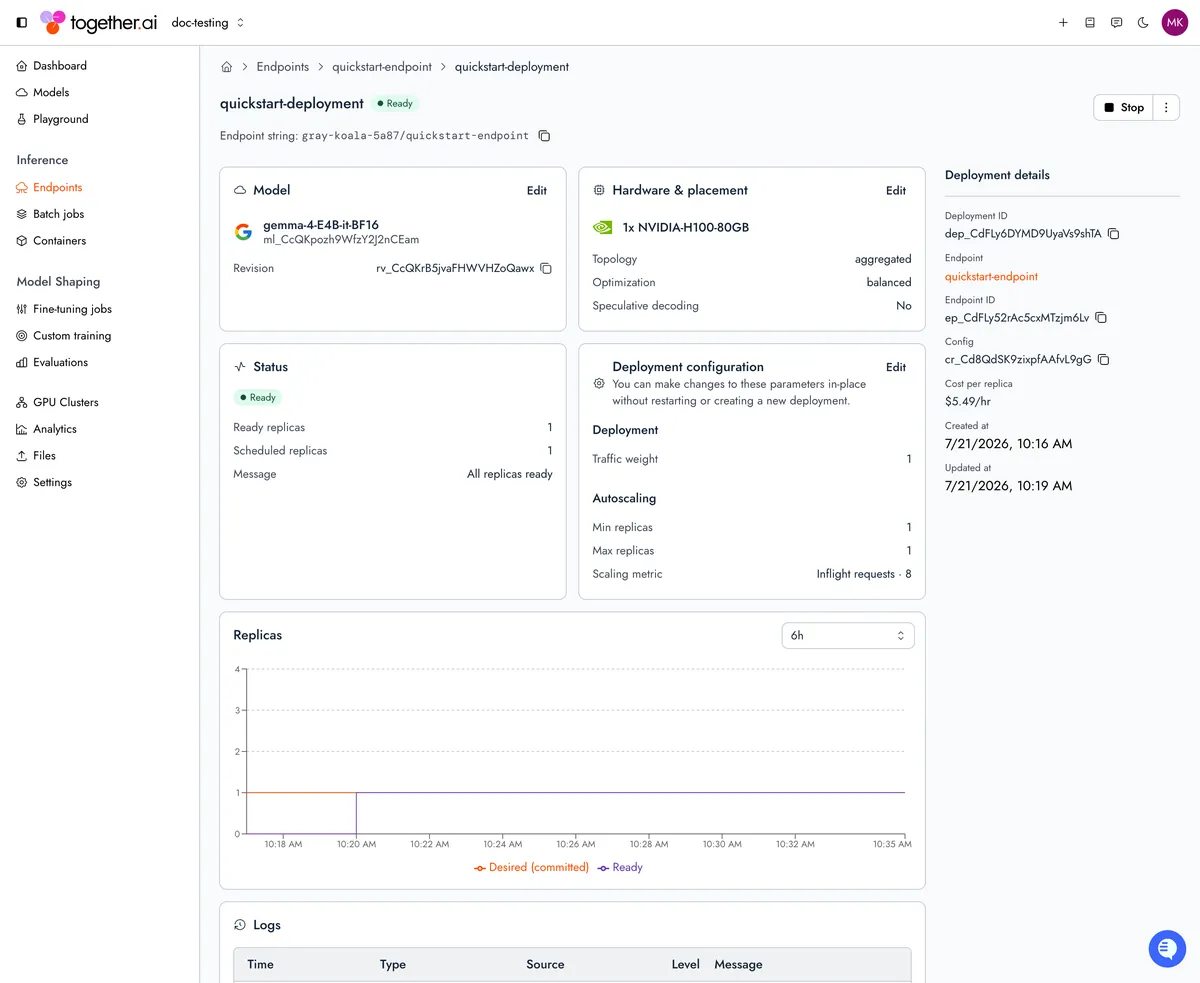
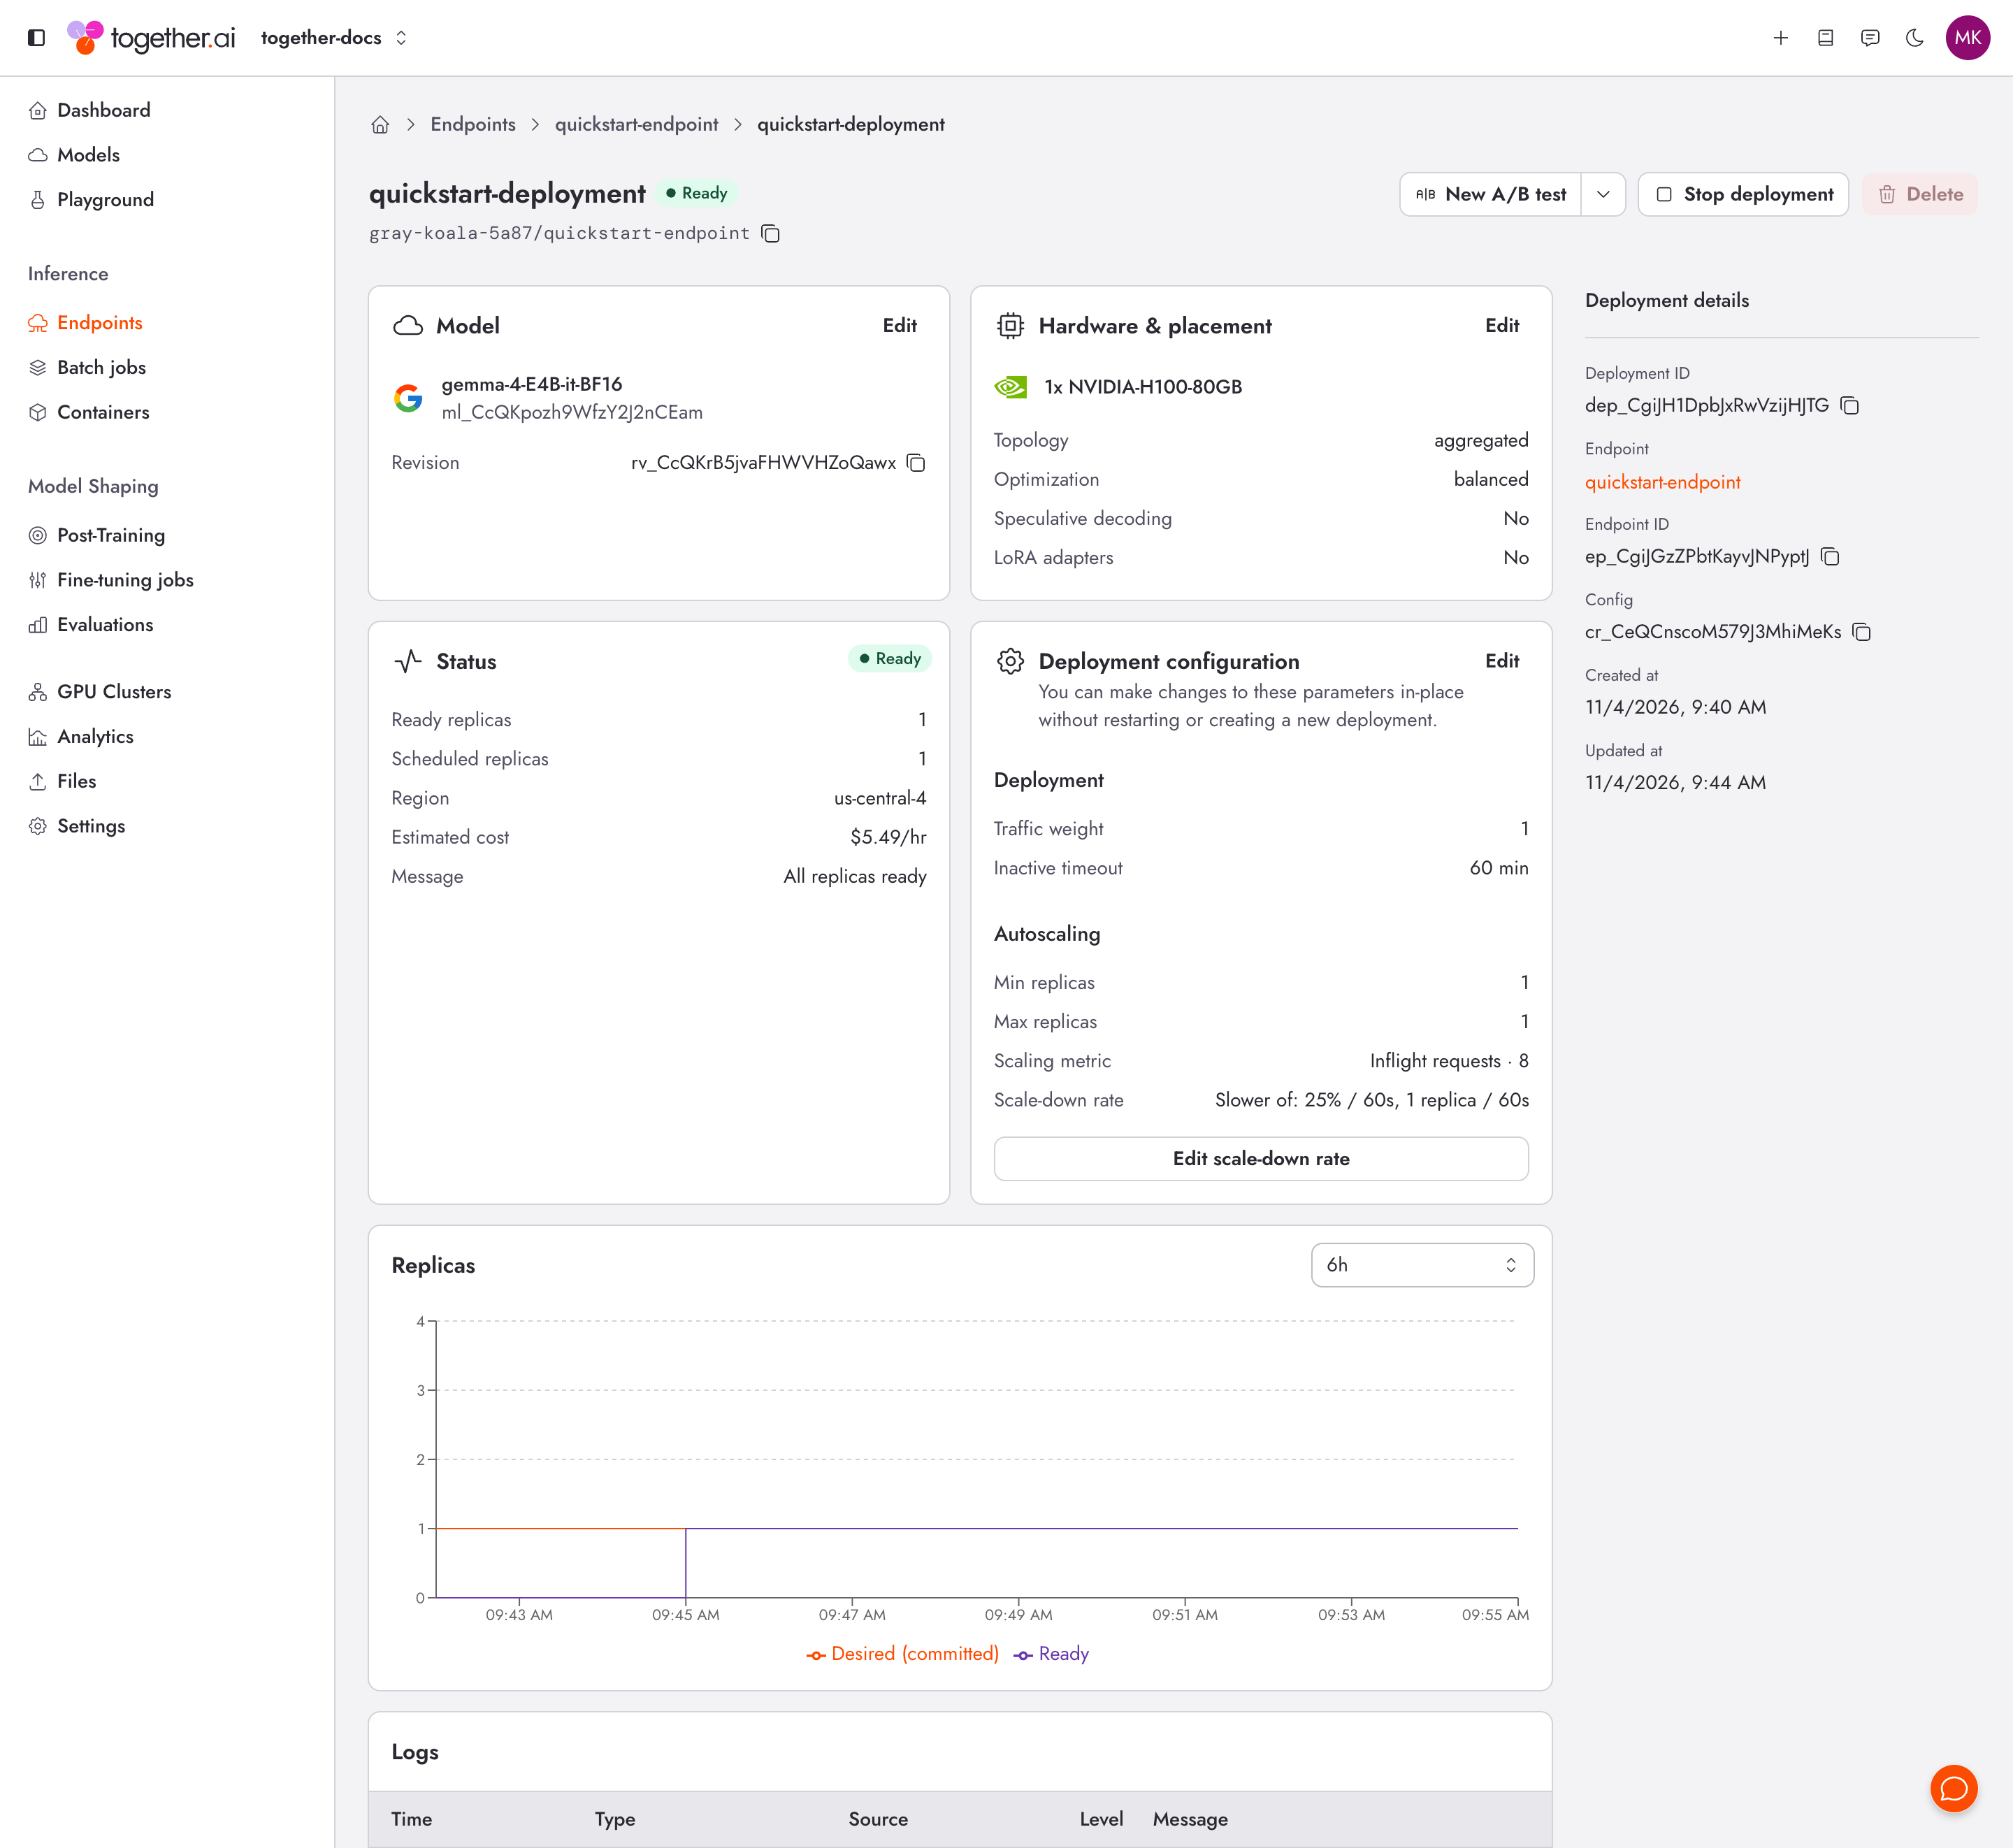
Dedicated inference: NVIDIA HGX H100 | $5.49 per GPU per hour, on-demand | Single-tenant GPU instances with guaranteed performance, custom model support and autoscaling. Reserved: Contact sales. |
Dedicated inference: NVIDIA HGX B200 | $8.99 per GPU per hour, on-demand | Reserved: Contact sales. |
GPU Clusters | Per GPU per hour, by hardware type | Preemptible and on-demand hourly rates, plus reserved terms of 3-30, 31-90, 91-180 and 181+ days. |
Code Sandbox | $0.0446 per vCPU per hour; $0.0149 per GiB RAM per hour | Customized deployments of VM sandboxes for large development environments. |
Fine-tuning | Per 1M tokens, by model, for LoRA or full fine-tuning | Fine-tunes open-source models without managing training infrastructure. Supervised Fine-Tuning and Direct Preference Optimization are priced separately. Tokens billed = training dataset size × number of epochs, plus validation dataset size × number of evaluations. Each job is subject to the minimum charge shown for its model. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
339 GitHub commits 90d12 GitHub stars0 vulnerabilities across 2 packages
See all signals from 7 sources
PyPI · together@3.1.1 · npm · together-ai@1.0.0
Alternatives to Together AI
The reviewed substitutes for Together AI among the model hosting platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Replicate
- Together AI and Replicate are cloud services where developers call open-source AI models by API instead of hosting them on their own GPUs. Together AI focuses on language models with serverless inference, fine-tuning and dedicated GPU clusters, while Replicate covers a wide range of image, audio, video and language models and deploys any Python model packaged with Cog.Applies to: Choosing between two products of the same kind for one job.
- Baseten
- Both host open-weight models as a managed service billed by usage. They are bought for the same job.
- Fireworks AI
- Together AI and Fireworks AI are cloud platforms that serve open-source and custom language models through an API, with serverless endpoints and fine-tuning. Together AI also rents dedicated GPU clusters and supports custom training, while Fireworks AI puts serving speed first with its own optimised inference stack and adds function calling and multi-modal APIs.Applies to: Choosing between two products of the same kind for one job.
- Groq
- Together AI and Groq run open language models for developers who want fast inference through an API. Groq serves models on its own custom LPU chips and stresses very low latency for real-time voice and agent workloads, while Together AI runs on GPUs and adds fine-tuning, dedicated clusters and custom training.Applies to: Choosing between two products of the same kind for one job.
- Runcrate
- Both serve open models through an OpenAI-compatible API billed per token and also rent GPUs on the same account (Runcrate's pricing page lists GPU instances beside its model API). Together AI adds a managed fine-tuning service; on Runcrate you fine-tune on your own GPU instance.Applies to: Calling open models from an application, with GPUs on the same account for fine-tuning.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Ollama
- Together AI is chosen instead of Ollama for open-weight inference workloads larger than a workstation holds, where prompts may leave the network. **Together AI** is the managed alternative for the same open models.
- vLLM
- Cross-class on purpose: a self-hosted inference engine against a managed endpoint is not the same product, and it is the decision a team actually makes. The 2026 guidance states the crossover in numbers -- choose vLLM when you already run GPU infrastructure, need full data sovereignty, or sustained volume runs past roughly 1-2 billion tokens a month on a single GPU; choose the managed endpoint below that, because a single T4 must sustain about 500-750 tokens a second around the clock just to match managed per-token pricing. Together is described as the default managed stop for most production teams -- the same OpenAI-compatible API shape, a comparable model catalogue and pricing within a few cents of Fireworks -- so the fork is operating GPUs rather than any difference in what the model can do.Applies to: Serving an open-weight model in production. Together AI stands in for vLLM when nobody wants to own GPU operations and volume is below the crossover; vLLM stands in when infrastructure exists, sovereignty is required, or sustained volume passes it.
- Anyscale
- Both offer serverless inference plus dedicated GPU clusters for open models.Applies to: Serverless inference and fine-tuning of open models, with dedicated GPU capacity when needed.
- Cohere
- Cohere and Together AI both give an application hosted language models through an API, so either can supply the model layer of an AI stack. Cohere sells its own enterprise models for generation, embeddings and retrieval with data privacy controls, while Together AI runs and fine-tunes open-source models on serverless endpoints or dedicated GPU clusters. The choice turns on whether the stack is built on a vendor's own models or on open models.Applies to: When an application calls hosted language models through an API instead of running models in-house.
- LocalAI
- Together AI is chosen instead of LocalAI for open-weight inference workloads that outgrow local hardware and can accept prompts leaving the network. **Together AI** removes the operational cost entirely, serving open weights over a managed API from $0.04 per million input tokens for small models to $3.00 input and $15.00 output per million for the largest, with no capacity to plan and no monthly floor.
- Snowflake Cortex
- Cortex's pitch is not model quality -- it hosts other vendors' models -- but the perimeter: unified governance, permissions, telemetry and spend controls, with the text you pass in never leaving the Snowflake account boundary. A hosting platform is the other answer: send the data out to a managed endpoint and get a wider model catalogue and independent scaling. For the enrichment and analytics workload that sits on warehouse data, a team picks one. Together AI is the general-purpose managed endpoint in that trade: an OpenAI-compatible API over a broad open-weight catalogue, with no relationship to where the data is governed.