Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Fireworks AI states |
|---|---|
Inference options | Serverless: pay per token, with Priority and Fast options. On-Demand: dedicated deployments, multi-region, supports post-trained models. Reserved: guaranteed capacity, higher quotas and the newest hardware first. |
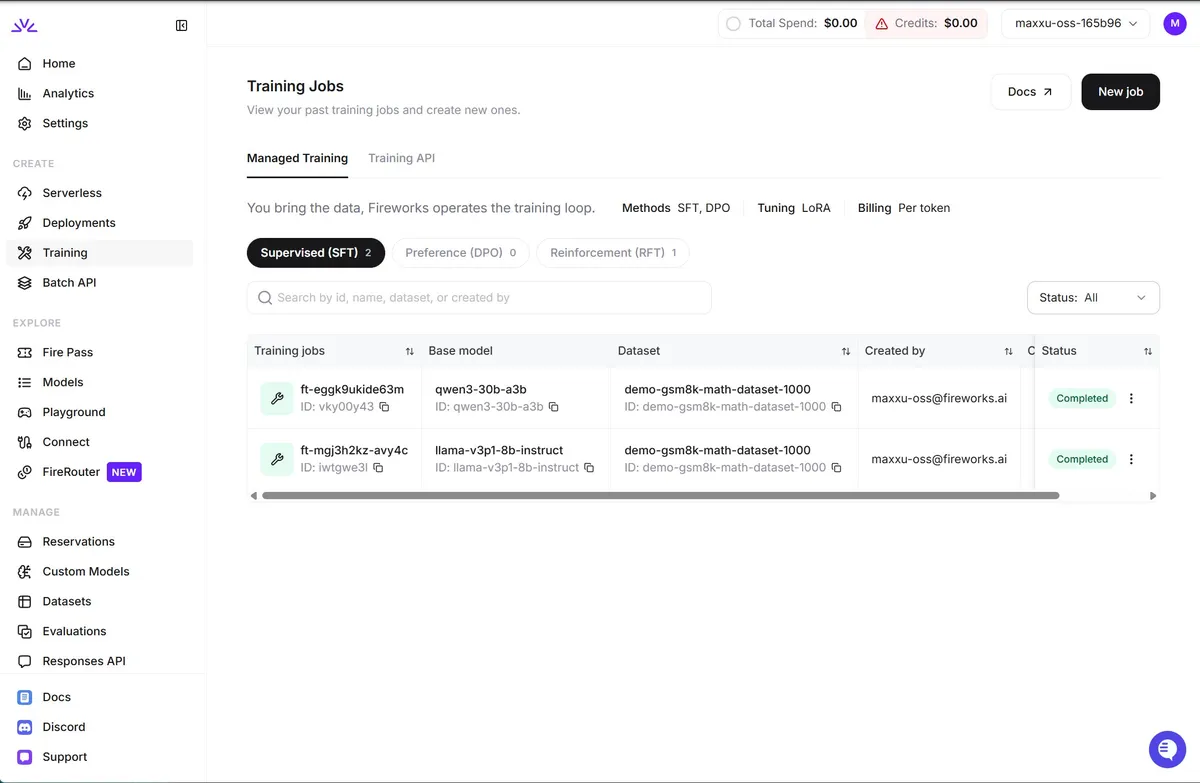
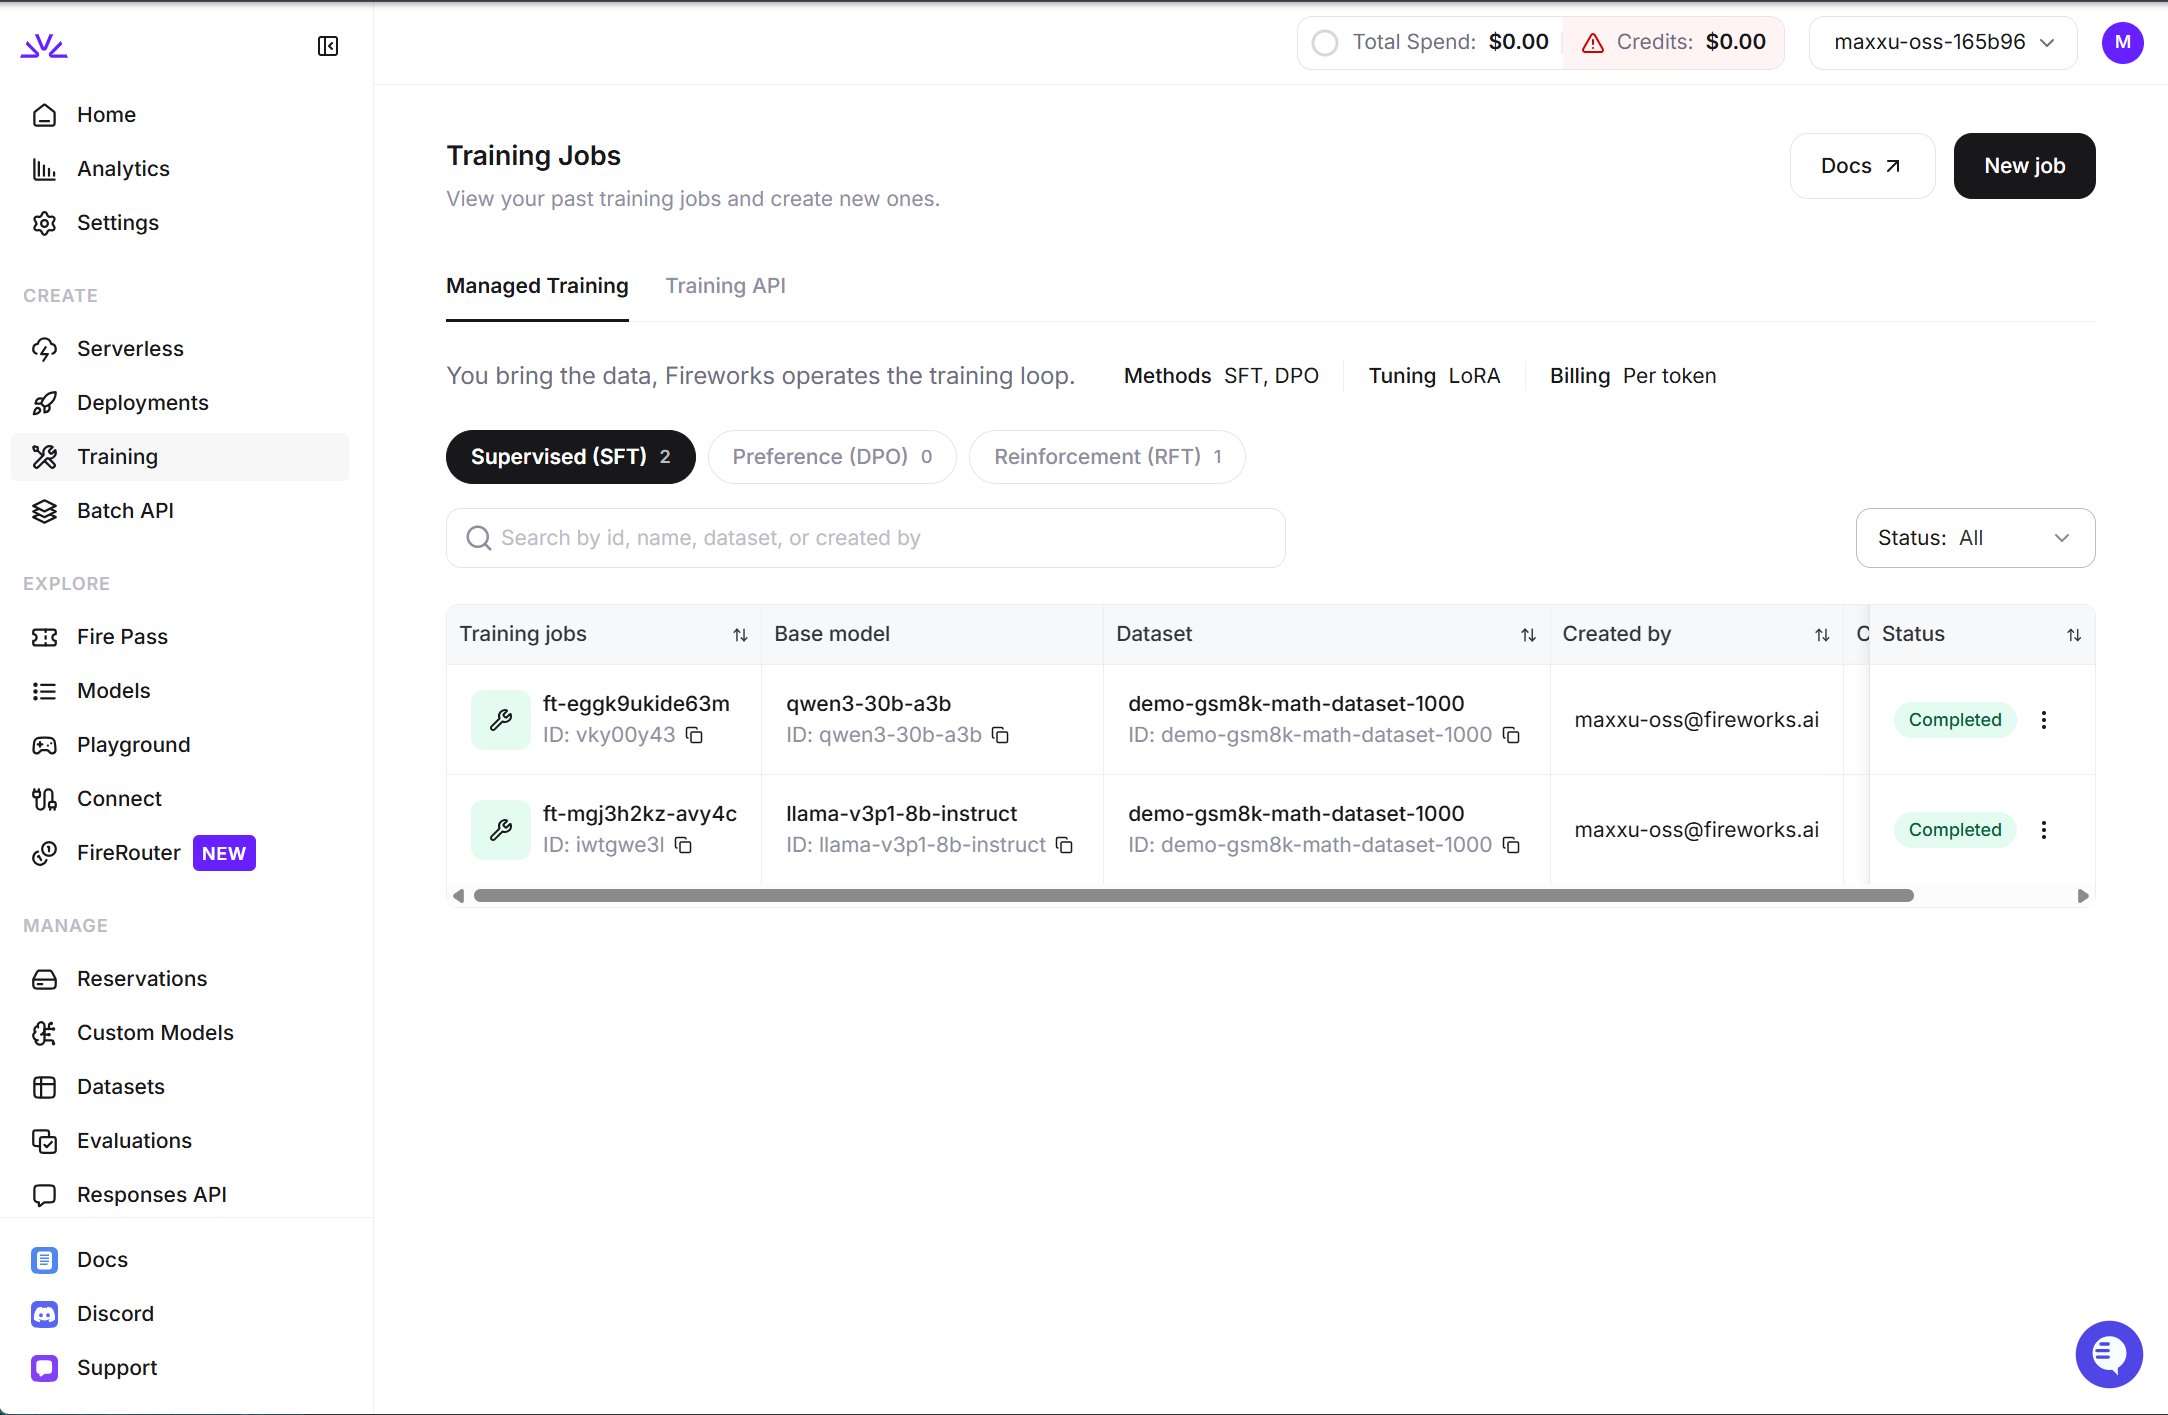
Training options | Managed SFT and DPO (LoRA or full-parameter); a Serverless Training API for LoRA on launch models; a Dedicated Training API priced per GPU hour. |
Enterprise | Fireworks asks buyers to contact it for enterprise deployments, which it says bring faster speeds, lower costs and higher rate limits. |
Python SDK | Apache-2.0 library, installed with pip install fireworks-ai; Python 3.9+; synchronous and asynchronous clients. |
Training data | JSONL files. The SDK uploads files under 150MB directly and larger files through a signed URL. |
Our take
Fireworks AI makes most sense if you plan to go from calling open models to fine-tuning or RL-training your own versions and serving them in one place. If you only need one closed model behind a fixed API, its training and deployment options add little.
Evaluate Fireworks AI
Comparisons
Where it stands out
Drop-in API. Serverless inference is OpenAI and Anthropic compatible, which matters if your code already uses those APIs.
Fine-tuned models at base prices. Fireworks serves fine-tuned models for the same price as base models, and every checkpoint deploys to production in seconds. Customizing a model does not add a serving premium.
Training depth. You can start with a guided run (describe the task, review the plan and cost, approve), move to configuration-led runs, or write your own loss, trainer and RL loop on Fireworks GPUs.
Customer example. Notion's AI Lead, Sarah Sachs, is quoted on the Fireworks site saying fine-tuning with Fireworks cut latency from about 2 seconds to 350 milliseconds.
Product screenshot
Trade-offs to weigh
Training token counts grow with data shape. Fireworks estimates training tokens as dataset tokens times epochs. With intermediate thinking traces, multiply again by the average number of turns divided by two; adding reasoning_content to assistant turns raises the count.
Serverless budgets depend on the model and path. The pricing page sends buyers to Fireworks' pricing documentation for current rates on the Standard, Priority and Fast serving paths, so check the exact model and path before you plan a budget.
Training setup is stricter than inference. SDK training needs Python 3.11+, fireworks-ai[training]>=1.2.11,<2 and a training-scoped API key. The legacy 0.19.20 package has no training module.
Serverless training covers launch models only. The Serverless Training API trains LoRA on its launch models; Fireworks says other frontier models are coming soon.
Pricing and plan conditions
Serverless inference has zero setup and no cold starts. It is pre-paid: you add a payment method, buy credits, and usage is deducted from the balance. It is billed on input, output and cached tokens. Auto Reload tops up a low balance, or a monthly spend limit caps usage. On-demand deployments bill per GPU second, with no extra charge for start-up time; Dedicated Training API jobs use the same GPU rates per hour. Region-restricted deployments are priced at a 1.5x premium.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Product | Published price | Conditions |
|---|---|---|
Serverless inference | GLM 5.3 Flash: $0.15/M input, $0.5/M output. GLM-5.3: $1.4/M input, $4.4/M output. Kimi K3: $3/M input, $15/M output. | Model rates shown in the Fireworks model library. |
Embeddings | $0.008 / 1M input tokens (up to 150M parameters); $0.016 (150M - 350M); $0.1 (Qwen3 8B) | Priced by base model parameter count. |
Managed training, models up to 16B | LoRA SFT $0.50; LoRA DPO $1.00; Full Param SFT $1.00; Full Param DPO $2.00 | Per 1M training tokens. Image fine-tuning is also billed per 1M tokens. |
Managed training, models 16.1B - 80B | LoRA SFT $3.00; LoRA DPO $6.00; Full Param SFT $6.00; Full Param DPO $12.00 | Per 1M training tokens. |
Managed training, models 80B - 300B (e.g. Qwen3-235B, gpt-oss-120B) | LoRA SFT $6.00; LoRA DPO $12.00; Full Param SFT $12.00; Full Param DPO $24.00 | Per 1M training tokens. |
Managed training, models >300B (e.g. DeepSeek V3, Kimi K2) | LoRA SFT $10.00; LoRA DPO $20.00; Full Param SFT $20.00; Full Param DPO $40.00 | Per 1M training tokens. |
Serverless Training API | Per 1M tokens, e.g. Qwen 3.8 27B: $1.86 prefill, $0.372 cached prefill, $5.595 sample, $4.103 train | LoRA on launch models: Muse Spark Open (256K context), GLM 5.3 Flash (200K), GLM 5.3 (262K), Qwen 3.8 27B (128K), Kimi K3 (192K), DeepSeek V4 Flash 0731 (262K), Muse Glimmer 30B (128K), DeepSeek V4.1 Flash. Shared trainer pool, no provisioning or idle cost. Checkpoint storage included during private preview. Limited-time: Muse Glimmer 30B SFT free until 11/30, no credit card required. |
On-demand H100 80 GB | $0.134 per minute; $8.00 per hour | Billed per GPU second. |
On-demand H200 141 GB | $0.134 per minute; $8.00 per hour | Billed per GPU second. |
On-demand B200 180 GB | $0.217 per minute; $13.00 per hour | Billed per GPU second. |
On-demand GB300 288 GB | $0.334 per minute; $20.00 per hour | Billed per GPU second. |
On-demand B300 288 GB | $0.250 per minute; $15.00 per hour | Billed per GPU second. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
51 GitHub commits 90d10 GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
PyPI · fireworks-ai@1.2.30
Alternatives to Fireworks AI
The reviewed substitutes for Fireworks AI among the model hosting platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Baseten
- Both are managed inference platforms for open and custom models. A team sends a workload to one of them.
- Groq
- Choose Groq when sub-100ms time-to-first-token latency is your primary constraint and you can work within its supported model catalog.Applies to: Choosing where open models are hosted and served for inference.
- Replicate
- Choose Replicate when its supported media models and Cog deployment fit your pipeline.Applies to: Choosing where open models are hosted and served for inference.
- Together AI
- Together AI and Fireworks AI are cloud platforms that serve open-source and custom language models through an API, with serverless endpoints and fine-tuning. Together AI also rents dedicated GPU clusters and supports custom training, while Fireworks AI puts serving speed first with its own optimised inference stack and adds function calling and multi-modal APIs.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Ollama
- Fireworks AI is used rather than Ollama for pay-per-token serverless inference workloads where the specific model served decides the choice. **Fireworks AI** is another pay-per-token serverless option for open models, with $1 in free credits for new accounts to evaluate against.
- vLLM
- Cross-class on purpose: a self-hosted inference engine against a managed endpoint is not the same product, and it is the decision a team actually makes. The 2026 guidance states the crossover in numbers -- choose vLLM when you already run GPU infrastructure, need full data sovereignty, or sustained volume runs past roughly 1-2 billion tokens a month on a single GPU; choose the managed endpoint below that, because a single T4 must sustain about 500-750 tokens a second around the clock just to match managed per-token pricing. Fireworks is the case this is documented against, and it adds full fine-tuning, LoRA and Multi-LoRA serving that a self-hosted stack has to assemble.Applies to: Serving an open-weight model in production. Fireworks stands in for vLLM when the team wants a compliant endpoint in minutes with no GPU to operate and volume sits below the crossover; vLLM stands in when the GPUs and the on-call capacity already exist, or data must not leave.
- LocalAI
- Fireworks AI is used rather than LocalAI for pay-per-token serverless inference workloads where the specific model version matters more than keeping the runtime in-house. **Fireworks AI** covers similar ground with pay-per-token serverless inference over open models and trial credits for new accounts.