Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Replicate states |
|---|---|
Model catalog | Thousands of community-contributed open-source models, plus proprietary models. The catalog covers images, video, speech, music and language models, with official listings from Google, OpenAI, Anthropic, Black Forest Labs and ByteDance. |
API access | An API token. The official JavaScript client installs from npm, ships TypeScript types and runs on Node.js 18 or later, Cloudflare Workers and Vercel Functions. |
Custom models | Cog generates the API server for your model; Replicate deploys it and scales instances up and down with demand. |
Our take
Choose Replicate when you want to call many different hosted models, or deploy your own, through one API and pay per use instead of running GPU servers yourself.
Evaluate Replicate
Comparisons
Where it stands out
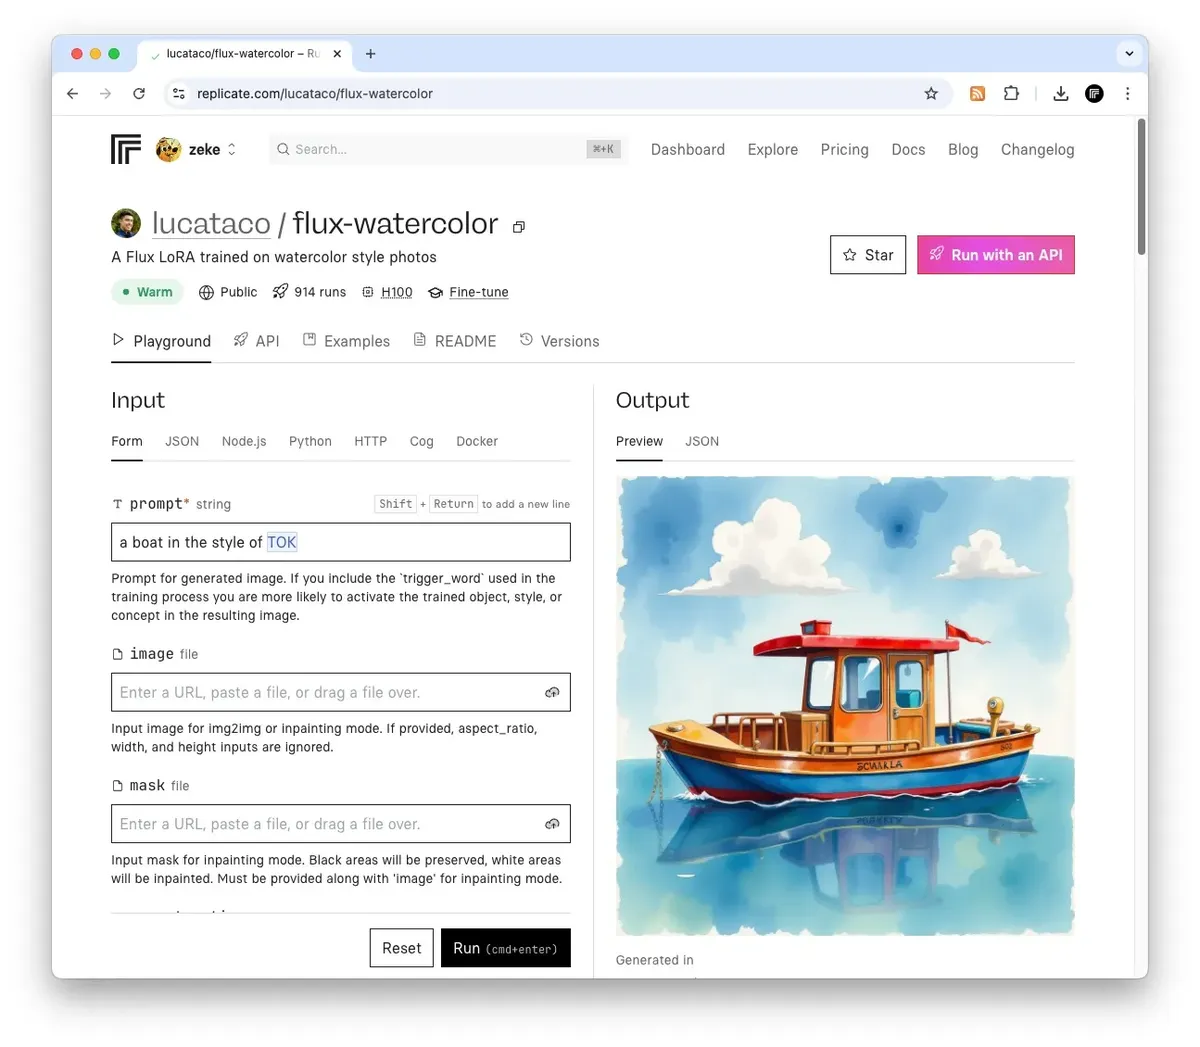
Easy to try many models. Community, official and your own models use the same run call, so switching models means changing an identifier. Each model page shows a cost estimate.
Fine-tuning from your own data. One API call can train a new model from your data, for example a FLUX LoRA trainer on a zip of images, and you then run the result like any other model.
Production plumbing in the client. Predictions can run in the background with wait or polling, stream output as server-sent events, and send signed webhooks on start, output, logs and completed events. Metrics and per-prediction logs help with debugging.
Product screenshot
Trade-offs to weigh
Private models force a sizing choice. Keeping a private model's instances online means paying for idle time; letting them scale down to zero means paying setup time each time traffic returns. New deployments default to a minimum of 0 and a maximum of 1 instance, so set both to match your traffic.
Uploaded files are capped and short-lived. The client uploads local files up to 100 MiB, and uploaded files expire after 24 hours. Larger inputs, or files you want to keep using, need your own storage and a public URL.
Pricing and plan conditions
Replicate says you only pay for what you use, but the unit depends on the model. Most public models bill per second at the rate of the hardware they run on, and you pay only for the time your request takes; others bill per input and output, such as per image, per second of video or per token. Private models on dedicated hardware bill for all the time their instances are online, including setup and idle time. Fast booting fine-tunes are the exception and bill only active time.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Example public model | Listed price |
|---|---|
black-forest-labs/flux-1.1-pro | $0.04 per output image |
black-forest-labs/flux-dev | $0.025 per output image |
black-forest-labs/flux-schnell | $3.00 per thousand output images |
deepseek-ai/deepseek-r1 | $3.75 per million input tokens; $0.01 per thousand output tokens |
ideogram-ai/ideogram-v3-quality | $0.09 per output image |
recraft-ai/recraft-v3 | $0.04 per output image |
wavespeedai/wan-2.1-i2v-480p | $0.09 per second of output video |
wavespeedai/wan-2.1-i2v-720p | $0.25 per second of output video |
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Hardware | Price | Notes |
|---|---|---|
CPU (Small), cpu-small | $0.000025 per second ($0.09 per hour) | 1 CPU, 2GB RAM |
CPU, cpu | $0.000100 per second ($0.36 per hour) | 4 CPUs, 8GB RAM |
Nvidia T4, gpu-t4 | $0.000225 per second ($0.81 per hour) | 16GB GPU RAM |
Nvidia L40S, gpu-l40s and gpu-l40s-2x | 1x: $0.000975 per second ($3.51 per hour); 2x: $0.001950 per second ($7.02 per hour) | 48GB GPU RAM per GPU |
Nvidia A100 (80GB), gpu-a100-large and gpu-a100-large-2x | 1x: $0.001400 per second ($5.04 per hour); 2x: $0.002800 per second ($10.08 per hour) | 80GB GPU RAM per GPU |
Nvidia H100, gpu-h100 | $0.001525 per second ($5.49 per hour) | 80GB GPU RAM |
4x and 8x Nvidia A100 (80GB) | $0.005600 and $0.011200 per second ($20.16 and $40.32 per hour) | Additional multi-GPU A100 capacity is available with committed spend contracts. |
2x, 4x and 8x Nvidia H100 | $0.003050, $0.006100 and $0.012200 per second ($10.98, $21.96 and $43.92 per hour) | Additional multi-GPU H100 capacity is available with committed spend contracts. |
Nvidia H200: 1x, 2x, 4x and 8x | $0.001525, $0.003050, $0.006100 and $0.012200 per second ($5.49, $10.98, $21.96 and $43.92 per hour) | H200 capacity is available with committed spend contracts. |
4x and 8x Nvidia L40S | $0.003900 and $0.007800 per second ($14.04 and $28.08 per hour) | Additional multi-GPU L40S capacity is available with committed spend contracts. |
For more support or complex needs, Replicate offers a dedicated account manager, priority support, higher GPU limits, performance SLAs, and help with onboarding, custom models and optimizations. It also offers volume discounts for large amounts of spend.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
0 GitHub commits 90d598 GitHub stars0 vulnerabilities across 2 packages
See all signals from 6 sources
npm · replicate@1.4.0 · PyPI · replicate@1.0.7
Alternatives to Replicate
The reviewed substitutes for Replicate among the model hosting platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Fireworks AI
- Two model hosting services running open models behind an API for the same inference workload. They are compared on latency, model coverage and price per token, and a team routes its traffic to one.Applies to: Choosing where open models are hosted and served for inference.
- Together AI
- Together AI and Replicate are cloud services where developers call open-source AI models by API instead of hosting them on their own GPUs. Together AI focuses on language models with serverless inference, fine-tuning and dedicated GPU clusters, while Replicate covers a wide range of image, audio, video and language models and deploys any Python model packaged with Cog.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Hugging Face
- Hugging Face and Replicate both give developers hosted access to open-source AI models, so either can run the model layer of a stack. Hugging Face is the main hub for open models, datasets and demo apps and offers inference on top of it, while Replicate is a cloud platform that runs image, language, audio and video models behind a simple HTTP API. The pick depends on whether the stack starts from the model hub or from a ready-to-call API.Applies to: When a developer wants hosted inference on open-source models through an API.
- Ollama
- Replicate is used rather than Ollama for bursty or long-running generation workloads that are not chat-shaped. **Replicate** bills per second of compute rather than per token, with published hardware rates from CPU up through GPU tiers.
- vLLM
- The same self-hosted-against-managed fork, at the shallow end. The 2026 guidance is blunt about where Replicate belongs -- use it for prototypes or low-volume workloads where setup speed matters more than unit economics -- which is precisely the condition under which not running vLLM is the right call. Past that the economics invert: a single T4 has to sustain roughly 500-750 tokens a second around the clock to match managed per-token pricing, and sustained volume above 1-2 billion tokens a month on one GPU is where self-hosting pays.Applies to: Getting an open-weight model behind an API. Replicate stands in for vLLM while the work is a prototype or low volume and setup speed decides; vLLM stands in once volume is sustained, the GPUs exist, or the data cannot leave.
- Anyscale
- Both host and serve open models by API; Replicate is pay-per-second inference, Anyscale is a managed Ray cluster.Applies to: Serving open models by API without operating the GPU fleet.
- LocalAI
- Replicate is used rather than LocalAI for image, video, and audio generation workloads billed by compute second rather than by token. **Replicate** bills per second of compute rather than per token, with published hardware rates from CPU through GPU tiers.
- Modal
- Modal is used rather than Replicate for programmable GPU jobs, custom model-serving code, and batch AI processing workloads. **Modal** is a serverless cloud platform for AI and ML workloads built around GPU containers, scheduled jobs, model serving, and batch processing.