Decision comparison
Replicate vs Together AI
Compare Replicate for managed image, video, audio and text models, and Together AI for the LLM serving and training workflow you need. Replicate uses hardware-time or input/output units and supports training for selected models. Most private Replicate hardware deployments bill setup and idle time, so bursty traffic alone does not establish savings. Compare model support, complete rates and deployment requirements.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
All 2 are model hosting platforms.
Quick Comparison
| Decision factor | Replicate | Together AI |
|---|---|---|
| Billing Model | Hardware-time or input/output billing; CPU (Small) $0.09/hr and H100 $5.49/hr are hardware rates, not universal model prices | Token-based serverless pricing from $0.04/M to $3.00/M input tokens |
| Primary Focus | Multimodal inference marketplace covering image, video, audio, and language models | LLM inference optimization with dedicated endpoints and fine-tuning infrastructure |
| Fine-tuning | Training jobs for supported models; Cog deployment also accepts externally trained models | Native platform service from $3/M tokens with integrated training-to-serving pipeline |
| Pricing Range | Pay for what you use. Most models bill by run time at a per-second hardware rate; some bill by input and output. Hardware: CPU (Small) $0.09/hr, CPU $0.36/hr, Nvidia T4 $0.81/hr, L40S $3.51/hr, A100 (80GB) $5.04/hr, H100 $5.49/hr, 4x H100 $21.96/hr, 8x H100 $43.92/hr. Models: flux-schnell $3.00 per thousand output images, flux-1.1-pro $0.04 per output image, deepseek-r1 $3.75 per million input tokens, wan-2.1-i2v-480p $0.09 per second of output video. Volume discounts for large spend. Verified 2026-10-05 against https://replicate.com/pricing. | Pay as you go. Serverless inference is priced per 1M tokens by model, with separate input and output rates; paid chat models range from $0.04 input (Tev1 4B Experimental) to $3.00 input and $15.00 output (Kimi K3). Dedicated inference on demand: $5.49 per GPU per hour for NVIDIA HGX H100 and $8.99 for HGX B200; other GPUs and reserved capacity are quoted by sales. GPU clusters on demand from $3.99 per GPU per hour (H100). LoRA fine-tuning from $0.34 per 1M tokens (SFT), with a minimum charge per job from $4.00. Verified 2026-10-05 against https://www.together.ai/pricing. Together AI GPU Clusters on demand cost $3.99 per GPU-hour for NVIDIA HGX H100, $5.99 for HGX H200 and $8.19 for HGX B200. Code Sandbox is $0.0446 per vCPU-hour and $0.0149 per GiB RAM-hour, Code Interpreter is $0.03 per 60-minute session, and Shared Filesystem storage is $0.16 per GiB per month. Verified 2026-10-05 against https://www.together.ai/pricing. On Together AI serverless inference, Qwen3.7-Max costs $1.50 per 1M input tokens and $4.50 per 1M output tokens; gpt-oss-120B costs $0.15 input and $0.60 output. Verified 2026-10-05 against https://www.together.ai/pricing. |
| Model Ecosystem | Large community marketplace with diverse models across image, video, audio, and text | Curated selection of popular open-source LLMs optimized for throughput |
| Best For | Teams needing managed multimodal model APIs; compare model units and private deployment online time | Teams focused on LLM workloads needing predictable token-based pricing and fine-tuning |
Replicate
- Billing Model:
- Hardware-time or input/output billing; CPU (Small) $0.09/hr and H100 $5.49/hr are hardware rates, not universal model prices
- Primary Focus:
- Multimodal inference marketplace covering image, video, audio, and language models
- Fine-tuning:
- Training jobs for supported models; Cog deployment also accepts externally trained models
- Pricing Range:
- Pay for what you use. Most models bill by run time at a per-second hardware rate; some bill by input and output. Hardware: CPU (Small) $0.09/hr, CPU $0.36/hr, Nvidia T4 $0.81/hr, L40S $3.51/hr, A100 (80GB) $5.04/hr, H100 $5.49/hr, 4x H100 $21.96/hr, 8x H100 $43.92/hr. Models: flux-schnell $3.00 per thousand output images, flux-1.1-pro $0.04 per output image, deepseek-r1 $3.75 per million input tokens, wan-2.1-i2v-480p $0.09 per second of output video. Volume discounts for large spend. Verified 2026-10-05 against https://replicate.com/pricing.
- Model Ecosystem:
- Large community marketplace with diverse models across image, video, audio, and text
- Best For:
- Teams needing managed multimodal model APIs; compare model units and private deployment online time
Together AI
- Billing Model:
- Token-based serverless pricing from $0.04/M to $3.00/M input tokens
- Primary Focus:
- LLM inference optimization with dedicated endpoints and fine-tuning infrastructure
- Fine-tuning:
- Native platform service from $3/M tokens with integrated training-to-serving pipeline
- Pricing Range:
- Pay as you go. Serverless inference is priced per 1M tokens by model, with separate input and output rates; paid chat models range from $0.04 input (Tev1 4B Experimental) to $3.00 input and $15.00 output (Kimi K3). Dedicated inference on demand: $5.49 per GPU per hour for NVIDIA HGX H100 and $8.99 for HGX B200; other GPUs and reserved capacity are quoted by sales. GPU clusters on demand from $3.99 per GPU per hour (H100). LoRA fine-tuning from $0.34 per 1M tokens (SFT), with a minimum charge per job from $4.00. Verified 2026-10-05 against https://www.together.ai/pricing. Together AI GPU Clusters on demand cost $3.99 per GPU-hour for NVIDIA HGX H100, $5.99 for HGX H200 and $8.19 for HGX B200. Code Sandbox is $0.0446 per vCPU-hour and $0.0149 per GiB RAM-hour, Code Interpreter is $0.03 per 60-minute session, and Shared Filesystem storage is $0.16 per GiB per month. Verified 2026-10-05 against https://www.together.ai/pricing. On Together AI serverless inference, Qwen3.7-Max costs $1.50 per 1M input tokens and $4.50 per 1M output tokens; gpt-oss-120B costs $0.15 input and $0.60 output. Verified 2026-10-05 against https://www.together.ai/pricing.
- Model Ecosystem:
- Curated selection of popular open-source LLMs optimized for throughput
- Best For:
- Teams focused on LLM workloads needing predictable token-based pricing and fine-tuning
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Replicate | Together AI |
|---|---|---|
| GitHub commits, 90d(Developer adoption) | 0 | 337 |
| GitHub stars(Developer adoption) | 597 | 13 |
| Search interest(Market interest) | 1 | 11 |
| Hacker News mentions, 90d(Community interest) | 0 | 3 |
| npm weekly downloads(Developer adoption) | 773.5k | 90.7k |
| PyPI weekly downloads(Developer adoption) | 294.0k | 387.6k |
| Hugging Face downloads(Product adoption) | Not available | 24.0k |
| Hugging Face likes(Product adoption) | Not available | 2.4k |
As of November 16, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Replicate
November 16, 2026Package vulnerabilities
npm · replicate@1.4.0 · PyPI · replicate@1.0.7
0 vulnerabilities
across 2 packages
Repository security score
Not available
Together AI
November 16, 2026Package vulnerabilities
PyPI · together@3.1.1 · npm · together-ai@1.1.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Interface Preview
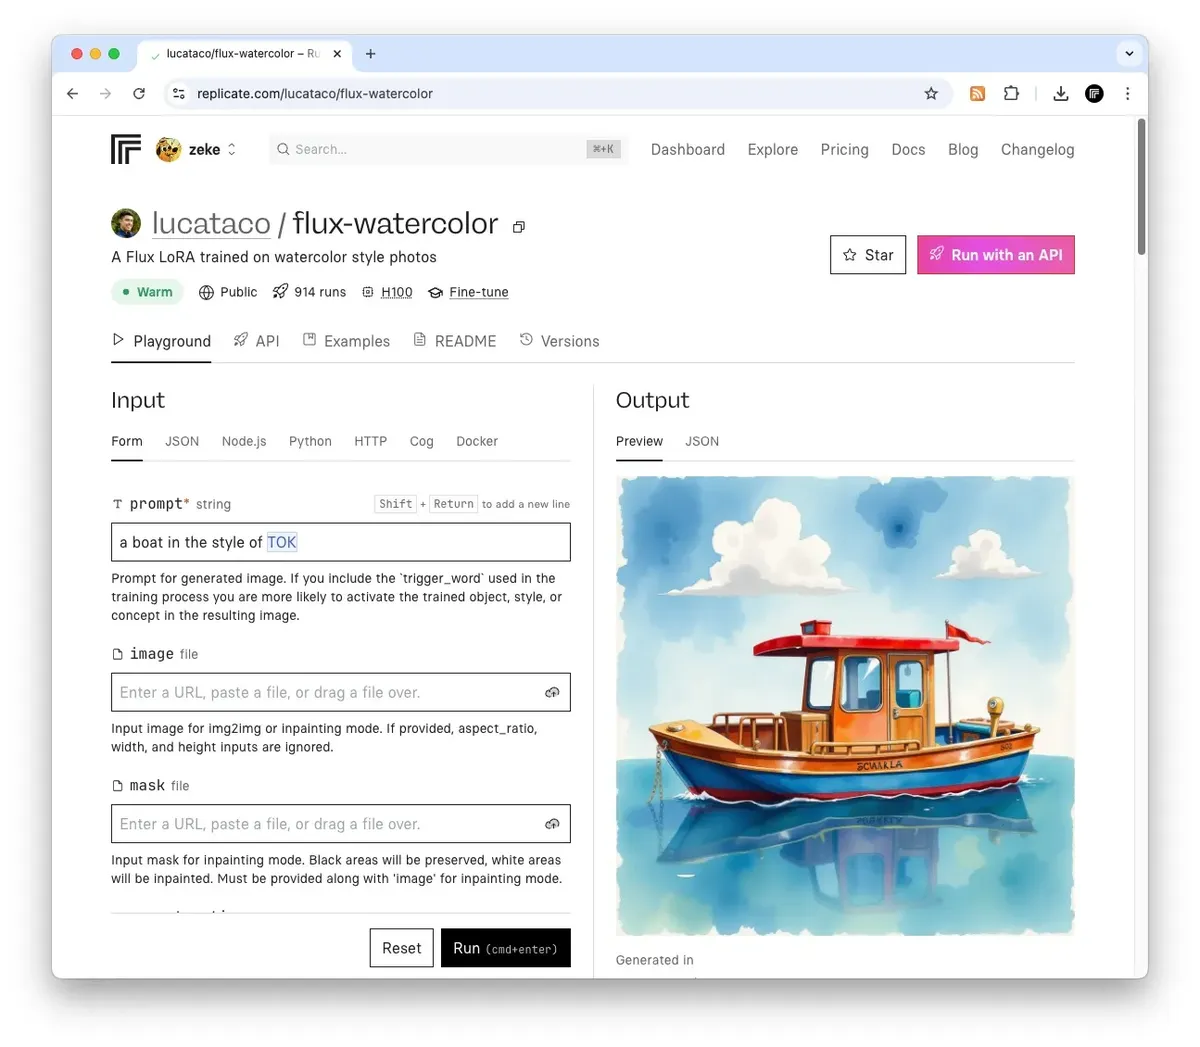
Replicate
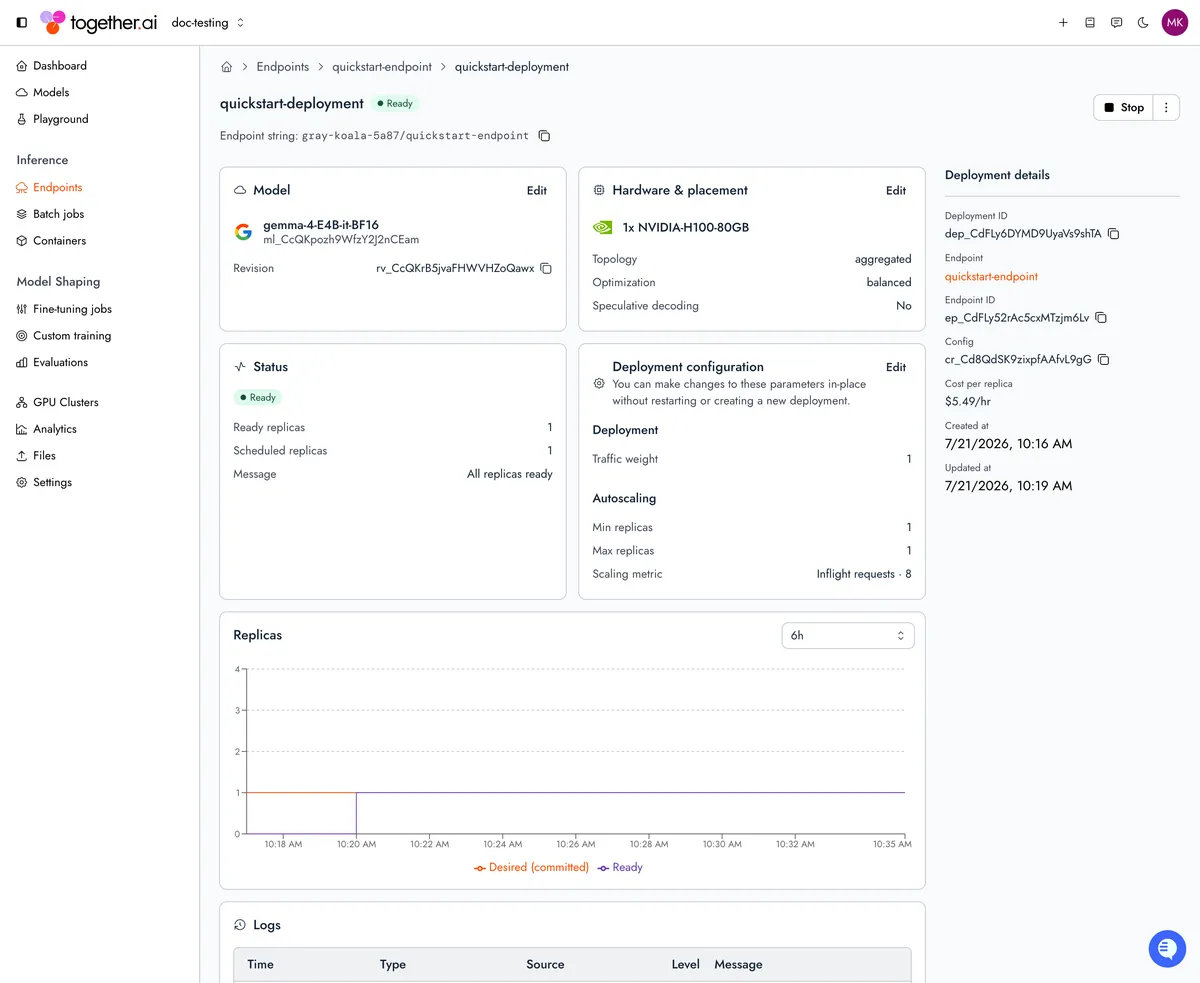
Together AI
Feature Comparison
| Feature | Replicate | Together AI |
|---|---|---|
| Inference Capabilities | ||
| LLM Inference | Available via API; DeepSeek R1 at $3.75/1M input tokens | Core platform strength with optimized throughput; $0.04-$3.00/M input tokens |
| Image Generation | Flux Schnell $0.003/image, Flux 1.1 Pro $0.04/image, SDXL and community models | Not a primary platform capability |
| Video Generation | Wan 2.1 480p at $0.09 per second of video output | Not available as a core offering |
| Audio Models | Whisper, MusicGen, and other community audio models | Not a primary modality |
| Infrastructure & Deployment | ||
| GPU Hardware Options | CPU, T4 ($0.81/hr), A100 ($5.04/hr), H100 ($5.49/hr), multi-GPU up to 8x H100 | A100 and H100 configurations; dedicated H100 at $5.49/GPU/hr |
| Custom Model Deployment | Cog containerization for packaging any ML model as an API | Upload and serve custom models on platform infrastructure |
| Dedicated Endpoints | Hardware-tier selection with per-second billing | Dedicated GPU clusters from $3.99/GPU/hour with guaranteed throughput |
| Auto-scaling | Scales to zero when idle; pay only for active compute seconds | Serverless endpoints auto-scale; dedicated endpoints require provisioning |
| Training & Customization | ||
| Fine-tuning | Training jobs for supported models; Cog deployment also accepts externally trained models | Native service from $3/M tokens with integrated training pipeline |
| Model Library | Large community marketplace with thousands of public models across modalities | Curated selection of popular open-source LLMs optimized for performance |
| Pricing & Access | ||
| Billing Model | Model-specific hardware-time or input/output billing; most private hardware deployments include setup and idle time | Per-token for serverless; per-GPU-hour for dedicated endpoints |
| Free Tier | Pay-as-you-go; check current trial eligibility rather than assuming free credits or first-call billing | Pay as you go |
| Enterprise Options | Volume discounts via committed spend agreements | Custom pricing for high-volume enterprise usage |
Inference Capabilities
LLM Inference
Image Generation
Video Generation
Audio Models
Infrastructure & Deployment
GPU Hardware Options
Custom Model Deployment
Dedicated Endpoints
Auto-scaling
Training & Customization
Fine-tuning
Model Library
Pricing & Access
Billing Model
Free Tier
Enterprise Options
Which to choose
Compare Replicate for managed image, video, audio and text models, and Together AI for the LLM serving and training workflow you need. Replicate uses hardware-time or input/output units and supports training for selected models. Most private Replicate hardware deployments bill setup and idle time, so bursty traffic alone does not establish savings. Compare model support, complete rates and deployment requirements.
Best-fit scenarios
Choose Replicate if:
Choose Replicate when its managed model catalog and Cog deployment fit your image, video, audio or text pipeline. FLUX Schnell is $0.003 per output image. Check each model's hardware-time or input/output units; most private hardware deployments bill setup and idle time. Measure your workload before choosing on cost.
Choose Together AI if:
Choose Together AI for high-volume LLM inference with predictable costs from $0.04 to $3.00/M input tokens, dedicated H100 endpoints at $5.49/GPU/hr for production latency requirements, and native fine-tuning from $0.34/M tokens. Token-based pricing makes it straightforward to evaluate and budget for text generation workloads.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Can I use Replicate for LLM inference, or is it only for image and video models?
Replicate supports token-priced LLM inference: DeepSeek R1 is $3.75 per million input tokens plus $0.01 per thousand output tokens. Other models use hardware-time billing. Compare the selected model's complete input/output rates or billable runtime rather than treating every Replicate LLM as billed per second.
How does per-second billing compare to per-token billing for cost predictability?
Both providers offer token-priced models. Estimate those with input and output token counts. For Replicate hardware-billed models, use measured runtime and the selected hardware rate; most private deployments also bill setup and idle time. Compare the same model and workload before judging cost or predictability.
Does Together AI support image or video generation like Replicate?
Together AI's platform is built primarily around large language model workloads. It does not position image or video generation as a core capability. Replicate offers dedicated image generation pricing (Flux Schnell at $0.003/image) and video generation (Wan 2.1 i2v 480p at $0.09 per output-video second). If multimodal AI is a significant part of your workflow, Replicate provides substantially more breadth.
Which platform is better for fine-tuning custom models?
Replicate supports training jobs for models with a Train tab, with results stored as versions in a training destination. Compare supported base models, training charges and serving requirements with Together AI's workflow; training is not available for every Replicate model, and there is no universal Replicate fine-tuning price.