Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Vespa states |
|---|---|
Deployment | Run your own Vespa instance from the GitHub repository, which holds all the code needed to build and run it, or deploy to the Vespa Cloud service |
Vespa Cloud hosting | Vespa-managed AWS and GCP accounts, or a data plane that runs entirely in customer-owned dedicated accounts |
Managed operations | On Vespa Cloud: node procurement, failover between regions, encryption at rest and in transit, automatic OS patches, and a team ready to act 24-7 if manual intervention is needed |
Release cadence | A new open-source release every morning CET, Monday through Thursday; Vespa Cloud applications get new platform versions automatically four times a week |
Community help | Vespa Slack community for questions and feedback, plus documentation and sample applications |
Our take
Choose Vespa if ranking quality is part of your product and you have engineers who will write and tune rank profiles and models. If you only need to store embeddings and run simple similarity lookups, a narrower vector store is likely enough, and Vespa's ranking and tensor model becomes work you do not need.
Evaluate Vespa
Comparisons
Where it stands out
One query over vectors, text and structured data. Documents can hold any number of vector fields, tensors for multi-chunk embeddings, positional text indexes with bm25 and stemming, and structured fields. A query can be any boolean combination of operators across all three, so hybrid search does not need a second system.
Machine-learned ranking near the data. Rank scores can be any function over tensors, hand-written or from ONNX or XGBoost models. The first and second ranking phases run locally where the data is stored, and a third phase runs after distributed results are matched. You can define any number of rank profiles, for example for bucket tests or markets.
Built for large, changing data. Vespa says it scales to billions of constantly changing data items and thousands of queries per second with latencies below 100 milliseconds. Content clusters grow by adding nodes for more data or groups of nodes for more traffic, and cluster sizes can change without stopping queries or writes.
Streaming search for personal data. For applications where each query touches only one user's small slice of data, Vespa offers a streaming search mode instead of building indexes. Vespa claims this delivers personal search 20x cheaper than with indexing; test that against your own data.
Named production users. Vespa's home page carries testimonials from Spotify, Yahoo, Elicit and Farfetch; Farfetch's engineer reports recommendations under 100ms. The project README says Vespa is used on several large internet services that serve hundreds of thousands of queries per second.
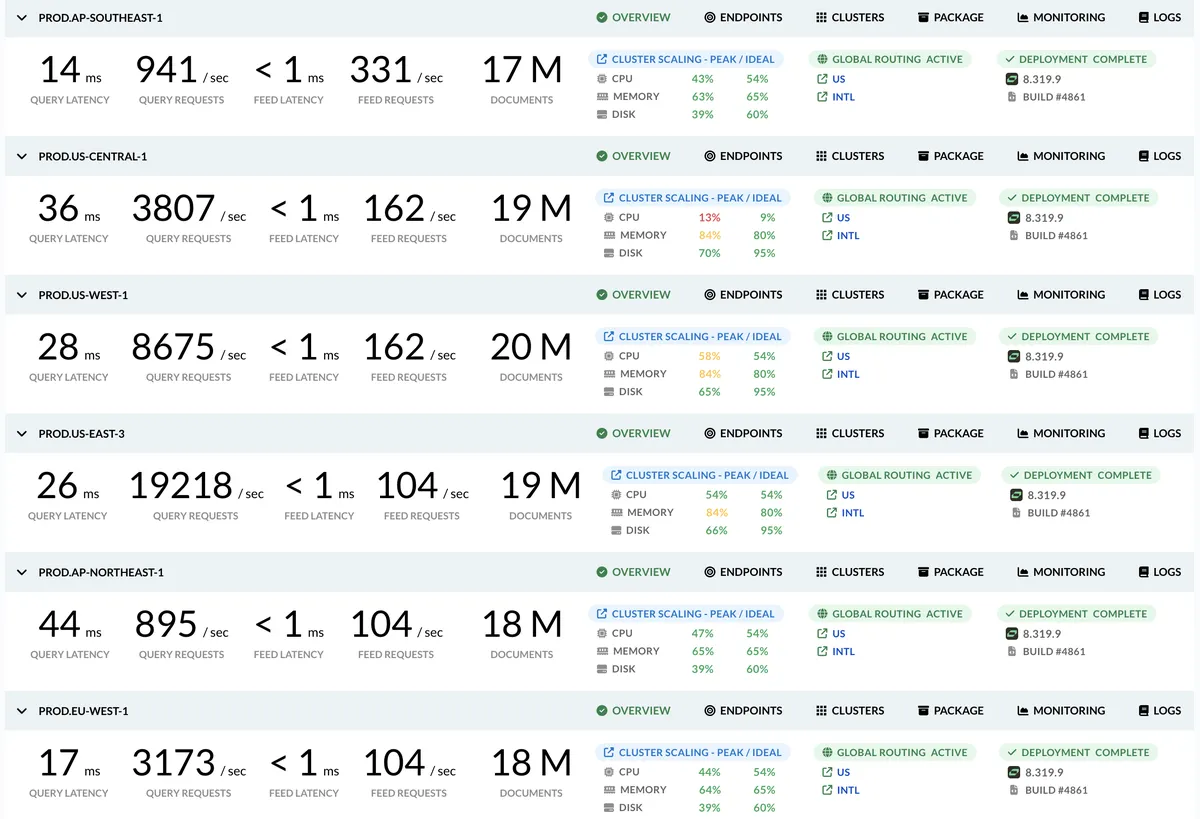
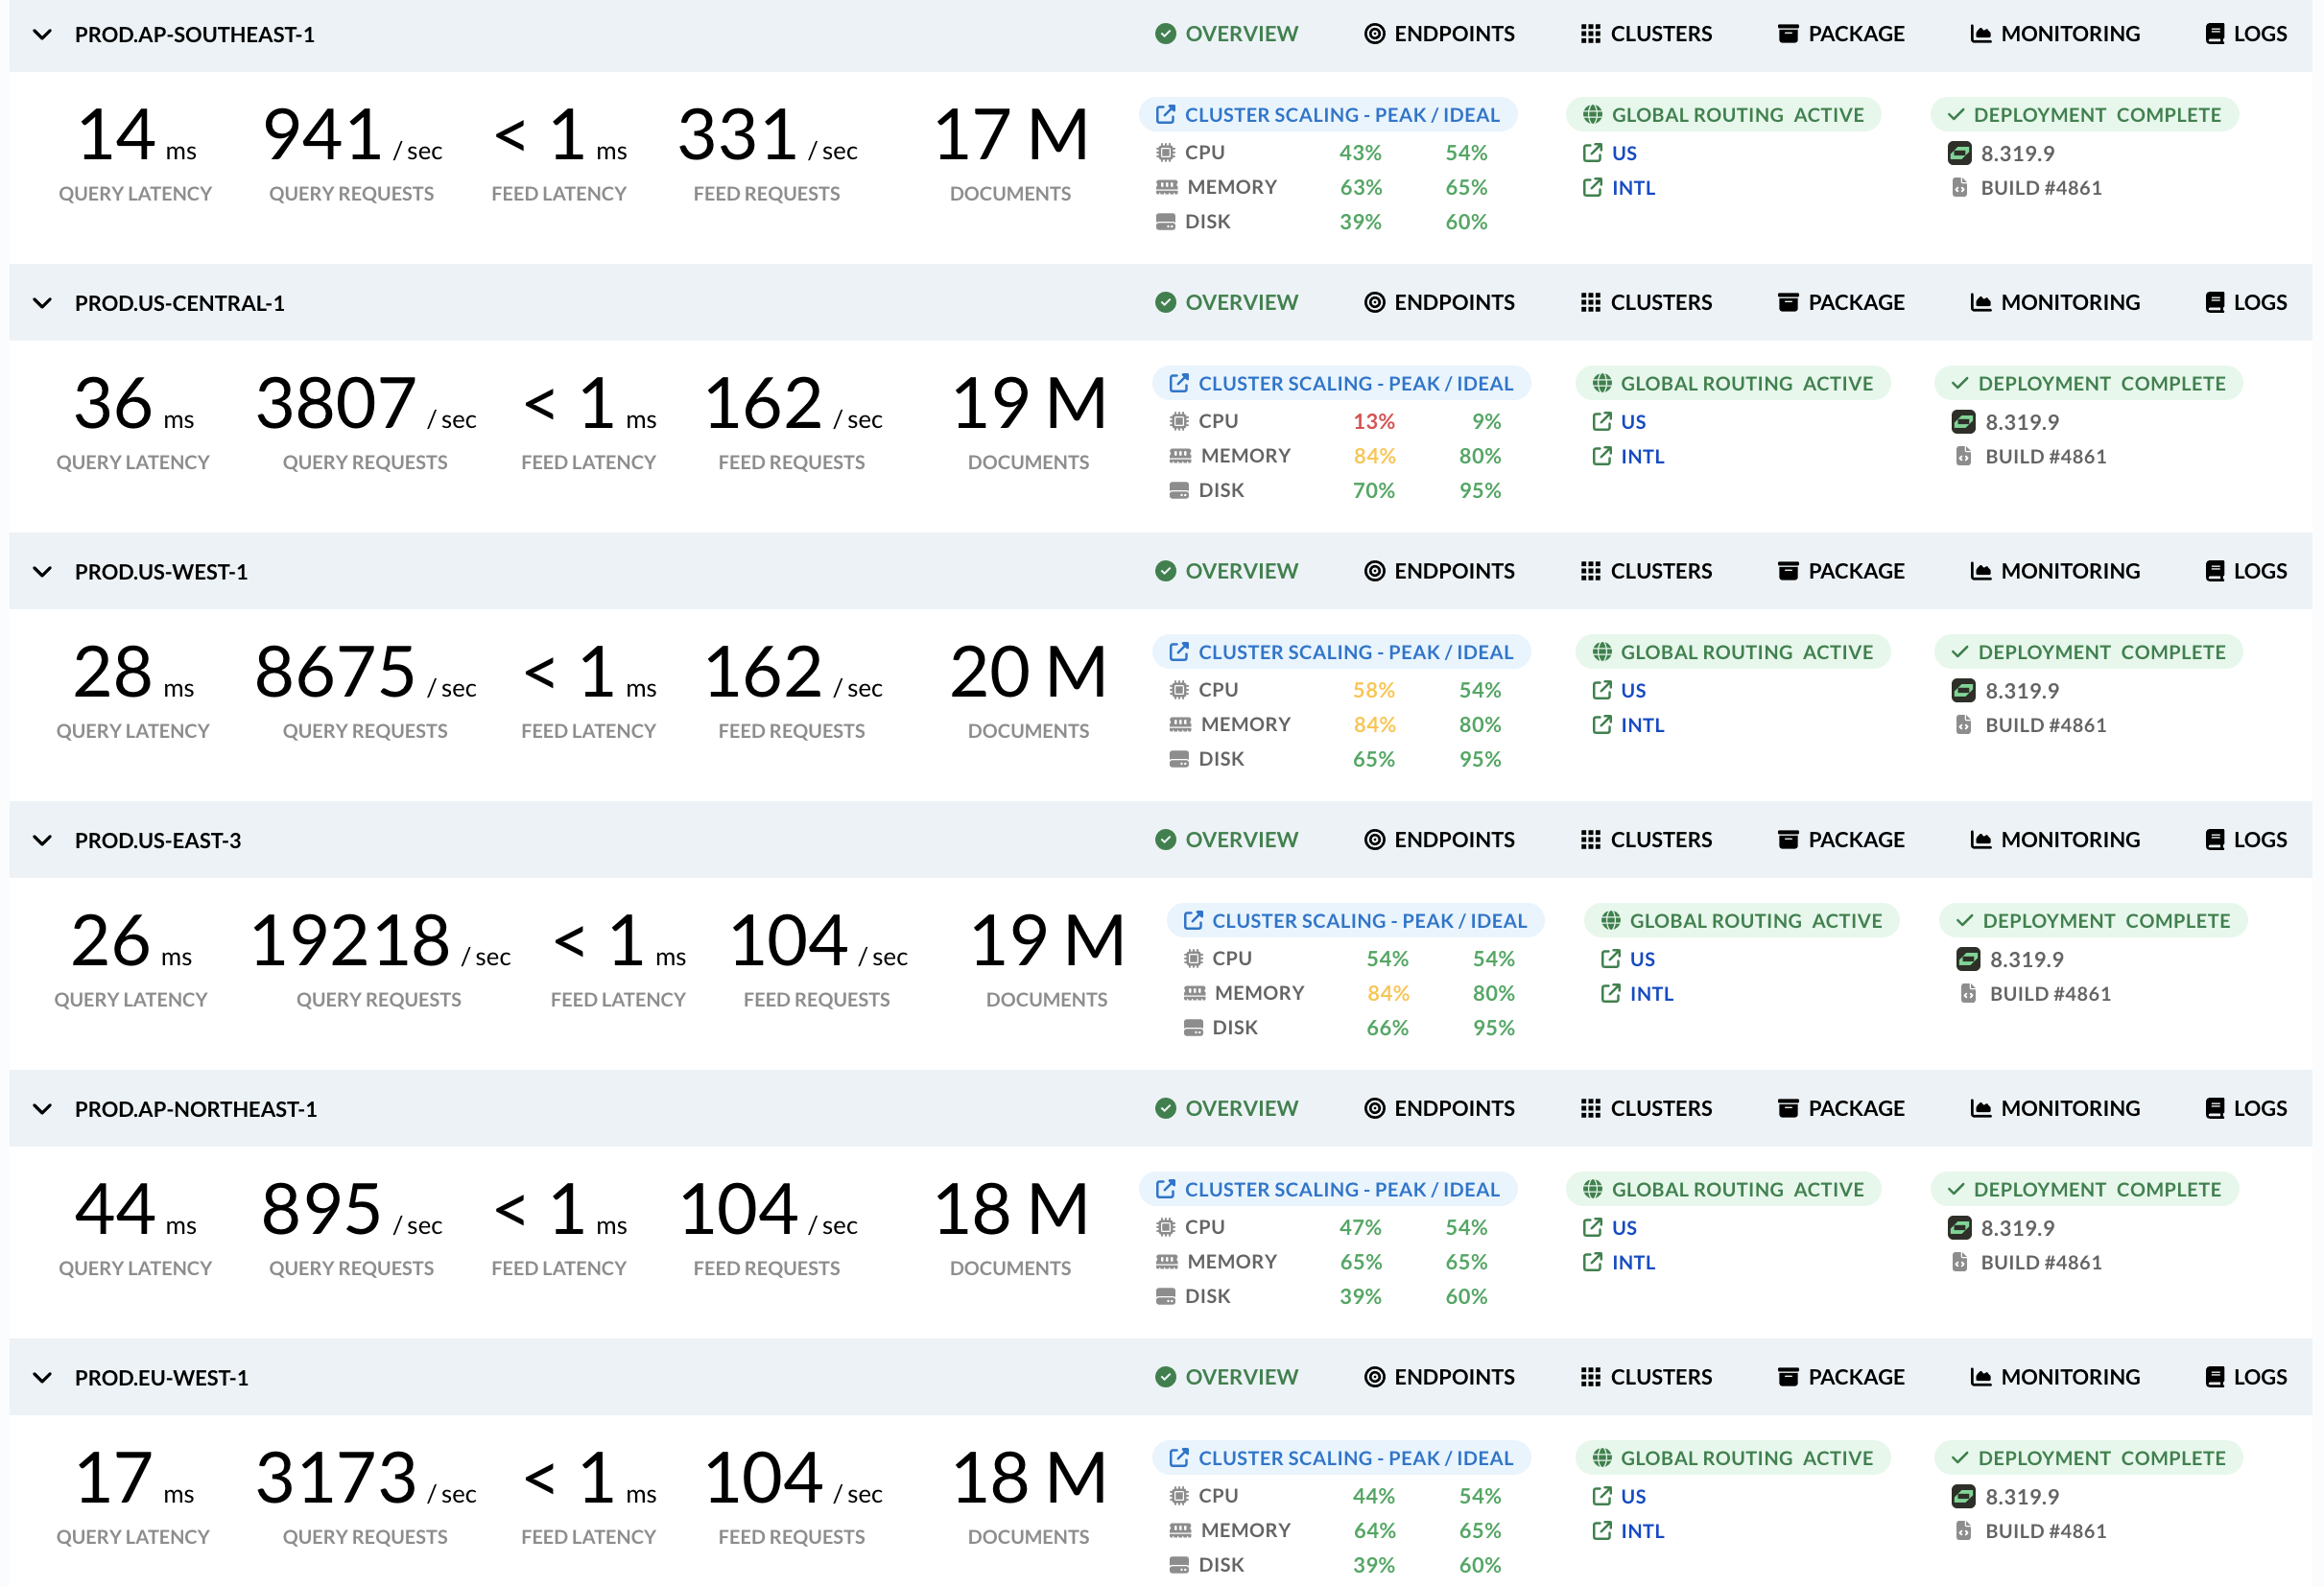
Product screenshot
Trade-offs to weigh
Relevance is your job. Rank profiles, tensor functions and multi-phase ranking give control, but someone has to design and maintain them. Teams that want a default similarity result with little tuning will carry concepts they do not use.
Self-hosting moves operations to you. Vespa's getting-started application is production-ready, but Vespa suggests adding more nodes for redundancy. Failover, patching and security hardening that Vespa Cloud handles become your team's work when you run your own instance.
Fast upgrade pace on Vespa Cloud. Automatic platform rollouts keep applications current, which Vespa ties to security. Teams that need to hold a fixed version for change control should confirm how this fits their process.
Contributing needs a specific toolchain. You do not need to build Vespa to use it. Building the C++ and Java code is supported on AlmaLinux 8; the Java code alone builds on any platform with Java 17 and Maven 3.8+.
Pricing and plan conditions
The choice is between paying for your own nodes and the people who run them, or paying for a managed service. Use the Vespa Cloud trial with your real data volume and query load before you compare the two.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Option | What Vespa states | What the buyer runs |
|---|---|---|
Self-hosted open source | Apache 2.0 license | Your own Vespa instance; add more nodes for redundancy |
Vespa Cloud | Free trial to run applications in the cloud | Managed service; cluster sizes and node resources can follow traffic and data size |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
2.1k GitHub commits 90d7.2k GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
PyPI · pyvespa@1.2.10
Alternatives to Vespa
The reviewed substitutes for Vespa among the search engines, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Milvus
- A dedicated vector store and a search engine with vector support both serve embedding retrieval. The decision is whether hybrid keyword and vector search in one engine is preferable to a purpose-built vector service, and both arrangements are common.Applies to: Whether embedding retrieval needs a dedicated vector store or a search engine that also does vectors.
- Pinecone
- A dedicated vector store and a search engine with vector support both serve embedding retrieval. The decision is whether hybrid keyword and vector search in one engine is preferable to a purpose-built vector service, and both arrangements are common.Applies to: Whether embedding retrieval needs a dedicated vector store or a search engine that also does vectors.
- Marqo
- Marqo optimises search conversion using click-stream, purchase and event data, creating a personalised experience that knows what your customers are looking for - better than they do.Applies to: For teams that build and operate their own ecommerce search and recommendations on a search platform.