Decision comparison
Databricks vs Tiger Data
Databricks is the clear choice for teams building unified analytics and AI platforms that span data engineering, ML, and BI workloads at enterprise scale. Timescale is purpose-built for time-series data on PostgreSQL and delivers superior performance for IoT, DevOps monitoring, and financial data workloads at a fraction of the cost.
Data Warehouses
Last Updated:
Quick Comparison
| Decision factor | Databricks | Tiger Data |
|---|---|---|
| Best For | Unified analytics and AI platform for data engineering, ML pipelines, and lakehouse workloads across AWS, Azure, and GCP | Time-series data workloads on PostgreSQL including IoT sensor data, DevOps metrics, and financial tick data |
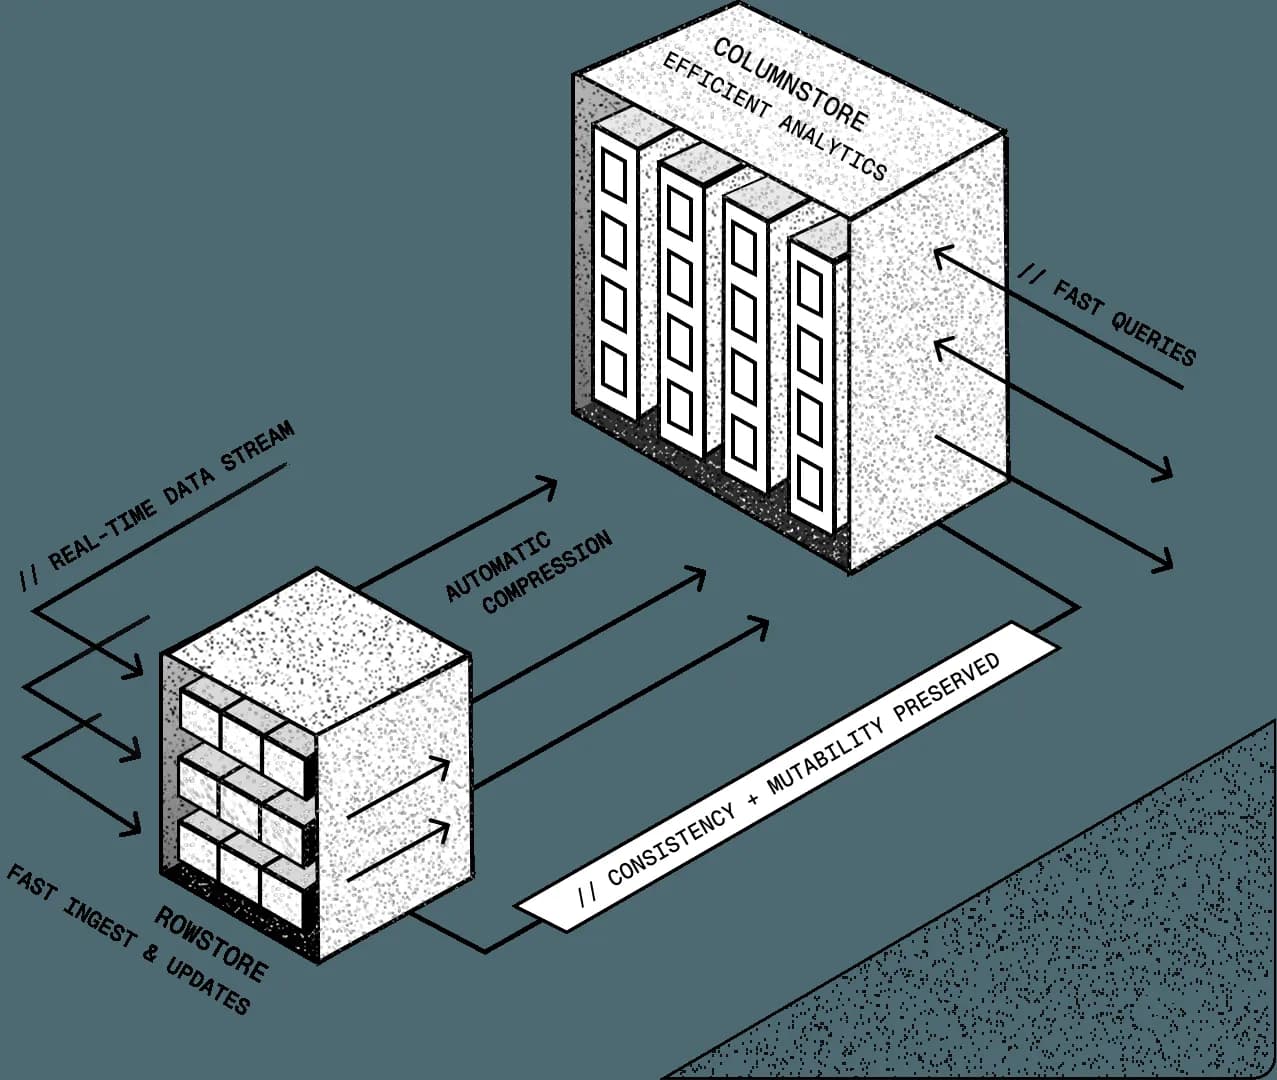
| Data Architecture | Lakehouse architecture combining data lake and warehouse on cloud object storage with Delta Lake ACID transactions | PostgreSQL-native with automatic hypertable partitioning, row-columnar hybrid storage, and up to 95% compression |
| Pricing Model | Standard $289/mo (5TB), Premium $1,499/mo (50TB). Free trial available. | Free tier (up to 10GB storage), Paid plans start at $29/mo |
| Query Language | Multi-language support with SQL, Python, Scala, and R through collaborative notebooks and managed Apache Spark | Standard PostgreSQL SQL with 200+ specialized time-series functions and full pgvector support for hybrid search |
| Scalability | Petabyte-scale processing with serverless SQL warehouses, auto-scaling clusters, and multi-cloud deployment options | Petabyte-scale time-series with independent storage and compute scaling, tiered storage to object storage, and read replicas |
| Security & Compliance | Unity Catalog governance, role-based access control, audit logging on Premium tier, and multi-cloud marketplace availability | SOC 2 Type II compliant, encryption at rest and in transit, private networking, and 99.9% uptime SLA |
Databricks
- Best For:
- Unified analytics and AI platform for data engineering, ML pipelines, and lakehouse workloads across AWS, Azure, and GCP
- Data Architecture:
- Lakehouse architecture combining data lake and warehouse on cloud object storage with Delta Lake ACID transactions
- Pricing Model:
- Standard $289/mo (5TB), Premium $1,499/mo (50TB). Free trial available.
- Query Language:
- Multi-language support with SQL, Python, Scala, and R through collaborative notebooks and managed Apache Spark
- Scalability:
- Petabyte-scale processing with serverless SQL warehouses, auto-scaling clusters, and multi-cloud deployment options
- Security & Compliance:
- Unity Catalog governance, role-based access control, audit logging on Premium tier, and multi-cloud marketplace availability
Tiger Data
- Best For:
- Time-series data workloads on PostgreSQL including IoT sensor data, DevOps metrics, and financial tick data
- Data Architecture:
- PostgreSQL-native with automatic hypertable partitioning, row-columnar hybrid storage, and up to 95% compression
- Pricing Model:
- Free tier (up to 10GB storage), Paid plans start at $29/mo
- Query Language:
- Standard PostgreSQL SQL with 200+ specialized time-series functions and full pgvector support for hybrid search
- Scalability:
- Petabyte-scale time-series with independent storage and compute scaling, tiered storage to object storage, and read replicas
- Security & Compliance:
- SOC 2 Type II compliant, encryption at rest and in transit, private networking, and 99.9% uptime SLA
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Databricks | Tiger Data |
|---|---|---|
| GitHub stars(Developer adoption) | 385 | 23,000+ |
| npm weekly downloads(Developer adoption) | 573.0k | Not available |
| Product Hunt comments(Community interest) | 5 | Not available |
| Product Hunt rating(Community interest) | 5.0/5 | Not available |
| Product Hunt reviews(Community interest) | 5 | Not available |
| Product Hunt votes(Community interest) | 91 | Not available |
| PyPI weekly downloads(Developer adoption) | 21.6M | Not available |
| Stack Overflow questions(Community interest) | 8.4k | Not available |
| GitHub commits, 90d(Developer adoption) | 699 | 380 |
| Hacker News mentions, 90d(Community interest) | 69 | Not available |
As of August 31, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Databricks
August 31, 2026Package vulnerabilities
npm · @databricks/sql@2.0.0 · PyPI · databricks-sdk@0.133.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Tiger Data
August 31, 2026Package vulnerabilities
Not available
Repository security score
github.com/timescale/timescaledb
5.8/10
Interface Preview
Tiger Data
Feature Comparison
| Feature | Databricks | Tiger Data |
|---|---|---|
| Data Storage & Architecture | ||
| Storage Format | Delta Lake with ACID transactions, schema evolution, and time travel on Parquet files in cloud object storage | PostgreSQL-native hypertables with row-columnar hybrid storage (Hypercore) and up to 95% native compression |
| Data Partitioning | Hive-style partitioning with Z-ordering and data skipping optimizations on Delta tables | Automatic time-based and key-based hypertable partitioning with partition skipping at query planning time |
| Tiered Storage | Cloud object storage (S3, ADLS, GCS) with compute separation and Delta Lake caching layer | Automatic tiering from hot SSD storage to low-cost object storage with full query access retained |
| Query & Analytics | ||
| SQL Engine | Databricks SQL endpoint with Delta Engine optimizations and serverless SQL warehouse option at $0.70/DBU | Full PostgreSQL SQL compatibility with 200+ specialized time-series hyperfunctions for time-based analytics |
| Real-Time Analytics | Structured Streaming on Apache Spark for batch and real-time data processing with Delta Live Tables | Continuous aggregates for incrementally refreshed rollups powering real-time dashboards without batch jobs |
| Search Capabilities | Full-text search through Spark SQL and integration with external search services | Native hybrid search combining BM25 keyword ranking with HNSW vector search (pgvectorscale) in PostgreSQL |
| Data Integration | ||
| ETL Pipelines | Delta Live Tables (DLT) for declarative ETL with end-to-end pipeline monitoring and automatic error remediation | Native Kafka and S3 ingestion connectors with SQL-based streaming into hypertables without external pipeline tools |
| Lakehouse Integration | Native lakehouse architecture with Delta Sharing for open data sharing and Databricks Marketplace | Tiger Lake for automatic synchronization of hypertables with Apache Iceberg tables in Amazon S3 |
| Ecosystem Connectors | Integrates with AWS, Azure, GCP ecosystems plus JDBC/ODBC drivers and Python, Node.js, Go SDKs | Full PostgreSQL ecosystem compatibility with native AWS MSK, RDS PostgreSQL, Aurora PostgreSQL, and S3 connectors |
| AI & Machine Learning | ||
| ML Tooling | Managed MLflow for experiment tracking, model serving, and Mosaic AI services with GPU cluster support | Not a primary focus; supports pgvector for embedding storage and vector similarity search within PostgreSQL |
| Notebook Environment | Collaborative notebooks supporting Python, SQL, Scala, and R with shared repos and dashboards | Not available; connects to external tools through standard PostgreSQL interfaces and SQL clients |
| AI Governance | Unity Catalog provides unified governance for data, analytics, and AI with lineage tracking and model registry | Not available; relies on PostgreSQL role-based access controls for data-level security |
| Operations & Reliability | ||
| High Availability | Multi-cloud deployment with auto-scaling clusters and serverless options; uptime depends on cloud provider SLA | 99.9% uptime SLA with replicated HA services, automated backups, and up to 14-day point-in-time recovery |
| Backup & Recovery | Relies on cloud-native backup mechanisms and Delta Lake time travel for data versioning and rollback | Automated backups via pgBackRest with weekly full backups, daily incrementals, and continuous WAL retention |
| Compliance | Enterprise tier provides audit logging, IP access lists, and customer-managed keys across all cloud providers | SOC 2 Type II certified, GDPR support, encryption at rest and in transit, and enterprise security standards |
Data Storage & Architecture
Storage Format
DatabricksDelta Lake with ACID transactions, schema evolution, and time travel on Parquet files in cloud object storage
Tiger DataPostgreSQL-native hypertables with row-columnar hybrid storage (Hypercore) and up to 95% native compression
Data Partitioning
DatabricksHive-style partitioning with Z-ordering and data skipping optimizations on Delta tables
Tiger DataAutomatic time-based and key-based hypertable partitioning with partition skipping at query planning time
Tiered Storage
DatabricksCloud object storage (S3, ADLS, GCS) with compute separation and Delta Lake caching layer
Tiger DataAutomatic tiering from hot SSD storage to low-cost object storage with full query access retained
Query & Analytics
SQL Engine
DatabricksDatabricks SQL endpoint with Delta Engine optimizations and serverless SQL warehouse option at $0.70/DBU
Tiger DataFull PostgreSQL SQL compatibility with 200+ specialized time-series hyperfunctions for time-based analytics
Real-Time Analytics
DatabricksStructured Streaming on Apache Spark for batch and real-time data processing with Delta Live Tables
Tiger DataContinuous aggregates for incrementally refreshed rollups powering real-time dashboards without batch jobs
Search Capabilities
DatabricksFull-text search through Spark SQL and integration with external search services
Tiger DataNative hybrid search combining BM25 keyword ranking with HNSW vector search (pgvectorscale) in PostgreSQL
Data Integration
ETL Pipelines
DatabricksDelta Live Tables (DLT) for declarative ETL with end-to-end pipeline monitoring and automatic error remediation
Tiger DataNative Kafka and S3 ingestion connectors with SQL-based streaming into hypertables without external pipeline tools
Lakehouse Integration
DatabricksNative lakehouse architecture with Delta Sharing for open data sharing and Databricks Marketplace
Tiger DataTiger Lake for automatic synchronization of hypertables with Apache Iceberg tables in Amazon S3
Ecosystem Connectors
DatabricksIntegrates with AWS, Azure, GCP ecosystems plus JDBC/ODBC drivers and Python, Node.js, Go SDKs
Tiger DataFull PostgreSQL ecosystem compatibility with native AWS MSK, RDS PostgreSQL, Aurora PostgreSQL, and S3 connectors
AI & Machine Learning
ML Tooling
DatabricksManaged MLflow for experiment tracking, model serving, and Mosaic AI services with GPU cluster support
Tiger DataNot a primary focus; supports pgvector for embedding storage and vector similarity search within PostgreSQL
Notebook Environment
DatabricksCollaborative notebooks supporting Python, SQL, Scala, and R with shared repos and dashboards
Tiger DataNot available; connects to external tools through standard PostgreSQL interfaces and SQL clients
AI Governance
DatabricksUnity Catalog provides unified governance for data, analytics, and AI with lineage tracking and model registry
Tiger DataNot available; relies on PostgreSQL role-based access controls for data-level security
Operations & Reliability
High Availability
DatabricksMulti-cloud deployment with auto-scaling clusters and serverless options; uptime depends on cloud provider SLA
Tiger Data99.9% uptime SLA with replicated HA services, automated backups, and up to 14-day point-in-time recovery
Backup & Recovery
DatabricksRelies on cloud-native backup mechanisms and Delta Lake time travel for data versioning and rollback
Tiger DataAutomated backups via pgBackRest with weekly full backups, daily incrementals, and continuous WAL retention
Compliance
DatabricksEnterprise tier provides audit logging, IP access lists, and customer-managed keys across all cloud providers
Tiger DataSOC 2 Type II certified, GDPR support, encryption at rest and in transit, and enterprise security standards
Decision Summary
Databricks is the clear choice for teams building unified analytics and AI platforms that span data engineering, ML, and BI workloads at enterprise scale. Timescale is purpose-built for time-series data on PostgreSQL and delivers superior performance for IoT, DevOps monitoring, and financial data workloads at a fraction of the cost.
Best-fit scenarios
Choose Databricks if:
Choose Databricks when your organization needs a unified platform for data engineering, machine learning, and business intelligence across multiple cloud providers. Databricks excels at processing diverse workloads including ETL pipelines via Delta Live Tables, collaborative data science in multi-language notebooks, and AI model development with managed MLflow and Mosaic AI. Teams running complex Spark-based transformations, building lakehouse architectures with Delta Lake, or deploying production ML models will benefit from the integrated platform. The consumption-based pricing starting at $0.07/DBU for model serving and $0.15/DBU for jobs compute makes it cost-effective for batch processing, though total costs including cloud infrastructure typically range from $500 to $8,000+ per month for mid-size teams.
Choose Tiger Data if:
Choose Tiger Cloud for applications that need time-series, real-time analytics, events, vector search, or keyword search on Postgres. Its Performance plan is for new applications and internal tools and includes up to four database services, with up to 8 CPU, 32 GB memory, and 16 TB disk storage per service. Billing is consumption-based: compute is metered hourly and starts at $30 per month, while storage is priced at $0.177 per GB-month. The supplied pricing evidence also offers a 30-day Performance-plan trial with no credit card required. Confirm the workload-specific compute configuration and any charges for add-ons such as high-availability replicas, IO boost, tiered storage, or production support.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Can Databricks handle time-series data like Timescale does?
Databricks can process time-series data using Apache Spark and Delta Lake, but it lacks the specialized optimizations that Timescale provides. Timescale offers automatic time-based hypertable partitioning, 200+ purpose-built time-series SQL functions, continuous aggregates for real-time dashboards, and up to 95% native compression. In Databricks, you would need to manually configure partitioning strategies, write custom windowing logic, and manage data lifecycle policies. For dedicated time-series workloads like IoT monitoring or financial data analysis, Timescale delivers quick query performance and reduced operational overhead because the database is designed specifically for temporal data patterns.
How do the pricing models compare for a mid-size data team?
The supplied evidence documents Tiger Cloud's consumption pricing but does not provide Databricks pricing, so a like-for-like mid-size team cost comparison cannot be made. Tiger Cloud meters compute hourly and storage based on average GB consumption per hour. Performance compute starts at $30/month with storage priced at $0.177/GB-month, while Scale compute starts at $36/month with storage priced at $0.212/GB-month. Buyers should confirm their compute configuration, actual storage use, and any add-on charges, such as HA replicas, IO boost, tiered storage, and production support.
Can I use standard SQL with both platforms?
Both platforms support SQL, but the experience differs significantly. Timescale is built on 100% unforked PostgreSQL, so any standard PostgreSQL query, tool, or driver works without modification. It adds 200+ time-series-specific SQL functions on top. Databricks provides SQL through its Databricks SQL endpoint and Delta Engine, which supports ANSI SQL but runs on Apache Spark under the hood. Databricks also supports Python, Scala, and R in collaborative notebooks for workloads that go beyond SQL. If your team primarily works in SQL and uses the PostgreSQL ecosystem of tools, Timescale provides a more familiar and seamless experience. If you need multi-language support for complex data engineering and ML tasks, Databricks offers broader flexibility.
Which platform is better for real-time analytics and dashboards?
For time-series real-time analytics, Timescale has a clear advantage with continuous aggregates that incrementally refresh materialized views, delivering instant dashboard performance without batch jobs. It also offers native hybrid search combining BM25 keyword ranking with vector search in a single query. Databricks handles real-time data through Structured Streaming on Apache Spark and Delta Live Tables for continuous ETL pipelines, which is more suited to complex multi-source data processing. Timescale processes trillions of metrics daily (as documented by their customers) with sub-second query latency on PostgreSQL. Databricks is better when you need to combine real-time streaming with machine learning inference or process data from many heterogeneous sources simultaneously.