Decision comparison
Imply Cloud vs StarRocks
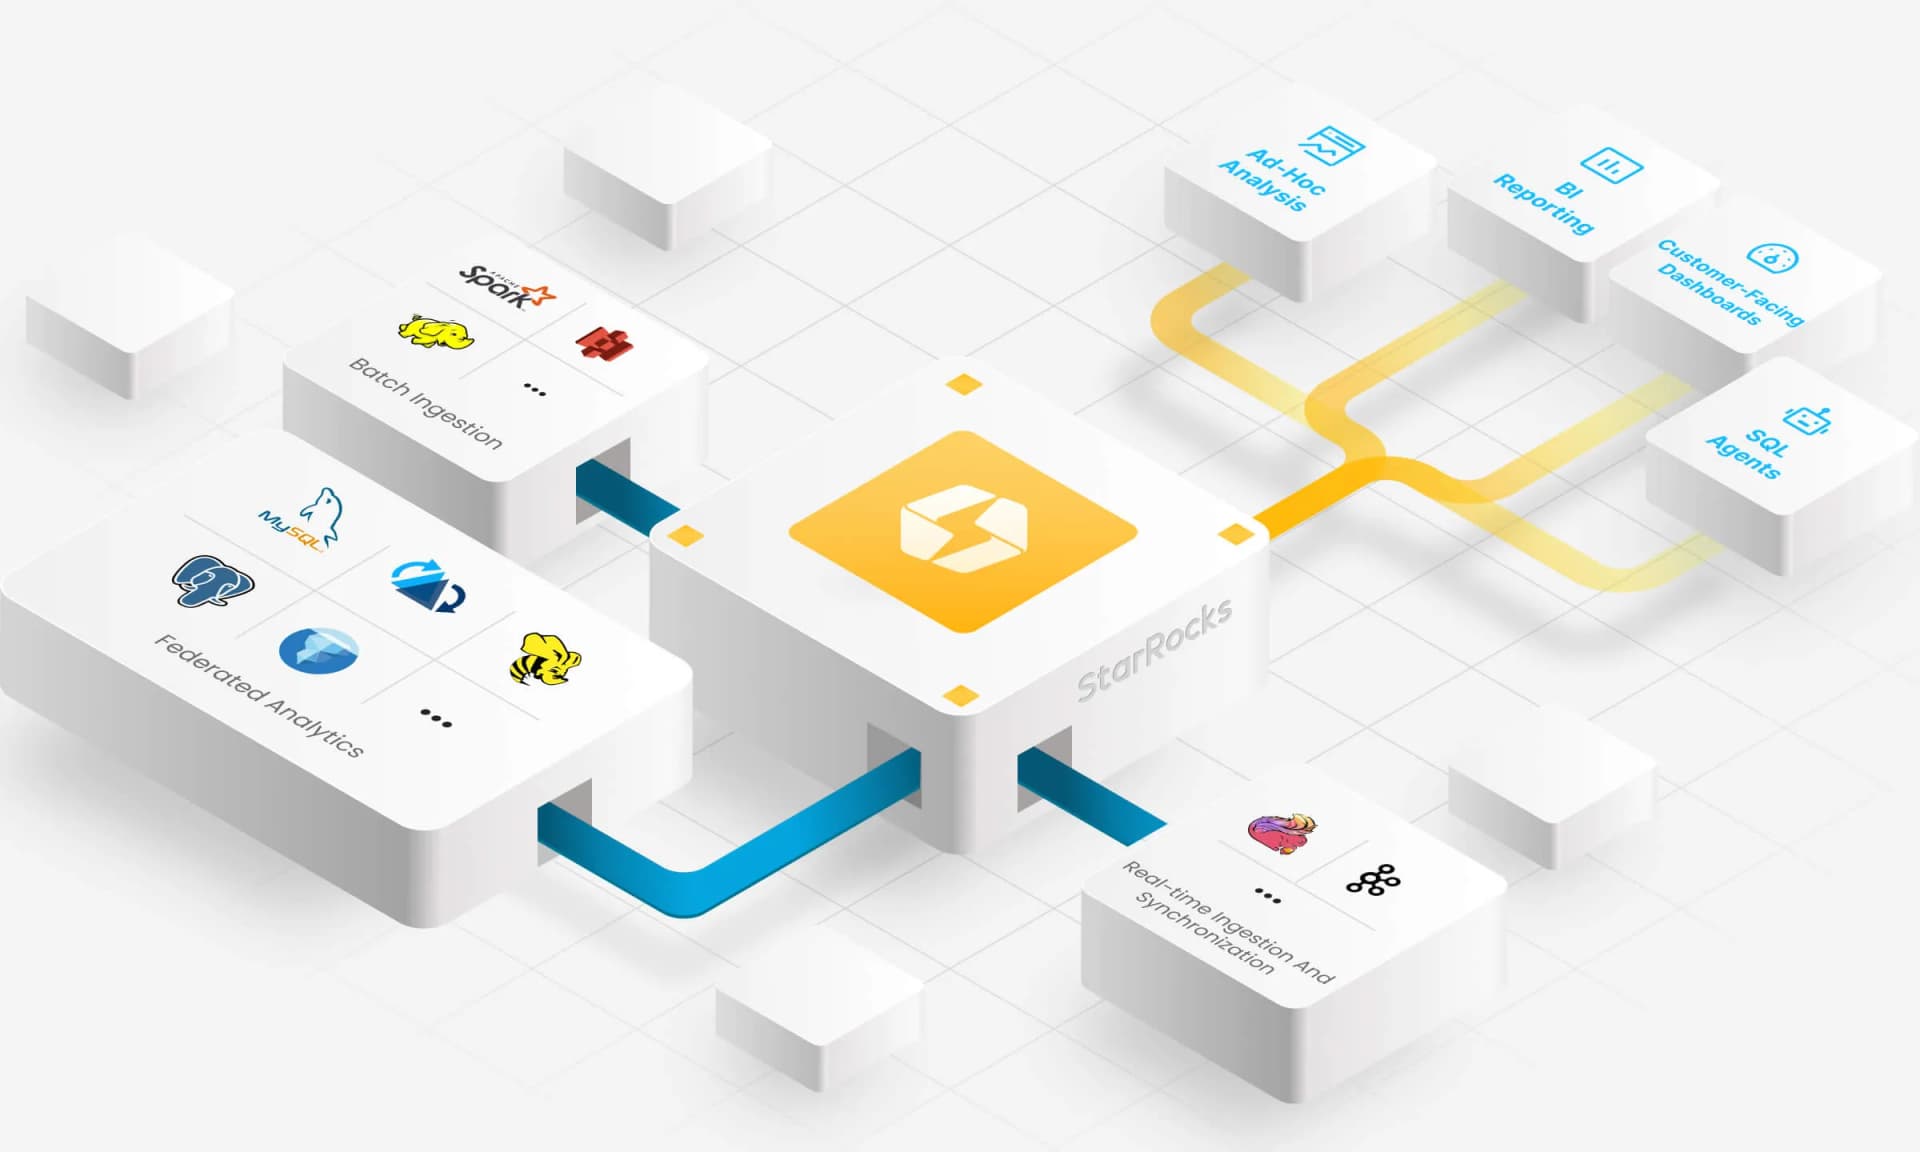
Imply and StarRocks both answer analytical queries in under a second, and they assume different data models. Imply, built on Apache Druid, is optimised for denormalised event data with rollup and high concurrency, delivered as a managed platform with support. StarRocks joins tables at query time, speaks the MySQL protocol and queries Iceberg, Hudi and Delta Lake tables in place.
Architecture choice. These take different approaches to the same problem. Read the table as a fit question rather than a feature race.
All 2 are OLAP databases.
Quick Comparison
| Decision factor | Imply Cloud | StarRocks |
|---|---|---|
| What it is | A commercial platform built on Apache Druid by the team behind it, available as a managed service or supported in your own environment | An open-source MPP analytical database with fast joins, a MySQL-compatible interface and direct lakehouse querying |
| Query shape | Optimised for aggregation over event data with high concurrency | Handles aggregation and multi-table joins, including joins at query time rather than pre-joined tables |
| Data model | Denormalised event data, with rollup at ingestion | Star and snowflake schemas work directly, so denormalisation is optional |
| Lakehouse | Ingests into its own segment storage | Queries Iceberg, Hudi, Delta Lake and Hive tables in place, as well as its own storage |
| Interface | SQL plus Pivot, an analytical interface built for time series exploration | MySQL wire protocol, so existing MySQL clients and BI tools connect |
| Who runs it | Imply runs the cluster in its managed form, or supports your own deployment | You do, unless you buy a managed service from a provider |
| Best fit | High-concurrency event analytics where operations should be someone else's job | Teams needing joins and lakehouse access alongside real-time analytics |
Imply Cloud
- What it is:
- A commercial platform built on Apache Druid by the team behind it, available as a managed service or supported in your own environment
- Query shape:
- Optimised for aggregation over event data with high concurrency
- Data model:
- Denormalised event data, with rollup at ingestion
- Lakehouse:
- Ingests into its own segment storage
- Interface:
- SQL plus Pivot, an analytical interface built for time series exploration
- Who runs it:
- Imply runs the cluster in its managed form, or supports your own deployment
- Best fit:
- High-concurrency event analytics where operations should be someone else's job
StarRocks
- What it is:
- An open-source MPP analytical database with fast joins, a MySQL-compatible interface and direct lakehouse querying
- Query shape:
- Handles aggregation and multi-table joins, including joins at query time rather than pre-joined tables
- Data model:
- Star and snowflake schemas work directly, so denormalisation is optional
- Lakehouse:
- Queries Iceberg, Hudi, Delta Lake and Hive tables in place, as well as its own storage
- Interface:
- MySQL wire protocol, so existing MySQL clients and BI tools connect
- Who runs it:
- You do, unless you buy a managed service from a provider
- Best fit:
- Teams needing joins and lakehouse access alongside real-time analytics
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Imply Cloud | StarRocks |
|---|---|---|
| GitHub commits, 90d(Developer adoption) | 0 | Not available |
| GitHub stars(Developer adoption) | 0 | Not available |
| Search interest(Market interest) | Unavailable | 1 |
| Hacker News mentions, 90d(Community interest) | 0 | 0 |
| Docker Hub pulls(Product adoption) | Not available | 906.6k |
| GitHub commits, 90d(Product adoption) | Not available | 1.3k |
| GitHub stars(Product adoption) | Not available | 12,000+ |
| Product Hunt comments(Community interest) | Not available | 0 |
| Product Hunt reviews(Community interest) | Not available | 0 |
| Product Hunt votes(Community interest) | Not available | 2 |
| PyPI weekly downloads(Developer adoption) | Not available | 131.3k |
| Stack Overflow questions(Community interest) | Not available | 11 |
As of September 21, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Imply Cloud
Package vulnerabilities
Not available
Repository security score
Not available
StarRocks
September 21, 2026Package vulnerabilities
PyPI · starrocks@1.3.4
0 vulnerabilities
across 1 package
Repository security score
Not available
Interface Preview
StarRocks
Feature Comparison
| Feature | Imply Cloud | StarRocks |
|---|---|---|
| Query | ||
| Sub-second aggregation over large datasets | Full support | Full support |
| Fast multi-table joins | Partial support | Full support |
| Real-time ingestion from Kafka | Full support | Full support |
| High concurrency | Full support | Full support |
| Data access | ||
| Query Iceberg and Delta Lake tables in place | Not verified | Full support |
| MySQL protocol compatibility | Not verified | Full support |
| Rollup or pre-aggregation at ingestion | Full support | Full support |
| Record-level updates | Partial support | Full support |
| Operations | ||
| Managed service from the vendor | Full support | Partial support |
| Self-hosted deployment | Full support | Full support |
| Commercial support | Full support | Partial support |
| Automated cluster management | Full support | Partial support |
| Platform | ||
| Open source engine | Full support | Full support |
| Object storage for older data | Full support | Full support |
| Purpose-built analytical interface | Full support | Not verified |
| Standard BI tool connectivity | Full support | Full support |
Query
Sub-second aggregation over large datasets
Fast multi-table joins
Real-time ingestion from Kafka
High concurrency
Data access
Query Iceberg and Delta Lake tables in place
MySQL protocol compatibility
Rollup or pre-aggregation at ingestion
Record-level updates
Operations
Managed service from the vendor
Self-hosted deployment
Commercial support
Automated cluster management
Platform
Open source engine
Object storage for older data
Purpose-built analytical interface
Standard BI tool connectivity
Which approach fits
Imply and StarRocks both answer analytical queries in under a second, and they assume different data models. Imply, built on Apache Druid, is optimised for denormalised event data with rollup and high concurrency, delivered as a managed platform with support. StarRocks joins tables at query time, speaks the MySQL protocol and queries Iceberg, Hudi and Delta Lake tables in place.
When each approach fits
Choose Imply Cloud if:
Choose Imply when the workload is high-concurrency aggregation over event data and you want the cluster operated for you. Rollup at ingestion reduces what is stored and scanned, the managed service removes segment management and upgrades, Pivot suits exploratory analysis of high-cardinality time series, and support comes from the engine's own developers.
Choose StarRocks if:
Choose StarRocks when your data is not naturally one wide table. Joining dimension tables at query time means you keep a normalised model instead of denormalising at ingestion, MySQL protocol compatibility lets existing clients and BI tools connect, and querying Iceberg, Hudi and Delta Lake in place avoids copying lake data into another store.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
What kind of workload are these built for?
Sub-second aggregation over large volumes of event data, answered for many concurrent users — the shape of user-facing analytics, operational dashboards and real-time monitoring. None of them is a general-purpose warehouse, and none is built for complex joins across many large historical tables. If your queries are heavy multi-table joins over years of data, compare warehouses instead; these systems answer a different question.
Why does join performance matter here?
Because it decides how you model data. Systems optimised for denormalised event data expect one wide table, so dimension attributes are flattened in at ingestion. That is fast to query and painful when a dimension changes, since history has to be rewritten. A system with fast joins lets dimensions stay in their own tables and change independently, at the cost of work at query time.
What does querying the lake in place give us?
One less copy. If your data already sits in Iceberg or Delta Lake tables on S3, StarRocks can query it directly, so the analytical database serves recent hot data while historical data stays where it is. That reduces both storage duplication and the pipeline keeping a second copy current, which is a common source of quiet inconsistency.
How much does MySQL compatibility help?
It removes an integration step. Existing MySQL clients, drivers and many BI tools connect without a new connector, and engineers who know MySQL syntax are productive quickly. It does not make StarRocks a transactional database — the engine is columnar and analytical — but the wire protocol being familiar lowers the cost of adoption noticeably.
What does running either cluster involve?
Multiple node roles, a metadata layer, storage management, ingestion supervision from Kafka and capacity planning as volume grows. Both are distributed systems with real operational demands. Imply's managed service removes that for the Druid side; for StarRocks the equivalent means choosing a managed provider or staffing the operations yourself.
How do we control cost?
Keep recent data on fast storage and older data on object storage, and reduce what is scanned through rollup, pre-aggregation or materialised views. Ingestion method matters too: real-time ingestion from Kafka costs more in resources than batch loading the same volume, so data that does not need second-level freshness should not arrive that way.