Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Imply states |
|---|---|
Deployment | Fully managed Polaris service on AWS, with region choices of N. Virginia (us-east-1), Ohio (us-east-2), Oregon (us-west-2), Frankfurt (eu-central-1), Ireland (eu-west-1), Mumbai (ap-south-1) and Seoul (ap-northeast-2). |
Billing model | Pay-as-you-go plan with no upfront costs or annual commitments; usage is charged automatically to a credit card at the end of each month. |
Free trial | New signups get $500 in credits to use over 30 days on a Starter project or a Standard A.01 or D.04 project. No credit card is needed, and data ingestion and file storage are not charged during the trial. |
Data sources | Built-in connectors for Confluent Cloud, Kafka, Kinesis, S3 and more. All Polaris environments include unlimited data sources and auto-scalable ingestion. Polaris also integrates with third-party monitoring and visualization tools. |
Security | Authentication required for all users, with SSO support; role-based access control; AES-256 encryption for stored data and TLS 1.2 for data in transit. |
Support | Base support by default. Standard or Mission-critical support, with quicker response times, is an upgrade arranged through an Imply sales representative. |
Command line | polaris-cli creates and manages Imply SaaS resources, for example creating a table, uploading a file, creating a batch job and querying data. It requires Java 1.8+. |
Our take
Imply Cloud suits teams that want Druid's low-latency queries over streaming and batch data without running Druid clusters themselves, as long as they can size the data they keep in a project. Use the trial credits to ingest a sample of real data first: Imply itself recommends a trial to size data when you are unsure of your needs.
Evaluate Imply Cloud
Popular comparisons
See all 5 Imply Cloud comparisons
Where it stands out
Druid query design. Imply says Druid's scatter/gather engine reads only the relevant part of a data set and gives sub-second performance for most queries, even with data sets of multiple petabytes.
Hot and cold data. For performance-sensitive workloads, data is pre-loaded into local caches before queries run. Data that is not precached can stay in deep storage at a lower cost and be queried asynchronously.
Two project types per size. A-Series projects are compute optimized for sub-second queries and high concurrency; D-Series projects are for general-purpose use, balancing compute, memory and storage.
Pause and scale. You can scale a Polaris tier up or down at any time, and pause a project to reduce costs, then resume it quickly later.
Compression. Imply says Polaris typically compresses ingested data by more than 90%, which typically reduces the project size you need.
Included operations. Every Polaris environment includes high availability, built-in monitoring and alerts, performance monitoring and built-in monitoring visualization. Polaris also offers embedded visualizations for building analytical apps.
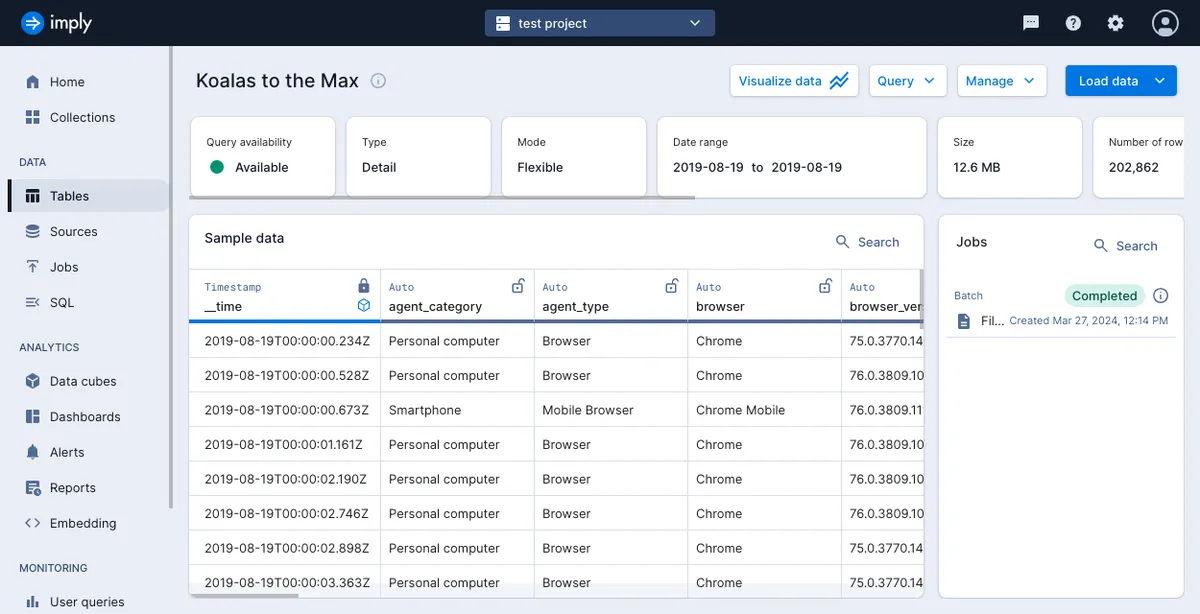
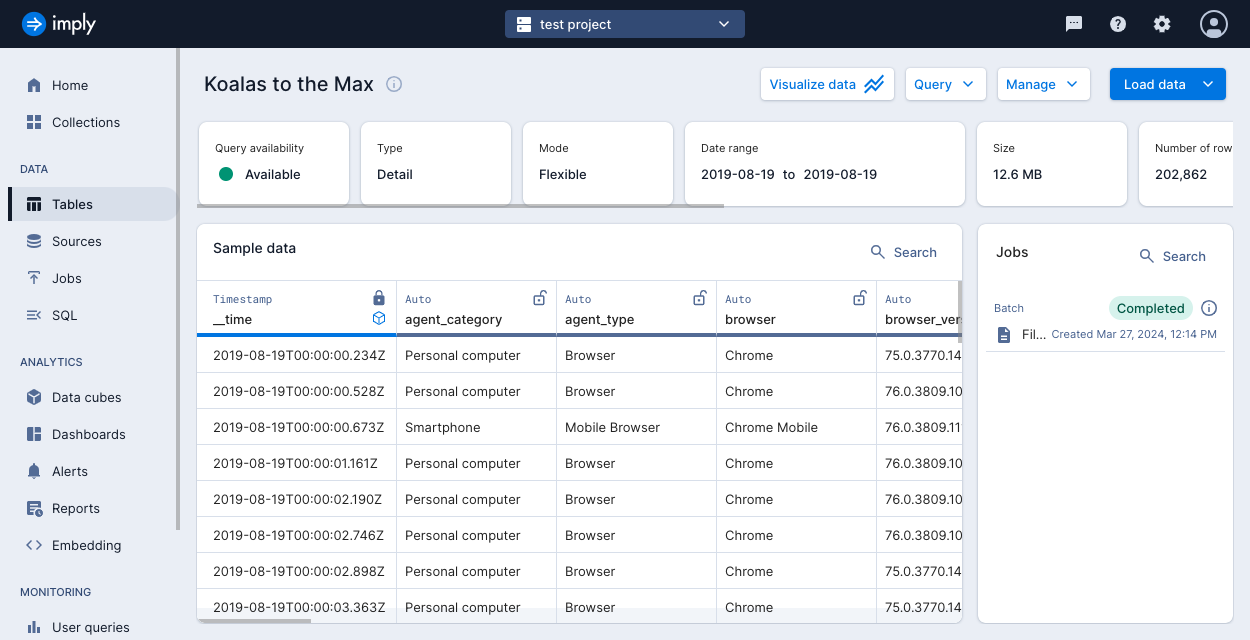
Product screenshot
Trade-offs to weigh
The project meter runs by the hour. The monthly bill is the tier's list price times the hours in the month, plus ingestion and file storage. Imply says pausing an idle project reduces costs, and because the bill multiplies the tier price by hours, a smaller tier also lowers it.
Compression does not shrink ingestion charges. Ingestion is billed on the raw bytes Polaris processes during ingestion and transformation, so the compression benefit applies to project size, not to the ingestion line.
Starter is for evaluation only. A Starter project offers 25 GB at variable performance, with a minimum of 4 vCPU and 16 GB RAM, and Imply strongly recommends against using it for performance testing or production.
Trial data has a deadline. After the trial expires you have 30 days to enter a credit card; if you do not, Imply deletes the organization and its data.
Large projects need a quote. Use cases above 10 TB capacity run on Custom projects, which require contacting Imply for sizing and pricing.
Pricing and plan conditions
Polaris follows a consumption-based model. Imply meters the selected tier per hour, batch and streaming data ingested per GB, and file storage per GB-month; async queries are billed per Data Processing Unit (DPU) minute. Rates vary by AWS region. Plan cards show starting monthly prices; the rate table below shows sample usage rates.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it includes |
|---|---|---|
Starter | Starts at $100/month | Small environment for proof-of-concept evaluations; project size limited to 25 GB; variable performance; free trial. |
Standard | Starts at $600/month | Production environments at two performance levels; project sizes up to 9.6 Terabytes; 99.9% uptime SLA; private networking options. |
Custom | Contact us for pricing | Highest-scale production environments; unlimited project size; 99.95% uptime SLA; highly customizable environment; scheduled upgrades. |
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Metered item | Rate | Conditions |
|---|---|---|
A.01 project | $1.30/hr | 100 GB capacity, 10 vCPU, 64 GB RAM; the A-Series runs up to A.96 with 9,600 GB capacity at $124.80/hr. |
Streaming and batch ingestion | $0.35/GB for the first 1,000 GB in a month; $0.25/GB for the next 9,000 GB; $0.15/GB over 10 TB | Streaming and batch data are each measured and billed independently. |
File storage | $0.060 per GB-month | For files kept in Polaris after upload and ingestion; no charge if you delete files after ingestion. |
Async queries | $0.0020 per DPU-min | Compute for each async query task per minute, for queries on data in deep storage. |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
0 GitHub commits 90d0 GitHub stars
See all signals from 2 sources
Alternatives to Imply Cloud
The reviewed substitutes for Imply Cloud among the OLAP databases, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- ClickHouse
- ClickHouse and Imply Cloud both run real-time analytical queries over large event streams for dashboards and user-facing apps. Imply Cloud is a managed service built on Apache Druid, while ClickHouse is an open-source columnar database that is also sold as a serverless cloud service.Applies to: Choosing between two products of the same kind for one job.
- SingleStore
- Real-time analytical queries on fresh data are the core job of both SingleStore and Imply Cloud. Imply Cloud is Imply's managed service built on Apache Druid, focused on streaming event data and interactive dashboards. SingleStore is a distributed SQL database that also processes transactions, which suits applications that write and analyse data in the same system.Applies to: Choosing between these two for the real time analytical databases decision.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Apache Druid
- Apache Druid is used rather than Imply Cloud for organizations that require Druid-based real-time analytics under their own cloud deployment and operating model. **Apache Druid** is an open-source distributed data store whose design combines data warehouse, time-series, and search-system characteristics.
- Apache Pinot
- Apache Pinot is used rather than Imply Cloud for user-facing real-time analytics workloads that demand highly configurable indexing and very high query concurrency. We recommend Pinot for teams building interactive analytics experiences with high concurrency and strong indexing requirements.
- Elasticsearch
- A columnar analytical database and a search engine both answer questions over large volumes, one by aggregation and one by search and relevance ranking. The overlap on log and event analytics is real, which is why they are compared, and the decision follows whether the workload is aggregation or retrieval.Applies to: Whether the workload is aggregation over events or search and relevance over documents.
- StarRocks
- StarRocks is chosen instead of Imply Cloud for lakehouse analytics workloads requiring complex multi-table SQL and frequent updates or deletes. **StarRocks** is a sub-second MPP OLAP database for real-time analytics, ad hoc queries, and data lakehouse scenarios.