Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Kubeflow states |
|---|---|
License | Apache-2.0, per the kubeflow/kubeflow repository. |
Where it runs | The project says the same code runs on a local laptop, on-premises, or in any cloud. |
Projects in the stack | Kubeflow Pipelines, Notebooks, Trainer, Katib, Hub (formerly Model Registry), Spark Operator and the Central Dashboard. |
Governance | Community-led, maintained by Kubeflow Working Groups under the Outreach, Distribution and Steering Committees. Kubeflow is a CNCF graduated project. |
Community channels | Weekly community calls, a mailing list and a Slack workspace. |
Our take
Kubeflow makes sense if you already run Kubernetes and want open source building blocks for training, pipelines and notebooks that you can add one at a time. If no one on your team will own the cluster those projects run on, weigh that ongoing work before you pick it.
Evaluate Kubeflow
Popular comparisons
See all 7 Kubeflow comparisons
Where it stands out
Adopt one piece at a time. The project describes its tools as composable: you mix and match them across the AI lifecycle. A team can start with Pipelines or Notebooks and add other projects later.
Distributed training across frameworks. Kubeflow Trainer is a Kubernetes-native platform for LLM fine-tuning and model training with PyTorch, MLX, HuggingFace, DeepSpeed, Megatron, JAX, XGBoost and more.
Built-in AutoML. Katib handles hyperparameter tuning, early stopping and neural architecture search as a Kubernetes-native project.
Portable ML workflows. Kubeflow Pipelines (KFP) is for building and then deploying portable, scalable machine learning workflows on Kubernetes. Hub adds an index of models, versions and ML artifact metadata between experiments and production.
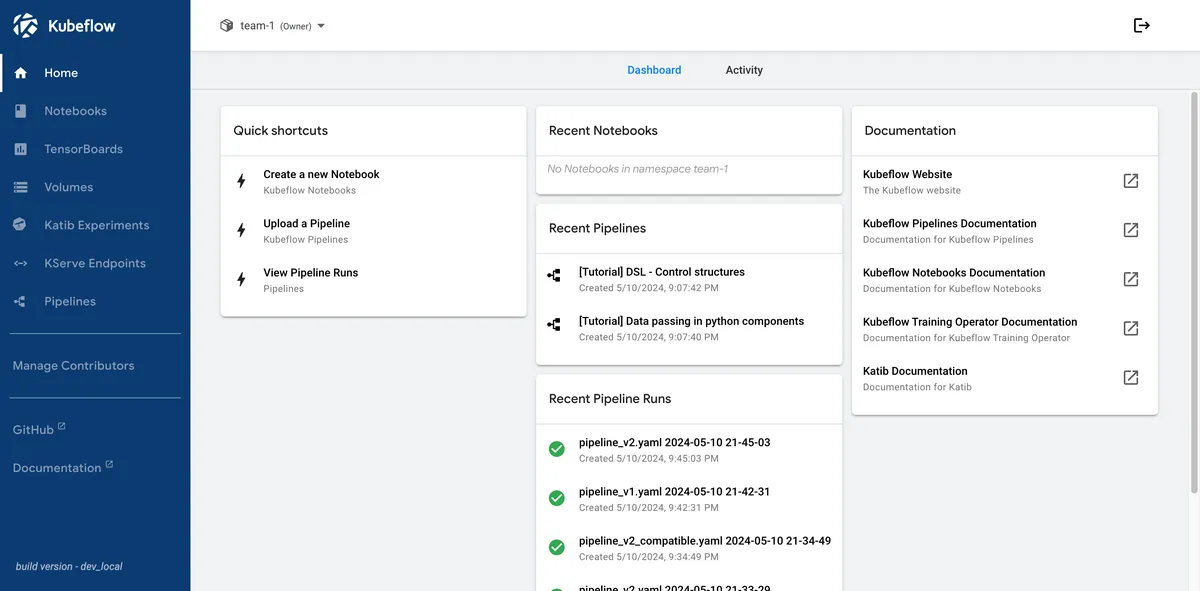
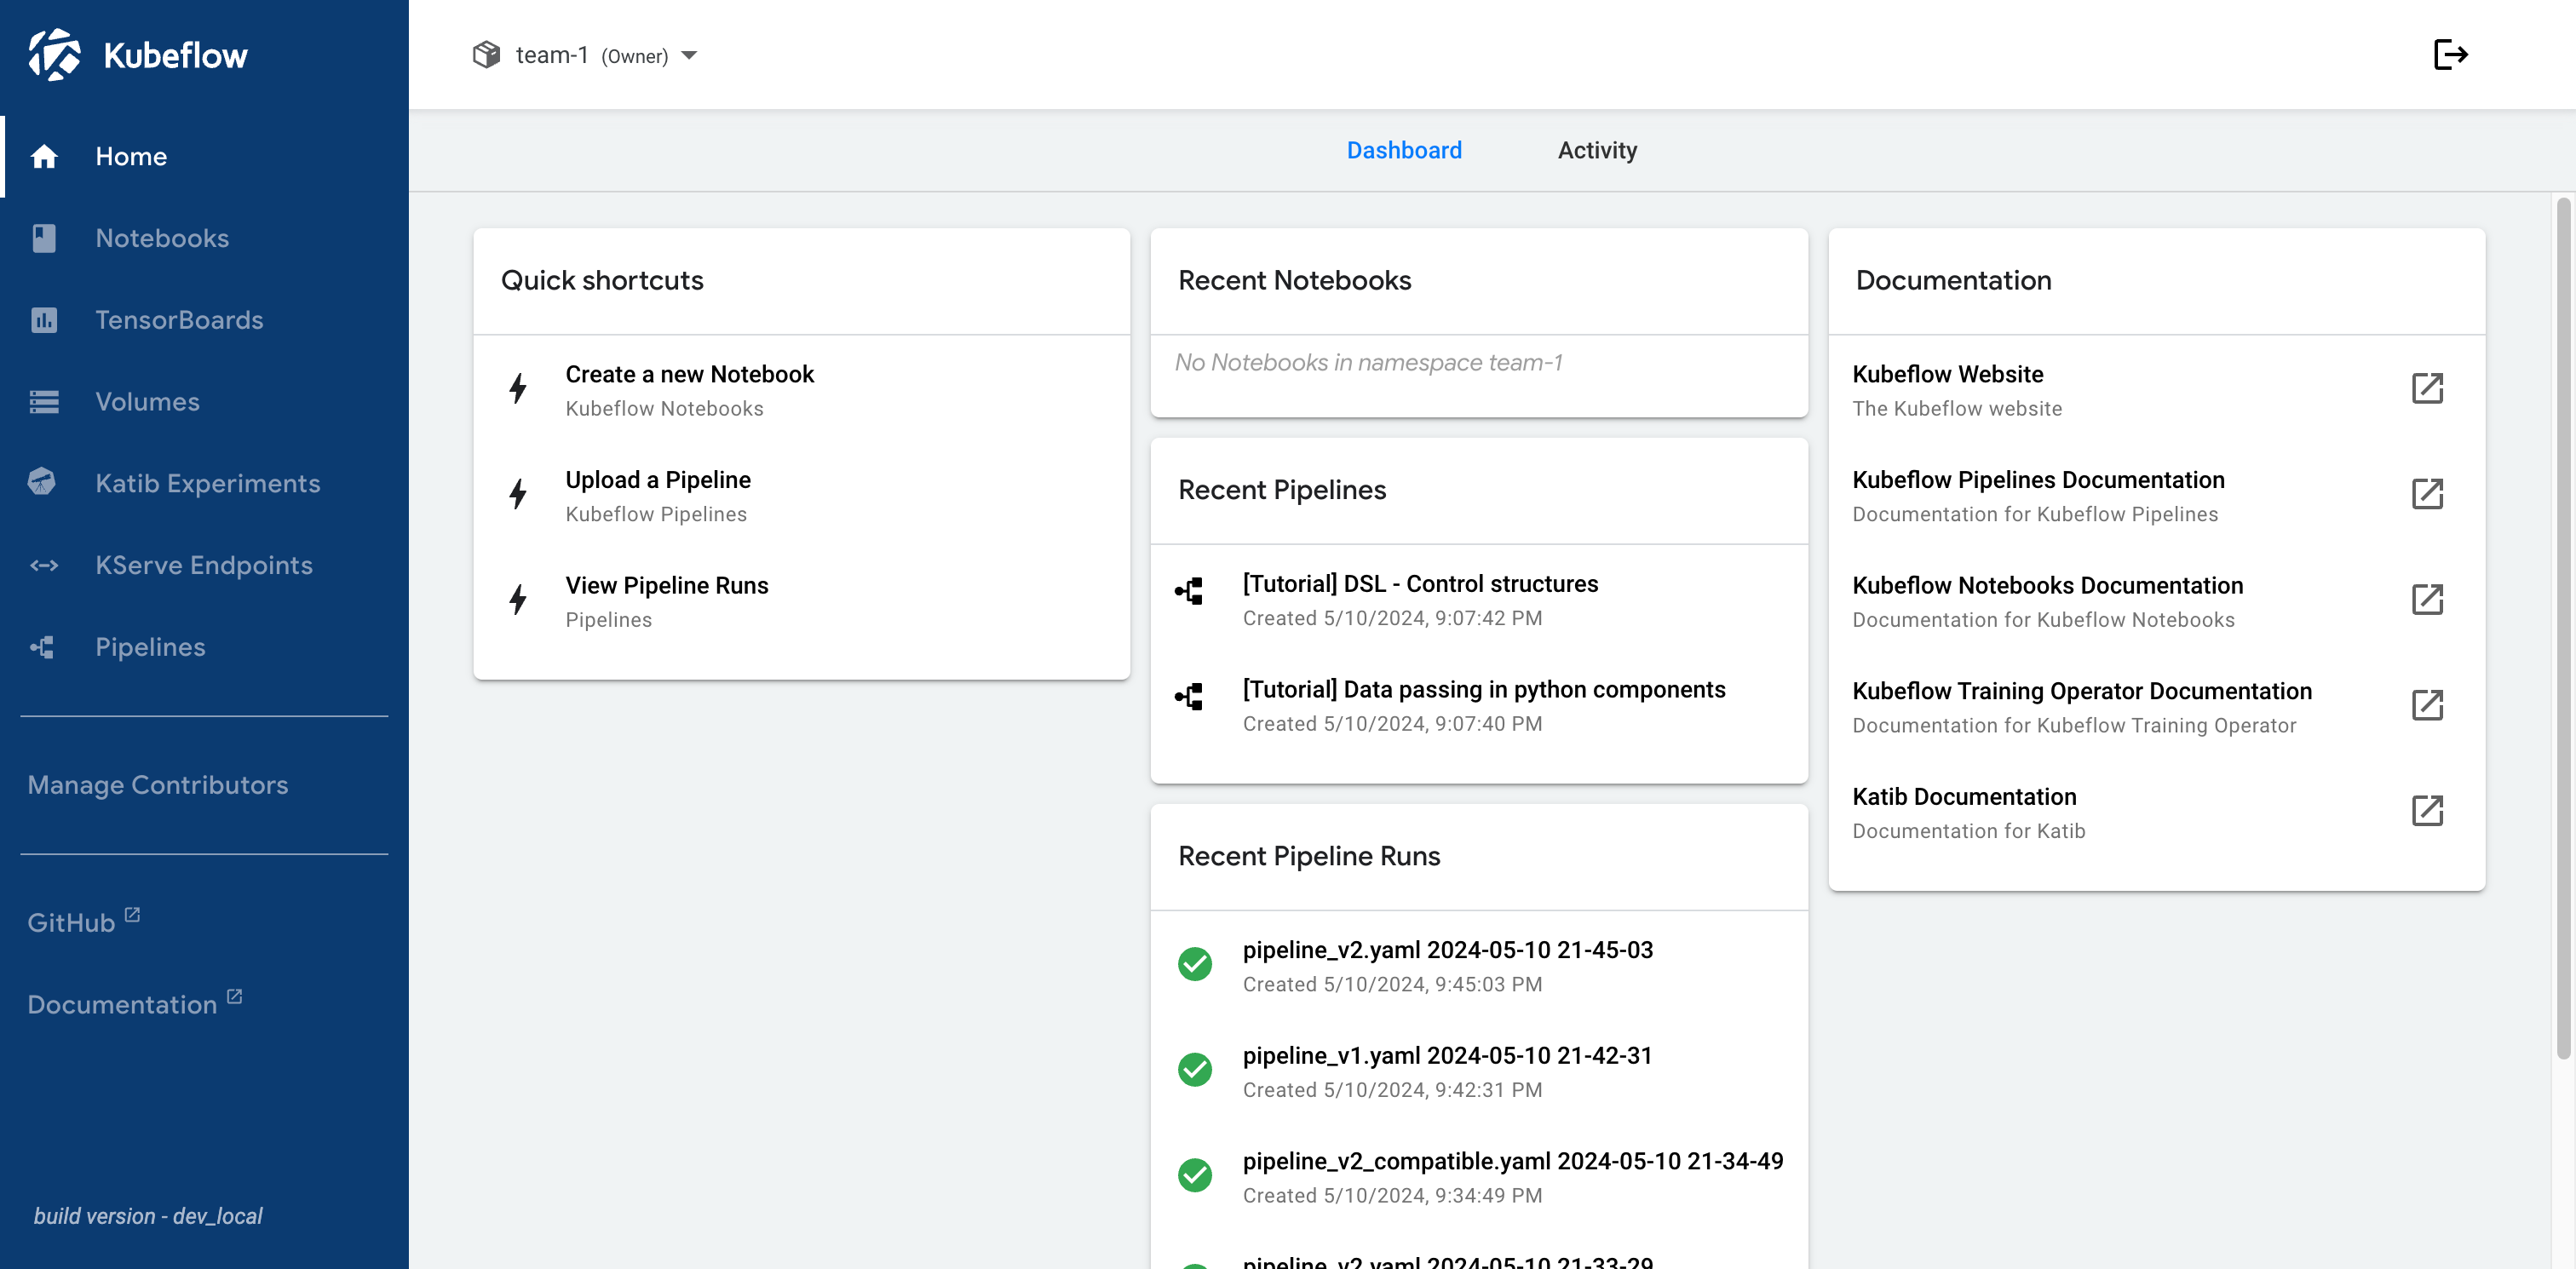
Product screenshot
Trade-offs to weigh
Kubernetes is the base layer. Every project targets Kubernetes. The project's stated goal is to let you run workloads without becoming a Kubernetes expert, but someone still has to run the cluster.
Many repositories to track. The main repository is a gateway; development happens in each subproject's own repository. Plan upgrades and security reviews per project, not for one product.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
2 GitHub commits 90d16.0k GitHub stars0 vulnerabilities across 1 package
See all signals from 6 sources
PyPI · kfp@2.18.0
Alternatives to Kubeflow
The reviewed substitutes for Kubeflow among the ML pipeline frameworks, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Metaflow
- Choose Metaflow if your team values simplicity and wants to ship ML projects without learning new abstractions.Applies to: Choosing between two products of the same kind for one job.
- Flyte
- Kubeflow and Flyte both orchestrate machine learning pipelines on Kubernetes. Kubeflow is a broad open-source platform whose projects for notebooks, training and serving can be adopted one by one, while Flyte puts the focus on typed, versioned and cached Python tasks and has a managed version through Union.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- MLflow
- Choose MLflow if you want the broadest ecosystem support and a gentle learning curve that does not require Kubernetes expertise.Applies to: Deciding whether run tracking and pipeline orchestration come from one tool or two.
- Ray
- Choose Ray if you need a distributed compute framework that goes beyond ML pipelines into general parallel Python workloads.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
- Weights & Biases
- Choose Weights & Biases if experiment visualization, team collaboration, and hyperparameter sweeps are your top priorities.Applies to: Deciding whether run tracking and pipeline orchestration come from one tool or two.
- Amazon SageMaker
- Amazon SageMaker and Kubeflow both cover building, training and deploying machine learning models. SageMaker is a fully managed AWS service, so Amazon runs the infrastructure, while Kubeflow is open source and runs on any Kubernetes cluster, which suits teams that want to stay portable across clouds or on their own servers.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Seldon
- The two sit at different layers of one system and the documented deployments run them together, so the reader's question is which job each one does rather than which to buy.Applies to: Whether these two do the same job, or different jobs in one pipeline.
Head to head
See detailed alternatives analysis
Organizations running ML workloads on Kubernetes often start with Kubeflow as their default orchestration layer, but the platform's operational complexity and steep learning curve push many teams to evaluate Kubeflow alternatives. With 15.6K GitHub stars and backing from the Cloud Native Computing Foundation, Kubeflow remains a powerful choice for teams deeply invested in Kubernetes infrastructure. However, several competing platforms now offer comparable ML lifecycle management with significantly less operational overhead, making it worth examining what else exists in the MLOps space.
Top Alternatives Overview
MLflow is an open-source MLOps platform for experiment tracking, model management, and related workflows. Backed by the Linux Foundation, it covers experiment tracking, model registry, evaluation, and deployment through a unified interface. MLflow integrates with 100+ AI frameworks including LangChain, OpenAI, and PyTorch, and its v3.11 release added agent server capabilities for deploying AI agents to production with a single command. Choose MLflow if you want the broadest ecosystem support and a gentle learning curve that does not require Kubernetes expertise.
Ray is a general-purpose distributed compute framework used for AI and Python workloads. Built by Anyscale, Ray handles distributed training, model serving, batch inference, and reinforcement learning through a Python-native API. Compare Ray and Spark using representative GPU batch-inference workloads, including infrastructure cost, runtime behavior, and operating effort. Ray supports heterogeneous GPU and CPU workloads with fine-grained scaling from a laptop to thousands of GPUs. Choose Ray if you need a distributed compute framework that goes beyond ML pipelines into general parallel Python workloads.
BentoML focuses specifically on model inference and serving, with 8.6K GitHub stars and an Apache-2.0 license. Its inference platform provides tailored optimization for latency, throughput, and cost, with features like distributed LLM inference across multiple GPUs, blazing-fast cold starts, and scale-to-zero capabilities. BentoCloud offers a managed version with BYOC (bring your own cloud) deployment. Choose BentoML if your primary bottleneck is getting trained models into production with optimized serving infrastructure.
Metaflow was originally developed at Netflix and provides a human-centric framework for building production ML pipelines. It emphasizes developer experience by letting data scientists use any Python library while handling dependency management, versioning, and cloud deployment automatically. Metaflow tracks variables inside flows for experiment tracking and deploys workflows to production with a single command. Choose Metaflow if your team values simplicity and wants to ship ML projects without learning new abstractions.
ClearML delivers an all-in-one MLOps platform covering experiment tracking, pipeline orchestration, dataset versioning, model deployment, and GPU compute orchestration. Originally developed as Allegro Trains, it offers both a free self-hosted open-source edition and a managed cloud option starting at $15 per month. The platform auto-logs experiments with minimal code changes. Choose ClearML if you want a single platform that covers the entire ML lifecycle without stitching together multiple tools.
Weights & Biases provides best-in-class experiment tracking and visualization with a freemium model starting at $0 for individuals, $60/month for Pro teams, and custom Enterprise pricing. W&B excels at collaborative model development, letting teams debug, compare, and reproduce models across architecture, hyperparameters, datasets, and GPU usage. Choose Weights & Biases if experiment visualization, team collaboration, and hyperparameter sweeps are your top priorities.
Architecture and Approach Comparison
Kubeflow takes a Kubernetes-native approach where every component runs as a Kubernetes resource. This means Kubeflow Pipelines, Katib (hyperparameter tuning), KServe (model serving), Notebooks, and the Model Registry all deploy as separate Kubernetes operators. The advantage is deep integration with Kubernetes RBAC, namespaces, and resource quotas. The disadvantage is that you need a dedicated platform team to manage the cluster, and every data scientist must understand Kubernetes concepts like pods, persistent volumes, and node selectors.
MLflow and Metaflow take the opposite approach by abstracting away infrastructure entirely. MLflow runs as a simple tracking server you start with one command (uvx mlflow server), while Metaflow lets you write decorated Python functions that transparently execute on AWS or Kubernetes. Neither requires your data scientists to understand container orchestration.
Ray sits in the middle, providing its own distributed runtime that can run on Kubernetes but does not require it. Ray's core primitives (tasks, actors, objects) give you fine-grained control over distributed computation without Kubernetes-specific concepts. This makes Ray more flexible but also means you are adopting a new distributed computing paradigm.
BentoML focuses specifically on the serving layer. Where Kubeflow tries to cover the full ML lifecycle, BentoML packages models into standardized "Bentos" with their dependencies, then deploys them with optimized serving patterns including real-time inference, async tasks, and batch processing. This narrower scope means less complexity but requires pairing with other tools for training and experimentation.
Pricing Comparison
All major alternatives in this comparison offer free open-source tiers, which is consistent with Kubeflow itself being entirely free under Apache-2.0. The cost differences emerge in managed services and commercial offerings.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Open Source | Managed/Pro Tier | Enterprise |
|---|---|---|---|
| Kubeflow | Free (Apache-2.0) | N/A (self-managed only) | N/A |
| MLflow | Free (Apache-2.0) | Databricks MLflow (bundled) | Databricks pricing |
| Ray | Free (Apache-2.0) | Anyscale ($100 free credit) | Custom pricing |
| BentoML | Free (Apache-2.0) | BentoCloud (usage-based) | Custom pricing |
| ClearML | Free (self-hosted) | From $15/month | Custom pricing |
| Comet ML | Free tier | $19/month Pro | Custom Enterprise |
| Weights & Biases | Free tier | $60/month Pro | Custom Enterprise |
The real cost of Kubeflow is not the software license but the operational overhead. Running a production Kubeflow cluster typically requires 1-2 dedicated platform engineers, Kubernetes cluster costs, and ongoing maintenance of multiple components. Teams switching to managed alternatives like ClearML or Weights & Biases often find the subscription fees are far less than the engineering time saved.
When to Consider Switching
Switch from Kubeflow when your platform team spends more time maintaining the ML infrastructure than your data scientists spend using it. If Kubeflow cluster upgrades consistently take weeks and break existing pipelines, that is a strong signal to evaluate simpler alternatives.
Consider MLflow or ClearML if your team primarily needs experiment tracking and model registry capabilities. Kubeflow's overhead is not justified when you are using only 20% of its features, and both tools provide these capabilities with minimal setup.
Move to Ray if you have outgrown Kubeflow's pipeline model and need flexible distributed computing. Ray's ability to handle heterogeneous workloads (training, serving, data processing) through a unified Python API eliminates the need for separate Kubernetes operators per workload type.
Adopt BentoML if model serving is your bottleneck. KServe within Kubeflow handles basic inference, but BentoML provides superior optimization for inference-specific concerns like cold start time, auto-scaling based on inference metrics, and distributed LLM serving across multiple GPUs.
Stick with Kubeflow if your organization has already invested in Kubernetes expertise, needs strict multi-tenancy with Kubernetes namespaces, and uses multiple Kubeflow components together (Pipelines, Katib, KServe, Notebooks). The integration between these components is tighter than any combination of standalone tools can provide.
Migration Considerations
Kubeflow Pipelines use a Python SDK that compiles to Argo Workflows YAML. Migrating to Metaflow or MLflow Pipelines requires rewriting pipeline definitions, though the underlying training code (PyTorch, TensorFlow, XGBoost) remains unchanged. Budget 2-4 weeks for a team migrating 10-20 active pipelines.
Experiment tracking data in Kubeflow is stored in a MySQL backend. MLflow uses a similar relational backend and supports importing historical runs, making it one of the easier migrations. Weights & Biases and ClearML both offer migration scripts for common tracking formats.
KServe models deployed through Kubeflow can transition to BentoML by packaging the same model artifacts into Bento format. The serving API signatures will change, requiring downstream client updates. BentoML's standardized packaging actually simplifies future migrations since Bentos are portable across any infrastructure.
The learning curve varies significantly. MLflow takes hours to get productive with (three-step setup from their docs). Metaflow requires about a day to learn the decorator-based pipeline syntax. Ray requires the most learning investment because its distributed computing model (tasks, actors, object store) is fundamentally different from Kubeflow's pipeline-based approach. Plan for 1-2 weeks of ramp-up time for Ray adoption.