Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Zylon states |
|---|---|
Deployment | Your data center, private cloud VPC or fully air-gapped environments; no internet connection required. Zylon in a Box is a pre-configured on-prem server. |
What is included | AI Core (local LLMs, vector databases, GPU orchestration); Workspace with an AI assistant, document creation, knowledge base access, collaborative projects and data connectors; and an API Gateway with authentication, logging, rate limiting and observability. |
Operations and governance | Self-contained Kubernetes deployment with 20+ packaged services, a CLI for installs, updates and model selection, LDAP/Active Directory with RBAC, and SIEM audit logs. |
Compliance frameworks shown | SOC 2, HIPAA, GDPR, ISO 27001, EU AI Act and NIS2 |
Target industries | Financial services, government and public sector, healthcare, and defense and critical infrastructure |
Open-source base | PrivateGPT, Apache-2.0 license; installs with Homebrew on macOS or uv on Linux and Windows |
Our take
Zylon fits a regulated organization that wants staff and developers using generative AI on private data with no traffic to a cloud model provider, and that is ready to run the servers itself. If your team only needs a local API layer and can manage inference, user access and auditing on its own, start with the open-source PrivateGPT instead.
Evaluate Zylon
Comparisons
Where it stands out
Works fully disconnected. Zylon lists air-gapped operation without external cloud dependencies, and n8n workflow automation also runs in that air-gapped setup. This matters where data may not leave the site at all, not just stay in one cloud region.
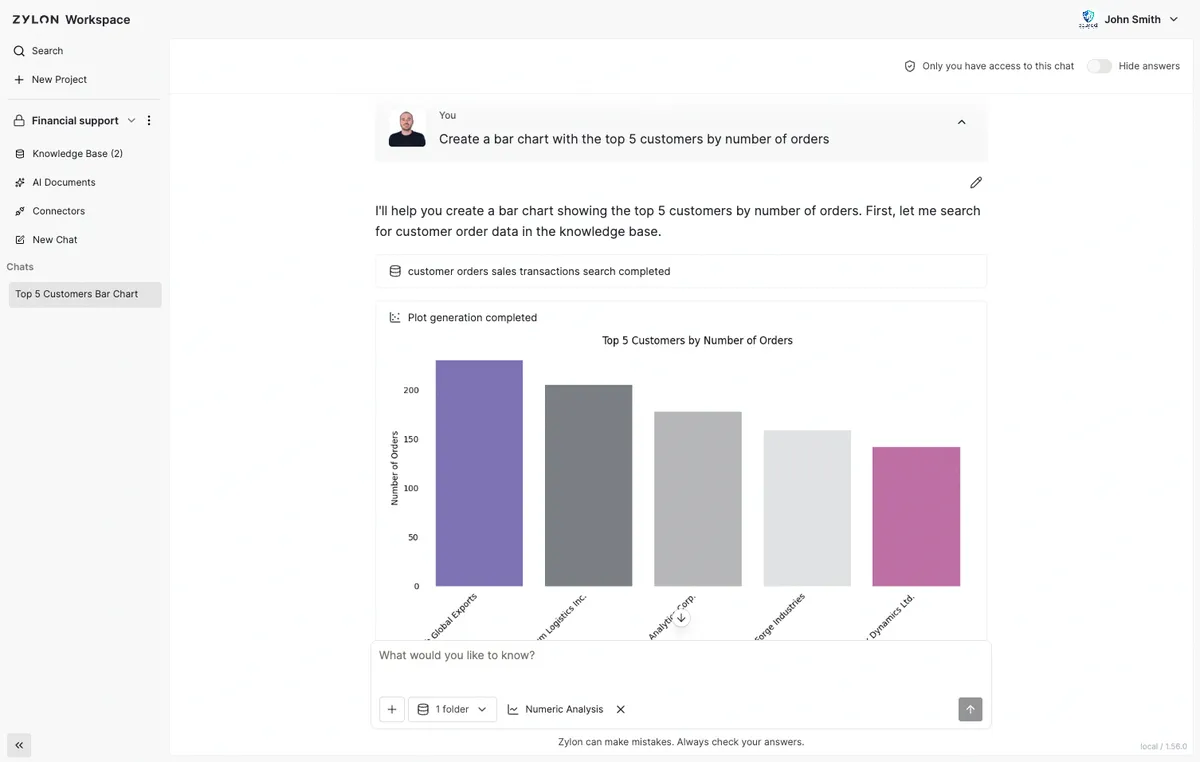
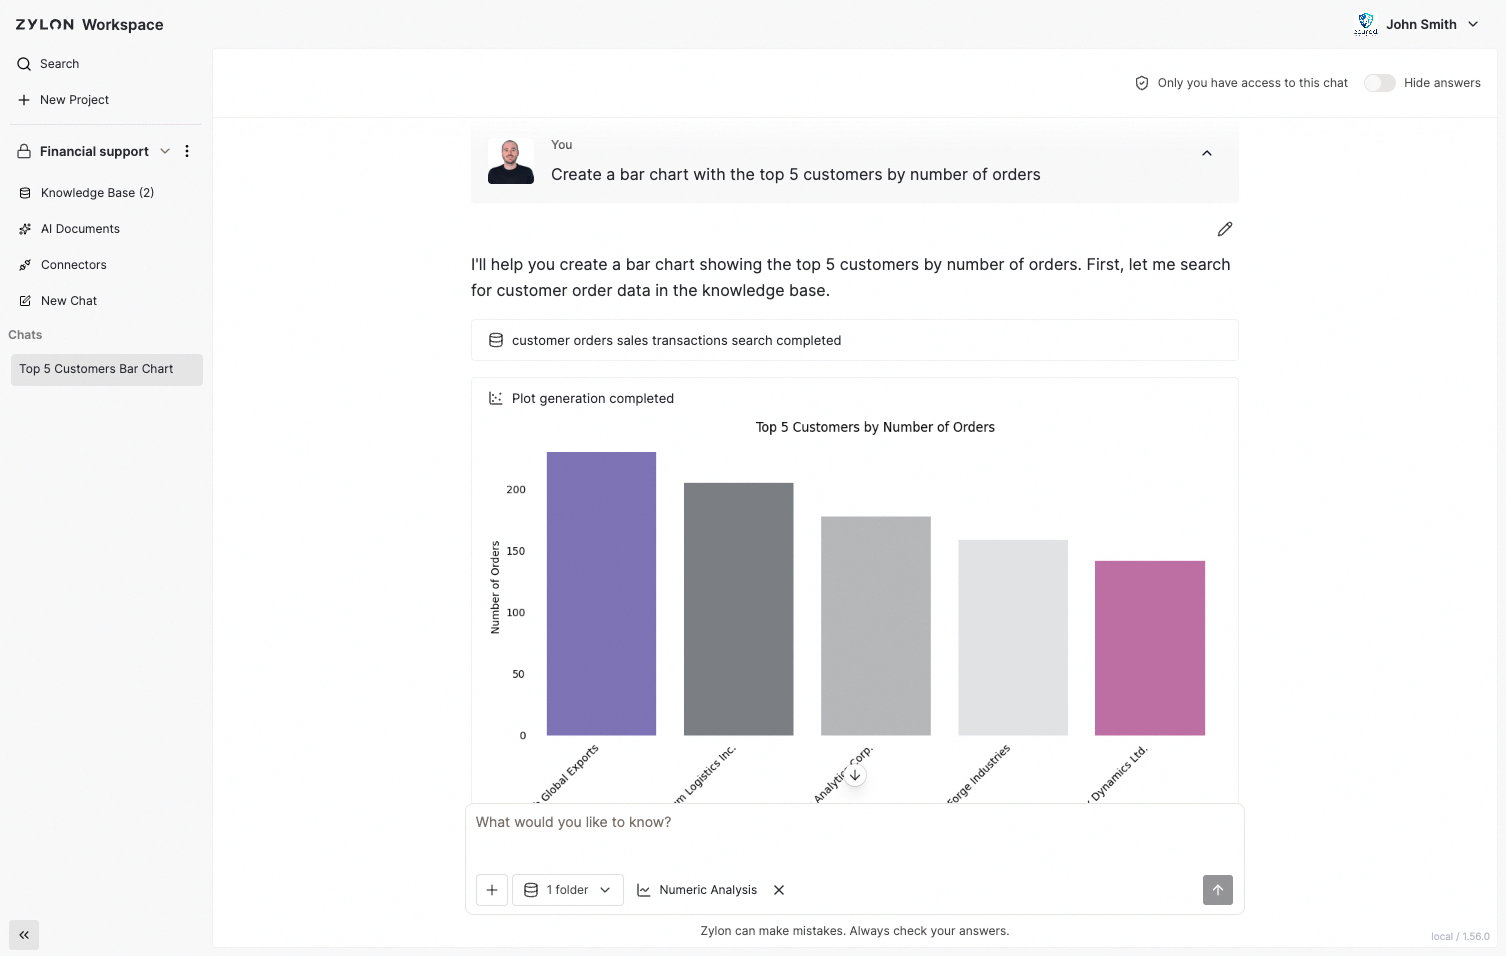
Banking core connectors. Zylon connects to Symitar, Corelation and Fiserv, plus SharePoint, Confluence, PostgreSQL, Salesforce, S3 and file systems, without moving data to the cloud. Its financial services examples include member service inquiries, loan document processing and compliance checks.
Standard APIs for builders. The API Gateway follows OpenAI and Anthropic API standards, so tools such as LangChain and Claude Code can point at private models. n8n deploys with one click on the same server, at its own subdomain, and updates with Zylon.
Model choice. Zylon's comparison says you can use any model, where ChatGPT and Copilot offer only vendor-provided models. Inference runs on an integrated NVIDIA Triton and vLLM server for open-weight models, with concurrency, batch processing and load balancing.
Short rollout, by Zylon's account. Zylon says deployment is a single command and production-ready in under one week, against 12-18 months it gives for an in-house build. Orsa Credit Union's Jon Burkey says they were production-ready in days.
Product screenshot
Trade-offs to weigh
You run the hardware. Zylon runs in your data center or private cloud, so GPU capacity, power and server upkeep sit with your IT team. Zylon in a Box arrives as a pre-configured server, which saves setup work, but you still host and run it. Ask early what hardware your expected users and models need.
Check what each compliance badge means. The site shows six frameworks side by side. Ask Zylon which are audited certifications and which describe how the platform supports your own compliance work.
Open source covers only the API layer. PrivateGPT does not run models itself and needs a separate OpenAI-compatible inference server. The Workspace app, directory integration, SIEM logs, connectors such as SharePoint, Confluence, FTP and Samba, and support come with Zylon.
API coverage has gaps. PrivateGPT's own comparison with the Claude API marks prompt caching as not supported and skills as basic, and structured outputs depend on the inference server.
Pricing and plan conditions
Token volume and usage do not move the Zylon bill, so heavy query and document workloads do not change it. The models run on servers in your own data center or private cloud, or on a Zylon in a Box server you host.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Option | Cost basis stated | What it includes |
|---|---|---|
Zylon platform | Fixed cost, independent of tokens; no usage limits | Workspace, API, n8n and AI models in one platform |
PrivateGPT (open source) | Apache-2.0 license | Messages API, document ingestion, retrieval with citations, tools, MCP connectors and database access; bring your own inference server |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
50 GitHub commits 90d57.6k GitHub stars
See all signals from 3 sources
Alternatives to Zylon
The reviewed substitutes for Zylon among the enterprise AI platforms, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Anthropic
- Anthropic is an AI safety and research company that's working to build reliable, interpretable, and steerable AI systems.Applies to: Whether models run on a hosted API or inside your own infrastructure under your own compliance.
Head to head
See detailed alternatives analysis
If you are evaluating Zylon alternatives, you are likely searching for an AI platform that can run securely within regulated environments while meeting strict compliance requirements. Zylon positions itself as an on-premise, air-gapped AI platform built for financial services, healthcare, and government sectors. However, depending on your deployment model preferences, budget constraints, or feature requirements, several other AI platforms offer compelling capabilities worth considering.
Top Alternatives Overview
OpenAI is the most widely adopted AI platform globally, powering GPT-4o and the ChatGPT ecosystem. OpenAI offers usage-based API pricing, with GPT-4o mini at $0.15 per million input tokens and $0.60 per million output tokens, with enterprise options through ChatGPT Enterprise that include SOC 2 compliance, data encryption at rest, and admin console controls. OpenAI provides a broad model selection and a sizable developer ecosystem, though data is processed on OpenAI's cloud infrastructure. Choose this if you need the most capable general-purpose models and your compliance requirements allow cloud-based processing with enterprise security controls.
Perplexity Computer delivers an AI-powered answer engine that combines large language models with real-time web search, providing sourced and cited responses. The platform offers both free and Pro tiers, with Perplexity Pro priced at $20/month for individuals, offering access to advanced models and unlimited Pro searches. Perplexity focuses heavily on accuracy and factual grounding through its retrieval-augmented generation approach. Choose this if your primary use case is research, knowledge retrieval, and question answering rather than building custom AI applications.
Edgee takes a fundamentally different approach by offering edge-native token compression that reduces LLM costs by up to 50%. Edgee provides a single OpenAI-compatible API that routes to over 200 models with intelligent request routing and built-in cost optimization. The platform uses usage-based pricing, making it attractive for organizations with variable workloads. Choose this if you want to reduce your AI inference costs while maintaining access to multiple model providers through one unified API.
Hala X Uni Trainer is a local-first platform designed for building datasets, fine-tuning LLMs, and deploying models to production with SHA-256 provenance tracking. The platform requires no coding and provides an end-to-end workflow from dataset creation through model validation and deployment. Uni Trainer emphasizes data provenance and auditability throughout the entire model lifecycle. Choose this if your focus is on custom model fine-tuning and you need a no-code environment with strong provenance tracking for regulated workflows.
NeuraLearn offers an AI Canvas Studio, a collaborative visual development platform for building neural networks. The enterprise-grade platform enables teams to design, train, and deploy models through a visual interface with real-time collaboration features. NeuraLearn targets teams that want to build custom AI solutions without deep ML engineering expertise. Choose this if you need a collaborative, visual environment for building and training custom neural network architectures within your organization.
Mirano focuses on transforming complex data into professional, on-brand visuals. Starting at $9/month on a freemium model, Mirano helps marketing and sales teams create infographics, charts, and slides using AI-powered design automation. The platform requires no design experience and can produce presentation-ready visuals in seconds. Choose this if your primary need is AI-powered data visualization and automated report generation rather than a full AI development platform.
Architecture and Approach Comparison
Zylon runs as a fully self-contained AI stack deployed on your own servers or private cloud. The architecture includes local LLMs, vector databases, GPU orchestration, an OpenAI-compatible API Gateway, and a built-in workspace, all running without any external internet dependency. Zylon supports air-gapped deployment, meaning the entire platform operates in complete network isolation. The platform uses fixed-cost licensing rather than per-token pricing, and includes built-in n8n for workflow automation.
OpenAI and Perplexity operate entirely in the cloud. OpenAI processes requests through its hosted infrastructure, while Perplexity combines LLM inference with live web retrieval. Neither supports on-premise deployment, though OpenAI offers Azure OpenAI Service through Microsoft for organizations needing data residency in specific regions. Edgee acts as an intermediary layer that sits between your application and multiple LLM providers, compressing tokens at the edge before routing to the most cost-effective model. Unlike Zylon, Edgee does not host its own models but optimizes how you consume models from other providers.
Hala X Uni Trainer and NeuraLearn both support local-first or self-hosted workflows. Uni Trainer runs the dataset creation and fine-tuning pipeline locally with SHA-256 hashing for provenance, while NeuraLearn provides a visual canvas approach to model building that can run within enterprise environments. These platforms focus on model development rather than providing a ready-to-use AI assistant, which is Zylon's primary interface through its Workspace product.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Platform | Pricing Model | Starting Price | Key Cost Factor |
|---|---|---|---|
| Zylon | Enterprise (fixed) | Contact sales | Per-deployment, unlimited tokens |
| OpenAI | Usage-based | $0.15/M input tokens (GPT-4o mini) | Per-token consumption |
| Edgee | Usage-based | Free tier available | Per-request with compression savings |
| Mirano | Freemium | $9/month | Per-seat subscription |
| Perplexity | Freemium | $20/month Pro | Per-seat subscription |
| Hala X Uni Trainer | Enterprise | Contact sales | Per-deployment |
| NeuraLearn | Enterprise | Contact sales | Per-deployment |
Zylon's fixed-cost model means your expense stays predictable regardless of how many tokens your teams consume. This is a significant advantage for organizations with high usage volume, where OpenAI's per-token pricing can scale quickly into six figures monthly. However, the upfront investment for Zylon includes hardware requirements since you are hosting the full AI stack on your own infrastructure, including GPU servers. OpenAI and Edgee eliminate infrastructure costs entirely by operating as cloud services.
When to Consider Switching
Organizations should evaluate Zylon alternatives when their compliance requirements do not mandate air-gapped or on-premise deployment. If your data classification allows cloud processing with proper encryption and access controls, platforms like OpenAI's enterprise tier or Azure OpenAI Service deliver more capable models with less operational overhead. You avoid managing GPU hardware, model updates, and infrastructure scaling entirely.
Consider switching if your use case is narrowly focused. If you primarily need AI-powered search and research, Perplexity delivers a more refined experience than running a general-purpose AI stack. If your goal is reducing inference costs across multiple model providers, Edgee's edge compression and intelligent routing can cut spending by 50% without infrastructure investment. If you need custom model fine-tuning with provenance tracking, Hala X Uni Trainer provides a dedicated workflow that Zylon's more generalist platform does not prioritize.
Teams with limited IT infrastructure capacity should also look at cloud alternatives. Zylon requires dedicated GPU servers, networking configuration, and ongoing maintenance. Organizations without a dedicated infrastructure team may find the operational burden outweighs the compliance benefits, particularly if they can achieve adequate data protection through cloud enterprise agreements and data processing addenda.
Migration Considerations
Moving away from Zylon is relatively straightforward from an API compatibility standpoint. Zylon implements OpenAI-compatible API endpoints, so applications built against Zylon's API Gateway can typically switch to OpenAI, Azure OpenAI, or Edgee by changing the base URL and authentication credentials. Custom workflows built with the included n8n instance will need to be migrated to a separately hosted n8n deployment or an alternative automation tool.
The primary migration challenge is data. If you have built vector databases and knowledge bases within Zylon's on-premise environment, you will need to export and re-index that content into your new platform's storage layer. Document ingestion pipelines and connector configurations to systems like SharePoint, Confluence, PostgreSQL, or banking core systems (Symitar, Corelation, Fiserv) will need to be rebuilt for the target platform.
Expect a migration timeline of 2-4 weeks for API-level switches and 6-8 weeks for full knowledge base and workflow migrations. The compliance and legal review process, particularly for organizations moving from on-premise to cloud deployment, often takes longer than the technical migration itself. Budget 4-6 weeks for compliance team sign-off when moving sensitive data processing to cloud infrastructure, especially in financial services or healthcare settings.