Decision comparison
Better Stack vs SigNoz
Better Stack and SigNoz both suit teams without a platform function, and they cover different ground. Better Stack bundles uptime monitoring, logs, status pages and on-call scheduling into one product. SigNoz is an open, OpenTelemetry-native platform covering metrics, logs and traces in one store, self-hosted or managed.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
Applies to: Choosing between these two for the apm observability decision.
All 2 are observability platforms.
Quick Comparison
| Decision factor | Better Stack | SigNoz |
|---|---|---|
| What it is | A developer-facing platform combining uptime monitoring, log management and incident response in one product | An open-source, OpenTelemetry-native observability platform, self-hosted or run as a managed cloud service |
| Emphasis | One product covering uptime, logs and on-call for a team that owns its services | An open, OpenTelemetry-native platform covering metrics, logs and traces |
| Licensing | Commercial SaaS with a usable free tier | Open source, self-hosted or as SigNoz Cloud |
| Scope | Monitoring, log management, status pages and incident response | Metrics, logs, traces and exceptions in one ClickHouse-backed store |
| Deployment | SaaS only | Your own infrastructure, or managed |
| On-call | Scheduling, escalation and status pages included | Alerting, with on-call scheduling expected from a dedicated tool |
| Best fit | Small teams wanting the whole monitoring and on-call workflow in one purchase | Teams wanting an open platform they can run themselves |
| Instrumentation path | OpenTelemetry SDKs in Python, Java, Node.js or Go emitting OTLP, or the platform's own agent | OpenTelemetry SDKs in Python, Java, Node.js or Go emitting OTLP, or the platform's own agent |
Better Stack
- What it is:
- A developer-facing platform combining uptime monitoring, log management and incident response in one product
- Emphasis:
- One product covering uptime, logs and on-call for a team that owns its services
- Licensing:
- Commercial SaaS with a usable free tier
- Scope:
- Monitoring, log management, status pages and incident response
- Deployment:
- SaaS only
- On-call:
- Scheduling, escalation and status pages included
- Best fit:
- Small teams wanting the whole monitoring and on-call workflow in one purchase
- Instrumentation path:
- OpenTelemetry SDKs in Python, Java, Node.js or Go emitting OTLP, or the platform's own agent
SigNoz
- What it is:
- An open-source, OpenTelemetry-native observability platform, self-hosted or run as a managed cloud service
- Emphasis:
- An open, OpenTelemetry-native platform covering metrics, logs and traces
- Licensing:
- Open source, self-hosted or as SigNoz Cloud
- Scope:
- Metrics, logs, traces and exceptions in one ClickHouse-backed store
- Deployment:
- Your own infrastructure, or managed
- On-call:
- Alerting, with on-call scheduling expected from a dedicated tool
- Best fit:
- Teams wanting an open platform they can run themselves
- Instrumentation path:
- OpenTelemetry SDKs in Python, Java, Node.js or Go emitting OTLP, or the platform's own agent
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Better Stack | SigNoz |
|---|---|---|
| GitHub commits, 90d(Developer adoption) | 31 | Not available |
| GitHub stars(Developer adoption) | 73 | Not available |
| Search interest(Market interest) | Unavailable | 1 |
| Hacker News mentions, 90d(Community interest) | 0 | 3 |
| npm weekly downloads(Developer adoption) | 225.1k | Not available |
| PyPI weekly downloads(Developer adoption) | 124.6k | Not available |
| Docker Hub pulls(Product adoption) | Not available | 1.0M |
| GitHub commits, 90d(Product adoption) | Not available | 609 |
| GitHub stars(Product adoption) | Not available | 32,000+ |
| Stack Overflow questions(Community interest) | Not available | 9 |
As of September 14, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Better Stack
September 14, 2026Package vulnerabilities
npm · @logtail/node@0.5.8 · PyPI · logtail-python@0.4.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
SigNoz
Package vulnerabilities
Not available
Repository security score
Not available
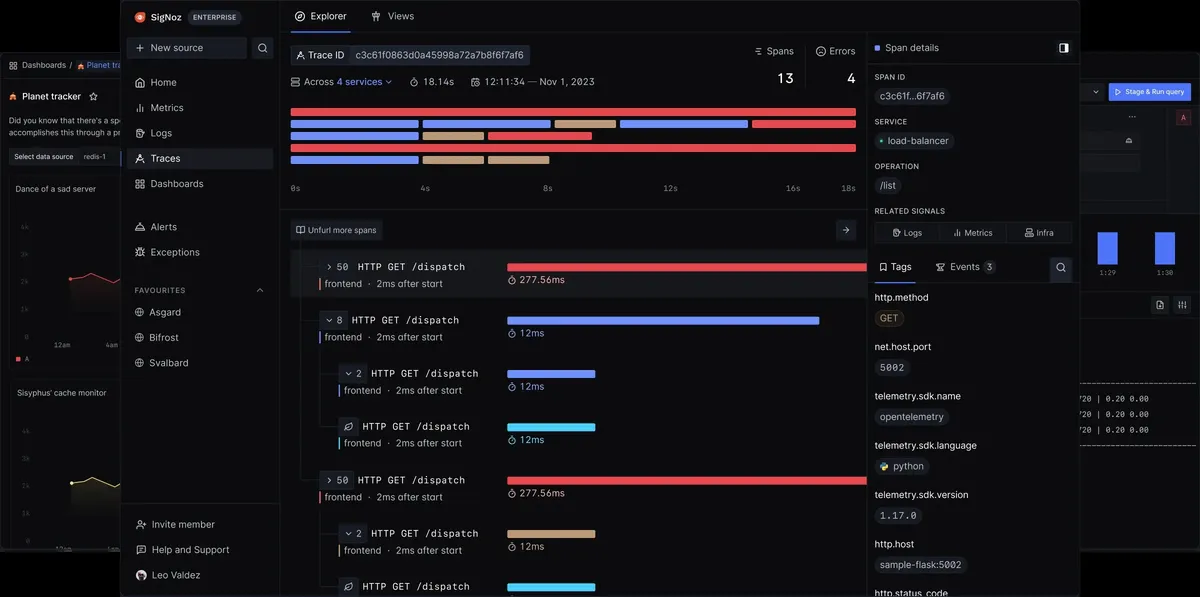
Interface Preview
Better Stack

SigNoz
Feature Comparison
| Feature | Better Stack | SigNoz |
|---|---|---|
| Operations | ||
| Uptime and synthetic checks | Full support | Partial support |
| Incident response and on-call scheduling | Full support | Not verified |
| Status pages | Full support | Not verified |
| Log management | Full support | Full support |
| Platform | ||
| Open source core | Not verified | Full support |
| Self-host the same software | Not verified | Full support |
| SQL access to telemetry | Not verified | Full support |
| Distributed tracing depth | Partial support | Full support |
| Adoption | ||
| Usable free tier | Full support | Full support |
| Setup measured in minutes | Full support | Full support |
| Works without vendor agents | Full support | Full support |
| Enterprise access control | Partial support | Partial support |
| Standards | ||
| OpenTelemetry ingestion | Full support | Full support |
| Distributed tracing | Full support | Full support |
| Log search | Full support | Full support |
| Metrics dashboards and alerting | Full support | Full support |
Operations
Uptime and synthetic checks
Incident response and on-call scheduling
Status pages
Log management
Platform
Open source core
Self-host the same software
SQL access to telemetry
Distributed tracing depth
Adoption
Usable free tier
Setup measured in minutes
Works without vendor agents
Enterprise access control
Standards
OpenTelemetry ingestion
Distributed tracing
Log search
Metrics dashboards and alerting
Which to choose
Better Stack and SigNoz both suit teams without a platform function, and they cover different ground. Better Stack bundles uptime monitoring, logs, status pages and on-call scheduling into one product. SigNoz is an open, OpenTelemetry-native platform covering metrics, logs and traces in one store, self-hosted or managed.
Best-fit scenarios
Choose Better Stack if:
Choose Better Stack when the gap is the workflow around an incident rather than the telemetry itself. Uptime checks from outside the system, alert routing, on-call rotas and a public status page arrive as one purchase, which for a small team is the difference between having monitoring and planning to set it up.
Choose SigNoz if:
Choose SigNoz when tracing and correlated telemetry are what you need, and when being open source matters. One ClickHouse-backed store keeps metrics, logs and traces together, SQL underneath supports ad-hoc analysis, and the platform can run on your own infrastructure rather than only on someone else's.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
What does OpenTelemetry-native mean in practice?
That the product's data model is the standard's rather than a vendor's, so there is no translation layer and no proprietary agent to install. Instrumentation written for it works unchanged against any other OTLP backend, which is what makes the decision reversible. Vendor agents still collect some application detail that generic instrumentation does not, so check whether the depth you rely on comes from the standard before assuming a clean swap.
What does self-hosting actually cost?
Storage is cheap; the engineer is not. Running an observability backend at production scale means capacity planning, upgrades, cardinality management and an on-call rotation that understands the telemetry system as well as the systems it watches. For a team already operating Kubernetes with ClickHouse or similar underneath, it is an incremental workload on existing skills. For a team without that, it is a job nobody has time for — which is why the open option also sells a managed tier.
Which gap should a small team close first?
Detection and response, almost always. An outage nobody notices until a customer calls is worse than one you know about but cannot yet explain, and on-call scheduling with a status page is the part teams most often lack. Deep tracing earns its place once detection is reliable and the remaining cost is the hours spent diagnosing.
What do these need to run?
An agent or an OpenTelemetry SDK in the application, and a destination. Services in Python, Java, Node.js or Go emit OTLP over HTTP or gRPC, and containers on Kubernetes are instrumented once per pod or once per node depending on the collector you choose. Nothing unusual is required on the application side; the operational weight sits in deciding what to sample, what to retain and for how long.
How portable is the instrumentation?
SigNoz is OpenTelemetry-native, so spans and attributes are standard OTLP and the backend is genuinely replaceable — instrumentation work transfers. Better Stack's monitoring is configuration rather than instrumentation: checks, alert rules, escalation policies and schedules, quick to recreate but not portable in any standard sense. The asymmetry matters less here than usual, because these two are complements more often than alternatives. Instrument with OpenTelemetry regardless, and treat on-call configuration as something you will rewrite if you move.
What actually drives the cost on each?
On Better Stack, the number of monitors, the volume of logs ingested and the size of the on-call team — all predictable in advance, with log ingestion the line that grows without anybody deciding it should. On SigNoz self-hosted, no licence and a ClickHouse cluster whose cost grows with hardware rather than data sent, plus the engineering time to operate it; SigNoz Cloud converts that into an invoice. One is a budget you set, the other is infrastructure you size and staff.
Who is each one for?
Better Stack is for a team without a platform function that needs uptime checks, alerting, on-call rotation and a status page working this week. SigNoz is for a team whose engineers instrument their own services and want traces, logs and metrics in one queryable store they can host themselves. The tell is what your last three incidents cost. If the expensive part was finding out at all, start with monitoring; if it was explaining what happened inside a request, start with the observability platform.
How should we evaluate them?
Send a slice of real traffic to both and then debug a real incident on each. Dashboards demo well and tell you very little; what matters is whether an engineer at 3am can go from an alert to the cause without knowing in advance which dashboard to open. OpenTelemetry makes that trial cheap, because the instrumentation is the same and only the destination changes.