Decision comparison
Evidence vs Lightdash
Evidence and Lightdash both assume a data team that works in dbt and Git, and they expose different amounts of it. Evidence writes the whole report as a file — SQL, prose and charts together — reviewed as code. Lightdash reads metrics defined in the dbt project and gives analysts a browser to explore them without writing files.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
All 2 are BI platforms.
Quick Comparison
| Decision factor | Evidence | Lightdash |
|---|---|---|
| What it is | A code-based BI framework where reports are Markdown files containing SQL and charts | A BI platform built directly on dbt, where metrics defined in dbt become the metrics people chart |
| Where metrics live | In the SQL of each report, with reuse through components | In the dbt project, defined once and read by every chart |
| How a report is made | Written in a file, reviewed in a pull request, deployed by continuous integration | Explored in the browser over dbt models, with saved charts and dashboards |
| Audience | Analytics engineers comfortable with Git and SQL | Analysts working over a dbt project, without needing to write files |
| Governance | Version control: every change has a diff, an author and a history | Metric definitions live in dbt and are reviewed there |
| Best fit | Teams who want the whole report reviewed like code | Teams on dbt who want its metrics exposed for self-service |
| Connectivity | Queries Snowflake, BigQuery, Redshift, Databricks and Postgres over standard drivers | Queries Snowflake, BigQuery, Redshift, Databricks and Postgres over standard drivers |
Evidence
- What it is:
- A code-based BI framework where reports are Markdown files containing SQL and charts
- Where metrics live:
- In the SQL of each report, with reuse through components
- How a report is made:
- Written in a file, reviewed in a pull request, deployed by continuous integration
- Audience:
- Analytics engineers comfortable with Git and SQL
- Governance:
- Version control: every change has a diff, an author and a history
- Best fit:
- Teams who want the whole report reviewed like code
- Connectivity:
- Queries Snowflake, BigQuery, Redshift, Databricks and Postgres over standard drivers
Lightdash
- What it is:
- A BI platform built directly on dbt, where metrics defined in dbt become the metrics people chart
- Where metrics live:
- In the dbt project, defined once and read by every chart
- How a report is made:
- Explored in the browser over dbt models, with saved charts and dashboards
- Audience:
- Analysts working over a dbt project, without needing to write files
- Governance:
- Metric definitions live in dbt and are reviewed there
- Best fit:
- Teams on dbt who want its metrics exposed for self-service
- Connectivity:
- Queries Snowflake, BigQuery, Redshift, Databricks and Postgres over standard drivers
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Evidence | Lightdash |
|---|---|---|
| GitHub commits, 90d(Product adoption) | 40 | 4.7k |
| GitHub stars(Product adoption) | 6,500+ | 6,000+ |
| Search interest(Market interest) | 0 | 0 |
| npm weekly downloads(Product adoption) | 18.9k | Not available |
| Product Hunt comments(Community interest) | 28 | Not available |
| Product Hunt rating(Community interest) | 4.8/5 | Not available |
| Product Hunt reviews(Community interest) | 4 | Not available |
| Product Hunt votes(Community interest) | 113 | Not available |
| Docker Hub pulls(Product adoption) | Not available | 2.8M |
| Hacker News mentions, 90d(Community interest) | Not available | 1 |
| npm weekly downloads(Developer adoption) | Not available | 30.0k |
| PyPI weekly downloads(Developer adoption) | Not available | 53 |
As of September 21, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Evidence
September 21, 2026Package vulnerabilities
npm · @evidence-dev/evidence@40.1.8
0 vulnerabilities
across 1 package
Repository security score
Not available
Lightdash
September 21, 2026Package vulnerabilities
npm · @lightdash/common@2.274.1 · PyPI · lightdash@1.1.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
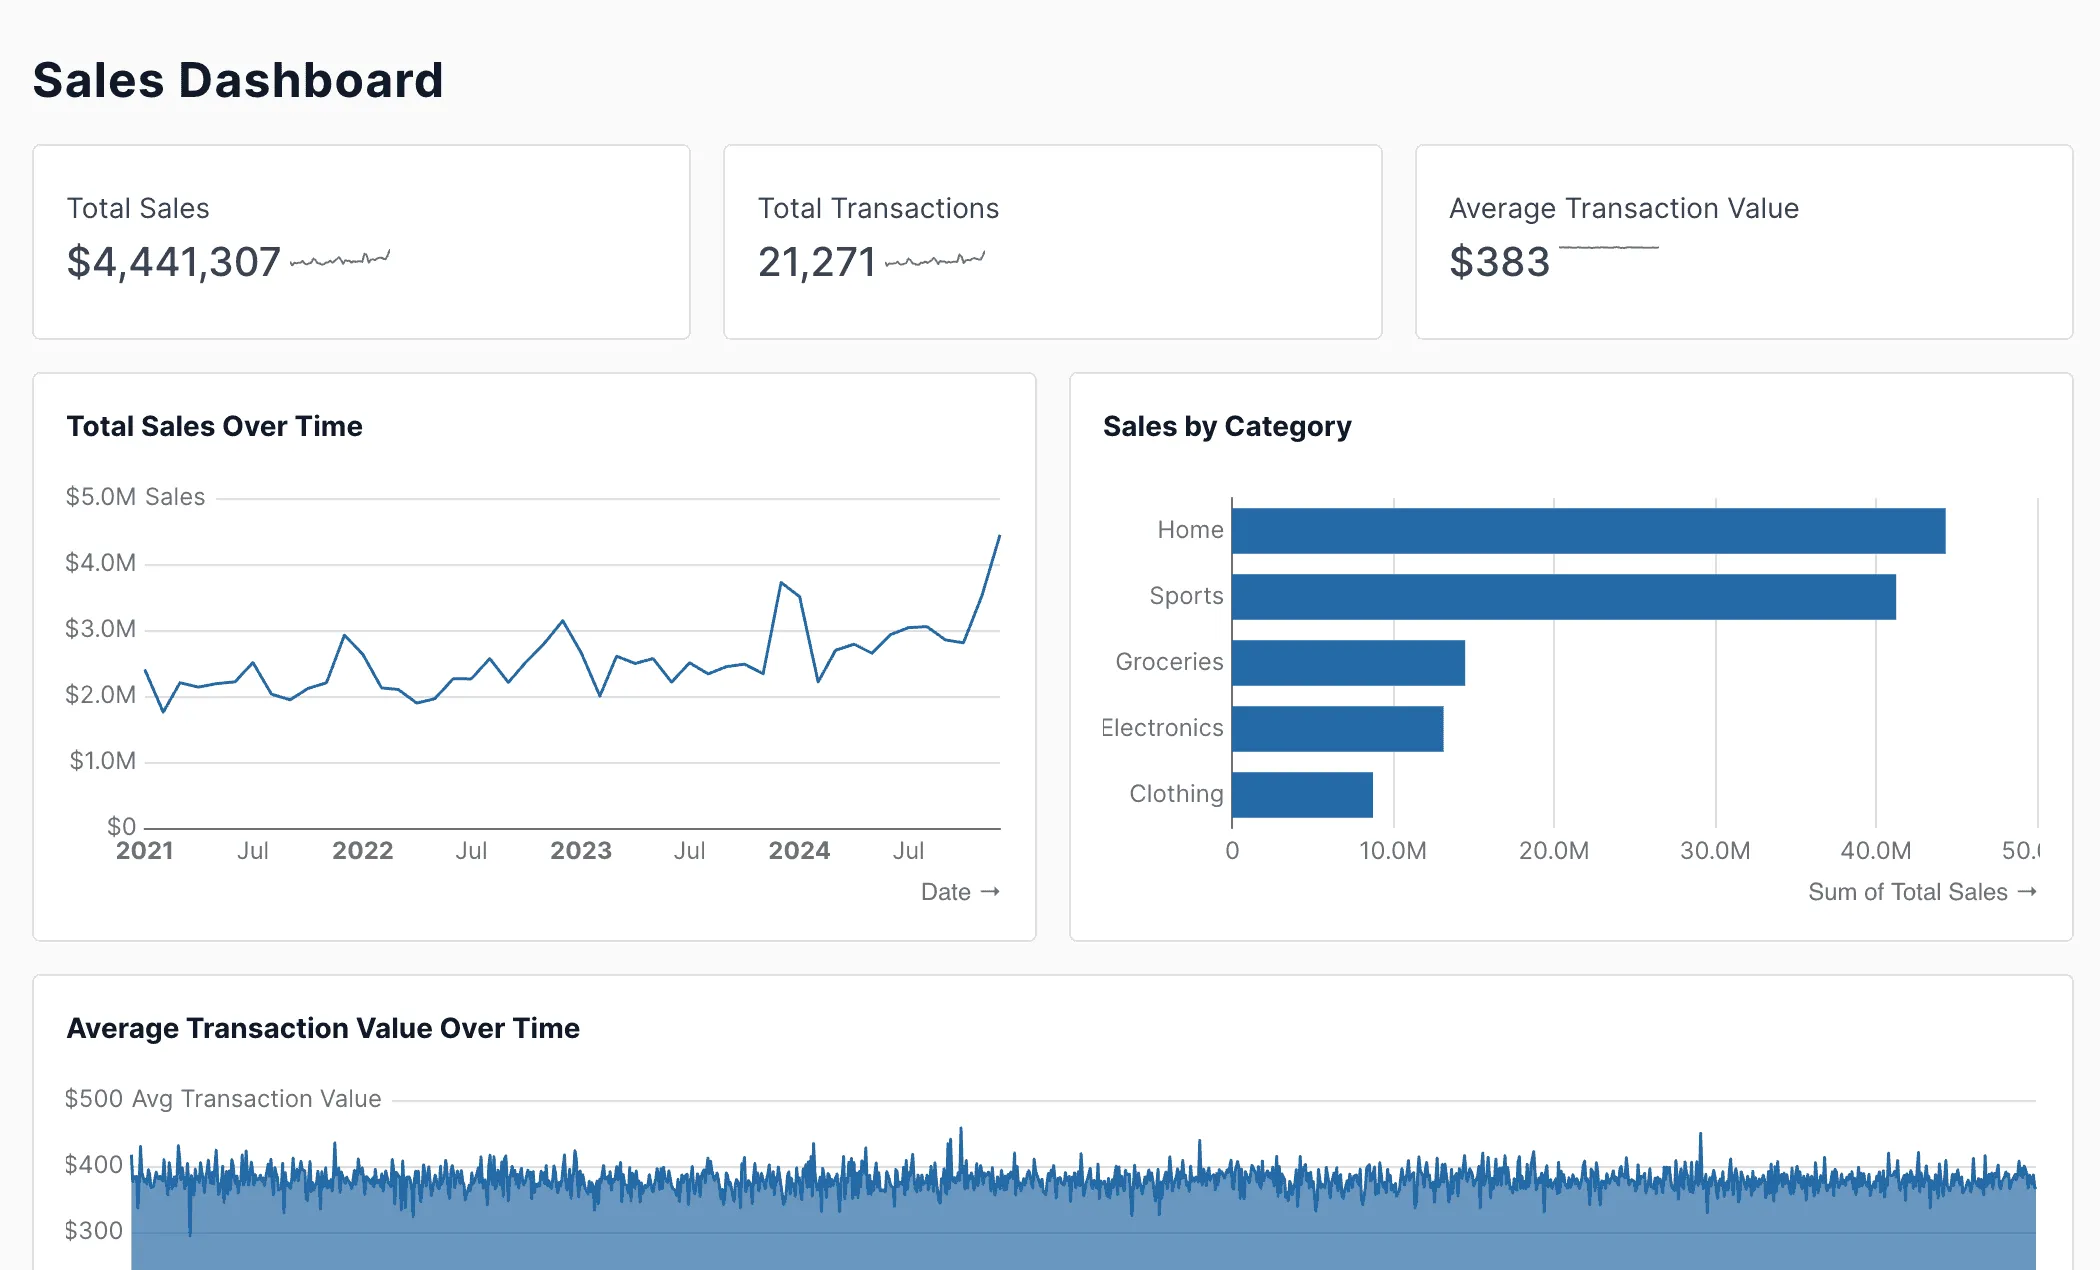
Interface Preview
Evidence
Lightdash
Feature Comparison
| Feature | Evidence | Lightdash |
|---|---|---|
| Modelling | ||
| Metrics defined in dbt | Partial support | Full support |
| Reports as version-controlled files | Full support | Partial support |
| Pull request review of changes | Full support | Partial support |
| Self-service exploration in a browser | Not verified | Full support |
| Delivery | ||
| Static site output | Full support | Not verified |
| Interactive filtering | Partial support | Full support |
| Scheduled delivery | Full support | Full support |
| Embedding in your own application | Full support | Full support |
| Adoption | ||
| Usable without engineering help | Not verified | Full support |
| Continuous integration friendly | Full support | Full support |
| Runs on your own infrastructure | Full support | Full support |
| Open source | Full support | Full support |
| Platform | ||
| Warehouse connectivity | Full support | Full support |
| Self-hosted deployment | Full support | Full support |
| Open source | Full support | Full support |
| Scheduled delivery | Full support | Full support |
Modelling
Metrics defined in dbt
Reports as version-controlled files
Pull request review of changes
Self-service exploration in a browser
Delivery
Static site output
Interactive filtering
Scheduled delivery
Embedding in your own application
Adoption
Usable without engineering help
Continuous integration friendly
Runs on your own infrastructure
Open source
Platform
Warehouse connectivity
Self-hosted deployment
Open source
Scheduled delivery
Which to choose
Evidence and Lightdash both assume a data team that works in dbt and Git, and they expose different amounts of it. Evidence writes the whole report as a file — SQL, prose and charts together — reviewed as code. Lightdash reads metrics defined in the dbt project and gives analysts a browser to explore them without writing files.
Best-fit scenarios
Choose Evidence if:
Choose Evidence when reports themselves should be reviewed. Writing the whole thing as a file means the narrative, the SQL and the charts all pass through the same review as any code change, which suits board reporting and any number where a silent edit would be unacceptable.
Choose Lightdash if:
Choose Lightdash when the dbt project is already the source of truth for metrics and the goal is to let people use them. Metrics defined once in dbt are charted by analysts in a browser, so the definition stays reviewed in version control while exploration does not require a pull request.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Which parts should be in version control?
Metric definitions, certainly — that is where inconsistency does the most damage and where review pays for itself. Whether the report layout also belongs there is the actual question between these two. Teams with a governed set of numbers that must not change silently usually want both; teams whose main problem is inconsistent definitions usually need only the first.
Does a dbt-native tool limit what analysts can ask?
It constrains them to the models and metrics that exist, which is the point and also the limit. Questions within the project are answerable without help; questions needing a join nobody modelled go back to the data team. That is a reasonable boundary when the project is well maintained, and a bottleneck when it is not.
Can they coexist?
Yes, and it is a coherent arrangement: Lightdash for self-service exploration over dbt models, Evidence for the reports that need narrative and review. Both read the same warehouse and both sit downstream of the same dbt project, so there is no second definition of anything — which is the usual objection to running two BI tools.
What does each one need to run?
Evidence needs a build step and somewhere to serve static files: a CI job runs the queries, renders the Markdown reports and publishes the output, plus credentials to reach the warehouse at build time. Lightdash needs a running service — self-hosted or Lightdash Cloud — and, more importantly, a dbt project with metrics and dimensions defined in it, because that project is where its semantic layer comes from. One is a pipeline you run on a schedule; the other is a platform plus an existing analytics engineering practice.
What happens to the cost as more people use it?
Neither charges per seat, because both are open source, which removes the usual growth cliff. What grows is different. Evidence's static builds query the warehouse once per build no matter how many people read the result, so a wider audience is nearly free and a faster refresh cadence is the cost. Lightdash queries on behalf of people exploring, so more explorers means more warehouse compute. Model the warehouse bill against your real audience: mostly readers favours the build-time shape, mostly explorers favours the interactive one.
How should we evaluate them?
Rebuild one dashboard people already rely on, and answer one question nobody has a dashboard for. The first tests modelling, refresh and permissions against something you already understand, so differences are obvious. The second tests whether a person who is not on the data team can actually get an answer, which is what self-service means and what demos never show.